AI Algorithm Engineer Self-Study Roadmap: A Complete Plan from Zero to Landing Your First Offer

A complete self-study roadmap for becoming an AI algorithm engineer, from zero to job-ready.
This article provides a comprehensive learning roadmap for aspiring AI algorithm engineers, covering the full skill set from business analysis and math foundations to core algorithms, CV/NLP specialization, model deployment, and job search preparation. It offers practical guidance for career changers on building end-to-end project capabilities and navigating the interview process.
For developers looking to transition into the artificial intelligence field, the biggest challenge often isn't "Can I learn this?" but rather "Where do I even start?" Facing an ocean of algorithms, models, and frameworks, self-learners without a systematic plan easily fall into the trap of aimlessly watching tutorials and reading papers without being able to apply anything. This article is based on a comprehensive AI algorithm engineer self-study roadmap, outlining the actual competency framework required for this role and helping you build a clear learning map.
What Skills Does an Algorithm Engineer Actually Need?
Many beginners have a misconception about algorithm engineers, thinking that mastering models and algorithms is enough. But from a practical work perspective, the skill requirements for this role are far more comprehensive than most people imagine.
A true algorithm engineer first needs business analysis capabilities. When you receive a business requirement, the first step isn't rushing to pick a model — it's analyzing: What data needs to be prepared for the current business scenario? What level of performance can the model achieve? Is this actually feasible? And how should it be done? This requirement-driven analytical thinking is what separates a "package caller" from a real engineer.
It's worth understanding deeply that business analysis in AI projects is fundamentally different from requirements analysis in traditional software development. In traditional development, once requirements are clear, there's usually a deterministic implementation path. But AI projects require judgment on whether the problem is suitable for machine learning, whether data is sufficient and of adequate quality, whether model accuracy can meet business expectations, and more. For example, a seemingly simple requirement to "identify product defects" actually requires evaluating whether defect samples are numerous enough to train a model, the diversity of defect types, real-time requirements, and many other dimensions. This capability requires simultaneously understanding technical boundaries and business logic — something pure technical study cannot cover. It comes from repeated refinement through real projects.
Second comes model and algorithm selection and optimization. Only after clarifying business objectives and data conditions do you enter the phase of selecting models, choosing algorithms, and performing optimization. After this phase, there's another often-overlooked but extremely important component — engineering deployment capabilities.
Deployment Skills: From Lab to Production
Getting a model to run in a Jupyter Notebook is just the first step of a long journey. In actual deployment, you need to consider model quantization, hardware integration, and server deployment. In other words, a complete project spans from requirements analysis, data acquisition, algorithm modeling, and model optimization to final deployment — you need to master every link to truly handle business independently.
Here it's worth elaborating: model quantization is the technique of converting deep learning models from high-precision floating point numbers (such as FP32, i.e., 32-bit floating point) to low-precision representations (such as INT8, FP16), with the goal of significantly reducing model size and inference latency while minimizing accuracy loss. Common quantization methods include Post-Training Quantization (directly compressing precision on already-trained models) and Quantization-Aware Training (simulating quantization errors during training to achieve better compression results). Hardware adaptation involves deploying models to different inference engines (such as NVIDIA's TensorRT, Microsoft's ONNX Runtime, Intel's OpenVINO) and hardware platforms (GPU, NPU, ARM edge devices, etc.). Each hardware platform has different requirements for model formats and operator support, and engineers need to perform targeted optimization based on the actual deployment environment — which is why deployment skills are so important in practice.
Therefore, passive learning approaches like "only reading papers and watching videos" are far from sufficient. Engineering practice, hands-on ability, and end-to-end project experience are what employers truly value.
Complete AI Algorithm Engineer Learning Roadmap Overview
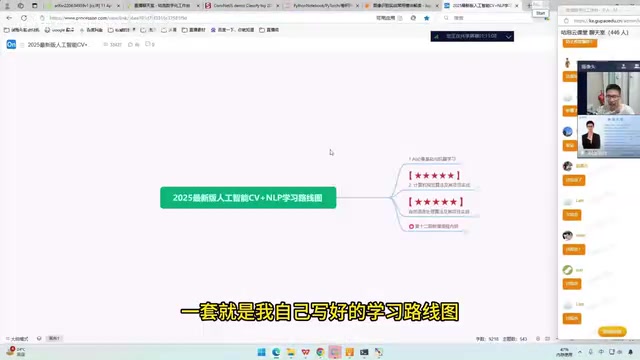
For beginners or career changers, a well-structured learning roadmap can dramatically improve learning efficiency and help avoid detours. A comprehensive AI self-study roadmap typically includes the following layers.
Foundation Phase: Programming and Mathematics
This phase focuses on building solid programming and math foundations, including Python programming skills, essential mathematics (linear algebra, probability and statistics, calculus, etc.), and basic machine learning algorithms. This is the foundation for all subsequent advanced learning and cannot be skipped.
For many career changers, math fundamentals are often the biggest psychological barrier. But it's important to clarify: the mathematics required for algorithm engineers isn't at the depth of pure mathematical research — it's a necessary tool for understanding algorithmic principles. Specifically, linear algebra is the cornerstone for understanding neural network operations — neural networks are essentially combinations of massive matrix multiplications and nonlinear transformations, and understanding matrix operations, eigenvalue decomposition, and similar concepts is essential to truly comprehending model architectures. Probability and statistics form the basis for understanding model evaluation metrics, Bayesian methods, and loss function design — for example, the essence of cross-entropy loss is the KL divergence from information theory. Calculus provides the theoretical foundation for gradient descent optimization algorithms — understanding backpropagation requires mastering the chain rule of derivatives, and understanding regularization requires knowledge of L1/L2 norms. Learners are advised to aim for "understanding the intuitive meaning and being able to follow formula derivations" without pursuing the mathematical rigor needed to prove theorems.
Core Algorithms and Project Practice
After mastering the foundations, you enter core algorithm learning. The emphasis here is that algorithm learning must be paired with project practice. A good roadmap typically specifies: which algorithms to learn, what project to add, and what specific tasks to complete within the project. Only by connecting algorithmic knowledge through projects can you build real capability rather than scattered knowledge points.
The core algorithm phase typically covers traditional machine learning (such as decision trees, random forests, SVM, XGBoost, etc.) and deep learning fundamentals (Convolutional Neural Networks/CNN, Recurrent Neural Networks/RNN/LSTM, attention mechanisms, etc.). The significance of project practice is that it takes you through the complete data processing pipeline — from raw data cleaning, feature engineering, model training and hyperparameter tuning, to result evaluation and analysis. During this process, you'll encounter real-world problems like data imbalance, overfitting, and training non-convergence, and the experience of solving these problems is precisely what's most valuable to discuss in interviews.
CV vs. NLP: How to Choose Between the Two Major Career Directions
After completing foundational and core algorithm learning, career directions typically diverge into two mainstream tracks: Computer Vision (CV) and Natural Language Processing (NLP).
Whether you choose CV or NLP, you need a targeted detailed plan. For CV, you need to systematically learn the algorithm models corresponding to classic tasks like image classification, object detection, and image segmentation. The NLP direction involves text processing, word embeddings, Transformer architecture, large language models, and more.
What particularly needs mention here is the Transformer architecture — it has become the most fundamental architecture in the current AI field. Transformer was proposed by the Google team in the 2017 paper Attention Is All You Need, with its core innovation being the Self-Attention mechanism, which can process information at all positions in a sequence in parallel, completely solving the training efficiency bottleneck and long-range dependency problems caused by sequential processing in RNN/LSTM. This architecture was initially designed for machine translation tasks but quickly expanded to the entire NLP field, giving rise to milestone works like BERT (bidirectional encoder) and the GPT series (autoregressive generative models), and further penetrating into the CV field (e.g., Vision Transformer/ViT using self-attention instead of convolution for image processing). It's fair to say that deeply understanding Transformer has shifted from a "nice-to-have" to a "must-have" for algorithm engineers, regardless of whether you choose the CV or NLP direction.
Interestingly, these two directions aren't the endpoint of learning. Beyond the core content of CV and NLP, there are numerous extension directions to explore, such as multimodal learning, generative models, reinforcement learning, and other frontier areas.
Multimodal learning refers to enabling models to simultaneously understand and process multiple types of data (such as text, images, audio, and video). Representative works include OpenAI's CLIP (which maps text and images to a unified semantic space through contrastive learning, enabling zero-shot image classification) and GPT-4V (a large language model with visual understanding capabilities). Generative models have evolved from early GANs (Generative Adversarial Networks, which train to generate realistic images through the adversarial interplay between a generator and discriminator) to today's diffusion models (such as Stable Diffusion, which generates high-quality images through a gradual denoising process) and autoregressive large language models (such as ChatGPT, which generates coherent text by predicting the next token). These frontier directions represent the trend of deep convergence between CV and NLP and are currently the hottest skill demands in the job market, worthy of focused attention after deepening your main direction.
Therefore, when planning your learning path, it's recommended to first focus deeply on one main direction, then expand horizontally.
Three Dimensions for Choosing Your Direction
When choosing between CV and NLP, consider these dimensions:
- Personal interest: Do you prefer working with images or text?
- Job market demand: Different regions and industries have varying demand for both. Looking at 2024 trends, the NLP direction has seen a surge in job openings due to the explosion of large language models, but competition is correspondingly fierce; the CV direction still has stable demand in vertical fields like autonomous driving, industrial quality inspection, and security.
- Personal background: Relevant domain experience makes it easier to get started — for example, someone with a medical imaging background has a natural advantage transitioning to CV.
It's recommended to explore introductory projects in both directions during the foundation phase before making your final decision.
Realistic Career Paths for Transitioning to Algorithm Roles
Looking at actual learner demographics, a significant proportion of AI algorithm role learners are career changers and people from non-CS backgrounds. Many come from other industries or non-computer science majors with a very clear goal — landing an algorithm position offer.
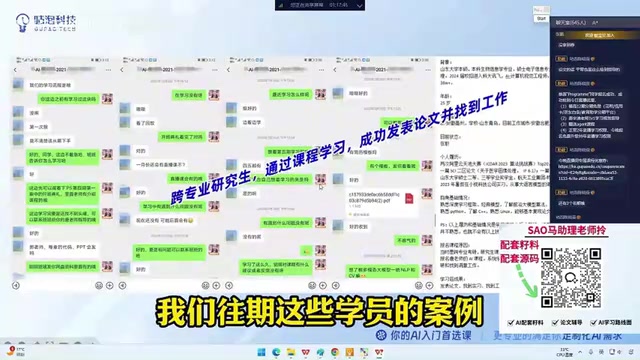
This shows that while AI algorithm engineering has a high barrier to entry, it remains accessible to career changers. The key is whether you have systematic planning and sustained commitment. For career changers, beyond technical learning itself, job search preparation is equally important, including:
- Paper guidance: Help understanding cutting-edge research, or even producing your own results to strengthen resume competitiveness. For algorithm role interviews, being able to deeply explain a top conference paper (from venues like CVPR, NeurIPS, ACL, etc.) — its motivation, methodology, and experimental design — demonstrates deep domain understanding and is a very powerful advantage in interviews.
- Resume coaching: How to package project experience into highlights recognized by HR and interviewers. The core of an algorithm role resume is demonstrating what problem you solved, what methods you used, and what quantified results you achieved (e.g., accuracy improved by X%, inference speed improved by X times).
- Career coaching: Interview techniques, algorithm fundamentals Q&A (commonly asked foundational knowledge questions in algorithm role interviews, covering machine learning principles, deep learning details, data structures and algorithms, etc.), and project defense preparation.
These components must work together to form a complete loop from learning to employment. It's worth noting specifically that algorithm role interviews typically include three core components: live coding, algorithm principle Q&A, and deep-dive project discussions — each requiring targeted preparation.
Summary: Building Your AI Algorithm Engineer Growth Path
Becoming a qualified AI algorithm engineer is far from simply "learning a few models." It requires you to develop full-pipeline capabilities spanning requirements analysis, data processing, algorithm modeling, model optimization, and engineering deployment. For beginners and career changers, the most important thing isn't rushing for quick results, but first establishing a clear learning map that specifies what to study and what projects to complete at each stage.
Start by building a solid foundation, then go deep into either CV or NLP as your main direction, accumulate experience through real projects, and make thorough preparations for the job search phase. With sustained investment along this path, transitioning into the AI field and landing your ideal offer is an entirely achievable goal. The total learning duration varies depending on individual backgrounds and time investment, but for full-time learners, it typically takes 6-12 months to go from zero to job-ready competitiveness; part-time learners generally need 12-18 months of sustained commitment. The key is maintaining consistency and avoiding long interruptions that lead to knowledge decay.
Related articles

Chain of Thought Isn't Just for AI: How Humans Can Use CoT to Improve Thinking Quality
Chain of Thought isn't just a prompt trick for large models. Starting from a Hacker News discussion, this article analyzes why CoT works for human thinking too, breaks down actionable ways to transfer it, and highlights the key differences between human CoT and machine CoT.
Cloudflare Teams Up with OpenAI: Closi…
Cloudflare Teams Up with OpenAI: Closing the Loop from Vulnerability Discovery to Defense with AI
Cloudflare uses OpenAI Daybreak to investigate security vulnerabilities and generate reviewable remediation plans, while developers use Codex to boost coding efficiency and quality.

Orca Multi-Agent Orchestration in Practice: A Guide to Parallel Collaboration with Claude and Codex
Orca is Stable AI's free open-source agent workbench supporting 34 agents like Claude Code and Codex in parallel. Learn its Git worktree isolation, multi-model orchestration, and mobile management.