AI Got It Right But Changed Too Much? LLM State Reconciliation Benchmark Reveals a Critical Blind Spot
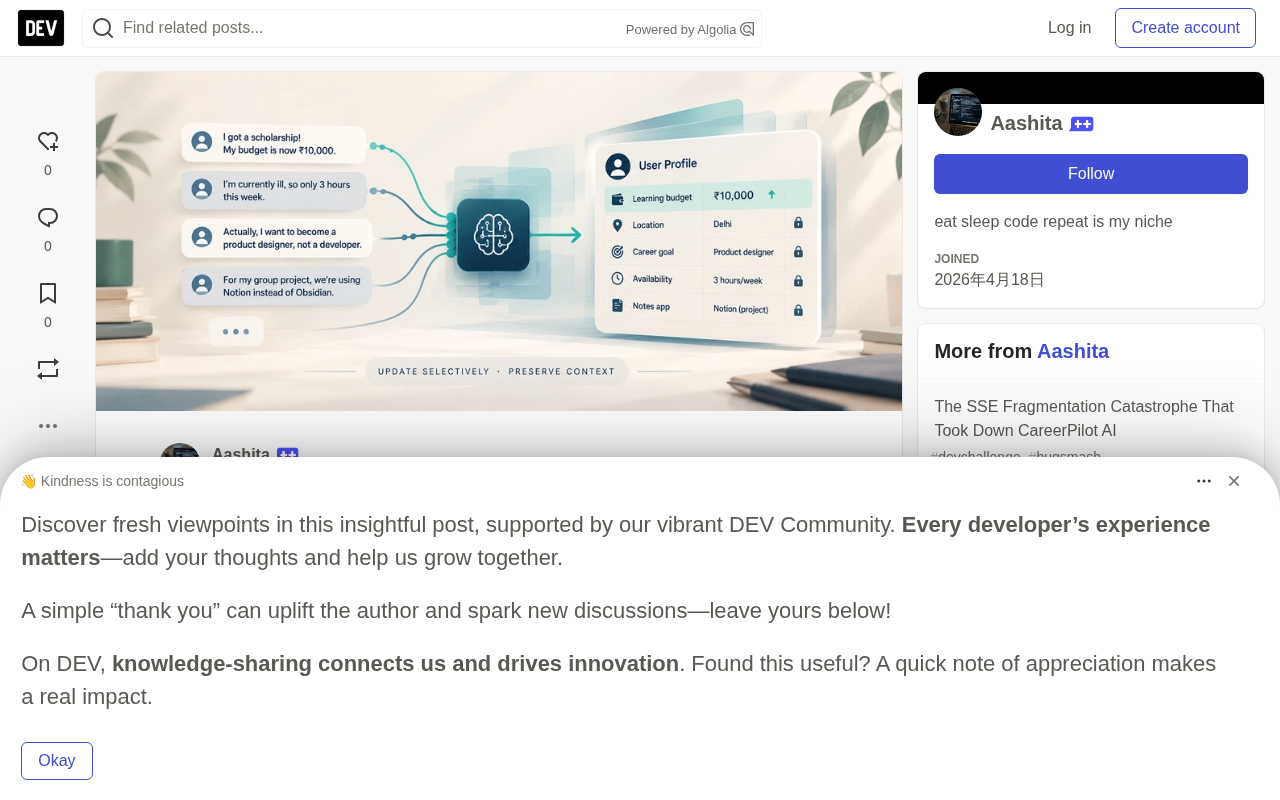
AI assistants can correctly update target fields while quietly tampering with unrelated ones — a failure mode called LLM State Reconciliation.
The article introduces an overlooked AI evaluation blind spot: language models maintaining structured user state across multi-turn conversations may correctly complete requested updates while tampering with fields that should remain unchanged. The author calls this LLM State Reconciliation and tests DeepSeek, Claude, and Gemini. The initial ten cases all scored perfect, but suspecting insufficient discriminative power, he designed a harder H01-H12 suite with nine expected updates and 291 protected field slots to test retention. A DeepSeek observation suggested possible cross-case contamination in a budget field, raising a debate over independent initialization vs. sequential conversation evaluation protocols. Due to missing complete raw outputs, the author refuses to provide an unverified leaderboard, arguing the benchmark's core value lies in reproducibility.
Getting It Right Doesn't Mean Nothing Went Wrong
A developer raised an easily overlooked evaluation blind spot in a Kaggle benchmark challenge: an AI assistant can make the correct modification when updating user information, while simultaneously and quietly tampering with fields that should have been left untouched. He calls this failure mode LLM State Reconciliation — when a model maintains structured user state across multi-turn conversations, can it change only what should change and preserve what should stay?
The initial experiments looked quite promising. He put DeepSeekAd, Claude, and Gemini through ten scenario tests, and every model scored a perfect result. Anyone else might have packed up and celebrated, but instead he began to suspect the benchmark itself — were these cases just too easy to distinguish?
The Budget Changed, Everything Else Must Stay Put
The core of the problem can be illustrated with a simple scenario. A user's study budget was originally ₹5,000. Later, a scholarship was approved, and the budget increased to ₹10,000. The budget should change, but the user's location, career goals, study preferences, and available time should all remain unchanged.
Once complexity rises, things get tricky: the user temporarily has only three hours available due to illness; the user corrects a previously stated career goal; the user mentions using a different note-taking app for a university group project; the user discusses an unconfirmed internship opportunity and relocation plans.
A reliable assistant must distinguish: temporary conditions from permanent changes, explicit corrections from contradictory information, confirmed facts from possibilities. It must also preserve the information that the latest message never asked it to change.
The author's research question is precisely this: can a language model update a structured representation of user information across multiple messages without losing important facts, without introducing irrelevant changes, and without treating uncertain events as established facts?
Why This Benchmark Is Different from Ordinary Tests
Testing whether a model changes only the settings it was asked to change is itself an independent and important question. But user information introduces an additional challenge: the meaning of an update depends on context.
A temporary reduction in available time is not the same as a permanent schedule change. A conditional resignation is not a completed resignation. A preference expressed for a team project does not automatically replace a personal preference. A possible relocation plan should not become a recorded fact before it happens.
These distinctions drive the benchmark's design. The author doesn't just check whether unrelated fields remain unchanged; he wants to examine whether the model understands which changes the conversation actually provides justification for. This means evaluating both the update itself and the state left behind after the update.
Retention is one of the core metrics for evaluating language model state updates. It refers to whether a model, after completing a target field update, can refrain from modifying or forgetting fields whose change the conversation did not request. It differs from Accuracy: accuracy only looks at whether the model did the requested operation correctly, whereas retention focuses on whether the model "didn't do wrong" what it shouldn't have done. In structured state maintenance scenarios, poor retention typically manifests in two forms — omission loss (a field is cleared or reverts to a default value) and incidental mutation (a field is changed to an irrelevant value). These two types of errors are completely invisible under metrics that only look at target update accuracy, so they must be evaluated separately. The difficulty of retention lies in the fact that the model needs to judge which fields are relevant to the current conversation and which are not, and the judgment of "relevance" is highly context-dependent, making retention evaluation closer to the state management challenge in real conversations than to a pure classification or extraction task.
From Easy Perfect Scores to Twelve Harder Cases
In the initial experiment, all models reported perfect accuracy on the ten cases. The author didn't take this as evidence that the problem was solved, but rather as a limitation of the evaluation: these cases lacked sufficient discriminative power.
So came the H01–H12 suite, built on a 25-field baseline and covering twelve different failure modes: temporary vs. permanent changes, explicit corrections, contradictory evidence, conditional future events, references to earlier messages, multiple simultaneous updates, task-specific vs. general preferences, outdated information, personal vs. project-level preferences, uncertain employment outcomes, confirmed vs. unconfirmed changes, and composite state reconciliation.
In the scoring design, this suite contains nine expected field updates and 291 protected field slots. This distinction is crucial: a model may correctly update the requested fields while quietly changing something else. Metrics that only measure requested updates would completely miss this failure.
Protected Field Slots is a counting unit used in benchmark design to quantify retention. In a structured user state containing N fields, for a given conversational message, only a few fields are explicitly requested to be updated, while the rest are in a "protected" state — meaning they should not be touched by this update. Summing these protected fields across all cases yields the total number of protected field slots. For example, in the H01–H12 suite, nine expected field updates correspond to 291 protected field slots, meaning that on average each case has roughly twenty-plus fields that need to remain as-is. The value of this design is that it transforms retention from a vague qualitative judgment into a computable ratio: how many of the 291 slots the model incorrectly modified is the direct numerator of the incidental mutation rate. It also explains why a perfect target update accuracy can be misleading — a model that correctly completes the nine updates will appear perfect on accuracy, while 291 retention failures are completely unreflected by that number.
An Anomalous Observation Exposes a Methodological Problem
An early DeepSeek observation illustrates why retention must be evaluated separately. In a location update case, the target location was correctly changed to Bengaluru, but the budget remained at ₹6,000 from the previous case instead of returning to the ₹5,000 baseline. This was recorded as possible cross-case contamination.
This observation also raises a methodological question: should each case start independently from the same baseline, or is the benchmark testing an intentionally continuous conversation? Independent testing requires independent initialization; sequential testing requires that the expected state carry only changes justified by earlier messages. The evaluation protocol must clearly distinguish these two situations.
The author also candidly points out the limitations of the current results. Although additional model responses and summaries were collected, not every complete raw output for every model and case was retained. Therefore, he cannot independently verify the full H01–H12 retention and incidental mutation metrics, nor can he provide a reliable comparative leaderboard. He presents the observations reported in the conversation separately from the scores that can actually be computed from the raw outputs — missing evidence is not the same as passing.
The most valuable finding so far comes at the methodological level: a benchmark can produce perfect scores while not measuring the difficult behavior you care about at all.
Cross-Case Contamination refers to when, in sequentially executed benchmark tests, the conversational state from a previous case accidentally leaks into subsequent cases, causing the model to face a contaminated input baseline in the later case. A typical manifestation is that a field does not return to the initial value for that case, but instead remains at a residual value from the previous case. Cross-case contamination has nothing to do with model capability — it is a flaw in the evaluation protocol — but its presence can severely distort results: a model may be incorrectly judged as having a retention failure when in fact it merely faithfully continued the state from the previous round. Distinguishing independent initialization from sequential continuation essentially requires the benchmark designer to explicitly declare the expected input state for each case and to use a baseline matching that protocol during scoring. Without this declaration, any retention and incidental mutation metrics are unreliable, because it's impossible to determine whether a field value deviation stems from a model change or from a protocol leak.
How to Properly Evaluate State Reconciliation
The author breaks evaluation into three core dimensions:
Target update accuracy — did the model make the changes the conversation justifies?
Retention accuracy — did it refrain from touching unrelated fields?
Incidental mutation — how often did it change things that should have remained unchanged?
Temporal reasoning and uncertainty handling should also be evaluated separately. A model should not permanently override a preference because of a one-time exception, nor should it treat a conditional plan as a completed event.
For reproducible comparison, all models should receive the same prompts and baselines, each case should follow a clearly defined independent or sequential protocol, complete outputs should be retained, and then each model should be scored against the same ground truth using the same deterministic scoring code.
Incidental Mutation is an independent metric measuring the severity of retention failures, counting how many fields a model changed in a single state update that should have remained unchanged. It complements retention accuracy: retention accuracy is a ratio, while incidental mutation is a raw count, which is more useful for pinpointing exactly which fields were mistakenly changed and to what values. In an evaluation protocol, incidental mutation should be counted separately by case and by field type, because mistakenly changing some fields (such as budget or location) is far more costly than others. At the same time, incidental mutation needs to be cross-analyzed with target update accuracy — a model may have a low incidental mutation count alongside low target update accuracy (overly conservative), or both may be high (reckless updating). Only when both metrics are presented together can we characterize a model's true balance between "changing what should change" and "leaving alone what should stay."
Implementation Progress and Real Limitations
At the implementation level, the author has created the shared baseline and the ground truth structure for the twelve cases, implemented scoring and validation code, and added automated tests. The latest development run passed all ten tests. The existing C1–C10 evaluations also remain usable after project changes.
But these are engineering checks, not proof of model performance. C1–C10 and the harder H01–H12 are different evaluations, and the former cannot substitute for the raw evidence the latter is missing.
The next steps include: recovering or regenerating complete raw outputs, running cases under a documented initialization protocol, repeating evaluations to measure consistency, and expanding the scenario scope. The author also wants to investigate whether the same failure mode appears in conversational agents that actually maintain user profiles in practice.
On the release side, the author encountered Kaggle account verification issues and is temporarily unable to provide a public benchmark link. He chose to document these limitations rather than present an unverified leaderboard as a result.
The Real Question
As conversational assistants take on more responsibility for remembering preferences, plans, goals, and constraints, correctly updating information is only half the problem.
The other half is knowing what this update has not authorized the assistant to change.
When an AI assistant changes what it remembers, can we trust it to preserve the things we never asked it to change? This is exactly the behavior that LLM State Reconciliation aims to measure.
One-line Summary
AI assistants can correctly update target fields while quietly tampering with unrelated fields — a failure mode called the LLM State Reconciliation problem.
Paragraph Summary
The article introduces an overlooked AI evaluation blind spot: when language models maintain structured user state across multi-turn conversations, they may correctly complete requested updates while simultaneously tampering with fields that should not be changed. The author calls this failure mode LLM State Reconciliation and tests it with DeepSeek, Claude, and Gemini. The initial ten cases all scored perfect, but the author suspected insufficient discriminative power and designed a harder H01-H12 suite containing nine expected updates and 291 protected field slots, specifically testing retention. One DeepSeek observation showed that a budget field may have suffered cross-case contamination, leading to a debate over independent initialization versus sequential conversation evaluation protocols. Because complete raw outputs are missing, the author refuses to provide an unverified leaderboard, arguing that the core value of a benchmark lies in reproducibility.
Related articles

WorkBuddy Agent in Action: From AI Q&A to Automated Office Work
WorkBuddy is Tencent's AI agent desktop workbench that reads local files, operates office software, executes multi-step tasks, and runs on schedules. This article explains its core features, key differences from traditional AI tools, and use cases.

Anthropic Research: LLMs Make Formal Software Verification at Scale Possible
Anthropic Frontier Red Team research shows LLMs can generate formal proofs at the RISC-V assembly level for over 100 real open-source libraries, covering 123 OSS-Fuzz libraries and 239 entry points, totaling about 180 million lines of Rocq proofs and finding hundreds of bugs. The article analyzes specification generation, the proof pipeline, trust boundaries, and cost reduction paths.

Prompt Engineering for Beginners: From Writing Prompts to Building AI Collaboration Skills
From the four functions of prompts to the six-step prompt engineering process, this article systematically covers core concepts, business value, and three layers of limitations to help beginners build a complete cognitive framework for prompt engineering.