Algorithmic Monoculture: Systemic Risks of Machine Learning Recommendation Systems

Study quantifies social costs of algorithmic monoculture; diversification cuts simulated loss by 19.41% on average.
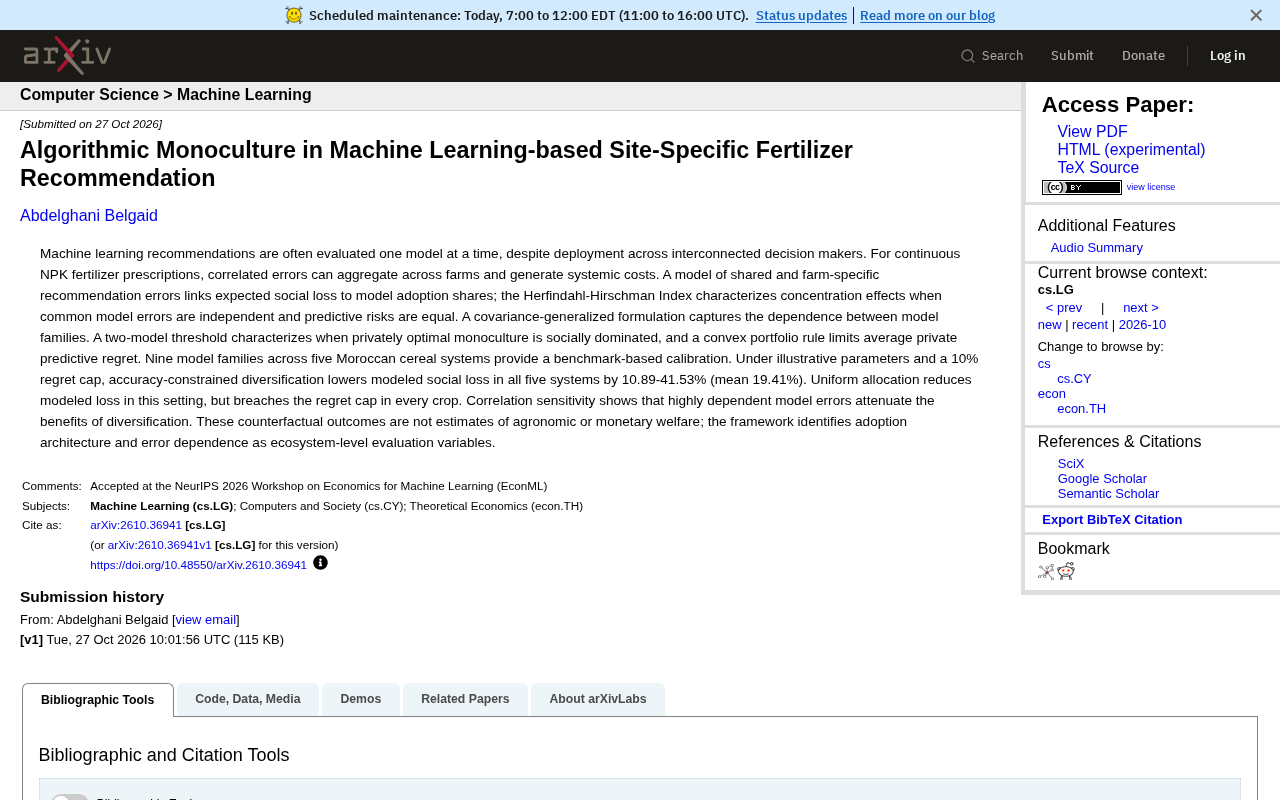
Machine learning recommendation systems are often judged by single-model accuracy, but when many decision-makers share one model, errors aggregate across users and create systemic social losses. Using Morocco's cereal system, a study applies the Herfindahl-Hirschman Index (HHI) and covariance formulas to capture model concentration and error dependency, proposing a two-model threshold and convex combination rule to identify when privately optimal monoculture is socially dominated. Calibration across five cereal systems and nine model families shows that under a 10% regret cap, accuracy-constrained diversification reduces simulated social loss by 10.89% to 41.53% (average 19.41%), while uniform allocation breaches the regret cap and highly correlated errors weaken diversification gains. The study urges including adoption architecture and error dependency in ecosystem-level evaluation of AI recommendation systems.
When multiple farms use the same machine learning model to recommend fertilizer application rates, the model's errors aggregate across farms, creating systemic social costs. A recent study uses Morocco's cereal system as a case study to quantify this "algorithmic monoculture" risk and proposes diversification strategies.
Why algorithmic monoculture matters
Machine learning recommendation systems are typically evaluated based on the accuracy of a single model, but in real-world deployment, many decision-makers may share the same model. For continuous nitrogen-phosphorus-potassium (NPK) fertilization recommendations, model errors are correlated across farms and can produce aggregated systemic losses. The study notes that this loss is related to model adoption share and can be characterized by the Herfindahl-Hirschman Index (HHI) to capture concentration effects.
The study builds a model with shared and farm-specific errors, linking expected social loss to model adoption share. When common model errors are independent and predictive risk is equal, HHI can characterize concentration effects; a covariance-based generalized formula captures dependencies between model families.
Herfindahl-Hirschman Index (HHI) was originally an indicator in industrial economics for measuring market concentration, calculated as the sum of squares of each participant's market share. In the context of algorithmic monoculture, it is borrowed to characterize the concentration of model adoption share: if all farms use the same model, HHI reaches its maximum of 1; if adoption is fully diversified, HHI approaches 0. The sum-of-squares structure of HHI aptly reflects the nonlinear nature of error aggregation—when adoption share concentrates on a few models, the compounding effect of shared errors is amplified. This analogy allows a tool originally used for market structure to be transferred to the field of algorithmic governance, providing a concise statistic for quantifying "how many farms share the same model."
Key finding: diversification reduces social loss
The study proposes a two-model threshold to determine when privately optimal monoculture is dominated at the social level, and provides a convex combination rule to bound average private prediction regret. Based on calibration of five cereal systems in Morocco and nine model families, under example parameters and a 10% regret cap, accuracy-constrained diversification reduced simulated social loss in all five systems, by 10.89% to 41.53%, averaging 19.41%.
You may not have noticed that while uniform allocation also reduces simulated loss under this setting, it breaches the regret cap in every crop. Correlation sensitivity analysis shows that highly dependent model errors weaken the benefits of diversification.
Private prediction regret is a concept from decision theory referring to the additional loss a decision-maker incurs by adopting a particular model rather than their private optimal model. In the diversification rule proposed here, the regret cap constraint ensures that no farm suffers excessive individual loss from being forced to use a non-preferred model. The convex combination rule allocates weights across different models, reducing error correlation between models while controlling average private regret, thereby balancing individual rationality and collective welfare. This mechanism explains why uniform allocation, despite reducing social loss, breaches the regret cap—it ignores the differentiated needs of individual farms for model accuracy.
Implications and limitations
These counterfactual results are not estimates of agronomic or monetary welfare, but rather identify adoption architecture and error dependency as ecosystem-level evaluation variables. For deployers of AI recommendation systems, this means evaluation cannot stop at single-model accuracy; it must also consider the distribution of models across populations and the correlation structure of errors.
The study offers a new perspective for algorithmic governance: in interconnected decision environments, promoting model diversity may have more social value than pursuing a single highest accuracy.
Counterfactual results in causal inference and policy evaluation refer to estimates of "what would happen if another strategy were adopted," derived from model simulation rather than actual observation. The 10.89% to 41.53% loss reductions in this paper do not come from field trials but are calculated from calibrated models under hypothetical adoption architectures. Therefore, these figures should be understood as directional evidence rather than precise welfare estimates; their value lies in revealing the importance of adoption architecture and error correlation as evaluation dimensions, not in predicting specific benefits after real policy implementation.
Key takeaways
- Machine learning recommendations are often evaluated in isolation, but in deployment, multiple decision-makers sharing a model leads to error aggregation.
- The study uses HHI and covariance formulas to characterize model concentration effects and error dependency.
- In five Moroccan cereal systems, accuracy-constrained diversification reduced simulated social loss by an average of 19.41%.
- Uniform allocation breaches the regret cap, and highly correlated errors weaken diversification benefits.
- The framework identifies adoption architecture and error dependency as ecosystem-level evaluation variables.
One-line Summary
Study quantifies the social cost of algorithmic monoculture, finding that diversification reduces simulated loss by an average of 19.41%.
Paragraph Summary
Machine learning recommendation systems are often evaluated by single-model accuracy, but when many decision-makers share the same model, errors aggregate across users, creating systemic social losses. A study using Morocco's cereal system as a case study employs the Herfindahl-Hirschman Index (HHI) and covariance formulas to characterize model concentration effects and error dependency, proposing a two-model threshold and convex combination rule to determine when privately optimal monoculture is dominated at the social level. Calibration across five cereal systems and nine model families shows that under a 10% regret cap, accuracy-constrained diversification reduces simulated social loss in all systems by 10.89% to 41.53%, averaging 19.41%; uniform allocation breaches the regret cap, and highly correlated errors weaken diversification benefits. The study calls for incorporating adoption architecture and error dependency into ecosystem-level evaluation of AI recommendation systems.
Related articles

Googlebook's First Developer Case Studies: How Notability and Logitech Built Desktop-Class Android Experiences
Notability and Logitech share first-hand experience building for Googlebook: using Jetpack Compose, Navigation 3, and Jetpack Ink for desktop-class Android, plus how the peripheral customization API bridges hardware and OS.
Google Play Multi-Device Publishing Guide: Modular Architecture and Review Pitfalls
Complete guide to Google Play multi-device publishing: why modular App Bundles beat a single bundle, track exceptions for Wear OS and Android Auto, how three-tier testing channels pre-validate reviews, and common rejection reasons for TV, XR, cars, and Wear OS with avoidance tips.
Why Are Baby Boomers Wealthier? An Analysis of Luck and Institutional Advantages
Why are baby boomers wealthier? This article breaks down the generational advantages, housing and stock market gains, zero-sum mechanisms like restrictive zoning, and the intergenerational impact of rising Social Security generosity in their wealth sources.