Alibaba Releases Qwen4-Max: 2.4T MoE Architecture, 1M Context

Alibaba launches 2.4T MoE proprietary flagship Qwen4-Max, shifting focus to cost per task.
Alibaba officially releases Qwen4-Max, a flagship proprietary model with 2.4T total and 71B activated MoE parameters, native vision, and 1M token context at $1.5 per million input tokens. It claims a 62% cut in cost per task on Work360, signaling a shift from parameter-stacking to cost per task. The article covers MoE's cost decoupling, infrastructure demands of 1M context and native multimodality, task-level vs per-token pricing, and Alibaba's dual-track open-source/proprietary strategy.
Alibaba has officially released Qwen4-Max, a flagship proprietary model built on MoE architecture. It features 2.4T total parameters with 71B activated parameters, native visual understanding, and a 1M token context window, priced at $1.5 per million input tokens. The company also disclosed that on the Work360 benchmark, the model cuts cost per task by 62%. These figures point to the same signal: competition among large models is shifting from "stacking parameters" to "cost per task."
Architecture Choice: Why MoE Has Become the Flagship Standard
Qwen4-Max uses a mixture-of-experts architecture with 2.4T total parameters and 71B activated parameters. Total parameters determine the model's capacity ceiling, while activated parameters determine the actual computation per inference. The roughly 34x gap between the two means the model can maintain a massive scale while keeping the compute overhead per request far below that of a dense model.
This design approach has gradually become consensus among flagship models. Pushing a dense model to the same capability level would cause inference costs to grow linearly or even faster, whereas MoE decouples "capability" from "cost" through sparse activation. Qwen4-Max's pricing—$1.5 per million input tokens—in the context of a 2.4T parameter scale, itself illustrates the cost structure shift this architecture enables.
What's notable is the activation ratio. An activated scale of 71B is on the larger end among MoE models, meaning each token is routed to more experts, so the model doesn't noticeably compromise on expressiveness or reasoning depth due to sparsification. This is the "large total parameters, large activation" route, rather than pursuing extreme sparsity.
Mixture-of-Experts (MoE) works by replacing the single feed-forward network (FFN) in a standard Transformer with multiple parallel "expert" subnetworks, and using a learnable router to dynamically select and activate only a few experts for each token. Total parameters are the sum of all expert parameters, while activated parameters are only those actually involved in computation during a single forward pass—this is the source of "2.4T total, 71B activated" mentioned above.
The key tradeoff in MoE lies in routing quality and load balancing: if the router consistently assigns tokens to a few experts, it leads to low parameter utilization and training instability, which the industry typically mitigates with auxiliary load-balancing losses. In addition, MoE models' memory requirements are still determined by total parameters (all experts must reside in memory or be split via expert parallelism), so what it reduces is compute cost, not deployment cost—an important point for understanding its pricing logic.
1M Context and Native Vision: Tradeoffs Across Two Capability Dimensions
The 1M token context window is another core selling point of Qwen4-Max. The real value of long context isn't "how much text you can stuff in," but whether retrieval and reasoning remain stable across extremely long inputs. What's disclosed is the window size; no specific evaluation data on long-context retrieval precision is given, so actual performance still needs independent testing.
Native vision means image understanding isn't bolted on through external modules but integrated into the model during training. For enterprise scenarios that need to process documents, charts, and text together, native multimodality can reduce modality-conversion losses in the pipeline.
Raising context length, multimodality, and parameter count simultaneously puts exponential pressure on inference infrastructure. That Qwen4-Max can maintain $1.5 per million tokens at 1M context indicates Alibaba has done considerable engineering optimization on the inference side.
Context windows are constrained by the computational complexity of attention mechanisms and the memory footprint of the KV Cache: standard full attention grows quadratically with sequence length, and a 1M token sequence is nearly infeasible with a naive implementation. Mainstream approaches include chunked attention, sliding windows, linear attention approximations, and positional encoding extrapolation (such as RoPE's NTK interpolation or YaRN). These methods often introduce precision decay while extending the window, with notably divergent performance especially on "needle-in-a-haystack" long-distance retrieval tasks—which is why the article emphasizes that "window size" and "retrieval stability" are two different levels of metrics.
Native multimodality differs from "bolt-on拼接" in training objectives and data ratios: the native approach lets visual tokens and text tokens share the same attention and expert routing during pretraining, so the model learns joint cross-modal representations; bolt-on approaches typically freeze the language model and train only a projection adapter, limiting cross-modal reasoning. The cost is that native approaches require larger-scale interleaved image-text corpora and higher training compute.
62% Cost Reduction: A New Pricing Unit for Enterprise Procurement
The most thought-provoking figure about Qwen4-Max isn't the parameter count, but the 62% drop in cost per task on the Work360 benchmark. Work360 is an evaluation set oriented toward real work-task scenarios, measuring the total cost required to complete a full task rather than the per-token price.
The distinction between these two metrics is crucial. A low unit price doesn't equal low task cost—if a model needs more rounds or longer outputs to complete a task, the total cost may be higher no matter how cheap each token is. The 62% task-level cost reduction implies improvements in task-completion efficiency, not just a price war.
For enterprise buyers, this means the standard for evaluating models needs updating: from "how much per million tokens" to "how much to complete a business task." Qwen4-Max has put this pricing logic on the table, and subsequent pricing narratives for similar products will likely follow this framework.
Cost per task evaluation typically requires fixing a task set, allowing the model to autonomously decide the number of rounds and output length, then tallying end-to-end token consumption and cost. Its relationship to per-token pricing can be approximated as: task cost ≈ per-token price × (input tokens + output tokens), where the output token price is usually significantly higher than input. Therefore, a drop in task cost can come from three sources: lower unit price, output compression (more concise but correct answers), and fewer rounds (getting it right the first time rather than repeated retries). Distinguishing these three is critical for procurement decisions—if the advantage mainly comes from output compression, it may narrow in scenarios requiring long outputs (such as report generation).
Proprietary Flagship Route and Division of Labor with the Open-Source Ecosystem
Qwen4-Max is explicitly labeled as a proprietary model. This contrasts with the reputation the Qwen series previously built in the open-source community: Alibaba maintains ecosystem influence through open-source small and medium-scale models while channeling its strongest capabilities into a proprietary flagship for commercialization.
This dual-track strategy is not uncommon among leading vendors, but its practical impact on developers is layered: research and secondary development can still use open-source weights, while commercial applications seeking top-tier capability and long context need to pay per token to access the proprietary API. The choice is in users' hands, but the cost structures differ.
Position in the Competitive Landscape
Looking at Qwen4-Max's numbers together—2.4T MoE, 71B activated, 1M context, native vision, $1.5 per million tokens, 62% lower task cost—it targets the enterprise high-value task market rather than price-sensitive mass-call scenarios.
The real test lies in actual retrieval precision under long context, multimodal performance on complex documents, and whether the 62% cost advantage can be replicated outside Work360. All of these require third-party evaluation for cross-validation. What's certain is that the competitive dimension for flagship models has expanded from mere parameter scale to "cost per task," a metric closer to business reality.
One-line Summary
Alibaba releases the 2.4T MoE proprietary flagship Qwen4-Max, steering competition toward cost per task.
Paragraph Summary
Alibaba has officially released its flagship proprietary model Qwen4-Max, built on a MoE architecture with 2.4T total parameters and 71B activated parameters, natively supporting visual understanding and a 1M token context, priced at $1.5 per million input tokens. The company claims it cuts cost per task by 62% on the Work360 benchmark, seen as a signal that large-model competition is shifting from "stacking parameters" to "cost per task." The article analyzes how MoE sparse activation decouples capability from inference cost, the extremely high demands of 1M context and native multimodality on inference infrastructure, and the difference between task-level cost and per-token pricing. It also notes Alibaba's dual-track commercialization path of open-source ecosystem plus proprietary flagship, while long-context retrieval precision and multimodal performance still await third-party validation.
Related articles
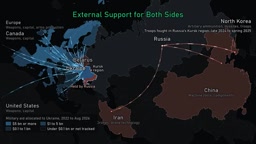
How Did North Korea Become a Key Foreign Backer of Russia's War Machine? A Deep Dive from the Lex Fridman Podcast
Lex Fridman Podcast military analysis reveals the foreign support structure of the Russia-Ukraine war: North Korea once supplied 40% of Russian artillery ammunition and sent troops, Russia's war spending is 9%-10% of GDP but its economic structure is deteriorating, while Ukraine relies heavily on Western support and faces U.S. policy uncertainty.
Ressa's New Book: Why Tech Oligarchs Are a Threat on Par With Dictators
Maria Ressa explains in a Vox 'The Gray Area' interview why she calls Zuckerberg and Duterte both dictators, Facebook's role in the Philippines drug war, the tech oligarch accountability gap, and how ordinary people can fight back by auditing feeds, building open-source tech, and taking offline action.
A Black Hole Hiding at the Edge of the Solar System? An Alternative Explanation for Planet Nine
Could Planet Nine at the solar system's edge be a primordial black hole? Explore the origins, evidence, and controversy behind this orbital anomaly hypothesis.