AlphaGenome 2: Google AI Decodes Disease Roots at the Cellular Level
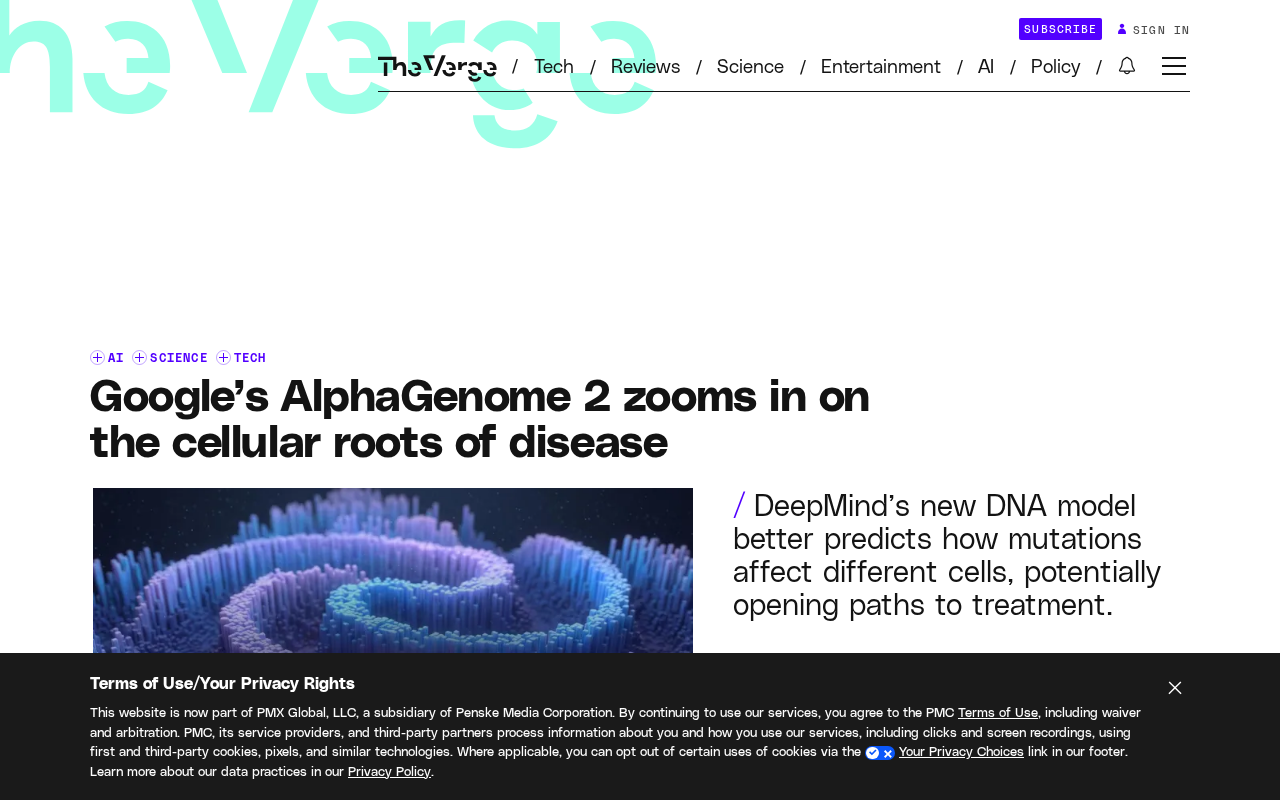
DeepMind releases AlphaGenome 2 to predict regulatory effects of DNA variants across cell types.
Google DeepMind launches AlphaGenome 2, an AI model focused on how DNA variants produce different effects across cell types. Most disease-associated variants lie in non-coding regulatory regions, and the same variant can behave completely differently in liver cells versus neurons. The model continues the sequence-to-phenotype approach but zooms in on cell-type differences to help prioritize biologically meaningful targets. No performance metrics or benchmarks were disclosed.
Google DeepMind has released AlphaGenome 2, a next-generation AI model aimed squarely at a long-standing challenge in genetics: how variants in DNA sequences produce vastly different effects across different cell types. This is more than a technical iteration—it could change how scientists hunt for disease causes and drug targets.
From Sequence to Cell: Where the Core Problem Lies
The vast majority of disease-associated variants in the human genome do not directly alter protein coding; instead, they fall in regulatory regions—segments that determine when, where, and how strongly a gene is expressed. The same variant may be inconsequential in liver cells yet trigger a cascade in neurons.
According to Google DeepMind, the core capability of AlphaGenome 2 lies in predicting how changes in DNA sequence affect different cell types, giving researchers a more granular lens on the cellular roots of disease. The importance of this direction is clear: the genetic signals for many complex diseases (such as neurodegenerative and metabolic disorders) are concentrated precisely in these non-coding regulatory regions, which traditional methods struggle to systematically parse.
Non-coding regulatory regions refer to DNA segments in the genome that do not directly encode proteins but are responsible for regulating gene expression, including promoters, enhancers, silencers, and insulators. About 98% of the human genome consists of non-coding sequence, a substantial portion of which is functional in regulation. Enhancers can act at positions hundreds of thousands of base pairs away from their target genes, making spatial contact with promoters through three-dimensional chromatin folding. More than 90% of disease-associated variants identified by GWAS (genome-wide association studies) lie in these non-coding regions and are often enriched in open chromatin and histone modification marks specific to particular cell types—which explains why the same variant can have drastically different effects across tissues.
Regulatory genomics is the branch of study concerned with how gene expression is encoded and regulated by genomic sequence. Its core tasks include identifying regulatory elements, characterizing their cell-type specificity, and predicting the effects of variants on regulatory activity. In recent years, the field has relied heavily on two types of resources: first, multi-tissue, multi-cell-type annotation data from large-scale epigenomic mapping projects such as ENCODE and Roadmap Epigenomics; second, deep learning-based sequence-to-function prediction models such as DeepSEA, Basenji, and Enformer. These models take DNA sequence as input and directly predict experimental readouts such as ChIP-seq, ATAC-seq, and RNA-seq, thereby assessing the regulatory consequences of variants without wet-lab experiments. The AlphaGenome series advances along this same paradigm.
Positioning of AlphaGenome 2: Inheritance and Advance
AlphaGenome 2 is the successor to the previous model. The original coverage describes it as an upgraded version of the AlphaGenome series, emphasizing its refined ability to dissect the relationship between DNA variants and cellular function.
Based on available information, the model's design logic continues the approach of "predicting molecular phenotypes directly from genomic sequence," but pushes the focus further down to the level of cell-type differences. This means researchers can pose more precise questions about specific cellular contexts rather than settling for single, generic genome annotations. This is particularly valuable for experimental designs that require cross-cell-type comparisons—for example, determining whether a candidate variant is functional only in specific tissues.
Potential Significance for Disease Research
DeepMind says the tool could provide important clues to the causes of disease and point toward new therapeutic paths. The logic is straightforward: if the regulatory consequences of a variant in a specific cell can be determined more accurately, truly biologically meaningful targets can be prioritized, reducing blind spots in downstream validation.
One caveat: the original material did not disclose the model's specific performance metrics, the number of cell types covered, or benchmark results. Judgments about its actual capabilities should therefore remain cautious—the model's value ultimately depends on its reproducibility and predictive accuracy in real research settings, which require independent experimental validation.
Wet-lab validation refers to experimental work that empirically tests computational predictions using biological systems such as cell culture, organoids, and animal models, as opposed to dry-lab computational analysis. In regulatory variant research, common validation approaches include reporter gene assays (such as MPRA, massively parallel reporter assay), detecting changes in target gene expression after CRISPR interference or base editing, and confirming chromatin state changes with ATAC-seq and ChIP-seq. Only after such experimental validation can a model-predicted variant effect be confirmed as biologically real. The hit rates of different models' predictions in wet-lab experiments vary widely, and this is one of the core metrics for evaluating the practical value of sequence-to-function models.
Questions That Remain
AlphaGenome 2 operates in a highly competitive space, with multiple teams advancing sequence-based regulatory genomics prediction models. Whether its differentiated advantages hold up depends on three factors: generalization to rare cell types, modeling quality for long-range regulatory interactions, and validation rates in wet-lab experiments.
Moreover, the path from tool to actual drug discovery remains long. AI prediction can narrow the candidate pool, but causal validation at the cellular level still depends on experimental science. The more realistic positioning of AlphaGenome 2 is as an efficient aid for researchers in the hypothesis-generation stage—not as a replacement for the endpoint of experimentation.
Long-range regulatory interactions refer to regulatory relationships between enhancers and other regulatory elements and target gene promoters spanning tens to hundreds of kb of genomic distance, whose establishment often depends on chromatin looping and the three-dimensional genome structure mediated by CTCF/cohesin. Accurate modeling of such interactions is one of the main difficulties for current sequence-to-function prediction models: one-dimensional sequence models have limited receptive fields and struggle to directly capture distal elements, while three-dimensional conformation data such as Hi-C and Micro-C are insufficiently covered in most cell types, limiting the scale of supervision signals. Whether long-range regulatory connections can be inferred generically in unseen cell types is a key dimension distinguishing the capabilities of different models.
One-line Summary
DeepMind releases AlphaGenome 2 to predict the regulatory effects of DNA variants across different cell types.
Paragraph Summary
Google DeepMind has launched AlphaGenome 2, a next-generation AI model focused on how DNA variants produce differentiated effects across cell types. The article notes that the vast majority of disease-associated variants lie in non-coding regulatory regions, and that the same variant can have completely different consequences in liver cells versus neurons—precisely the core problem the model seeks to address. AlphaGenome 2 continues the approach of predicting molecular phenotypes directly from genomic sequence but pushes the focus down to the level of cell-type differences, potentially helping researchers prioritize biologically meaningful disease targets. The original coverage did not disclose performance metrics, the number of cell types covered, or benchmark results; its actual value still depends on generalization ability, long-range regulatory modeling quality, and wet-lab validation rates.
Related articles
11 Tested Rules to Slash Claude Token Costs to the Bare Minimum
Claude Token costs too high? Creator Doobie rewrote 11 token-saving rules after 30 days of logs: keep effort at medium, use /clear when switching tasks, don't let cache expire, downgrade auxiliary agents to Haiku—with official Anthropic data and cost comparisons.
Build Your First AI Agent with Zero Code: A Claude Code Practical Guide
Build an AI agent in Claude Code with zero code. Learn the full workflow: folder setup, claude.md rulebook, plan-mode briefs, skills, and independent review.
Claude Code Advisor Mode Explained: How Fable 5.2 and Sonnet 5.5 Collaborate on Code
A deep dive into Claude Code's experimental Advisor mode: how Fable 5.2 and Sonnet 5.5 split the work, access requirements, version thresholds, three ways to enable it, Fable's special billing rules, and a fact-check of the "3.4x cost reduction" claim against official docs.