AlphaGenome 2 Released: DNA Variant Prediction Achieves Cell-Type-Level Precision
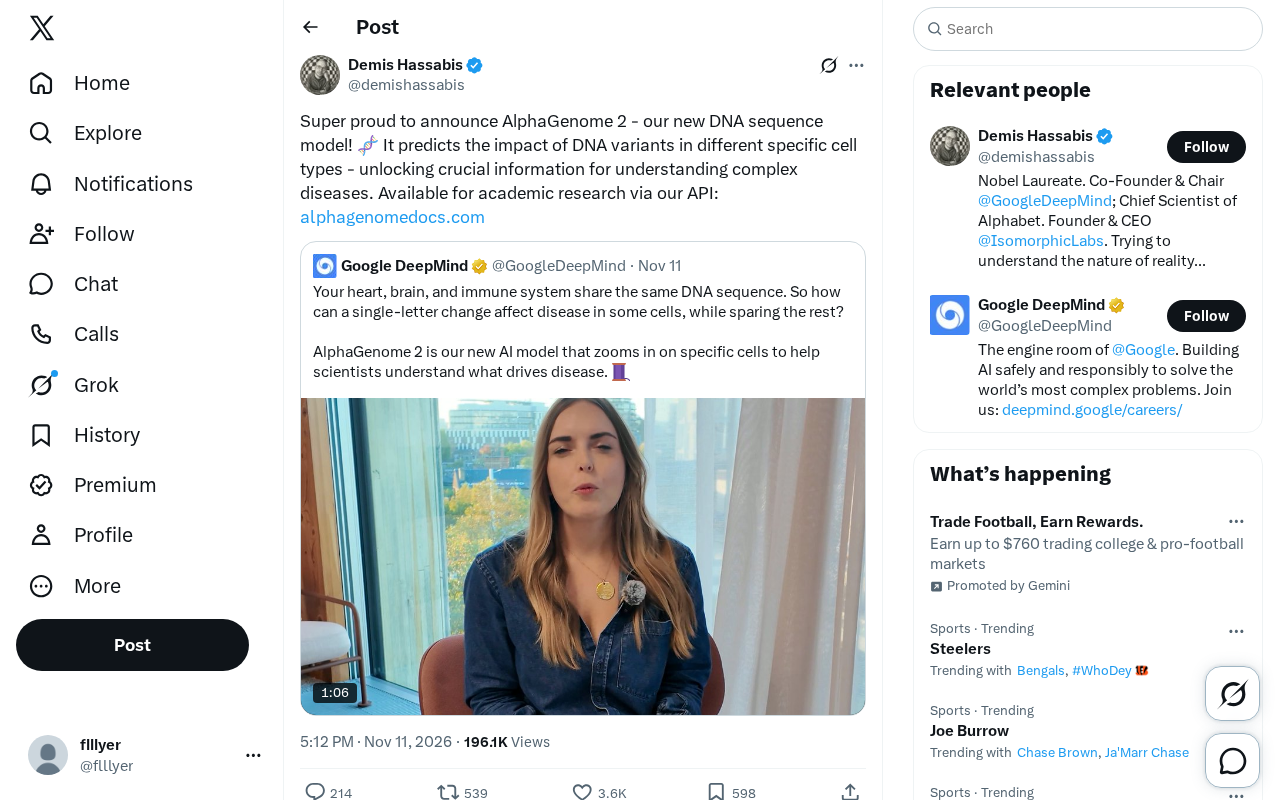
AlphaGenome 2 predicts DNA variant effects along the cell-type dimension, targeting non-coding variant interpretation in complex diseases.
AlphaGenome 2 is a new DNA sequence model that predicts the functional impact of DNA variants in specific cell types rather than giving generic averaged variant scores. The article notes that complex diseases largely involve weak-effect variants in non-coding regions that regulate gene expression in a highly cell-context-dependent manner, making cell-type-specific prediction more actionable for GWAS interpretation and drug target discovery. The model is currently available to academic research via API, lowering compute and reproduction barriers. But the announcement lacks model architecture, training data scale, benchmark performance, and API usage details, and does not clarify industry access, so the author urges caution until independent evaluation and peer review are available.
From Sequence to Disease: What Problem Does AlphaGenome 2 Aim to Solve
A core challenge in genomics is: why does the same DNA variant produce completely different consequences in different cells? The release of AlphaGenome 2 is aimed squarely at this question. According to the announcement on Twitter, this is a new DNA sequence model capable of predicting the impact of DNA variants in specific cell types, thereby providing key information for understanding complex diseases.

Traditional variant effect prediction tools often give an "averaged" answer that ignores tissue specificity. Yet many complex diseases—from autoimmune diseases to neurodegenerative disorders—exhibit pathological features only in specific cellular contexts. AlphaGenome 2 treats "cell type" as a fundamental dimension of prediction, a design choice that is inherently more biologically meaningful than generic variant scoring.
Cell-Type Specificity: A Key Angle for Complex Disease Research
The announcement repeatedly emphasizes "different specific cell types"—this is not a casual modifier. The genetic basis of complex diseases typically consists of a large number of variants with weak effects, and these variants often fall in non-coding regions, acting through the regulation of gene expression. Regulatory logic is highly dependent on cellular context: an enhancer sequence may be active in hepatocytes but silent in neurons.
Therefore, the ability to predict variant effects by cell type means researchers can map candidate loci from genome-wide association studies directly onto specific cellular contexts for interpretation. For drug target discovery, this is closer to actionable leads than a global pathogenicity score. The announcement explicitly positions "understanding complex diseases" as the core application scenario, with a clear focus.
Non-coding regions account for approximately 98% of the human genome, and the vast majority of disease-associated variants identified by genome-wide association studies (GWAS) fall in this region rather than in protein-coding sequences. These variants do not alter protein structure but instead change gene expression levels by affecting the activity of regulatory elements such as enhancers, promoters, and insulators. Because the same regulatory element is controlled by different combinations of transcription factors and chromatin states in different cell types, its activity is strongly tissue-specific. This is precisely why a variant may produce functional consequences only in specific cellular contexts, and why cell-type-resolved variant effect prediction is regarded as a key step in interpreting the downstream mechanisms of GWAS signals.
API Access: Usability Design for Academic Research
AlphaGenome 2 is currently open to academic research through an API. This distribution approach is noteworthy: it lowers the barrier to use, allowing researchers to embed variant effect prediction into their own analysis pipelines without having to reproduce the model or prepare large-scale compute resources.
However, the announcement provides limited information. Key details such as API call limits, the range of supported cell types, input formats, and output granularity are not disclosed. For researchers planning to adopt the model in actual projects, these are core parameters that determine usability and should be confirmed against official documentation.
In genomics, the usability of deep learning models has long been constrained by compute and engineering barriers: a large-scale DNA sequence model often requires tens to hundreds of GPUs for training, making reproduction and deployment extremely costly. Providing inference as an API service means researchers only need to upload variant loci and target cell types to obtain predictions, effectively packaging model capabilities as a cloud service. This distribution model has precedents in protein structure prediction and has significantly expanded adoption among researchers without computational backgrounds. But its limitations are also obvious: researchers cannot fine-tune the model on their own data, nor can they deeply inspect the model's internal representations. For projects with high requirements for methodological transparency, API encapsulation may pose a certain obstacle.
A Measured View: Gaps Beyond the Announcement
This release information is essentially a product announcement, not a technical paper. Model architecture, training data scale, benchmark performance, and comparisons with existing methods are all absent from the announcement. For a fast-iterating direction like DNA sequence models, the lack of benchmark data means it is impossible to judge how large its relative advantage actually is.
Another practical constraint is the limited scope of "academic research." The announcement does not state whether industry users can gain access or whether commercial use is restricted. This will affect the model's actual penetration speed in translational research.
Overall, the direction proposed by AlphaGenome 2—cell-type-specific variant effect prediction—addresses a real pain point in the genetics of complex diseases. But until independent evaluations and technical details are made public, judgment of its capabilities should remain cautious. Functional interpretation of non-coding variants remains one of the hardest open problems in genomics, and whether a model can substantially advance this field must ultimately be answered through peer review and reproducible benchmarks.
Evaluating the benchmark performance of DNA sequence models typically relies on several types of public tasks: variant effect prediction (e.g., distinguishing eQTL-positive from negative variants), regulatory element activity prediction, gene expression prediction, and chromatin state prediction. Commonly referenced evaluation frameworks include the ability to reproduce eQTL signals in cohorts such as GTEx, as well as generalization performance on held-out chromosomes or held-out cell types. Without such benchmark data, it is impossible to determine whether a model truly outperforms existing sequence-to-function models, nor to rule out the possibility of performance degradation on cell types outside its training distribution. For models claiming cell-type resolution, cross-cell-type generalization capability is especially worthy of independent testing.
One-line Summary
AlphaGenome 2 predicts DNA variant effects along the cell-type dimension, directly targeting the challenge of interpreting non-coding variants in complex diseases.
Paragraph Summary
AlphaGenome 2 is a new DNA sequence model whose core design is to predict the functional impact of DNA variants in specific cell types rather than providing generic averaged variant scores. The article notes that the genetic basis of complex diseases largely consists of weak-effect variants in non-coding regions that act by regulating gene expression, and that regulatory logic is highly dependent on cellular context—making cell-type-specific prediction more actionable for mechanistic interpretation of GWAS candidate loci and drug target discovery. The model is currently available to academic research via an API, lowering compute and reproduction barriers. However, the announcement does not disclose model architecture, training data scale, benchmark performance, or API usage details, nor whether industry users can access it. The author therefore recommends maintaining a cautious judgment of its capabilities until independent evaluation and peer review are available.
Related articles
11 Tested Rules to Slash Claude Token Costs to the Bare Minimum
Claude Token costs too high? Creator Doobie rewrote 11 token-saving rules after 30 days of logs: keep effort at medium, use /clear when switching tasks, don't let cache expire, downgrade auxiliary agents to Haiku—with official Anthropic data and cost comparisons.
Build Your First AI Agent with Zero Code: A Claude Code Practical Guide
Build an AI agent in Claude Code with zero code. Learn the full workflow: folder setup, claude.md rulebook, plan-mode briefs, skills, and independent review.
Claude Code Advisor Mode Explained: How Fable 5.2 and Sonnet 5.5 Collaborate on Code
A deep dive into Claude Code's experimental Advisor mode: how Fable 5.2 and Sonnet 5.5 split the work, access requirements, version thresholds, three ways to enable it, Fable's special billing rules, and a fact-check of the "3.4x cost reduction" claim against official docs.