Apple AI Partners with Alibaba for China Launch, Huawei Super Node Lights Up | AI Daily
Apple Intelligence China edition integrates Qwen, Ascend super node lights up, Kimi and SenseTime push on-device and efficiency.
This edition of AI Daily covers recent developments across compute, devices, and models. Apple confirms its partnership with Alibaba, integrating Tongyi Qianwen at the system level for Apple Intelligence in China, deeply merged with Siri, Writing Tools, and Visual Intelligence — developer beta next week, full release in December — marking a shift of model entry points from the app layer to the system layer. Huawei's first Ascend 950DT thousand-card liquid-cooled super node lights up in Wuhan with E-flops-level single-node compute, paired with Inner Mongolia's ten-thousand-card pool debugging; DeepSeek plans to deploy at least 160,000 Ascend chips for inference. On the model side, Kimi launches 3D Make, using natural language to generate scripts that drive Blender and CAD; SenseTime open-sources Loop-9B, trading recurrent attention and parameter sharing for efficiency, runnable locally with 16GB RAM. Internationally, Google runs a model on satellite TPUs, and Anthropic renames Max to Ultra and removes the 5-hour rolling limit for verified users.
Apple Intelligence's entry into China has finally been confirmed, but the star is not ChatGPT — it's Alibaba's Qwen. Meanwhile, Huawei's Ascend makes further strides in compute infrastructure, Kimi brings 3D modeling into the chat box, and SenseTime challenges the limits of large models with a 9B small model. This edition of AI Daily breaks down the signals behind these developments across three lines: compute, devices, and models.
Apple Intelligence in China: Qwen Integrated at the System Level, Fully Merged with Siri and Writing Tools
Apple has officially confirmed its partnership with Alibaba to integrate Tongyi Qianwen at the system level. According to a breakdown by Bilibili creator Will叔, the China-market Apple Intelligence will be deeply integrated into Siri, Writing Tools, and the Visual Intelligence system. Users can access it directly without a VPN, with a developer beta rolling out next week and a full release in December.
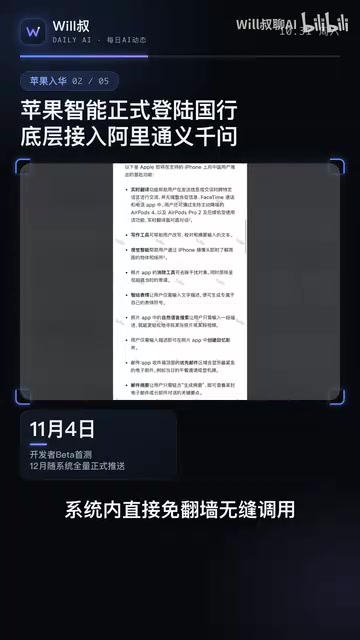
The key here isn't that "Apple now has AI" — it's the localization of the access path. Previously, overseas Apple Intelligence relied on OpenAI's model services, and the China version needed a compliant and usable alternative. Qwen fills exactly that slot. For Alibaba, this means Tongyi Qianwen gains a system-level entry point across hundreds of millions of iOS devices, with model capabilities packaged as an underlying service users never need to think about. For Apple, using a local model means features ship on schedule.
Worth noting is the phrase "system level." If Qwen is invoked at the layer of system components like Siri, Writing Tools, and Visual Intelligence rather than as a standalone app, model distribution efficiency will far exceed that of AI apps in the App Store. This is a clear competitive signal to other domestic model vendors: the battle for entry points is moving from the app layer up to the system layer.
Huawei Ascend Thousand-Card Super Node Lights Up, Domestic Compute Moves Toward Clustering
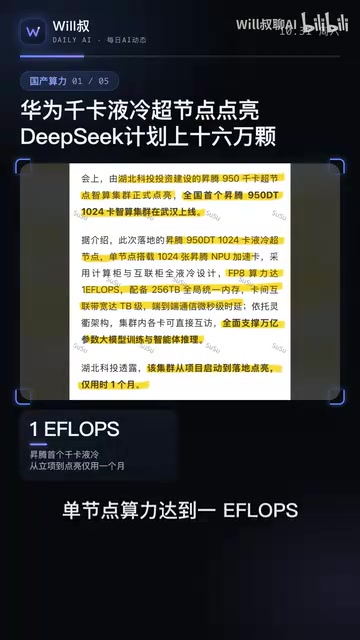
Huawei's first Ascend 950DT thousand-card liquid-cooled super node has officially lit up in Wuhan, achieving E-flops-level single-node compute and microsecond-level interconnect capability. According to Will叔's Daily AI Updates, the Inner Mongolia ten-thousand-card pool has also completed joint debugging, and DeepSeekAd plans to deploy at least 160,000 Ascend chips locally for inference.
The significance of the thousand-card super node lies in shifting the narrative from "single-card performance" to "cluster efficiency." The bottleneck in large model inference is often not single-chip compute but inter-card communication and heat dissipation — liquid cooling plus microsecond-level interconnect targets exactly these two pain points. E-flops-level single-node compute combined with ten-thousand-card pool debugging points to large-scale deployment capability on the inference side, not training.
DeepSeek's local deployment of at least 160,000 Ascend chips for inference is the most concrete footnote to this direction. Inference workloads have lower ecosystem compatibility requirements than training, making domestic chips more viable on this side. If this deployment proceeds as planned, it will become an observable sample of domestic compute carrying inference services for a leading model.
Super Node is an architectural concept that has emerged in AI compute infrastructure in recent years, referring to systems that tightly couple tens to thousands of accelerator cards through high-speed interconnect networks, logically serving as a single massive compute unit. Unlike traditional cluster models where "multiple servers operate independently," super nodes emphasize low latency and high bandwidth in inter-card communication, with typical metrics including interconnect latency (microsecond-level) and aggregate compute (e.g., E-flops level). Huawei, NVIDIA, and other vendors are all advancing similar architectures, aiming to enable distributed inference strategies like tensor parallelism and expert parallelism for large models to run efficiently at greater scale. The engineering challenges of super nodes lie mainly in interconnect topology, liquid-cooling heat dissipation, and fault isolation — which explains why the report specifically highlights "liquid cooling" and "microsecond-level interconnect" as the two key parameters.
E-flops (Exaflops) is a unit of compute measurement, where 1 E-flops equals 10^18 floating-point operations per second. For reference, current top-tier single AI accelerator cards typically deliver compute in the tens of petaflops (P-flops) range, so "single-node E-flops" means the node aggregates hundreds or thousands of cards. Note that vendor-claimed compute figures are often peak theoretical values at specific precision (e.g., FP16 or INT8), and actual effective compute is discounted by communication overhead, memory bandwidth, and model architecture.
Kimi Launches 3D Modeling: One Sentence Connects Directly to Blender and CAD
Moonshot AI has launched a 3D Make feature for Kimi, supporting one-sentence direct connection to Blender and CAD tools — writing scripts, building models, and assembling scenes in one go. Whether from sketches or text input, it can rapidly generate spatial structures and export them directly to 3D software.
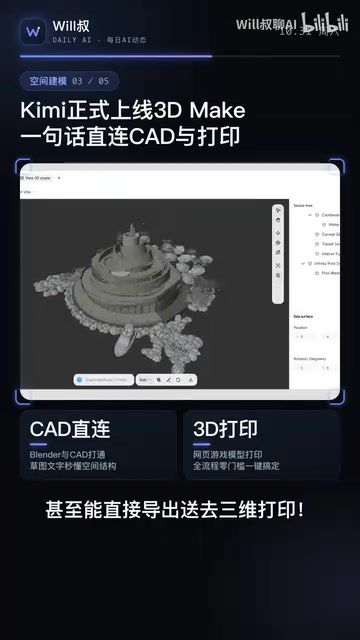
The essence of this feature is compressing the pipeline from natural language to 3D assets into a single conversation. In traditional workflows, going from idea to editable model requires crossing the threshold of modeling software operation. Kimi's approach is to have the model generate scripts that drive Blender and CAD, handing off "knowing how to write scripts" to AI. For non-professional modeling users, this expands capability boundaries; for professional users, it's more of a tool to accelerate the sketching phase.
3D content generation isn't new, but connecting directly to mature toolchains rather than building a proprietary rendering pipeline is the more pragmatic choice. Exported models can enter existing workflows, meaning they have a chance to be genuinely used rather than staying in demo videos.
Blender is an open-source 3D creation software supporting the full pipeline of modeling, sculpting, animation, and rendering, and provides a Python API through which scripts can programmatically generate and modify geometry, materials, and cameras in a scene. CAD (Computer-Aided Design) is more oriented toward engineering and industrial design, emphasizing precise dimensions and parametric constraints. What both share is that they provide scripting interfaces, enabling large models to "operate" the software by generating code rather than building their own 3D rendering or geometry engines. This "model generates scripts, scripts drive tools" pattern essentially positions the large model as an orchestration layer between natural language and professional software. Output quality depends on API coverage and script executability rather than the model directly generating 3D meshes. Compared to end-to-end 3D generation models, this path is easier to integrate into existing production workflows.
SenseTime Open-Sources Loop-9B: Trading Parameters for Efficiency with Recurrent Attention
SenseTime has open-sourced the Loop-9B model, which uses recurrent attention and parameter sharing mechanisms to trade parameter count for computational depth. According to reports, the model outperforms some larger-parameter models on complex tasks and runs smoothly locally with just 16GB of RAM, pushing on-device capability to a high level.
The small-model-punching-above-its-weight approach centers on replacing "stacking parameters" with "stacking computation steps." Recurrent attention lets the same set of parameters be called repeatedly, while parameter sharing compresses model size — at the cost of increased computational depth during inference. The value of this approach lies in on-device deployment: the 16GB memory threshold means it can run on consumer-grade devices without relying on the cloud.
This contrasts with the aforementioned Huawei Ascend inference deployment. One end clusters massive compute; the other compresses models into local devices. The two paths solve problems in different scenarios. If models like Loop-9B perform stably on-device, they will drive more AI features from the cloud down to local devices.
Recurrent Attention and Parameter Sharing are two common approaches to improving model parameter efficiency. The idea behind recurrent attention is to have the same set of Transformer layers (or attention weights) called repeatedly during inference, effectively increasing "computational depth" without increasing parameter count, allowing the model to perform multiple rounds of iterative processing on complex inputs. Parameter sharing has different layers reuse the same set of weights, directly compressing model size. The common cost of both is increased computation steps or serial depth during inference, making them more sensitive to latency and memory bandwidth. This approach contrasts with the Scaling Law philosophy of "stacking parameters and data" and is more relevant in on-device deployment scenarios, where the bottleneck for consumer devices is typically memory capacity rather than peak compute. Loop-9B's 16GB memory threshold is a direct reflection of this design orientation.
Google AI Goes to Space, Anthropic Adjusts Subscription Limits
Internationally, Google has taken AI to space — TPU chips on a satellite successfully ran a model in orbit and wrote their first poem. According to Will叔's Daily AI Updates, this marks the beginning of Earth-based compute extending toward orbit.
Running TPU in orbit is more about validation than practical utility: the radiation, heat dissipation, and communication conditions in space differ vastly from those on the ground, and getting a model to run at all is itself an engineering validation. In the short term, it has limited impact on everyday AI applications, but it provides a reference for future on-satellite data processing.
Another piece of news: Anthropic has officially announced that Max is being renamed Ultra, and the 5-hour rolling limit for verified users is being removed. The subscription-tier adjustment reflects the trade-off between inference costs and user retention — usage limits for heavy users have always been a sensitive point for AI subscription products.
The Common Trend Behind These Three Threads
Looking at these developments together, compute, devices, and model efficiency are all advancing simultaneously. Huawei's Ascend thousand-card super node and ten-thousand-card pool point to clustered inference infrastructure; Apple's partnership with Qwen brings models into system-level entry points; and Kimi's 3D Make and SenseTime's Loop-9B each push forward at the application and efficiency layers respectively.
For developers and product teams, two signals are worth watching: first, the opening of system-level AI entry points will change app distribution logic; second, on-device runnable small models are becoming practical. The former affects customer acquisition paths, the latter affects feature architecture.
Related articles
 Tech Frontiers
Stylome Bot Slammed as Useless Junk: Why Do AI Detection Tools Keep Failing?
Reddit users test the Stylome AI detection bot: Gemini-rewritten text judged human-written, consistently low confidence. An analysis of AI text detection's technical dilemmas, privacy concerns, and credibility crisis in community governance.
 Tech Frontiers
When AI Becomes a Productivity Divide: Clarity or "AI Psychosis"?
A civil engineer's deep use of agentic AI boosted efficiency but bred contempt for peers who refuse to learn. Is this clarity or AI psychosis? An analysis of the cognitive and psychological challenges behind the AI productivity divide.
 Tech Frontiers
Opus 5.5 Benchmark Scores Climb, Community Says Its "Weights Are Blessed"
Reddit community discusses Opus 5.5's rising scores on the Benchmaxxing Bench, with users describing its performance as "weights are blessed." This article interprets the community reaction and cautions against conflating benchmark scores with real capability.