Arborformer: A Language Model That Replaces Transformers with Pure Decision Trees
A Reddit user showcases Arborformer, a pure decision-tree language model, sparking discussion on the feasibility of non-Transformer architectures.
A researcher on Reddit presented an experimental project called Arborformer, which attempts to build a language model using pure decision trees instead of Transformers. Decision trees capture token dependencies through conditional branches and offer interpretability advantages, but the community questions their expressiveness and scalability, especially regarding long-range dependency modeling and node explosion. The project currently lacks public benchmark data, so discussion remains largely conceptual. The article argues that such exploration reflects reflection on single-architecture monopoly and offers new ideas for non-Transformer approaches, though Arborformer remains an early proof of concept whose practicality awaits verification.
On Reddit, a researcher showcased an experimental project called "Arborformer" — a language model built entirely on decision trees, aiming to replace the Transformer architecture. The concept sparked discussion in the community, with curiosity about the non-neural-network approach as well as skepticism about its feasibility.
What Is a Decision Tree Language Model?
Traditional language models almost all rely on the Transformer's attention mechanism, whereas Arborformer's core idea is to use decision trees as the sole modeling unit. A decision tree partitions input through a series of conditional branches and ultimately produces a prediction. Applying this structure to language modeling means the model does not rely on matrix multiplication and attention weights, but instead captures conditional dependencies between tokens through tree-like rules.
This design is reminiscent of early rule-based natural language processing, but Arborformer attempts it at the scale of a language model. The author emphasizes that it is "100% decision tree," meaning the entire inference path consists of tree nodes with no hidden neural network layers.
Decision tree is a classic supervised learning model that recursively selects optimal features to partition data, forming a tree structure: internal nodes correspond to judgment conditions on features, and leaf nodes give predictions. Its training process typically selects split points based on criteria such as information gain or Gini impurity, and at inference time a new sample follows branches to a leaf node to obtain the output. Decision trees are naturally interpretable and do not rely on matrix multiplication. However, a single tree is prone to overfitting, and in practice ensemble methods (such as random forests and gradient boosted trees) are often used to improve performance. Using decision trees for language modeling means handling high-dimensional sparse token features and designing tree structures suitable for sequence prediction, which differs significantly from traditional classification tasks.
Why Are Some People Trying Non-Transformer Approaches?
Transformer's dominance in language modeling is firmly established, but it also suffers from high computational cost and weak interpretability. Decision trees, by contrast, are inherently interpretable: each branch corresponds to explicit feature conditions, and the inference process can be traced step by step. For scenarios requiring auditing or understanding of model decisions, this transparency is attractive.
In addition, the computational patterns of decision trees in training and inference differ from neural networks, and in theory they may be more efficient on certain hardware. However, whether these advantages can be realized in language model tasks remains without publicly available benchmark data.
Transformer's core is the self-attention mechanism, which allows the model to directly model dependencies between any two positions in a sequence, but computational complexity grows quadratically with sequence length and requires extensive matrix operations. In contrast, non-Transformer approaches such as state space models (SSM), convolutional architectures, and recurrent neural networks attempt to reduce computational cost or improve interpretability through different inductive biases. For example, SSMs process long sequences through linear recurrence with linear complexity; decision trees provide symbolic reasoning paths. These explorations are not intended to completely replace Transformer, but to offer alternatives for specific scenarios (such as long context, resource constraints, and high interpretability requirements), promoting architectural diversity.
Community Feedback and Core Skepticism
The original poster explicitly stated they were "seeking feedback," indicating the project is still in an early stage. Reddit community discussion focused on several aspects:
- Expressiveness: Are the depth and number of branches of decision trees sufficient to capture long-range dependencies in natural language?
- Scalability: As vocabulary grows and context lengthens, the number of tree nodes may expand dramatically, making training and storage costs challenging.
- Comparison with Transformer: The lack of public evaluation results makes it difficult to judge actual performance.
These concerns point to a core question: can decision trees achieve the expressiveness required for language models while maintaining interpretability? So far the author has not disclosed training data scale, parameter count, or benchmark scores, so the discussion remains largely at the conceptual level.
Long-range dependencies refer to semantic associations between tokens that are far apart in a sequence (such as pronoun reference and discourse coherence). Transformer can directly model dependencies at any distance through attention, whereas decision trees rely on branch conditions to partition layer by layer, and with limited depth it is difficult to cover long-distance relationships. If depth and branch count are increased to compensate, the number of tree nodes expands exponentially, leading to uncontrollable training and storage costs. In addition, language models need to handle open vocabularies and variable-length contexts, and decision trees also face challenges in partitioning efficiency for continuous features and sparse tokens. These factors together constitute the core skepticism about the expressiveness of decision trees.
Significance for AI Architecture Exploration
Although Arborformer's practicality remains to be verified, such attempts reflect the community's reflection on the monopoly of a single architecture. In recent years, non-Transformer approaches such as state space models and hybrid architectures have continued to emerge, exploring different inductive biases. If a decision tree language model can demonstrate feasibility on small-scale tasks, it may offer new ideas for interpretable language models.
For developers concerned with AI architecture diversity, this project is worth following. The author is collecting feedback on Reddit and may disclose more technical details and experimental results later.
Conclusion
Arborformer is currently more of a proof of concept than a mature product. Its value lies in raising the question: must language models use Transformer? Can decision trees become another option? In the absence of experimental data, these questions remain unresolved, but the discussion itself helps broaden the space for architecture exploration.
Related articles
US SEC Investigates Nvidia: Possible A…
US SEC Investigates Nvidia: Possible Accounting Issues
The US SEC's investigation into Nvidia focuses on potential accounting issues, not products. The news sparked heated discussion on Hacker News, with the market watching the AI chip giant's financial disclosure quality and regulatory signals.

FBI Crime Database Reportedly Hit by Hackers; Trump Says 'Not Good'
FBI's NCIC reportedly hit by hackers; FBI has launched an investigation and Trump said it's 'not good.' This article covers the incident, NCIC's importance, and law enforcement data security challenges.
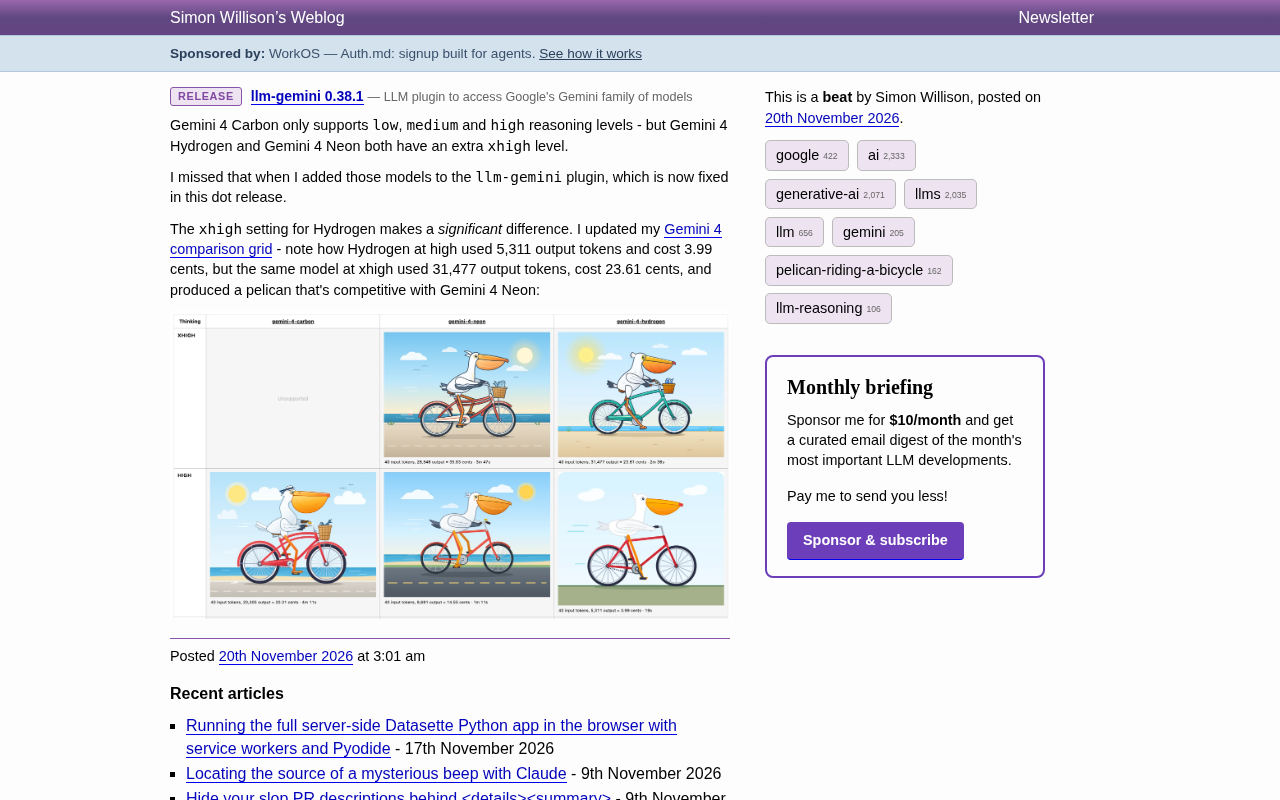
llm-gemini 0.38.1 Fix: Gemini 4 Hydrogen and Neon Gain xhigh Reasoning Level
llm-gemini 0.38.1 fixes the missing xhigh reasoning level for Gemini 4 Hydrogen and Neon. Comparison data shows xhigh sharply raises Hydrogen's output tokens and cost while clearly improving image quality to a level competitive with Neon.