llm-gemini 0.38.1 Fix: Gemini 4 Hydrogen and Neon Gain xhigh Reasoning Level
A minor llm-gemini fix exposes reasoning-level differences among same-generation models and their huge impact on quality and cost.
Simon Willison's llm-gemini plugin released 0.38.1, fixing a configuration oversight: Gemini 4 Carbon supports only low/medium/high reasoning levels, while Hydrogen and Neon additionally support xhigh, which the plugin had not exposed. Using a "pelican riding a bicycle" comparison test, the article shows that reasoning levels are not linear fine-tuning: after Hydrogen switches from high to xhigh, output tokens rise from 5,311 to 31,477 and cost from 3.99 cents to 23.61 cents, with image quality improving significantly to a level competitive with Neon. This shows that default levels may seal off a model's potential. The case further reveals that in multi-model integration, capability-matrix differences among same-generation variants are easily overlooked by plugin authors, and adaptation costs between the tool layer and the model layer will continue to rise.
A minor version update exposes differences in LLM reasoning-level design
Simon Willison's llm-gemini plugin has released version 0.38.1, a dot release that fixes an easily overlooked but not insignificant configuration oversight: Gemini 4 Carbon only supports three reasoning levels—low, medium, and high—while Gemini 4 Hydrogen and Gemini 4 Neon additionally support an xhigh level. The author had missed this discrepancy when adding these models to the plugin earlier, and this update fills the gap.
This seemingly tiny fix actually raises a more discussion-worthy issue: different variants of the same model generation are not consistent in their reasoning-level design, and the choice of reasoning level has an impact on output quality and cost that far exceeds intuition.
The difference xhigh makes: not just "thinking a little longer"
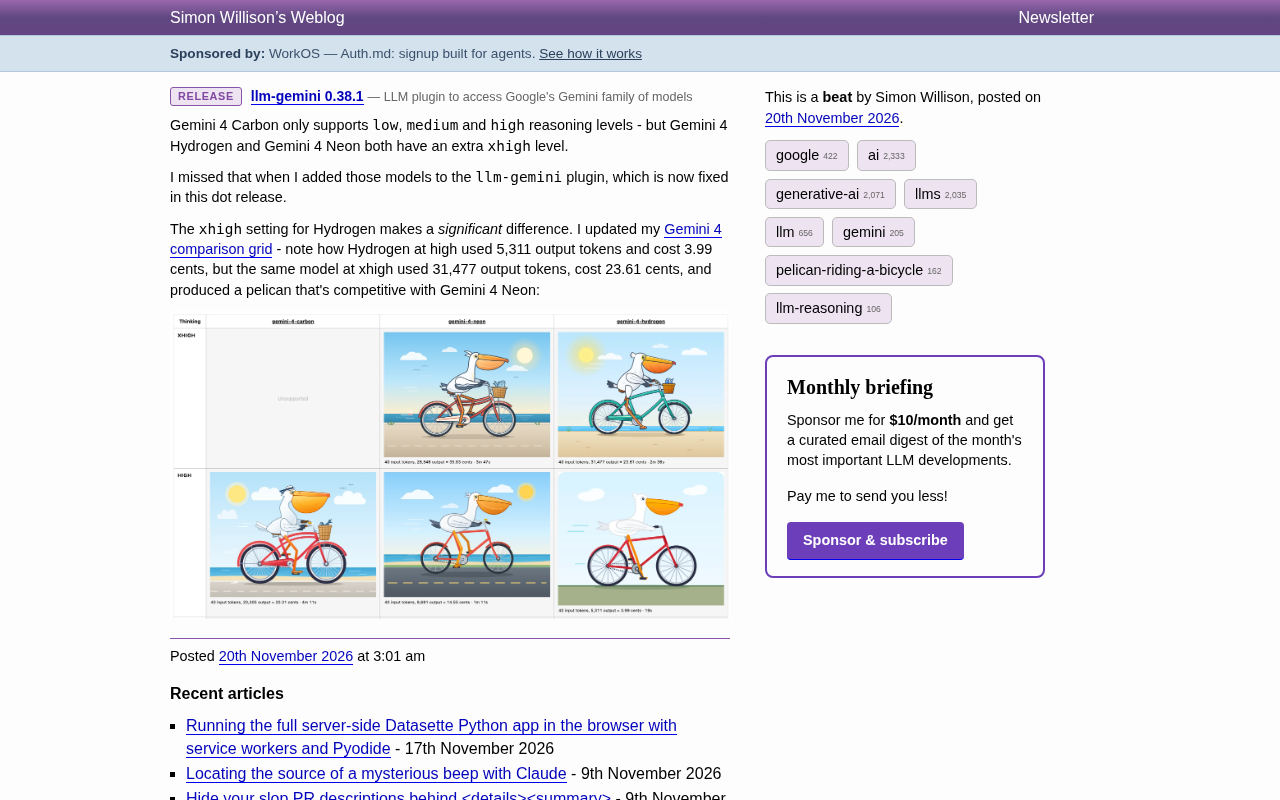
Simon updated his Gemini 4 comparison grid, using the classic "pelican riding a bicycle" prompt to compare the three models side by side at two reasoning levels. The data is telling:
At the high level, Gemini 4 Hydrogen consumed 5,311 output tokens at a cost of 3.99 cents, producing a rather flat pelican image—no bicycle basket, no seascape, just a bird riding a red bicycle on green ground.
After switching to the xhigh level, the same model output 31,477 tokens at a cost rising to 23.61 cents, and the image quality jumped noticeably: the pelican rides a teal bicycle along the beach, with a blue fish in the basket, and the overall composition is comparable to Gemini 4 Neon's output.

This comparison reveals a counterintuitive fact: upgrading the reasoning level is not a linear "small tweak." From high to xhigh, the number of output tokens grows by an order of magnitude and the cost rises sharply as well, but the quality gain is equally significant—in generative tasks, this "trade compute for quality" lever is steeper than many expect.
Positioning differences among Carbon, Neon, and Hydrogen
From this fix, it is clear that the three model variants have a distinct layering in their reasoning-capability design. Carbon, as the base tier, offers only three reasoning levels; Neon and Hydrogen add the xhigh "ultra-high" level.
Interestingly, at the high level, Neon's performance (9,691 output tokens, 14.55 cents) is clearly better than Hydrogen's (5,311 output tokens, 3.99 cents). But once Hydrogen is allowed to use xhigh, the gap narrows substantially: Neon at xhigh outputs 26,546 tokens at 39.83 cents; Hydrogen outputs 31,477 tokens at 23.61 cents. Hydrogen spends less money, outputs more tokens, and reaches image quality competitive with Neon.
In other words, Hydrogen's potential was constrained by the default reasoning level—xhigh is where its real strength lies.
Multi-variant layering within the same generation has become a mainstream release paradigm: vendors derive multiple variants from the same base model through different training recipes, scale trimming, or post-training strategies, targeting different cost and capability ranges. This layering means the differences between variants go beyond "size" and extend to the supported parameter matrix—including context length, tool-calling capability, and the reasoning-level ceiling discussed in this article. For integrators, the right approach is to maintain a matrix with "model × capability dimension" as coordinates, rather than assuming that variants of the same generation share the same parameter space. Variant names (codename-like labels such as Carbon, Neon, and Hydrogen) carry no capability information themselves; official capability tables must be the source of truth, and they must be re-checked whenever models are updated.
Practical impact on developers
For developers using the llm-gemini plugin, this update means that if you previously wondered on Hydrogen or Neon, "why does the same model perform so differently," it was very likely because the reasoning level had not been unlocked to xhigh.
More broadly, this case reminds us that when integrating multi-model APIs, a model capability table is not a checklist that can be taken for granted. Different variants of the same generation may differ in parameter space, reasoning levels, and pricing strategy, and missing one option can leave users unknowingly working with a model that has been "sealed."
Simon openly admitted in the release notes that this was his oversight and dismissed the fix in a single sentence—this lightweight release style itself also shows that detail maintenance of the toolchain is often more easily underestimated than feature development.
Reasoning effort is a common controllable parameter in LLM APIs. It does not change the model weights but adjusts the budget ceiling for the model's internal "thinking" before generating an answer—usually by allowing the model to generate more intermediate reasoning tokens (i.e., chain of thought) and then produce the final answer based on them. Vendors name the levels differently (such as low/medium/high, minimal/low/high, or OpenAI's reasoning effort parameter), but the design logic is consistent: the higher the level, the more reasoning steps the model can allocate and the more likely it is to complete complex tasks with multiple constraints and multiple steps; the lower the level, the faster and cheaper the response, suitable for simple queries or latency-sensitive scenarios. Because reasoning tokens are usually also billed as output tokens, the level directly determines the cost of a single call, making it both a quality lever and a cost lever. Developers need to manage "level" as an independent dimension alongside the model name.
Model adaptation issues in the plugin ecosystem
llm-gemini is a Gemini adapter plugin built around Simon's llm command-line tool. The core value of such plugins is to encapsulate differences among vendor APIs into a unified interface, but encapsulation also means information loss: if the plugin author does not fully keep up with all the capabilities of a given model, end users can hardly perceive where the boundaries are.
Dot releases like 0.38.1 exist precisely to continuously patch this loss. For users, keeping the plugin updated is a necessary action to obtain full model capabilities; for plugin authors, maintaining an accurate model capability matrix has become work that races against API changes.
The scope of this fix is small—it involves only a single reasoning level for two models—but the trend it points to deserves attention: as model variants proliferate and reasoning levels become finer-grained, the adaptation cost between the tool layer and the model layer will only continue to rise.
llm and its plugin system is a command-line tool ecosystem developed by Simon Willison: llm provides a unified CLI and Python API for calling models from different vendors, with each vendor's capabilities adapted by an independent plugin (such as llm-gemini, llm-openai, llm-anthropic). The value of plugins lies in abstracting away differences in authentication, request formats, and response parsing, letting users switch models with the same command; the cost is that plugins become the "gatekeepers" of capability information—parameters not exposed by the plugin cannot be set by users. Therefore, such plugins generally adopt a fast, small-step dot-release cadence to quickly follow API changes. Understanding this architecture helps determine whether a problem lies on the model side or the tool side: when the same model behaves abnormally, first confirming whether the plugin version already covers the relevant parameter is often more effective than suspecting the model itself.
One-line Summary
A minor llm-gemini fix exposes reasoning-level differences among same-generation models and their huge impact on quality and cost.
Paragraph Summary
Simon Willison's llm-gemini plugin released 0.38.1, fixing a configuration oversight: Gemini 4 Carbon supports only three reasoning levels (low/medium/high), while Hydrogen and Neon additionally support xhigh, which the plugin had not exposed. Using a "pelican riding a bicycle" comparison test, the article shows that reasoning levels are not linear fine-tuning: after Hydrogen switches from high to xhigh, output tokens rise from 5,311 to 31,477 and cost from 3.99 cents to 23.61 cents, with image quality improving significantly to a level competitive with Neon. This shows that default levels may seal off a model's potential. The case further reveals that in multi-model integration, capability-matrix differences among same-generation variants are easily overlooked by plugin authors, and adaptation costs between the tool layer and the model layer will continue to rise.
Related articles
US SEC Investigates Nvidia: Possible A…
US SEC Investigates Nvidia: Possible Accounting Issues
The US SEC's investigation into Nvidia focuses on potential accounting issues, not products. The news sparked heated discussion on Hacker News, with the market watching the AI chip giant's financial disclosure quality and regulatory signals.

FBI Crime Database Reportedly Hit by Hackers; Trump Says 'Not Good'
FBI's NCIC reportedly hit by hackers; FBI has launched an investigation and Trump said it's 'not good.' This article covers the incident, NCIC's importance, and law enforcement data security challenges.
Detonating a Large Pile of Lead Azide: A Dangerous Chemical Experiment
Science blog records an experiment detonating a large pile of lead azide, sparking Hacker News debate. This article analyzes lead azide's dangerous properties, experimental risk boundaries, and the scale of reporting dangerous experiments in science communication.