Backup Is Harder Than You Think: The Underestimated Engineering of Data Protection
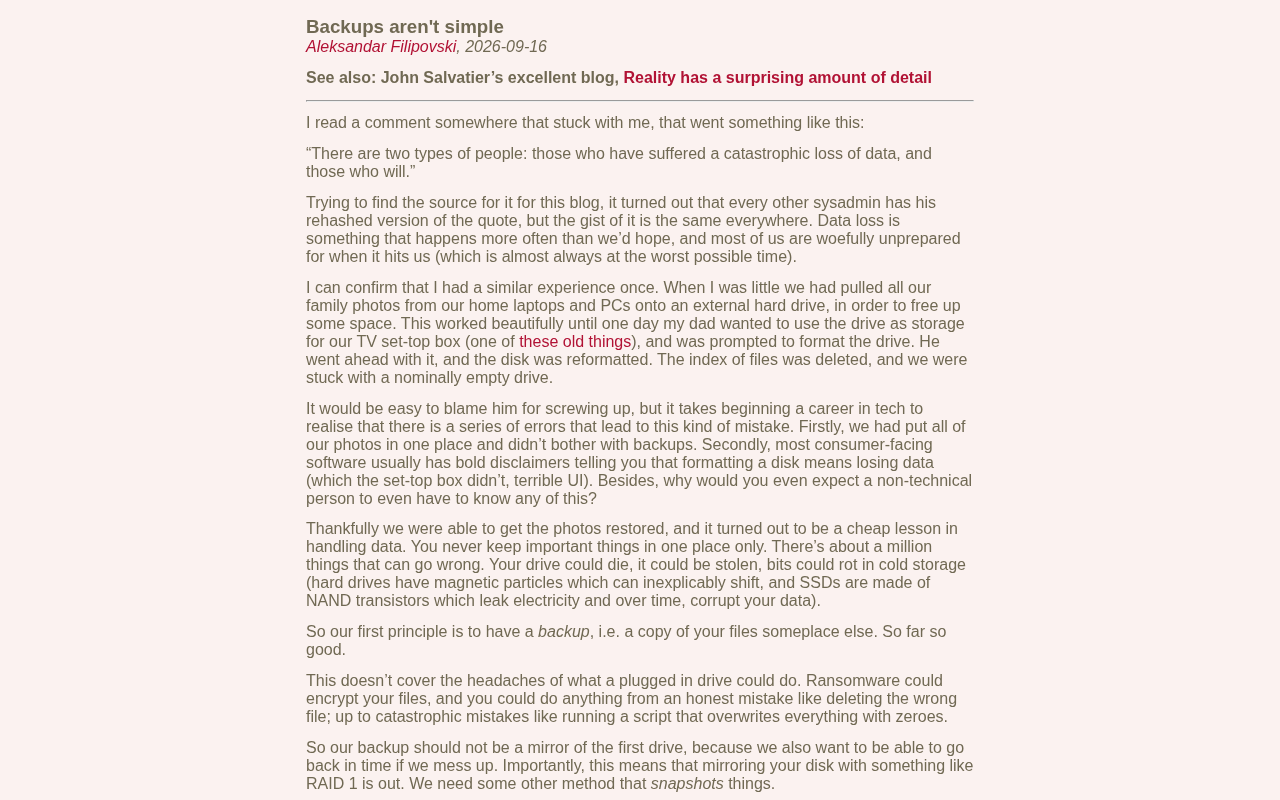
A backup only matters if you can restore from it — untested backups are just false confidence.
This article challenges the common misconception that "having a backup" equals "data safety." True security depends entirely on whether you can successfully restore. It systematically examines the key pitfalls: unverified backups, database consistency issues, encryption key management failures, broken backup chains, and the limits of the 3-2-1 rule when immutable storage and air-gapped copies are ignored. Framed within a disaster recovery mindset, the article shows how RPO and RTO should drive architecture and cost decisions, and offers four actionable baseline practices for individuals and small teams.
Backup: A Seriously Underestimated Engineering Problem
Most people's understanding of backup stops at "copy files to another drive" or "turn on cloud sync." But anyone who has worked in operations or lived through data loss knows the truth: backup has never been simple copy-and-paste. It's a systems engineering discipline involving strategy, validation, recovery drills, and long-term maintenance.
Filiporski's article earned 259 upvotes and 156 comments on Hacker News for a reason — it hits a universally overlooked nerve. Most people think they have backups, until the moment they actually need to restore something and discover those backups are completely unusable.
Why "Having a Backup" Doesn't Mean "Your Data Is Safe"
The core purpose of a backup isn't to "have a copy somewhere" — it's to "be able to restore from it." There's an enormous gap between those two things. A backup that has never been tested in a real recovery scenario is, at its core, nothing more than psychological comfort.
An Unverified Backup Is No Backup at All
Countless real-world incidents stem from exactly this: backup jobs appear to run successfully every day, no errors in the logs — but when disaster strikes and someone actually tries to restore, they discover corrupted files, incompatible formats, lost encryption keys, or that the backup was silently archiving an empty directory. Backup scripts fail silently. Storage media quietly degrades. Snapshot chains break. These problems only surface during recovery drills.
Regular restoration tests are the only reliable way to verify that a backup actually works. Even just restoring a subset of data once a month is infinitely better than blindly trusting the green checkmark on an automated job.
3-2-1 Is a Starting Point, Not a Finish Line
The classic 3-2-1 backup rule — keep 3 copies of data, on 2 different media types, with 1 stored offsite — is a solid baseline. But it's a starting point, not a complete strategy. Against modern threat models, you also need to consider air-gapped backups to defend against ransomware, and immutable storage to prevent backups themselves from being tampered with or deleted.
Immutable Storage refers to a storage mechanism where data, once written, cannot be modified or deleted for a specified retention period. Common implementations include object storage WORM (Write Once, Read Many) mode, and cloud services like AWS S3 Object Lock or Backblaze B2 Object Lock. The value is straightforward: even if an attacker or a malicious script obtains your storage credentials, they cannot erase the backup data. Air-gapped backups, on the other hand, mean the backup media is completely physically isolated from the network — typically offline tapes or disconnected hard drives. The two address different threats: immutable storage protects against "someone with network access who wants to delete data," while air-gapping protects against "the entire network environment has been compromised." Ransomware attacks routinely scan for and encrypt any accessible backups, making purely online backup strategies vulnerable to total wipeout. Immutable storage and offline copies have become indispensable layers in any modern backup strategy.
Common Pitfalls in Backup Engineering
The real complexity hides in the details. The following categories of problems appear repeatedly in both technical discussions and real-world incidents.
Consistency and Point-in-Time Issues
Doing a file-level copy of a running database is likely to produce a data file frozen mid-transaction — one that won't start cleanly. The right approach is to use the database's native consistent snapshot mechanism, or quiesce the application before capturing the backup. For distributed systems, achieving point-in-time consistency across nodes is an even harder problem.
The core challenge with database consistency snapshots is that a running database continuously writes data to in-memory buffers, and the files on disk can be in a half-written state at any given moment. Taking a filesystem snapshot or a raw cp copy may capture uncommitted transactions or miss committed ones that haven't been flushed to disk, causing the database to refuse to start or exhibit data inconsistencies after recovery. Different databases handle this differently: MySQL uses mysqldump --single-transaction or Percona XtraBackup's hot backup mechanism; PostgreSQL supports pg_basebackup combined with WAL (Write-Ahead Log) archiving; MongoDB relies on the WiredTiger storage engine's snapshot capability. For distributed databases like CockroachDB or TiDB, ensuring a globally consistent point-in-time across nodes requires distributed transactions or MVCC (Multi-Version Concurrency Control), adding significant engineering complexity.
Retention Policies and Storage Costs
More backups is not always better. Keeping every version indefinitely is expensive and unmanageable. You need a thoughtful retention policy: high frequency for recent data, sparse intervals for older data, while staying compliant with any regulatory requirements. Incremental backups save space, but they introduce dependency on an intact backup chain — if any link in that chain is corrupted, the entire chain may be unrecoverable.
Encryption and Key Management
Encrypting backups is non-negotiable, especially for offsite and cloud-stored copies. But this introduces the key management problem: if the encryption key lives in the same place as the data, the encryption is worthless; if the key is lost, the backup becomes a permanently unreadable pile of gibberish. Many organizations have stumbled badly at this step.
Upgrading Your Thinking: From "Backup" to "Disaster Recovery"
Zooming out, backup is just one component of a broader disaster recovery (DR) framework. The real questions to answer revolve around two critical metrics:
- RPO (Recovery Point Objective): How much data loss can you tolerate? How far back in time can you afford to roll back?
- RTO (Recovery Time Objective): From the moment of failure to the moment of restored service, how much downtime is acceptable?
These two metrics drive backup frequency, architecture decisions, and cost investment. For a personal blog, a daily backup and a few hours to restore is perfectly fine. For a financial trading system, second-level RPO and minute-level RTO imply an entirely different order of engineering complexity and budget.
Practical Advice for Individual Users and Developers
For individuals and small-to-medium teams, you don't need to start with an enterprise-grade solution — but these baseline principles are worth holding to:
- Automate + Monitor: Let backups run automatically, and alert on failures. Don't rely on memory.
- Offsite Storage: Keep at least one copy outside your local environment to protect against fire, theft, and ransomware.
- Regular Recovery Drills: Schedule a "try an actual restore" session. It's the only way to verify that your backups have real value.
- Document Your Process: Write down how to restore, so that when things go wrong, you're not scrambling — and so the encryption keys aren't locked inside one person's head.
Final Thoughts
The difficulty of backup isn't in high technical barriers — it's that backup is work that "shows no return when things go well, and reveals its value only when disaster strikes." This makes it chronically postponed and half-heartedly implemented.
The real lesson here: treating backup as a one-time configuration task is dangerous. It is a living system that requires continuous maintenance, verification, and evolution.
True security isn't the backup file sitting quietly on a hard drive. It's the confidence that comes from having already successfully restored from it once.
Background: RPO and RTO Explained
RPO (Recovery Point Objective) measures the acceptable window of data loss — if your RPO is 1 hour, it means in the worst case you can lose up to 1 hour's worth of data, which means your backup frequency must be at least hourly. RTO (Recovery Time Objective) measures the maximum allowable time from failure to restored normal operations. It directly determines how automated your recovery process needs to be and how much infrastructure redundancy to build in.
Both metrics need to be confirmed with business stakeholders, because they map directly to cost: shorter RPO means more frequent backups and higher storage costs; shorter RTO means investing in hot standby nodes, automatic failover, and extensive drill programs. Many engineering incidents trace back to the fact that the technical team never aligned on these two numbers with the business side — resulting in actual recovery times that far exceeded what the business could accept, or enormous spending to achieve a stringent target the business never actually needed.
Related articles
Three AI Researchers Debate: How Far Are We from Recursive Self-Improvement?
Three AI researchers including former OpenAI co-founder John Schulman debate recursive self-improvement and intelligence explosion, dissecting continual learning, distillation, RL success, and ASI timelines.
AI Recursive Self-Improvement (RSI): How Far Are We from the Real Thing?
How close is RSI (Recursive Self-Improvement) to reality? We analyze Acer AI's RSI Agent, a Shotcut watermark task, OS World 20 results, and OpenAI's automated researcher goal.
AI Coding Platforms Are Exploding in Popularity: Can Non-Technical People Really Build Money-Making Products?
An AI coding competition unexpectedly drew 1,000+ signups, sparking debate on whether non-technical people can build profitable products with AI. We break down the opportunities and the hype.