Bit-for-Bit Logprob Alignment Between Training and Inference on ROCm: How RL-Kernel Solves the RL Training Precision Problem

RL-Kernel achieves bit-for-bit logprob alignment between training and inference on AMD MI300X, eliminating RL numerical drift.
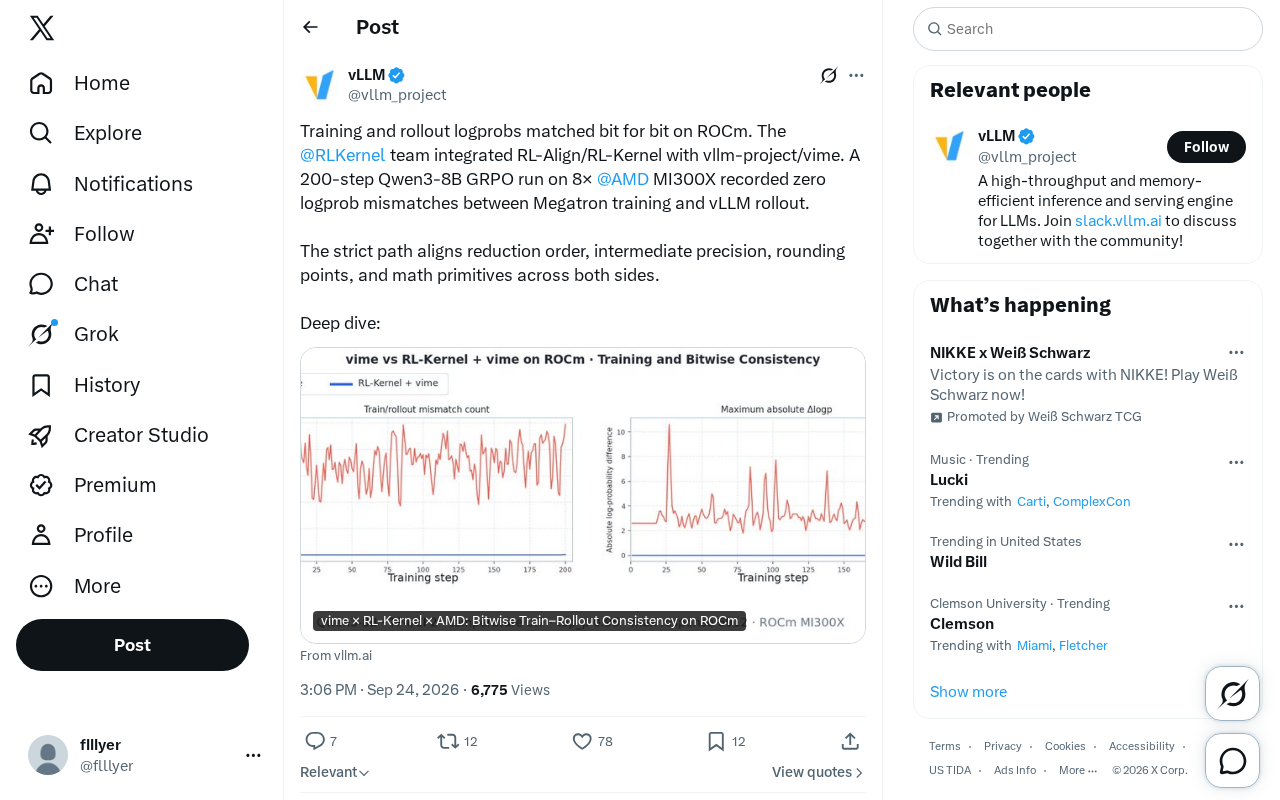
In LLM reinforcement learning, logprob mismatches between the training side (Megatron) and inference side (vLLM) — caused by differences in reduction order and numerical precision — get amplified through importance sampling weights, destabilizing training. RL-Kernel resolved this by unifying four key computation steps: reduction order, intermediate precision, rounding points, and math primitives. Running 200-step Qwen3-8B GRPO training on 8× AMD MI300X (ROCm), they recorded zero logprob mismatches, enabling exact importance sampling weights, improved training stability, and demonstrating AMD ROCm's maturity for demanding LLM training workloads.
The "Silent Killer" in RL Training: Logprob Mismatch
In large language model reinforcement learning (RL) training, there is a long-standing hidden problem that has troubled engineers: the log probabilities (logprobs) computed by the training framework often fail to match those computed by the inference framework during the rollout phase. These seemingly minor numerical discrepancies get amplified by the importance sampling weights in algorithms like GRPO and PPO, distorting training signals and potentially causing training collapse.
The root cause lies in the fact that training and inference are typically handled by two separate systems — training commonly uses frameworks like Megatron, while inference relies on high-throughput engines like vLLM. Subtle differences in computation order, numerical precision, and rounding behavior between these two systems accumulate into a "silent killer" that undermines RL training stability.
Log probabilities (logprobs) and importance sampling are the key concepts for understanding this problem. In policy optimization algorithms like PPO and GRPO, importance sampling (IS) is used to correct for the distributional shift between the "behavior policy" (the old policy used to collect data) and the "target policy" (the new policy being updated). The correction weight is proportional to the ratio of probabilities under the new and old policies for the same action: exp(logprob_new - logprob_old). Because this is an exponential function, even a logprob deviation of just 0.001 in either the numerator or denominator gets amplified into a substantial weight error. When there is a systematic discrepancy between the logprob_old computed by the training side (Megatron) and the logprob_old actually recorded by the inference side (vLLM) during rollout generation, the importance sampling weights are continuously miscalculated, causing policy gradient directions to drift. These errors do not cancel out on average — they accumulate over training steps, ultimately manifesting as oscillating training curves, non-converging rewards, or even catastrophic gradient explosions.
RL-Kernel's Breakthrough: Achieving Bit-for-Bit Consistency on AMD MI300X
According to disclosures from the @RLKernel team, they integrated RL-Align/RL-Kernel with components from vllm-project, achieving bit-for-bit (bit for bit) matching of logprobs between training and inference on the AMD ROCm platform.
The verification experiment is compelling: the team ran a 200-step Qwen3-8B GRPO training job on 8× AMD MI300X GPUs, with results showing zero logprob mismatches between the Megatron training side and the vLLM rollout side. In other words, throughout the entire training process, the log probabilities computed by both systems were completely identical, with no numerical deviation whatsoever.
For RL training, this represents a significant engineering milestone. Zero mismatches mean that importance sampling weights can be computed exactly, policy updates during training become more trustworthy, and stability is substantially improved.
The AMD MI300X is AMD's flagship accelerator for AI training and inference, featuring Chiplet packaging with 192 GB of HBM3 unified memory and a peak BF16 throughput of approximately 1.3 PFLOPS per card. ROCm (Radeon Open Compute) is AMD's open software stack — analogous to NVIDIA CUDA — providing the HIP programming interface and math libraries (such as rocBLAS and rocRAND) that are semantically aligned with CUDA. It is worth noting that achieving numerical alignment is no easier on ROCm than on CUDA — different hardware vendors' math primitives (especially hardware implementations of transcendental functions like exp/log) are permitted to differ by a few ULPs under compliance standards, which is precisely why RL-Kernel needs to separately align at the "math primitives" level. Achieving bit-for-bit matching on MI300X also indirectly demonstrates that the ROCm math libraries have reached a level of controllability sufficient for upper-level frameworks to perform fine-grained numerical behavior customization.
Technical Approach: Aligning Four Key Computation Steps
RL-Kernel's "strict path" achieves bit-for-bit alignment by unifying four critical computation steps between the training and inference sides:
Reduction Order
Floating-point addition is not associative — different summation orders produce different results. Using a consistent reduction order on both sides is the first step toward eliminating numerical drift.
Intermediate Precision
The choice of precision for intermediate results in operations like matrix multiplication and softmax directly affects the final output. The strict path ensures both sides use identical intermediate precision configurations.
Rounding Points
Where floating-point operations are rounded and which rounding mode is applied can also cause results to diverge. Unifying rounding points makes the computation fully reproducible.
Math Primitives
Differences in the implementation of low-level math functions (such as exp and log) are another source of error. Using the same math primitives on both sides guarantees consistency at the most fundamental level.
By achieving strict alignment across these four dimensions between the training and inference sides, RL-Kernel brings two independently evolved systems into complete numerical agreement.
The non-associativity of floating-point arithmetic is especially pronounced in large-scale parallel computation. Take summing a long sequence of logits in BF16 or FP16 format as an example: the GPU partitions the data across thousands of parallel threads for block-wise reduction (tree reduction), and the precision of the final result depends on the shape of the reduction tree and the rounding behavior at each level. The training framework (Megatron) may use a reduction strategy that shards across tensor-parallel splits for throughput, while the inference framework (vLLM) uses a different set of kernels optimized for KV-cache access patterns. Even with identical inputs, the last few ULPs (Units in the Last Place, the smallest unit of floating-point precision) in the output may differ. The core work of the "strict path" is to make both systems call the same underlying kernel implementations across these four dimensions, eliminating numerical noise introduced by divergent implementation paths at the source.
Why This Matters
The significance of this work goes beyond a single technical validation — it addresses a core pain point in RL training infrastructure.
Direct improvement to RL training stability. Logprob mismatch is one of the fundamental causes behind many instances of unstable and irreproducible RL training. After achieving bit-for-bit alignment, the determinism and reproducibility of training results improve dramatically, substantially reducing the cost of debugging and iteration.
Advancing the AMD ecosystem in AI training. The fact that this validation was performed on the ROCm platform with MI300X hardware demonstrates AMD GPU maturity in large-scale RL training scenarios. The CUDA ecosystem has long dominated this space, and achieving such fine-grained numerical alignment on ROCm signals that the AMD software and hardware stack is approaching the threshold required for demanding training workloads.
The value of open-source collaboration. The integration of RL-Align/RL-Kernel with the vLLM project exemplifies the open-source community's capacity to collaborate on solving deep infrastructure challenges. Work of this kind typically requires tight cross-framework integration across multiple systems.
Summary
Completing a 200-step Qwen3-8B GRPO training run on 8× MI300X with zero logprob mismatches represents a solid advance in RL training infrastructure. By unifying reduction order, intermediate precision, rounding points, and math primitives across the training and inference sides, it resolves the long-standing challenge of numerical alignment between two separate systems. For teams pursuing training stability and reproducibility, this "strict path" approach offers a practical engineering blueprint worth emulating. Interested readers can consult the team's in-depth technical writeup for further details.
Related articles

Random Pruning of the DPO Computation Graph: 1.4x Training Speedup and Lower Peak Memory
DPO training too slow and memory-hungry? This paper proposes a random pruning framework for the DPO computation graph, sampling independently across position, sequence, and branch dimensions; branch pruning achieves a 1.426x step-time speedup and cuts training time by about 30%, with in-depth attribution of memory and time gains.

Why Does JEPA Underperform MLM in Longitudinal EHR Representation Learning?
New study compares JEPA and MLM for longitudinal EHR representation learning on MIMIC-IV: three JEPA variants train stably without collapse but underperform MLM; target size, not heterogeneity, drives prediction error.

Transfer Learning + Visible Light Communication: A New Approach to Energy-Efficient Indoor Positioning
A study proposes a transfer learning-based visible light communication indoor positioning method, achieving 47% accuracy improvement on the BOSCH factory dataset, 67.5% model efficiency under high noise, and introducing the ME composite metric for energy-efficient positioning in energy-constrained industrial IoT scenarios.