Building an AI Reasoning Ladder with Aperiodic Order Research: An Open Dataset of Verifiable Reward Problems
A researcher releases 9 aperiodic order puzzles to explore building an RLVR curriculum from the real math frontier.
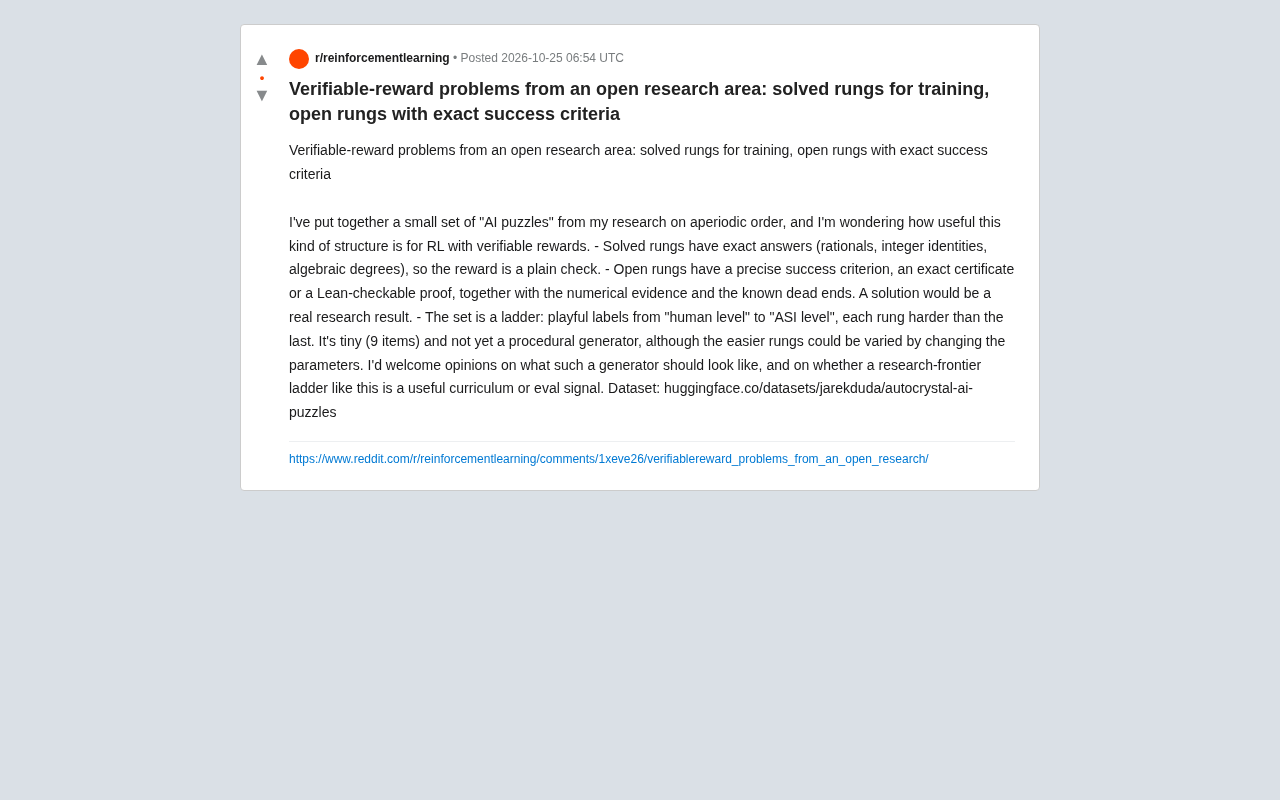
A researcher in aperiodic order posted a mini dataset of 9 puzzles on Reddit to explore RLVR. Puzzles come from real math research and split into solved rungs with exact answers for RL training and open rungs with precise success criteria—an exact certificate or Lean-checkable proof—whose solution would be a genuine math result. Published on Hugging Face, it is small and not yet a programmatic generator, and the author seeks community input on generator design and curriculum/evaluation use.
From Mathematical Research to an AI Training Ground: A Puzzle Ladder with Verifiable Rewards
A researcher working on aperiodic order posted a mini dataset of just 9 problems on Reddit, attempting to explore new possibilities for reinforcement learning with verifiable rewards (RLVR). According to their description, these "AI puzzles" are derived from real mathematical research, and each problem has a precise success criterion—either an exact numerical answer or a formal proof that can be checked by the Lean prover.
The design philosophy of this dataset stands in sharp contrast to current mainstream RLVR training sets. Most verifiable reward problems come from math competitions or programming problems, where answers are known and training signals are dense. What this researcher offers is a ladder structure: the lower "solved" problems are used for training, while the upper "open" problems correspond to the real research frontier—solving one constitutes a mathematical result.
Two-Tier Structure: Trainable "Solved Rungs" and Evaluable "Open Rungs"
According to the dataset author, the entire puzzle set is divided into two types of rungs:
Solved rungs have exact answers, such as rational numbers, integer identities, or algebraic degrees. The reward function is simply an answer checker, with no need for a complex scoring model. These problems are suitable for direct use in RL training, and "easier rungs can be used to generate variants by changing parameters," hinting at the potential for programmatic expansion.
Open rungs set precise success criteria—either providing an exact certificate or giving a Lean-checkable proof, along with numerical evidence and known dead ends. The author explicitly states: "Solving an open rung would be a genuine research result." This means these problems serve not only as evaluation signals but also as a bridge to real mathematical research.
This two-tier design is quite novel in the RLVR context: training signals come from the solved problems at the bottom, while evaluation signals point to unsolved research problems. The author labels the rungs from "human level" all the way to "ASI level," using gamified tags to imply a path of increasing difficulty.
Lean prover is an interactive theorem prover based on dependent type theory, which can also be used as a programming language. In mathematics, Lean and its mathematical library Mathlib are used to formally verify the correctness of theorem proofs—every step of reasoning must conform to logical rules, and the entire proof is ultimately checked mechanically by the computer kernel. This makes Lean an ideal vehicle for "verifiable rewards": if a Lean proof of a proposition compiles, then the truth of that proposition is guaranteed to the highest degree, without the need for human expert review. In recent years, the Lean community has formalized a large number of modern mathematical results (such as Voevodsky's univalence, the perfect space conjecture, etc.), gradually making it a bridge connecting frontier mathematical research and machine verification. For RLVR, the reward signal provided by Lean is binary and tamper-proof, which is stricter than answer-matching-based checkers, but also places higher demands on the model's formal reasoning capabilities.
Why Is Aperiodic Order a Good Testing Ground for RLVR?
Aperiodic order is a relatively niche but rich field of mathematics that studies systems that are neither fully periodic nor lacking in highly ordered structure, and is closely related to quasicrystals, symbolic dynamics, and spectral theory. The characteristic of such problems is that answers can often be stated precisely, but the path to discovery is highly nontrivial.
This precisely fits the core requirements of verifiable reward RL—rewards must be objectively checkable, but the problems themselves must not be too simple. According to the author, the success criteria for open rungs include "an exact certificate or a Lean-checkable proof," meaning that even if the answer is unknown, the verification process remains mechanical and requires no human subjective judgment.
From a broader perspective, this dataset touches on a key bottleneck in the RLVR field: the scarcity of high-quality verifiable problems. The community currently relies heavily on competition math problem banks, but there is a gap between these problems and real research. A "problem ladder" from an active research field may offer new ideas for curriculum learning and evaluation signal design.
Symbolic dynamics studies dynamical systems composed of discrete symbol sequences, with typical examples including shift spaces over finite alphabets and their subshifts. Aperiodic order (such as Sturmian sequences and substitution sequences) is often characterized within this framework: they are neither ultimately periodic nor lacking in strong ordering features such as low complexity and uniform recurrence. Spectral theory focuses on the spectral measures of operators (such as Schrödinger operators) associated with these sequences—the spectra corresponding to aperiodic order are often singularly continuous, which is deeply related to their "ordered but non-periodic" structure. The diffraction patterns of quasicrystals (such as the Al-Mn alloy discovered by Shechtman) are the physical manifestation of this structure. This background means that many problems in aperiodic order can be stated precisely as propositions about integer sequences, algebraic degrees, or rational approximations, with answers that can be mechanically verified, but discovering proofs requires deep mathematical insight—exactly the type of "verifiable but nontrivial" problems that RLVR craves.
Community Feedback and Open Questions: From 9 Problems to a Programmatic Generator
The author candidly admits that this dataset is "small (9 items), and not yet a programmatic generator," and actively solicits community input: What should such a generator look like? Can a ladder at the research frontier serve as a useful curriculum or evaluation signal?
These questions strike at the core challenges of RLVR data engineering. An ideal research frontier ladder needs to satisfy several conditions: the lower rungs must provide sufficiently dense training signals, the difficulty transitions between rungs must be smooth, and the top rungs must genuinely correspond to unsolved problems. Programmatic generation, meanwhile, requires a sufficiently formal understanding of the problem space in order to produce variants parametrically.
The author published the dataset on Hugging Face (jarekduda/autocrystal-ai-puzzles) for the community to experiment with. Judging from the discussion from a single source, this project is still at the proof-of-concept stage, and its actual training effectiveness and evaluation value remain to be verified. But the question it raises—can real research frontiers be used to build an RLVR curriculum—deserves serious consideration from researchers interested in verifiable reward RL.
For practitioners in AI programming and AI applications, this dataset also provides a concrete case study: how to transform domain knowledge into a machine-verifiable reward structure while preserving connections to real research problems. This may have more long-term value than simply scaling up competition problem sets.
Curriculum learning in reinforcement learning refers to arranging training samples in order of increasing difficulty, so that the agent gradually masters complex skills. In the RLVR context, curriculum design is especially critical: if problems are always too hard, the reward signal is too sparse and the model struggles to learn; if problems are too easy, they fail to push the capability boundary. An ideal "research frontier ladder" is essentially a curriculum—the solved rungs at the bottom provide dense rewards, while the open rungs at the top provide an evaluation benchmark. However, building such a curriculum faces the challenge of "difficulty calibration": the difficulty jumps between rungs need to be smooth, and the success rate at each level should fall within a range the model can learn from (a success rate between 20% and 80% is generally considered most effective). In addition, a programmatic generator needs to formally parameterize the problem space, which requires a sufficiently unified understanding of aperiodic order constructions to ensure that the generated variants both remain verifiable and retain research value.
One-line Summary
A researcher releases 9 aperiodic order puzzles to explore building an RLVR curriculum from the real mathematical frontier.
Paragraph Summary
A researcher in the field of aperiodic order posted a mini dataset of just 9 problems on Reddit, attempting to explore a new path for reinforcement learning with verifiable rewards (RLVR). These puzzles are derived from their real mathematical research and fall into two categories: solved rungs have exact answers and can be used directly for RL training; open rungs set precise success criteria—providing an exact certificate or a Lean-checkable proof—and solving one constitutes a genuine mathematical result. The author argues that aperiodic order problems "have answers that can be stated precisely but discovery paths that are nontrivial," fitting perfectly with RLVR's dual need for objective rewards and nontrivial problems. The dataset is published on Hugging Face, but it is small in scale and not programmatically generated, and the author openly solicits community input on generator design and on using the research frontier ladder as a curriculum or evaluation signal.
Related articles
AWS Launches Official Agent Toolkit: Letting AI Agents Directly Build and Manage AWS Applications
AWS launches the official Agent Toolkit, letting AI coding agents directly build and manage AWS apps across CDK, CloudFormation, Serverless, Bedrock Agents, and DevSecOps.
Does Agentic AI Need Its Own "Second Foundation"? A Three-Loop Architecture Explored
Inspired by Asimov's Foundation series, a multi-agent AI architecture hypothesis proposes execute, verify, and adapt control loops to reduce correlated errors and improve trust in AI results.
Rewriting a Commercial Engine in Jai: The Trade-off Between Performance and Productivity
Exploring the engineering practice of rewriting a commercial game engine in Jai: compile-time metaprogramming and data-oriented design advantages, plus ecosystem maturity and learning curve challenges.