Can AI Reverse-Engineer CUDA? A Community Vision to Break NVIDIA's Ecosystem Moat

Reddit user proposes using AI to generate an open-source CUDA implementation; article analyzes feasibility and limits.
Starting from a Reddit post by an AMD user proposing to use AI to reverse-engineer CUDA, the article analyzes the appeal and immense difficulty of this idea. CUDA's moat includes not just the API but also compilers, math libraries, toolchains, and framework bindings. Reverse engineering must advance on four levels. AI can assist with decompilation, code translation, and test generation, but cannot autonomously complete architecture-level reverse engineering. Existing attempts like ZLUDA, HIPIFY, and ROCm still have performance and compatibility ceilings. The idea is unrealistic short-term but reflects real pain from CUDA ecosystem lock-in and has long-term community exploration value.
A Technical Brainstorm Sparked by a Reddit Post
Recently, a Reddit user with an AMD Radeon GPU posted a thread with a blunt title: "Anyone feel like reverse-engineering CUDA?"
His motivation is very real—as an AMD card user, he's locked out of the CUDA ecosystem, while NVIDIA has built a near-monopoly in the AI training and inference market thanks to CUDA. He observed that more and more modders are using AI tools to reverse-engineer games and software, such as Photocraft, Gridcraft, and even mods that add Sonic characters to GTA5. So he proposed a bold idea: could AI be used to generate an open-source CUDA implementation?
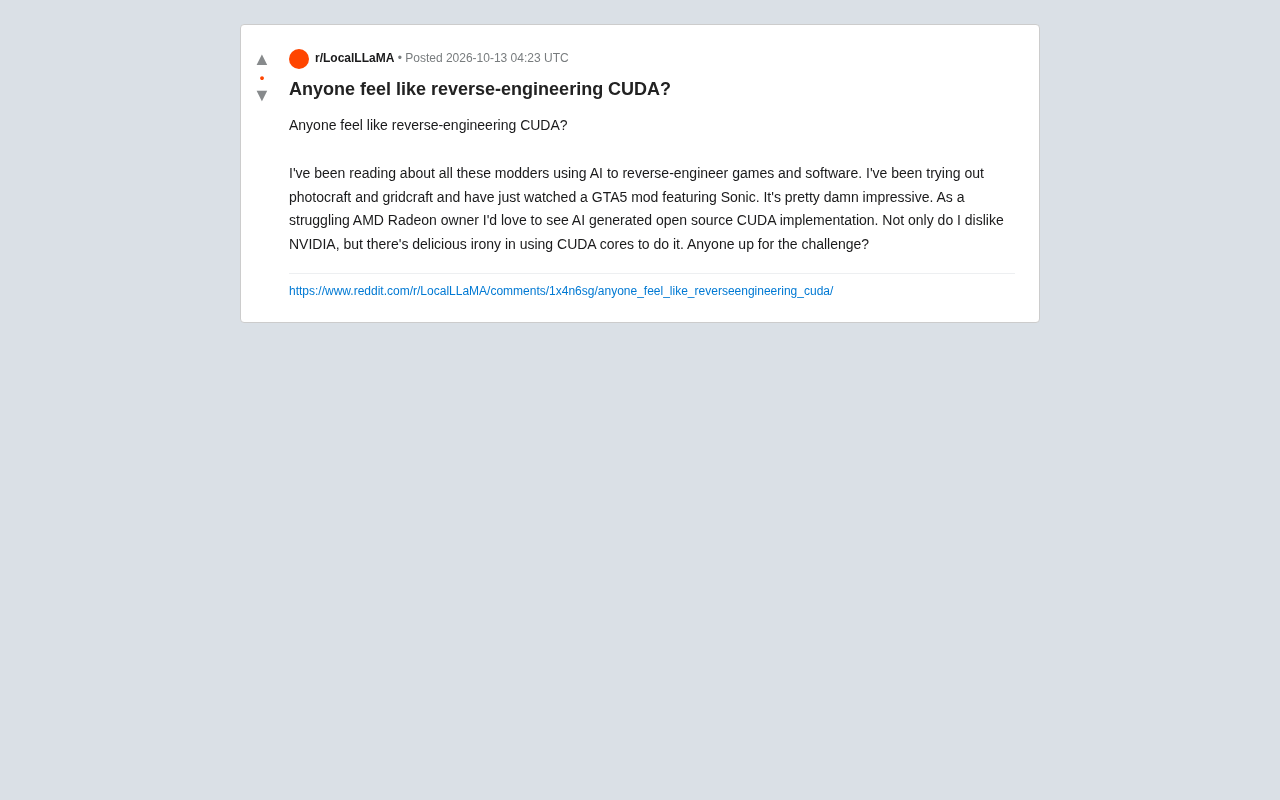
He added a rather sarcastic remark: using CUDA cores to do this is itself full of "delicious irony."
Why This Idea Is Both Fascinating and Tricky
CUDA's Moat Is More Than Just Technology
Since its launch in 2006, CUDA has accumulated nearly two decades of ecosystem development. It's not just an API; it also includes the compiler (NVCC), math libraries (cuBLAS, cuDNN), profiling tools (Nsight), and countless frameworks and frameworks of frameworks (PyTorch and TensorFlow's GPU backends are deeply tied to CUDA).
To "reverse-engineer" CUDA, the goal can be broken down into several layers:
- Driver layer: Enable AMD GPUs to execute CUDA's PTX intermediate code
- Runtime layer: Simulate CUDA runtime APIs (cudaMalloc, cudaMemcpy, etc.)
- Library layer: Rewrite core math libraries like cuBLAS and cuDNN
- Compiler layer: Convert CUDA C++ code into code that can run on other hardware
Each layer has different levels of difficulty. The community has actually made some attempts, such as the ZLUDA project, which tries to run CUDA binaries on AMD GPUs. However, it has clear ceilings in performance and compatibility, and was once interrupted due to legal and funding issues.
PTX (Parallel Thread Execution) is an intermediate instruction set architecture in the CUDA system, similar to Java bytecode. NVIDIA's compiler NVCC first compiles CUDA C++ source code into PTX, which is then converted by a JIT compiler in the driver into SASS machine code for a specific GPU architecture. The key value of PTX is that it provides a compatibility layer across GPU generations: the same PTX can run on NVIDIA GPUs of different architectures. Therefore, the most direct approach to "running CUDA binaries on AMD GPUs" is to implement a runtime or translation layer that can parse and execute PTX, converting PTX into instructions executable by AMD GPUs. ZLUDA takes this path, converting PTX to AMD's GCN/RDNA instructions. However, although the PTX specification is public, its semantic correspondence with hardware microarchitecture still highly depends on NVIDIA's implementation details, which is the fundamental reason why translation layers struggle to perfectly replicate performance.
HIP (Heterogeneous-compute Interface for Portability) is AMD's CUDA-like programming interface, with syntax highly similar to CUDA C++. With the HIPIFY tool, most CUDA source code can be automatically converted to HIP code, then compiled to AMD's ROCm platform or NVIDIA's CUDA backend. ROCm is AMD's complete open-source software stack comparable to CUDA, including compilers, math libraries, and runtime. Understanding the relationship between HIP and CUDA is crucial: HIP does not simulate CUDA but provides a separate API, enabling source-level migration through hipify rather than binary-level compatibility. This means that existing CUDA projects wanting to migrate to AMD usually need to be recompiled, and dependent third-party libraries (such as cuDNN) must have corresponding HIP versions (such as MIOpen). This is why ecosystem migration is far more difficult than API translation.
The Actual Capability Boundaries of AI Reverse Engineering
There is a huge gap between "using AI to reverse-engineer games" and "using AI to reverse-engineer CUDA" as mentioned in the post. Game mods typically involve memory modification, model replacement, or script injection on existing PC versions, essentially adding to known architectures and APIs. CUDA reverse engineering, however, involves closed-source compilers, proprietary instruction sets, and hardware microarchitecture. AI is currently far from being able to autonomously complete such tasks.
However, this doesn't mean AI is useless. AI can assist in the following areas:
- Decompilation assistance: Using large models to understand assembly code snippets and infer function intent
- Code translation: Automatically translating CUDA C++ to HIP (AMD's heterogeneous computing interface) or SYCL
- Test generation: Automatically generating large numbers of test cases to verify compatibility
- Documentation completion: Inferring API semantics based on behavior
But these are only "assists." True architecture-level reverse engineering still requires deep involvement from human experts.
Decompilation refers to the process of restoring machine code or assembly code to high-level language code, and is a core step in reverse engineering. Traditional decompilers like Ghidra and IDA Pro rely on pattern matching and control flow analysis, but when faced with highly optimized, inlined GPU kernel code, readability is often extremely poor. The potential of large models in this area lies in their ability to infer variable semantics and function intent from context, and even generate comments for obfuscated code. However, LLMs suffer from hallucinations and may generate code that seems reasonable but is semantically incorrect. Therefore, in scenarios with high security and correctness requirements, the output of AI decompilation must be reviewed by human experts. Additionally, CUDA kernels involve a large amount of parallel semantics and memory hierarchy details, which are difficult to fully recover at the assembly level—this is currently the main bottleneck for AI-assisted reverse engineering.
Community Reaction and Similar Attempts
The comment section of the Reddit post (though not fully included in the original) typically splits into two camps: one side views this as technological romanticism, while the other points to existing projects like ZLUDA and HIPIFY. In fact, AMD itself is pushing ROCm and HIP to reduce the cost of migrating CUDA code.
From a broader perspective, this post reflects a real pain point: CUDA's ecosystem lock-in effect. Many AI researchers and developers hesitate to use AMD or Intel GPUs because of CUDA dependencies. If there were an open-source, cross-platform CUDA compatibility layer, the entire AI hardware market might be healthier.
But we must also clearly see that NVIDIA's moat is not just software APIs; it also includes deep co-optimization between hardware and compilers. Reverse engineering can achieve "it runs," but achieving "it runs fast and stably" increases difficulty exponentially.
Summary: A Brainstorm Worth Taking Seriously
The Reddit user's question, on the surface, is "anyone want to work on this together?" but behind it is a rebellion against closed ecosystems. Using AI to assist in reverse-engineering CUDA is unrealistic in the short term, but as a long-term community project, it has exploratory value.
If you're interested in such projects, you can start with ZLUDA, HIPIFY, and some PTX-to-SPIR-V conversion tools to first understand the existing tech stack. Perhaps the next breakthrough will come from a late-night flash of inspiration from some AMD user.
One-line Summary
A Reddit user proposes using AI to generate an open-source CUDA implementation, and the article analyzes its technical feasibility and realistic boundaries.
Paragraph Summary
The article starts from a Reddit post by an AMD user proposing to use AI to reverse-engineer CUDA, analyzing the appeal and immense difficulty of this idea. CUDA's moat is not just the API but also includes compilers, math libraries, toolchains, and framework bindings. Reverse engineering must advance on four levels: driver layer, runtime layer, library layer, and compiler layer. Although AI can assist with decompilation, code translation, and test generation, it cannot autonomously complete architecture-level reverse engineering. The community already has attempts like ZLUDA, HIPIFY, and ROCm, but performance and compatibility still have ceilings. The article believes the idea is unrealistic in the short term but reflects the real pain point caused by CUDA ecosystem lock-in, and in the long run has community exploration value.
Related articles

How Big Can Stars Really Get? The Physical Limits of the Largest Stars
Red supergiants are the largest stars by volume, with radii up to 2,000 times the Sun, engulfing the inner solar system. But there is no precise upper limit on stellar size—models predict up to 15,000 solar radii. The most massive blue stars are far smaller than red supergiants—biggest and heaviest are two different things.

Apple HomeView Smart Display Full Feature Breakdown: Wall-Mount or Desktop, $299
Apple launches HomeView, a $299 smart display with wall-mount and desktop options, 12MP camera for facial recognition, smart home control, music playback, and recipe step-by-step cooking. Full breakdown of watch faces, apps, privacy, and cooking integration.

Where Did the Promised New Studio Go? Craft Computing Answers After Five Years
Craft Computing's host responds to viewer questions: the new studio promised five years ago was shelved as construction costs soared from $30,000 to $75,000, and was replaced by a 168-square-foot garage conversion.