#AMD
21 related articles

AMD MoRI + vLLM: Wide Expert Parallelism and RDMA KV Cache Transfer for MoE
AMD engineers will demonstrate MoRI + vLLM for MoE serving at PyTorch Conference 2026, featuring Wide Expert Parallelism and RDMA KV cache transfer on AMD hardware.

LTT's AMD Ultimate Upgrade: Where Did $5,000 Go? From NAS Builds to Tattoo Machines
LTT's AMD upgrade series spends $5,000 on a Ryzen 5 8500G DIY NAS, iPad Air drawing setup, and a wireless tattoo machine. A practical guide for NAS beginners.

Running Qwen3 LLM on AMD 395 iGPU: Local Deployment Test on Windows
A Bilibili creator open-sourced GFX1151 Engine, enabling AMD 395 iGPU to run Qwen3 Flash-Next on Windows. Real-world tests show ~900 tokens prefill, 96GB VRAM fully used.

AMD RCCL GPU-Initiated Networking Integrated into TorchTitan: 15% MoE Communication Performance Boost
AMD integrates RCCL's GPU-Initiated Networking (GIN) into PyTorch TorchTitan, boosting MoE all-to-all communication with up to 30% kernel gains and 12–15% end-to-end training speedup.

AMD FlyDSL Joins TorchInductor: A New MLIR-Native GPU Kernel Backend
AMD integrates FlyDSL, a Python-native MLIR-based GPU kernel DSL, into TorchInductor. On MI355: FP16 GEMM is ~19% faster than Triton; Flex Attention up to 5.8×.

GLM-5.3 Hits 469 tok/s on 8×MI355X: A Deep Dive into vLLM + TileRT Disaggregated Inference
TileRT and AMD achieve 469 tok/s single-user decode for GLM-5.3 on 8×MI355X using a disaggregated architecture where vLLM handles prefill and TileRT handles latency-critical decode.

AMD EPYC 9006: Positioning Server CPUs for the Agentic AI Era
Explore how AMD EPYC 9006 server CPUs are positioned for the Agentic AI era, and why high core density and memory bandwidth matter for AI agent orchestration.

Framework Desktop Now Available for Pre-order: AMD Ryzen AI Max 400 Series with Up to 192GB RAM
Framework opens pre-orders for its Desktop featuring AMD Ryzen AI Max 400 series and up to 192GB unified memory, targeting local AI inference and modular DIY users.

AMD Acquires Fei-Fei Li's World Labs for $8.2B; Claude Sonnet 5.5 Launches
AMD acquires Fei-Fei Li's World Labs for $8.2B; Anthropic launches Claude Sonnet 5.5; NVIDIA embeds Agent safety in hardware; Florida sues to restrict OpenAI model development.

AMD's New 256-Core EPYC Arrives: 16-Channel DDR5-12800 Approaches RTX 5090 Memory Bandwidth
AMD's new 256-core EPYC with 16-channel DDR5-12800 hits 91% of RTX 5090 memory bandwidth, sparking debate in the LocalLLaMA community over specs, cost, and real inference performance.

AMD's $8.2 Billion Acquisition of Fei-Fei Li's World Labs Targets Spatial Intelligence
AMD announces $8.2B acquisition of Fei-Fei Li's World Labs. Li joins as EVP and Chief Scientist. Analysis of the spatial intelligence strategy and AMD's play against NVIDIA.

Portable Computer Lands on AMD Ryzen AI Max: Local AI Agents Come to Windows
Portable Computer for Windows now supports AMD Ryzen AI Max, enabling local AI agents to run on-device — connecting local files and apps, with instant and scheduled tasks, no cloud required.

vLLM v0.30.1rc0 Released: Adds AMD MI355 NVFP4 and MoRI Kernel Support
vLLM v0.30.1rc0 adds dense NVFP4 quantization kernels and MoRI kernel mirror support for AMD MI355, expanding ROCm ecosystem LLM inference capabilities.

GMKTec Neo X1 Pro Review: Big Performance in a Tiny Box, but $3,200 Is a Hard Sell
GMKTec Neo X1 Pro mini gaming PC review: Ryzen 9 9955HX3D + RTX 5070, strong 1440p performance and great repairability — but $3,199 and rigid configs make it hard to recommend.

Rumor: Radeon RX 10800 XT May Outperform RTX 5090 in 4K Gaming and Local AI
Rumor claims AMD's Radeon RX 10800 XT may beat NVIDIA RTX 5090 by 15–25% in 4K gaming and local AI. We analyze the claim, the architecture, and what it means for the market.
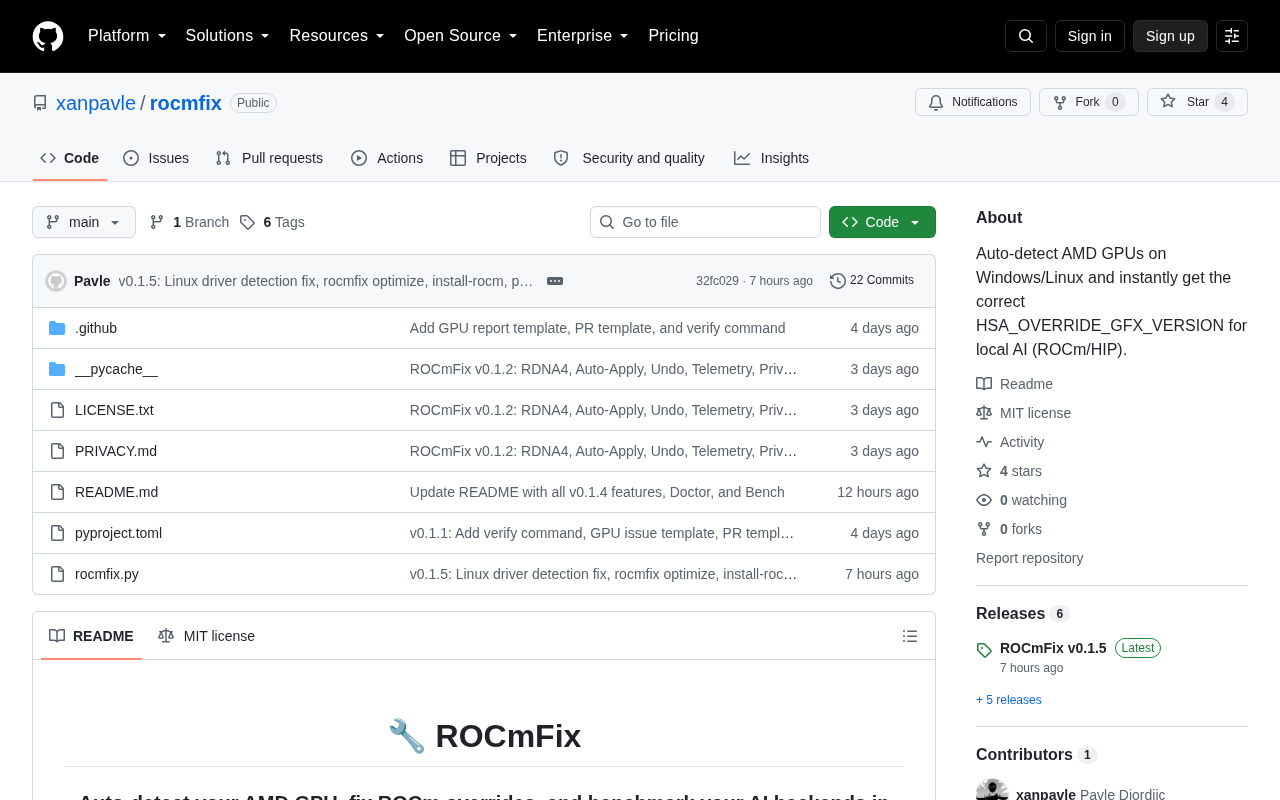
ROCmFix and InferBench: Running Local LLMs on AMD GPUs — A Practical Look
ROCmFix simplifies AMD GPU ROCm setup for local LLMs, while InferBench benchmarks Vulkan vs. HIP backend performance — practical tools for AMD local inference users.
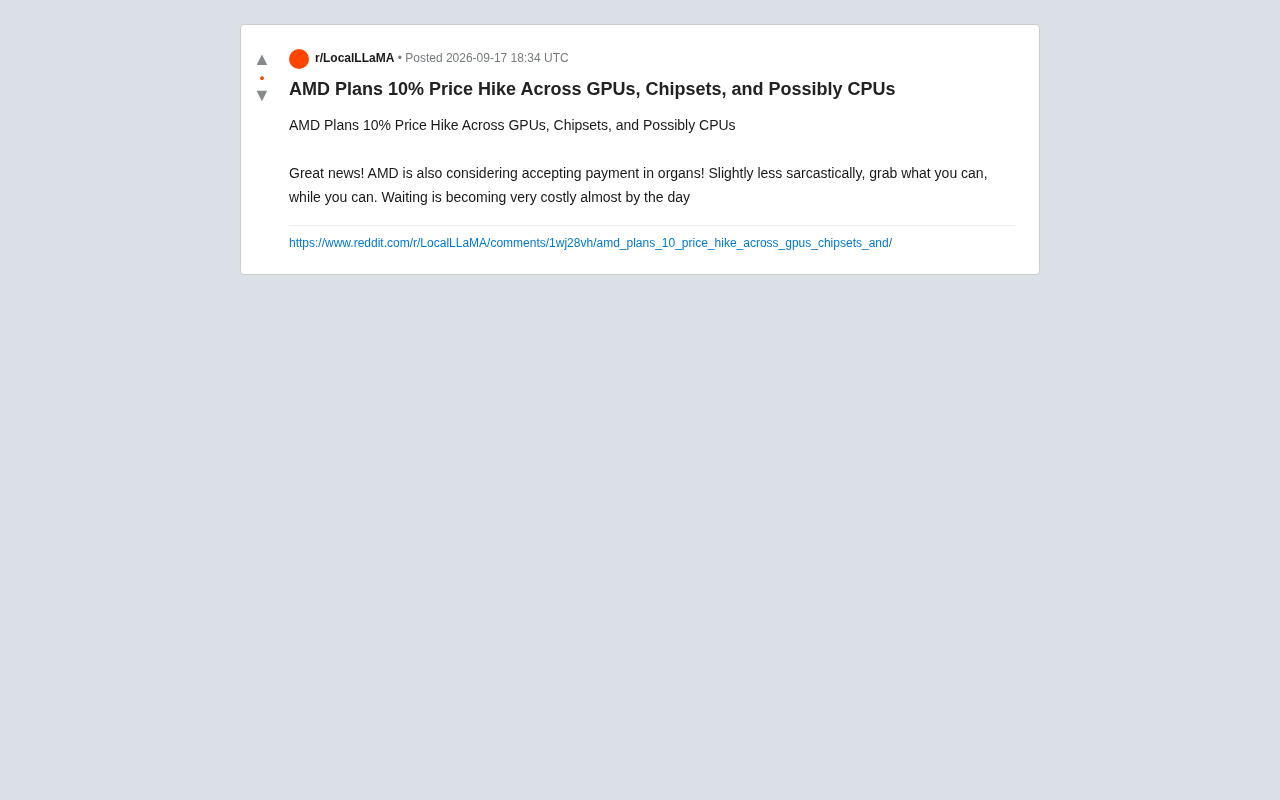
AMD Plans Across-the-Board 10% Price Hike: GPUs, Chipsets, and Possibly CPUs
Rumors on Reddit suggest AMD may raise prices ~10% across GPUs, chipsets, and CPUs. We break down the scope, market impact, and how consumers should respond.
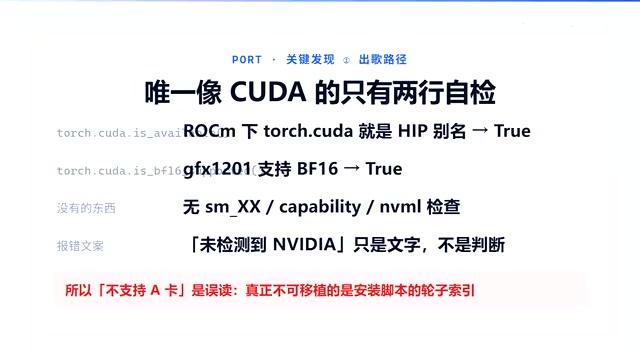
Running YuE Music Generation on a 16GB AMD GPU: Full ROCm Port of 9070XT Tested
A 16GB AMD 9070XT successfully runs the open-source YuE music generation model locally. Only 5 code changes needed to port from CUDA to ROCm, with a surprise 35.9% speedup.
 Industry Insights
AMD MI355X Beats B200: Full-Stack Optimization Breakdown for 5% Lower TCO on DeepSeek-R1 Inference
AMD Instinct MI355X achieves 5% lower TCO than NVIDIA B200 on DeepSeek-R1 disaggregated inference via SGLang+MoRI full-stack optimization with 1.25x per-GPU throughput.
 Product Reviews
Intel Core Ultra 7 270K Drops $50 — Does It Now Crush AMD X3D in Value?
Intel Core Ultra 7 270K Plus drops $50, matching AMD Ryzen X3D gaming performance at a lower price. Detailed benchmarks, AMD comparison, and 2025 gaming CPU buying advice.