Cap-and-Track: Dynamically Scaling LLM Inference Scheduling with Capacity

Meta proposes Cap-and-Track, using rejection signals to drive LLM inference request scheduling, saving 43% of GPUs.
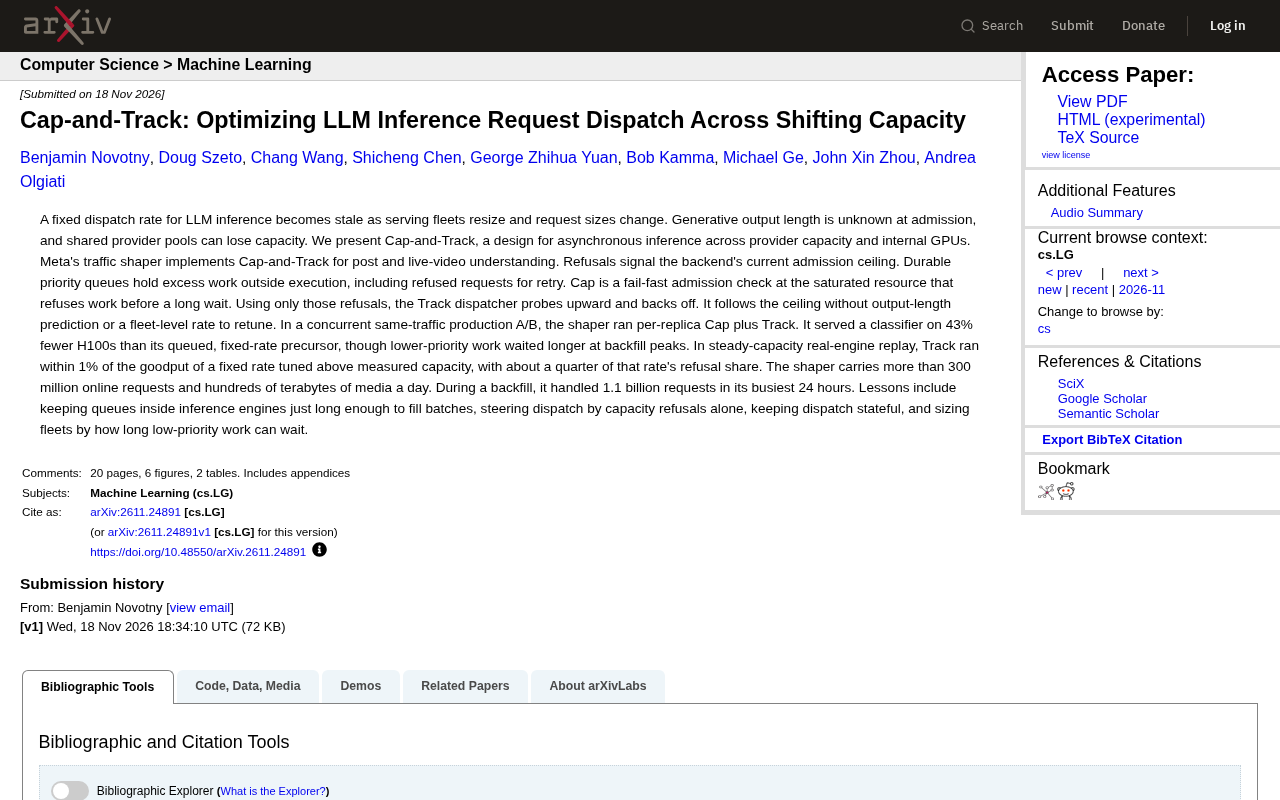
Meta's engineering team proposes a scheduling design for LLM inference request dispatch in the paper "Cap-and-Track," deployed in its traffic shaper. Fixed dispatch rates fail under cluster scaling and request-size fluctuation, because generation-phase load depends on output token counts unknown at admission, and shared provider capacity may vanish mid-flight. Cap-and-Track combines fail-fast Cap admission with Track's rejection-signal-based capacity probing, requiring no output-length prediction or global rate. Production A/B tests used 43% fewer H100s for the same classifier, with goodput within 1% of a tuned fixed rate and about a quarter of the rejection ratio.
When large model inference service clusters keep scaling up and down, and the requests themselves vary in size, a fixed scheduling rate quickly becomes outdated. Even trickier: the length of generative output is completely unknown when a request is admitted, and shared provider resource pools may lose capacity at any time. Meta's engineering team presents a design called Cap-and-Track in the paper "Cap-and-Track: Optimizing LLM Inference Request Dispatch Across Shifting Capacity," and has deployed it in Meta's traffic shaper to support online services such as image-text and live video understanding.
Why Fixed Rates Fail
The traditional approach is to set a fixed dispatch rate for the scheduler—for example, how many requests per second to send to the inference cluster. This rate works well in steady state, but once the service cluster's scale changes or the average output length of requests fluctuates, the tuned rate drifts away from optimal: set it too high and many requests get rejected or queue for a long time; set it too low and compute sits idle.
The problem is that what truly determines the system bottleneck is the load of the "generation phase," and the workload of the generation phase depends not only on the number of requests but also on the number of tokens each request actually produces—a number that is completely unknown at admission time. On top of that, capacity from shared provider pools may disappear mid-flight, making any static configuration hard to keep aligned with reality.
Load differences between the generation and prefill phases: LLM inference typically splits into two phases—prefill, which processes the input prompt and computes attention over all input tokens at once and is compute-intensive; and decode (generation), which autoregressively outputs token by token, processing only one token per step and being memory-bandwidth-intensive. The two place very different demands on GPU resources. The article points out that the generation phase truly determines the system bottleneck, because generation time is proportional to the number of output tokens, and output length is unknown at admission time, so request count alone cannot reflect real load. A fixed-rate scheduler that dispatches purely by request count will underestimate generation load when long-output requests dominate and overestimate it when short-output requests dominate, causing the rate to frequently drift from optimal.
The Two Core Mechanisms of Cap-and-Track
Cap: Fail Fast on Saturated Resources
Cap is a "fail-fast" admission check. It acts on the resource that is currently saturated, making a rejection decision before the request enters a long queue wait. Rejected requests are not lost; they are placed into a persistent priority queue awaiting retry. These rejection signals themselves carry information about the backend's current admission limit—in other words, a rejection is not an error but a form of feedback.
Fail-fast and persistent priority queues: Fail-fast is a system design pattern in which an error is returned immediately when a resource is definitely unavailable or a request is bound to fail, rather than letting the request wait a long time before failing. In inference scheduling, if a request queues for seconds before being rejected, it wastes queue capacity and prevents upstream from retrying or degrading in time. Cap moves rejection earlier to admission time and places rejected requests into a persistent priority queue—persistence means that even if the scheduler process restarts or the cluster scales, queued requests and their priorities are not lost, keeping scheduling state continuous across events. This echoes the later lesson that "scheduling state must be persistent."
Track: Probing Upward Using Only Rejection Signals
The Track scheduler works solely from these rejection signals: it probes capacity upward and backs off on rejection, continuously following the backend's limit. The whole process requires no prediction of output length and no global rate that must be repeatedly tuned at the cluster level. Scheduling state therefore remains stateful—which the authors list as one of the key lessons.
AIMD-style probing and goodput: Track's "probe upward, back off on rejection" is essentially additive-increase/multiplicative-decrease (AIMD) feedback control, conceptually akin to TCP congestion control—the sender keeps nudging the rate up slightly and backs off sharply upon a congestion signal, approaching link capacity without relying on a precise model. Here the "rejection signal" plays the role of the congestion signal. The term goodput, which appears repeatedly in the article, refers to the useful work successfully completed per unit time and not rejected, as distinct from raw throughput, which includes failed requests. Measuring scheduling effectiveness by goodput captures both throughput and rejection cost, so the paper uses it to compare Track against a tuned fixed rate.
Measured Performance in Production
The paper presents two sets of data. In a concurrent production A/B test with identical traffic, the shaper ran per-replica Cap plus Track, and served the same classifier with 43% fewer H100 GPUs than its queuing fixed-rate predecessor. The cost: during backfill peaks, low-priority tasks wait longer.
The other set is a real-engine replay under steady-state capacity: Track's throughput efficiency (goodput) is within 1% of a fixed rate tuned above measured capacity, while its rejection ratio is about a quarter of the latter's. In terms of operational scale, the shaper handles over 300 million online requests and hundreds of TB of media data per day; during one backfill period, it processed 1.1 billion requests in its busiest 24 hours.
Lessons from Frontline Deployment
Several lessons the authors summarize are broadly applicable. First, queues should live inside the inference engine, but retention time should be just long enough to fill batches—don't let requests pile up indefinitely in the engine. Second, the scheduling direction should be driven entirely by capacity rejection signals rather than relying on external prediction models. Third, scheduling state must be persistent to remain continuous across scaling events. Fourth, cluster sizing should be based on "how long low-priority tasks can wait," not just peak throughput.
These lessons point to a more fundamental view: in inference scenarios with constantly shifting capacity, rather than trying to predict precisely, build a feedback loop that reacts quickly to rejection signals. The value of Cap-and-Track may lie precisely in turning "rejection" from a bad outcome to be avoided into a usable signal source for the scheduler.
One-line Summary
Meta proposes Cap-and-Track, using rejection signals to drive LLM inference request scheduling, saving 43% of GPUs.
Paragraph Summary
Meta's engineering team proposes a scheduling design for LLM inference request dispatch in the paper "Cap-and-Track," deployed in its traffic shaper. The article notes that fixed dispatch rates fail under cluster scaling and request-size fluctuation, because generation-phase load depends on output token counts unknown at admission, and shared provider capacity may vanish mid-flight. Cap-and-Track has two mechanisms: Cap performs fail-fast admission checks on saturated resources, with rejected requests going into a persistent priority queue; Track probes capacity upward using only rejection signals and backs off on rejection, needing no output-length prediction or global rate. In a production A/B test it served the same classifier with 43% fewer H100s; in steady-state replay, goodput was within 1% of a tuned fixed rate with only about a quarter of the rejection ratio.
Related articles
US SEC Investigates Nvidia: Possible A…
US SEC Investigates Nvidia: Possible Accounting Issues
The US SEC's investigation into Nvidia focuses on potential accounting issues, not products. The news sparked heated discussion on Hacker News, with the market watching the AI chip giant's financial disclosure quality and regulatory signals.

FBI Crime Database Reportedly Hit by Hackers; Trump Says 'Not Good'
FBI's NCIC reportedly hit by hackers; FBI has launched an investigation and Trump said it's 'not good.' This article covers the incident, NCIC's importance, and law enforcement data security challenges.
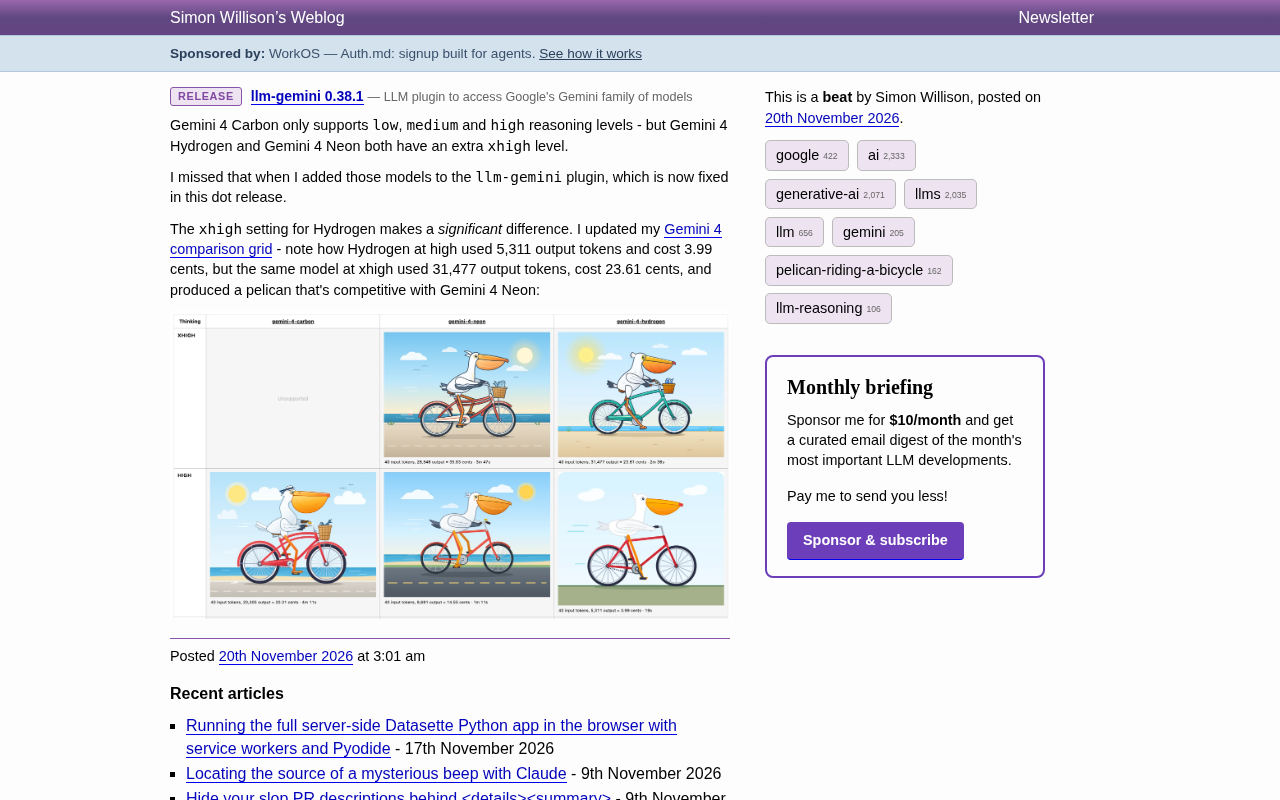
llm-gemini 0.38.1 Fix: Gemini 4 Hydrogen and Neon Gain xhigh Reasoning Level
llm-gemini 0.38.1 fixes the missing xhigh reasoning level for Gemini 4 Hydrogen and Neon. Comparison data shows xhigh sharply raises Hydrogen's output tokens and cost while clearly improving image quality to a level competitive with Neon.