ChatGPT Full-Duplex Voice Model GPT Live Launches: A Complete Revolution in Conversational AI

OpenAI's GPT Live One brings true full-duplex voice interaction, real-time translation, and deep reasoning delegation to ChatGPT.
OpenAI has launched a new ChatGPT Voice experience powered by GPT Live One, its most capable voice model yet. The model achieves true full-duplex conversation — eliminating turn-taking constraints — and demonstrates real-time bilingual translation. A delegation mechanism offloads complex reasoning to GPT 5.5 in parallel, while natural back-channeling and emotional speech synthesis make interactions feel genuinely human.
The "Turing Moment" for Voice Interaction
The phrase "Turing moment" carries deep historical weight. Computer science pioneer Alan Turing proposed the "Imitation Game" in 1950 — what we now call the Turing Test — where a machine is considered to have achieved human-level intelligence when a person, unaware of what they're communicating with, can no longer tell whether their conversational partner is human or machine. This standard shifts the metric from "task completion rate" to "interaction naturalness," and GPT Live is now mounting a direct challenge on exactly that dimension.
OpenAI officially unveiled the new version of ChatGPT Voice at its latest livestream, powered by a voice model codenamed GPT Live One. The company positions it as "the most powerful voice model ever built" — a truly full-duplex conversational partner in the most literal sense.
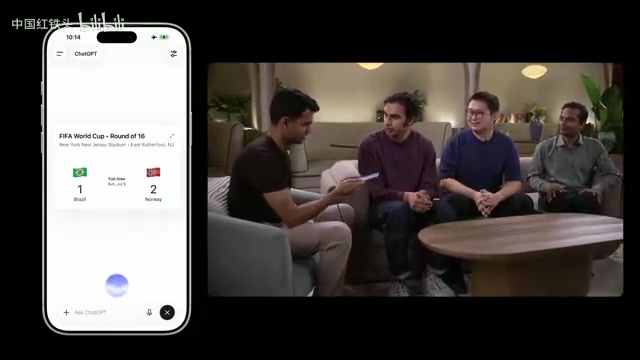
The launch event itself was a live demonstration: the OpenAI team co-hosted the stream alongside ChatGPT. Throughout the event, the AI remained continuously "present" — no wake words required, free to interject, add context, or gracefully yield — delivering a level of conversational fluency never seen before.
This matters because, despite years of iteration, voice assistants have never escaped a fundamental pain point: interactions feel unnatural. Users are forced to carefully "take turns" speaking, and in noisy environments, these systems often fail almost entirely. GPT Live aims to solve this at the architectural level.
As the team put it during the stream: "This is the moment when talking to technology finally feels like a real conversation — not a command line."
Core Breakthrough #1: Full-Duplex Continuous Interaction
The most critical technical advance in this release is the model's achievement of true full-duplex capability.
What Is Full-Duplex?
The full-duplex concept originates from telecommunications engineering. Traditional communication systems operate in three modes: simplex (one-way only, like radio broadcasts), half-duplex (bidirectional but not simultaneous, like walkie-talkies), and full-duplex (simultaneous bidirectional transmission, like a phone call). The livestream offered an intuitive analogy: like a phone call with a friend, where both parties can listen and speak at the same time — that's full-duplex.
Early voice AI systems were constrained by Voice Activity Detection (VAD) technology — the system had to determine whether the user had finished speaking before it could begin processing and responding. This was fundamentally a half-duplex architecture, producing the familiar "lag" and "breaks down when interrupted" experience. The core challenge of achieving full-duplex AI voice is that the model must continuously listen to and understand the input stream while simultaneously generating output, and must decide in real time when to stop speaking and when to yield — placing extreme demands on real-time inference and streaming processing architectures.
In the technical words of team member Kundan, full-duplex means the model "can continuously process the input stream while continuously producing the output stream, at all times." "Conversation no longer has the concept of turns" — the model can instantly respond to interruptions, pauses, corrections, and the natural "thinking-while-talking" flow of human speech.
Real-Time Translation: The Ultimate Expression of Full-Duplex Capability
Simultaneous speech translation is widely regarded as one of the most complex tasks in language technology. The core challenge lies in the "front-heavy" nature of human language — especially in Chinese and Japanese, where the core meaning of a sentence often only becomes clear at the end. Traditional simultaneous interpretation systems must accumulate a threshold of information before producing output, inevitably introducing latency.
One of the most impressive demonstrations in the livestream was real-time voice translation. One team member spoke in Chinese, another in English, and ChatGPT simultaneously dubbed both sides of the conversation in the other language while each person was still talking. The model "pauses intelligently at semantic nodes to collect more context" — an AI-native solution to the classic simultaneous interpretation problem: outputting translations at points of minimum semantic ambiguity, striking a dynamic balance between fluency and accuracy. Compared to human interpreters, the AI system has the advantage of being able to handle multiple language pairs simultaneously without cognitive fatigue.
Translation is not mechanical word-for-word conversion — it operates at the level of meaning, prioritizing fluency and semantic accuracy over literal correspondence. It's worth noting that real-time translation is just one capability of this general-purpose model. The same model handles real-time translation, everyday conversation, and proactive error correction in language-learning contexts — switching fluidly based on user instructions.
Core Breakthrough #2: Delegation Mechanism Enables "Thinking While Talking"
Voice assistants have long faced a trust problem: their intelligence consistently lags behind text-based models. The root reason people don't rely on voice assistants is that they "don't sound smart enough."
GPT Live breaks through this bottleneck with an elegant architectural design — dual-model collaboration + delegation. This design philosophy echoes microservice architecture in software engineering and the "Mixture of Experts (MoE)" concept in AI, as well as psychologist Daniel Kahneman's dual-process theory of human cognition: the fast, intuitive System 1 maintains conversational flow, while the slow, deliberate System 2 handles complex problems requiring deep reasoning.
In traditional monolithic voice models, there is a fundamental trade-off between reasoning depth and response speed — stronger reasoning typically means higher latency, yet voice conversation is extremely latency-sensitive (generally requiring under 200ms to feel natural). The delegation mechanism breaks this constraint by splitting "maintaining conversational flow" and "deep reasoning tasks" between two models running in parallel: when GPT Live encounters a complex question requiring deep reasoning, it delegates the task to the more powerful GPT 5.5 for parallel processing while continuing to converse with the user, ensuring the interaction never breaks.
In the livestream demo, a user was preparing a lecture on the history of sound while simultaneously asking ChatGPT to verify historical dates, check whether BART's 16th Street Mission station was delayed, and confirm the afternoon weather. The model handled multiple simultaneous search and reasoning tasks and wove the results naturally into the conversation — ultimately pointing out that the user's "Edison tinfoil phonograph, 1865" should be corrected to 1877.
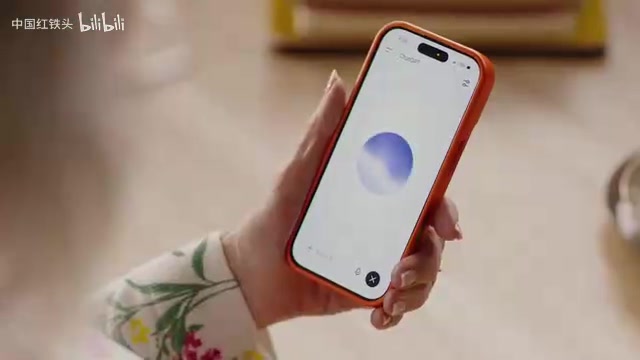
The team also revealed a practical design detail: the model includes a built-in intelligence picker. Users can select "instant" mode for maximum speed, or switch to "medium" or "high" tiers when deeper reasoning is needed.
A More Natural Conversational Feel
Beyond the core technical breakthroughs, GPT Live has made equally significant strides in the details of conversational experience.
The livestream showcased a wealth of nuances: natural filler words, "back-channel" responses, laughter, and rapid back-and-forth exchanges. "Back-channeling" is a term from conversational analysis referring to the brief acknowledgment signals a listener produces while the other person is speaking — "uh-huh," "right," "I see" — signals that communicate "I'm listening, please continue" and are essential for maintaining conversational rhythm and coherence. The absence of back-channeling is one of the key reasons early AI voice assistants felt cold and mechanical. Technically, generating appropriate back-channel responses requires the model to have real-time speech comprehension and the ability to judge whether a current semantic unit is complete — something only achievable in a full-duplex architecture. These seemingly small elements make the entire interaction feel "lighter and more genuine."
In the language-learning demo, the model played the role of an English coach, capable of proactively and instantly interrupting the learner's grammatical errors — for example, correcting "I've never went" to "I've never been" and explaining the difference between "excited" and "exciting." This demonstrates that the model is not passively waiting for the user to finish, but actively listening, making real-time judgments, and intervening at the right moment. Generating natural laughter and filler expressions falls under emotional speech synthesis (Emotional TTS), requiring the model to not only output words but also dynamically control intonation, rhythm, and timbre in real time.
One team member shared that what surprised him most was the model's overall sense of "timing and emotional expression" — so natural that at certain moments, you genuinely forget you're talking to an AI. This is the most colloquial expression of the Turing Test, and the fundamental reason the team called this launch a "Turing moment."
Safety and Future Outlook
The team emphasized that safety has been the top priority from day one of model training. As the model's naturalness and intelligence continue to advance, OpenAI says it will continue strengthening safety mechanisms, including guiding conversations away from sensitive or risky topics when necessary.
In the closing segment, Kundan stated that this model "brings us one step closer to truly accessible AGI — a world where talking to AI finally starts to feel like a real conversation."
From Commands to Conversation: A Paradigm Shift in Human-Computer Interaction
The significance of GPT Live extends beyond technical metrics — it represents a fundamental redefinition of the human-computer interaction paradigm: from the half-duplex command mode requiring "taking turns" to the full-duplex natural dialogue of "simultaneous listening and speaking"; and with the delegation mechanism bringing in the reasoning depth of top-tier models, voice interaction is becoming a truly low-barrier, high-intelligence interface. This shift means AI is being evaluated not just on "task completion rate" but on "interaction naturalness" — and the latter is the intelligence boundary that ordinary users actually perceive.
The model began rolling out to ChatGPT users on the day of the announcement. As for how many previously unimaginable use cases it will unlock — as the team said — they've "only just scratched the surface."
Key Takeaways
Related articles

Felix Rieseberg Personal Homepage
Felix Rieseberg's personal homepage sparks attention on Hacker News. This article covers the Slack engineer's technical background, the rise and fall of nativefier, and the value of a developer homepage as a tech calling card.

@ai-sdk/vue 3.0.306 Patch Release Syncs with [email protected] Update
@ai-sdk/vue 3.0.306 released, synced with [email protected]. A routine patch release for the Vercel AI SDK ecosystem with no public API changes; the Vue adapter layer stays version-aligned with the core package.

Gemini 4 Argon API Launches: The Era of Million-Token Output Begins
Google launches Gemini 4 Argon with sparse MoE architecture, up to 1M output tokens, and a 68.90% Vals Index score, available across API, AI Studio, and the Gemini app.