Cloudflare GLM-5.3 Leaks User Prompts: Memory Residue Behind the 200 OK

Cloudflare GLM-5.3 silently leaked 155 cross-user prompts via an SGLang bug, all marked as 200 success.
GLM-5.3 deployed on Cloudflare returned 155 responses containing fragments of other customers' prompts over two weeks, all carrying HTTP 200 status codes and thus invisible to monitoring. The root cause was an SGLang bug: prompts exceeding the prefill GPU capacity (~681,000 tokens) should have errored but were replaced with a single-token placeholder and decoding continued, while reserved memory pages weren't cleared between users, letting the model read the previous user's residual data. Cloudflare's tests only checked status codes and speed, not answer semantics, allowing the leak to occur silently. The bug was submitted back in July; self-hosted users should upgrade to 0.5.22. The incident reveals systemic weak points at the intersection of inference engine memory management, testing strategy, and open-source fix cadence.
A "Successful" Failure: Why the Leak Was Labeled 200 OK
According to disclosures from a YouTube channel, GLM-5.3 deployed on Cloudflare returned 155 answers over two weeks that contained fragments of other customers' prompts. The most unsettling detail isn't the leak itself, but that every leaked response carried an HTTP 200 status code—from a monitoring perspective, everything looked normal.
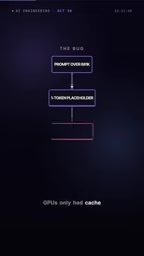
According to the postmortem published by Cloudflare (released Monday), the prefill GPU's memory capacity supports roughly 681,000 tokens, and prompts exceeding that length should have returned an error outright. But a bug in SGLang (an open-source inference engine) replaced the rejected prompt with a single-token placeholder and continued execution. The decode side had already reserved memory pages, and those pages were not cleared between users. The result: the model read residual data left by the previous user and returned it as part of the answer—all flagged as successful.
Each link in this chain is harmless in isolation, but combined they create a silent privacy leak channel. Status code checks, latency monitoring, and throughput metrics all passed because the system "thought" it had completed its work.
Uncleared Memory Pages: A Known SGLang Hazard
The root cause lies at the inference engine layer. SGLang, a widely used open-source serving framework, pre-allocates memory pages during the decode phase to optimize performance. These pages should be reset or isolated after a request ends, but in this case they weren't.
When the oversized prompt was replaced with a single-token placeholder, the decoder continued down the pre-reserved memory path, and those uncleared pages still held the previous user's context. The model couldn't distinguish between "the current request's input" and "historical residue in memory," so it used both as context to generate the answer.
More interestingly, according to the video, this SGLang bug was submitted back in July. That means there was ample time between the bug report and Cloudflare stepping on the landmine for the issue to be discovered and fixed. Between the open-source ecosystem's fix cadence and commercial deployments' update frequency, there's a crack that's easy to overlook.
SGLang's RadixAttention and Memory Page Reuse Mechanism
SGLang's efficiency in serving large models hinges on its RadixAttention (radix tree attention) mechanism. It organizes the KV Cache (key-value cache) of multiple requests into a prefix tree, letting requests with identical prefixes share already-computed memory pages and avoid redundant computation. Pre-allocating memory pages during the decode phase is an extension of this design: the system predicts where subsequent tokens will be written and locks GPU memory in advance to reduce latency.
The problem is that these "pages" are an abstraction of physical VRAM, and after a request ends they must be explicitly reset or marked as overwritable. If the engine skips the cleanup step on an error path (such as when an oversized prompt is replaced by a placeholder), the key-value vectors remaining in the pages become context visible to the next request. Fixes for such issues in the SGLang community typically involve forcing a page-release call at the end of a request's lifecycle, which is one of the key contents of the 0.5.22 release.
Testing Blind Spot: Measuring Speed, Not Verifying Content
Cloudflare's postmortem unusually candidly admits a fundamental oversight: their tests checked status codes and response speed, but never verified whether the answers were sensible.
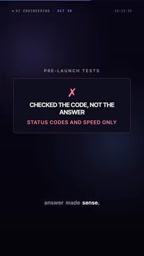
This exposes a common mindset in AI service operations—monitoring models as if they were ordinary APIs. Traditional services' correctness can be judged by status codes and latency, but the "correctness" of LLM output is semantic and cannot be proven by a 200 OK. When prompts are silently replaced and memory is reused across users, all infrastructure metrics show green while the output content is wildly wrong.
To their credit, Cloudflare took the model offline within 40 minutes of discovering the issue. Only prompts exceeding the length limit were affected, keeping the scope relatively contained. But the value of the postmortem itself lies in how it punctures an industry habit: we monitor the system, not the answer.
Why "Semantic Correctness" Is Hard to Monitor
Traditional API monitoring is built on a "deterministic contract": the same input should produce a predictable status code and response structure. But LLM output is probabilistic—the same prompt may yield different text on two calls, so it can't be judged right or wrong with simple assertions. Common industry compromises include maintaining a set of "golden prompts" and periodically comparing key entities or factual fragments in outputs, using another model as a judge to score responses, or scanning outputs for PII/sensitive terms. Cloudflare's blind spot here was exactly that it only did infrastructure-level monitoring and established no content-level spot-checking mechanism, so cross-user data appearing in answers went unnoticed.
Practical Reminders for Self-Hosted and Platform Users
If you host SGLang yourself, the video's advice is direct: upgrade to version 0.5.22. For teams using hosted models, the lesson is subtler—don't trust a provider's advertised context limit until you've personally verified output content at that size.
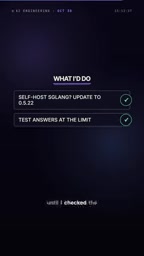
"Every one of those leaks came back marked success. That was the whole problem." This line deserves to be pinned to the wall of everyone building AI infrastructure. Length limits aren't a boundary you can trust based on documentation promises; they're an engineering problem that needs stress testing under real conditions. In oversized-context scenarios, requests being rejected, truncated, or replaced is all normal—but continuing to run after replacement and returning someone else's data is a failure at the system design level.
From a broader perspective, this incident is an accident at the intersection of three things: inference engine memory management, service providers' testing strategies, and open-source defect response speed. If any one of them had been done right, the leak wouldn't have happened. Cloudflare's postmortem is praised as "unusually candid" precisely because it didn't pin the blame on a single factor but laid out the weak points along the entire chain.
What the 681,000 Token Figure Means
681,000 tokens is roughly equivalent to a context of about 500,000 English words or 1 million Chinese characters, far exceeding the publicly disclosed context windows of current mainstream models. The prefill GPU's memory capacity determines this physical limit: the size of the KV Cache is proportional to sequence length, layer count, and hidden dimension, so longer sequences consume more. Once a prompt exceeds capacity, the correct approach is to reject the request and return an error code. SGLang's bug instead "tricked" the downstream flow with a single-token placeholder, letting the system continue decoding even with VRAM full—a textbook case of a physical boundary being bypassed by software logic.
FAQ
Which users were affected by the GLM-5.3 leak?
Only users who submitted oversized prompts exceeding the prefill GPU's capacity (about 681,000 tokens) were affected. Cloudflare took the model offline within 40 minutes, and requests of normal length were not impacted.
What should self-hosted SGLang users do?
The video recommends updating SGLang to version 0.5.22. The bug was submitted back in July; keeping dependencies up to date is a basic step to avoid stepping on landmines.
Why didn't status code monitoring catch the leak?
Because the leaked responses returned HTTP 200, with status codes and latency metrics all normal. Cloudflare's tests only checked status codes and speed and never verified the semantic sensibility of answers—the core testing blind spot of this incident.
Related articles

AI Can Read Neural Network Weights Directly: Do Models Already Exceed Expectations?
A Reddit developer experiment shows language models can directly read neural network weights and infer their function. Astra, Opus 5.5, and Muse Spark 1.3 all passed the test, sparking discussion on model generalization and training sources.

India's Microdrama Market Explodes: EloElo Secures $80M Investment from NBCUniversal
EloElo secures $80M from NBCUniversal to boost StoryTV, its microdrama platform with over 33M monthly active users, as India's microdrama market draws global capital.

Acoustic Detection of Multi-Rotor UAVs: Fusing Handcrafted Features with Pre-Trained Embeddings
Study reveals data leakage from random splits in UAV acoustic detection, proposes source-disjoint protocol with stacked ensemble of handcrafted features and YAMNet embeddings, achieving 95.29% accuracy for low-cost drone detection.