codebase-memory-mcp: Giving AI Agents a Memory for Large Codebases

codebase-memory-mcp decouples memory management into a dedicated MCP server so AI agents can navigate large codebases without losing context.
AI agents often get "lost" in large enterprise codebases due to context window limitations, struggling to maintain coherent memory across thousands of files and dependencies. The open-source project codebase-memory-mcp addresses this by fully decoupling memory management from the agent itself, delegating it to a dedicated MCP (Model Context Protocol) server that maintains a clean data stream — letting agents focus on reasoning rather than state tracking. Compared to building your own solution, this approach avoids debugging hundreds of lines of brittle glue code. That said, it does require upfront MCP toolchain setup and offers limited benefit for small projects; its true value emerges in large-scale enterprise codebases.
Why AI Agents Keep Getting Lost in Large Codebases
When you point an autonomous AI agent at a massive enterprise-scale repository, a familiar problem surfaces almost immediately: it loses its bearings in the tangled web of code dependencies, unable to track where it is. This phenomenon is aptly described as an agent losing context inside a "spaghetti web" of interconnected code.
The larger the codebase, the worse the problem gets. Agents need to maintain a clear mental map across thousands of files, function call chains, and module dependencies — yet traditional approaches often leave them overwhelmed. As the agent processes new sections of code, previously accumulated context gets crowded out or simply forgotten.
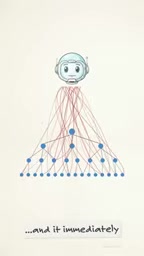
The root cause is the large language model's context window limitation. During each inference pass, the model can only "see" a fixed amount of text (measured in tokens). Anything beyond that window gets truncated and discarded. For enterprise codebases that routinely span hundreds of thousands of lines, even modern models with 100K+ token windows fall far short of holding all relevant code at once. As an agent incrementally explores a codebase, it must constantly decide what to keep and what to drop — a process prone to error. It might be deep in analyzing a function while having already forgotten the original call entry point, or it may have lost track of critical global configuration. Traditional approaches like Retrieval-Augmented Generation (RAG) attempt to address this by pulling in relevant snippets on demand via semantic search, but for code tasks that require understanding complex dependency chains, fragmented retrieval rarely reconstructs the full call context.
How codebase-memory-mcp Solves the Problem
The core idea behind the open-source project codebase-memory-mcp is radical decoupling. Rather than cramming memory logic into the agent itself, it extracts that responsibility entirely and hands it off to a structured, purpose-built MCP (Model Context Protocol) server.
In other words, the agent no longer has to shoulder both "thinking" and "remembering" at the same time. The MCP server organizes what would otherwise be chaotic context into a clean data stream, allowing the agent to safely traverse the entire codebase without losing any piece of context along the way.

Why Not Just Build It Yourself?
Some might ask: can't I just write this myself? The honest answer is — nobody wants to debug 500 lines of brittle glue code just to manage agent state.
Rolling your own solution may feel like it gives you control, but in practice it means wading through mountains of boilerplate that's fragile and hard to maintain. Using a ready-made MCP server saves hours of repetitive work and lets you focus on actual business logic.
MCP (Model Context Protocol) is an open protocol introduced by Anthropic to establish a standardized communication interface between AI models and external tools or data sources. Think of it as the "USB port" of the AI world — regardless of how the underlying tool is implemented, as long as it follows the MCP protocol, any model can call it in a uniform way. MCP servers run as independent processes, handling domain-specific tasks (such as filesystem access, database queries, code indexing, etc.) and interacting with agents via standardized message formats. The architectural advantage here is separation of concerns: the agent only needs to issue semantic requests without knowing any implementation details, while the MCP server focuses on completing specific tasks efficiently and reliably. codebase-memory-mcp leverages this protocol to wrap codebase context-state management into a dedicated service, enabling agents to retrieve precise location information within the code at any time — much like querying an external database.
Prerequisites Worth Being Honest About
This solution isn't a silver bullet. A few things are worth acknowledging upfront.
First, you'll still need to complete the initial MCP toolchain setup — that overhead can't be eliminated. Second, if your codebase is relatively small, the payoff will be limited, since context management isn't much of a pain point in smaller projects.

The real value of this tool shines in large-scale codebase scenarios. Only when the code reaches a certain size and agents genuinely start getting lost does a dedicated memory layer prove its worth. For large repositories, agents can finally navigate the full complexity of the codebase confidently and completely.
Who Is This For?
If you're building AI agent-powered engineering tools — especially ones that need an agent to understand and operate on large codebases — codebase-memory-mcp is worth trying. It standardizes and modularizes the otherwise tedious and error-prone work of agent state management, so builders don't have to reinvent the wheel.
For small projects or proof-of-concept stages, the benefit is limited and you can set it aside for now. But for enterprise-scale, long-lived codebases, this kind of dedicated memory infrastructure may be exactly the missing piece for bringing AI agents into production.
Related articles

Zero-Cost Local Jarvis: Open-Source Voice Cloning and Task Automation in Practice
AI Workshop shows how to build a zero-cost local Jarvis with Ollama and Voice Studio: local model switching, open-source voice cloning, file retrieval, and tool-calling tests, with setup steps and hardware trade-offs.

Mistral Large 4 Released: 1T-Parameter MoE Tops Western Open-Source Leaderboard
Mistral releases its flagship Mistral Large 4: a 1T-parameter MoE architecture activating only 49B parameters at inference, trained from scratch on 3,800 Grace Blackwell GPUs, topping the Western open-weight leaderboard with third-party endorsements in law, finance, and cybersecurity.

Mistral Large 4 Review: Can Europe's Strongest Open-Source Model Challenge the US and China?
Mistral Large 4 (L-Charm) review: trillion-parameter MoE, standout cybersecurity benchmarks but behind Kimi K3 in software engineering, 3,800 GPUs, a key step for European sovereign AI.