Data Attribution Should Steer Pretraining: From Ranking to Reusable Guidelines

Data attribution should move beyond one-off document ranking to become testable, reusable guidelines for pretraining data management.
The article points out that current data selectors based on influence functions can only rank documents for a single training run; once the training configuration or checkpoint changes, the ranking may become invalid. The authors argue that data attribution should further identify explainable, testable data properties and turn them into management guidelines reusable across corpora and checkpoints. This requires a feedback loop: explaining attribution sources, testing candidate data changes, and clarifying the evidence required for five types of claims and the conclusions that cannot be established. Ultimately, new methods must be falsifiably compared with cheap baselines such as perplexity and classifiers under total compute that includes discovery cost, to scientifically validate their cost-effectiveness.
Introduction
Pretraining data management determines what data the model learns from, but whether a document is worth learning depends on what the model already knows. Currently, data selectors based on influence functions can already rank documents to improve a single training run, but a position article from RSS, "Data Attribution Should Steer Pretraining," argues that training data attribution should go further: by identifying testable data properties, converting them into reusable management guidelines, and evaluating them on new data at a matching total cost (including discovery cost) against cheaper selectors.
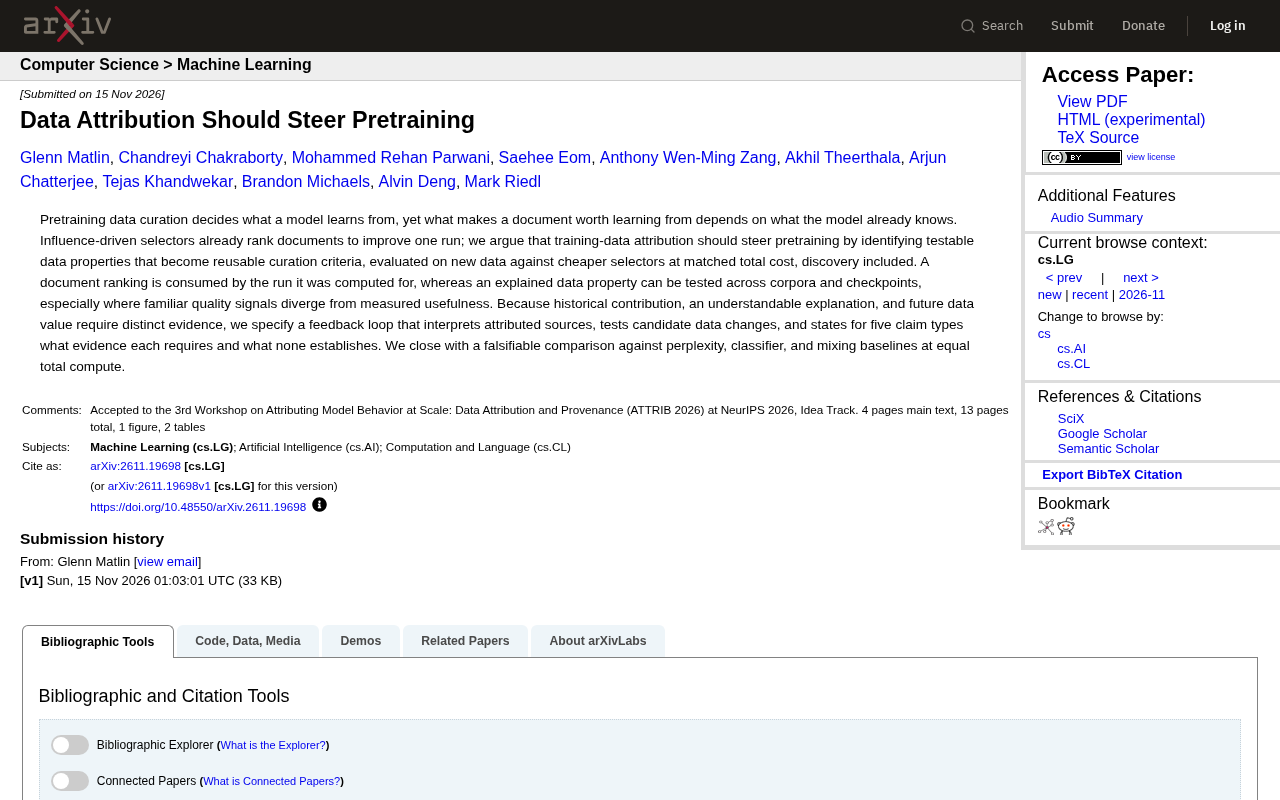
From Document Ranking to Explainable Data Properties
Traditional document ranking results only serve the one run in which they are computed. Once the training configuration changes, the ranking may become invalid. In contrast, an explained data property can be tested across different corpora and checkpoints, especially where familiar quality signals diverge from measured usefulness. For example, some documents considered "high quality" may not help the model much, while some seemingly ordinary documents may contain key knowledge. This divergence is exactly what explainable properties are needed to capture.
The article emphasizes that historical contributions, understandable explanations, and future data value require different kinds of evidence. Therefore, the authors propose a feedback loop: explain the source of attribution, test candidate data changes, and clarify, for five types of claims, what evidence each requires and what evidence cannot establish. This systematic approach aims to transform data attribution from a one-off ranking tool into a mechanism that continuously guides pretraining.
Influence functions are one of the core tools in data attribution. Originating from robust statistics, they estimate "how much the model parameters or loss would change if a given training sample were removed or altered." In deep learning, common approximation methods include TracIn and influence function approximations (such as LiSSA), which measure the contribution of an individual training sample to a specific prediction via gradient inner products. Data selectors based on influence functions can assign a "usefulness score" to each document, thereby filtering data before a single training run. However, such scores depend heavily on the current model checkpoint, training configuration, and target task: changing the checkpoint or loss function can significantly change the ranking. This is precisely the technical background for the article's argument to move beyond mere ranking toward explainable and reusable data properties.
Feedback Loop and Evidence Requirements
The core of the feedback loop is to turn attribution results into actionable insights. Specifically, it requires:
- Explaining the source of attribution: understanding why certain data is useful to the model, not just that it ranked at the top.
- Testing candidate data changes: experimentally validating the impact of data properties, such as adding or removing certain types of data.
- Clarifying evidence requirements: for five types of claims (such as "Data A is more useful than Data B"), specifying what evidence is needed and what evidence is insufficient to support a conclusion.
This rigor ensures that data management decisions are based on verifiable evidence rather than intuition. The article also notes that explainable data properties can be tested across corpora and checkpoints, thereby forming reusable management guidelines.
Perplexity baselines are among the most common control methods in language model pretraining data selection. The idea is to use a reference model (such as a small proxy model) to compute the perplexity of candidate documents, preferentially selecting documents with higher perplexity (i.e., ones the model is less familiar with and that may contain new knowledge), or conversely selecting low-perplexity documents to ensure quality. Classifier baselines typically train a lightweight classifier to predict whether a document is "useful" and then use it to score new documents. Hybrid baselines combine multiple signals (such as quality, diversity, and repetition) with weighting. These methods are cheap to compute and easy to implement, so the article requires that new data attribution methods must be compared falsifiably against these cheap baselines after accounting for discovery cost in order to demonstrate their practical value.
Falsifiable Comparison with Baselines
Finally, the authors propose the need for falsifiable comparisons with perplexity, classifier, and hybrid baselines under the same total compute. This means that new data attribution methods must not only prove their effectiveness but also outperform existing methods in cost-effectiveness. The comparison should include discovery cost, because identifying explainable properties itself requires computational resources.
This comparison framework emphasizes scientific verifiability: if data attribution-guided pretraining cannot demonstrate an advantage over cheaper selectors, its value is questionable. The article calls on the community to adopt this rigorous evaluation standard to advance the field of data management.
Conclusion
Data attribution should not stop at ranking documents; it should guide pretraining through explainable data properties. By establishing a feedback loop, clarifying evidence requirements, and conducting falsifiable comparisons with baselines, we can transform data management from one-off optimization into reusable scientific guidelines. This is key to building more efficient and more explainable pretraining pipelines.
One-line Summary
Data attribution should go beyond one-off document ranking and become testable, reusable guidelines for pretraining data management.
Paragraph Summary
The article notes that current data selectors based on influence functions can only rank documents for a single training run; once the training configuration or checkpoint changes, the ranking may become invalid. The authors argue that data attribution should go further by identifying explainable, testable data properties and converting them into management guidelines reusable across corpora and checkpoints. To this end, a feedback loop is needed: explain the source of attribution, test candidate data changes, and clarify, for five types of claims, the required evidence and conclusions that cannot be established. Ultimately, new methods must be falsifiably compared with cheap baselines such as perplexity and classifiers under total compute that includes discovery cost, in order to scientifically validate their cost-effectiveness.
Related articles
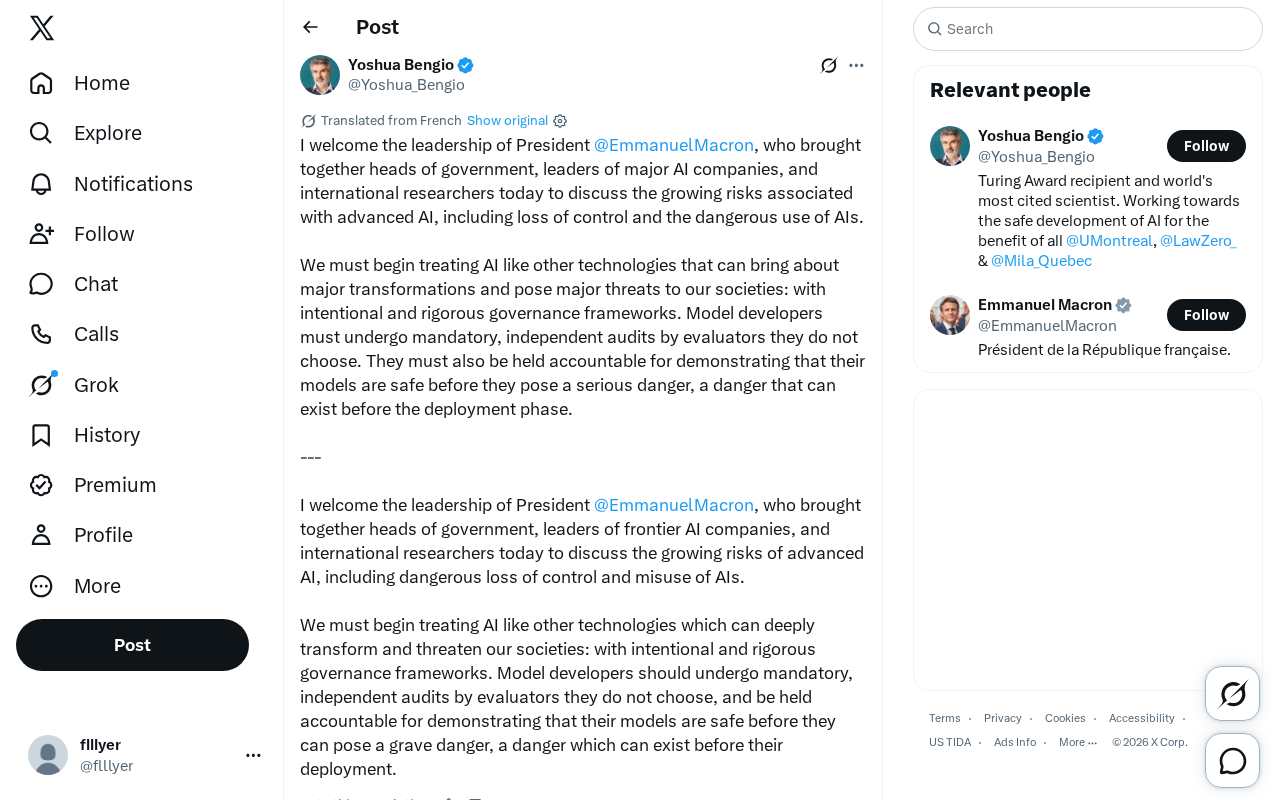
New AI Governance Initiative: Mandatory Independent Audits and Pre-Deployment Safety Proof
Macron convened government leaders, AI company executives, and researchers to discuss advanced AI risks. Statements call for a rigorous governance framework requiring mandatory independent audits and pre-deployment safety proof.

Roblox Funds Controversial Anorexia Treatment
Roblox funds flow to a controversial creator who promotes ketogenic diets over conventional treatment for anorexia and bulimia, raising medical and regulatory concerns.
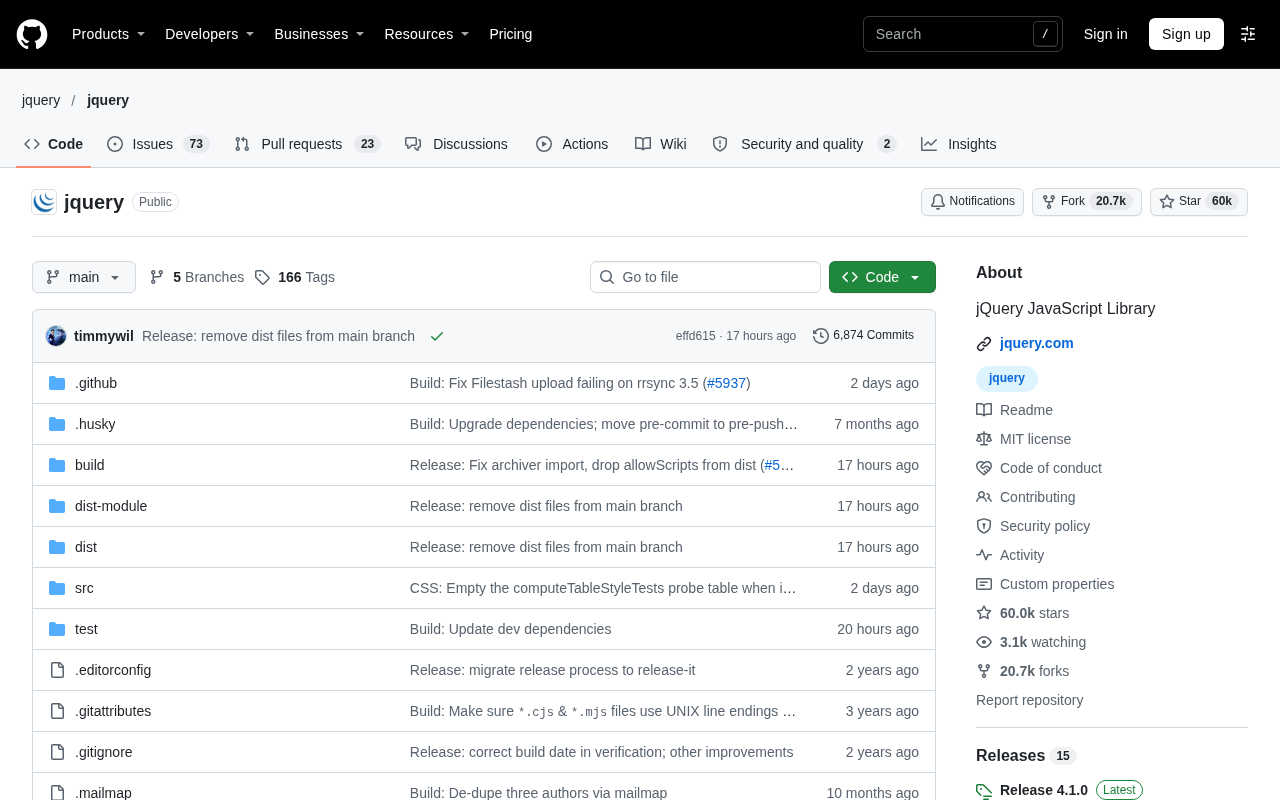
GitHub Daily · November 19: Veteran Frontend Framework Returns to the Charts, Historical Map Project Gains Nearly a Thousand Stars in a Day
GitHub Trending Nov 19: jQuery and SolidJS both make the list, Appwrite adopts an agent-oriented positioning, and Jiangshan Shixu gains nearly 1,000 stars in a day.