Databricks IP Functions Now GA: Native SQL for IP and CIDR Analysis

Databricks IP Functions hit GA: native SQL for IPv4/IPv6 and CIDR analysis, with 3.1× faster and 6.4× cheaper CIDR joins.
Databricks has announced GA for IP Functions, a set of built-in SQL functions for parsing, validating, and joining IPv4/IPv6 addresses and CIDR ranges — replacing fragile UDFs and regex workarounds. Natively optimized in the Photon vectorized engine, benchmarks show CIDR joins up to 3.1× faster and 6.4× cheaper than a leading competitor, with real cost implications for large-scale security log analysis. Databricks positions this as a key building block for its Security Lakehouse vision, enabling threat detection and network analytics on a single governed data copy.
Databricks has officially announced that IP Functions are now in GA (General Availability). This set of built-in SQL functions is designed for parsing, validating, and joining IPv4 and IPv6 addresses as well as CIDR network ranges, with performance optimizations for the Photon engine. For security and operations teams processing massive volumes of network logs every day, this is a long-awaited capability.
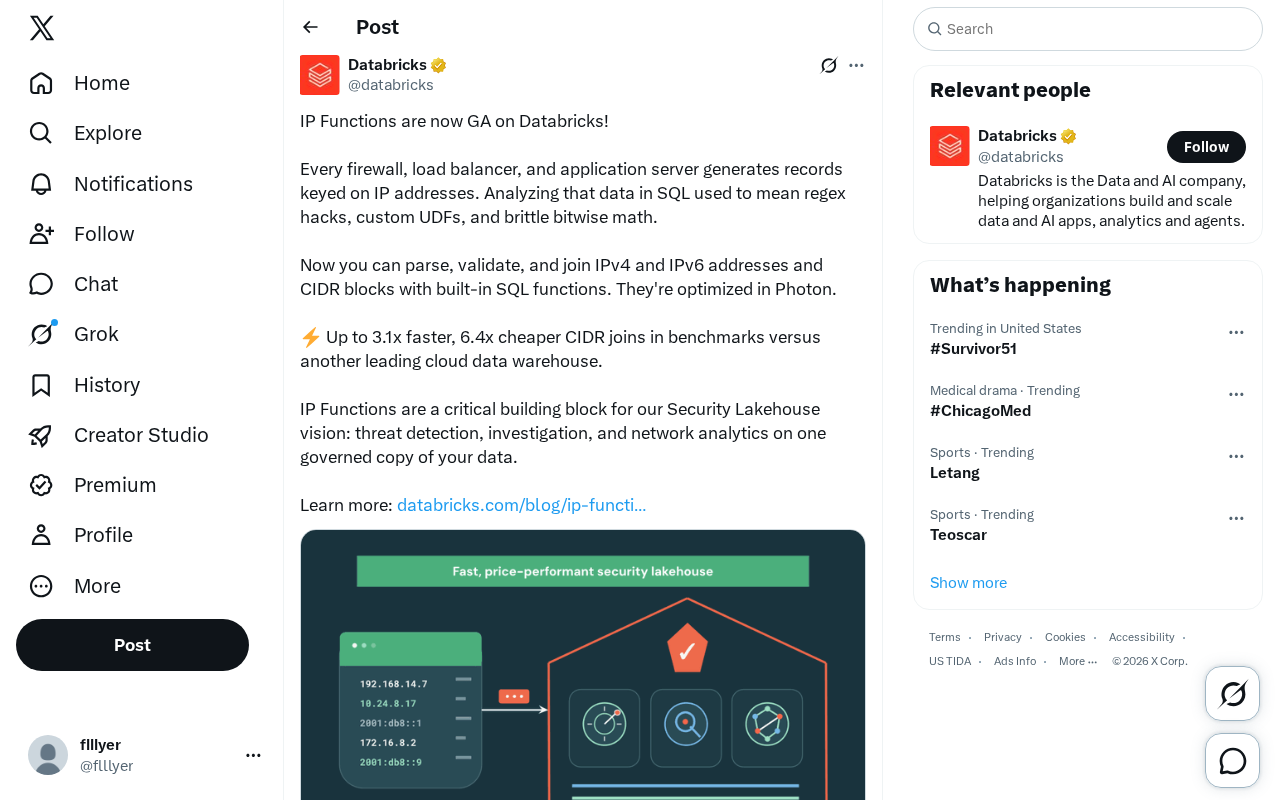
Why IP Analysis Has Always Been a Pain
Firewalls, load balancers, application servers — nearly all network infrastructure continuously generates records keyed by IP address. Yet working with this data in SQL has never been elegant.
As Databricks describes it, analyzing IP data in SQL used to mean one of three less-than-ideal approaches: hacking together regex patterns, writing custom UDFs (user-defined functions), or relying on brittle bitwise math. These solutions are hard to maintain, error-prone when dealing with mixed IPv4/IPv6 scenarios and CIDR range matching, and difficult to optimize for performance.
The core issue is that IP addresses are fundamentally numerical network objects, not ordinary strings. Using string logic to handle CIDR subnet membership or address range checks is neither intuitive nor efficient — and that's exactly what built-in functions are designed to fix.
CIDR (Classless Inter-Domain Routing) is the key concept here. CIDR uses an "address/prefix length" notation (e.g., 192.168.1.0/24 or 2001:db8::/32) to represent a contiguous block of IP addresses. Determining whether an IP belongs to a given CIDR range is fundamentally a bitmask operation: AND the IP address with the subnet mask, then compare against the network address. Without native functions, SQL engineers either simulate this logic with string manipulation (cumbersome and prone to missing IPv6's 128-bit addresses), or wrap Python/Java networking libraries in a UDF. When joining millions of log records against thousands of CIDR rules, the UDF approach hits a significant performance wall — every row incurs the overhead of a JVM or Python interpreter call.
What IP Functions Provide
Developers can now perform the following operations directly with built-in SQL functions:
- Parse: Convert text-form IP addresses into computable network objects
- Validate: Check whether an address or network range is valid
- Join: Match IP addresses against CIDR ranges — one of the most common and resource-intensive operations in network analysis
This function set covers both IPv4 and IPv6, as well as CIDR blocks. Critically, they are optimized within the Photon engine — meaning these are not just syntactic sugar, but high-performance implementations rebuilt at the execution layer.
Performance Numbers: 3.1× Faster, 6.4× Cheaper on CIDR Joins
Performance is the most compelling part of this release. According to Databricks' published benchmarks, compared to another leading cloud data warehouse, CIDR join operations achieve:
- Up to 3.1× faster execution
- Up to 6.4× lower cost
CIDR joins are a high-frequency, heavyweight operation in network log analysis — for example, matching millions of access records against a threat intelligence table of network ranges. A 6.4× cost reduction translates to real billing differences at scale for security analytics workloads. It's worth noting that benchmark results typically depend on specific data sizes and query patterns, so actual gains will vary by use case — but the directional signal is clearly positive.
Photon is Databricks' in-house vectorized query engine, written in C++, designed to leverage modern CPU SIMD (Single Instruction, Multiple Data) instruction sets and execute computations in columnar batches. It offers significant advantages over JVM-based Spark execution engines for CPU-intensive operations. IP functions implemented natively in Photon means CIDR matching bitwise operations can be executed in batch along the vectorized path, eliminating the per-row interpretation overhead of UDF calls. This also explains why the cost reduction (6.4×) far exceeds the speed improvement (3.1×) — faster execution means less time holding compute resources, and in cloud environments billed by the second, shorter execution times map directly to lower bills.
A Key Building Block for the Security Lakehouse Vision
Databricks positions IP Functions as a critical building block for its Security Lakehouse vision — a framing worth unpacking on its own.
Traditional security analysis often requires moving data back and forth between dedicated SIEM systems, data warehouses, and lake storage, creating multiple copies and making governance difficult. The Security Lakehouse approach consolidates threat detection, security investigation, and network analytics onto a single, governed copy of data.
The addition of IP Functions fills a key gap in native SQL handling of network-layer data. When low-level operations like IP parsing and CIDR matching become both fast and cheap, the technical and cost barriers to running security analysis directly on the lakehouse are significantly lowered. This aligns with the broader industry trend toward converging security operations with data platforms.
SIEM (Security Information and Event Management) systems are the backbone of traditional security operations, aggregating logs from network devices, servers, and applications for real-time correlation analysis to detect threats. However, traditional SIEMs commonly face challenges: high storage costs, short data retention windows, and fragmentation from data science and machine learning workflows. The core premise of the Security Lakehouse is replacing the closed storage of a SIEM with open-format data lakes (such as Delta Lake), letting security logs and business data share the same governance framework while supporting the full spectrum of analysis — from real-time alerting to long-horizon forensic investigations. Databricks is not the only player in this space — Snowflake, Microsoft Sentinel, and Elastic-based solutions are all pursuing similar convergence — but the GA of IP Functions marks Databricks completing native handling of network logs, one of the most critical data types in security operations.
What This Means for Actual Users
For teams already using Databricks, this GA release has several direct implications:
- Reduced technical debt: Custom UDFs and regex-based solutions can be gradually retired in favor of standard functions
- More reliable queries: Built-in validation logic reduces the probability of errors when handling edge cases like IPv6
- Predictable costs: Large-scale CIDR joins under Photon optimization are more cost-effective, making long-running security intelligence matching workloads more sustainable
For security and data engineering teams evaluating platform choices, this is also a signal — Databricks is actively extending the lakehouse from a general-purpose analytics platform toward one that covers security operations use cases. IP Functions are a small feature in isolation, but they reflect the platform's ongoing effort to fill capability gaps for vertical scenarios.
For more details, refer to the official documentation published by Databricks.
Related articles

Random Pruning of the DPO Computation Graph: 1.4x Training Speedup and Lower Peak Memory
DPO training too slow and memory-hungry? This paper proposes a random pruning framework for the DPO computation graph, sampling independently across position, sequence, and branch dimensions; branch pruning achieves a 1.426x step-time speedup and cuts training time by about 30%, with in-depth attribution of memory and time gains.

Why Does JEPA Underperform MLM in Longitudinal EHR Representation Learning?
New study compares JEPA and MLM for longitudinal EHR representation learning on MIMIC-IV: three JEPA variants train stably without collapse but underperform MLM; target size, not heterogeneity, drives prediction error.

Transfer Learning + Visible Light Communication: A New Approach to Energy-Efficient Indoor Positioning
A study proposes a transfer learning-based visible light communication indoor positioning method, achieving 47% accuracy improvement on the BOSCH factory dataset, 67.5% model efficiency under high noise, and introducing the ME composite metric for energy-efficient positioning in energy-constrained industrial IoT scenarios.