DeepSeek V4.1 Flash Real-World Test: Price Down 60%, So Why Did Total Cost Go Up 36%?

V4.1 Flash cuts input price 60% but real-world agent costs rose 36% — here's why.
DeepSeek V4.1 Flash uses an asymmetric MoE structure (80B input / 160B output activation) designed for Agent workloads, with cache-hit pricing slashed 60%. While benchmarks show clear wins on coding and Agent tasks, PhD-level reasoning scores actually regressed versus V4 Pro. A 300M-token community test found total costs up 36% due to aggressive sub-agent spawning, and a silent routing decision — swapping V4 Pro calls to Flash without notice — triggered widespread developer backlash over API stability.
"Across-the-Board Improvement"? Let's Look at the Numbers First
DeepSeekAd released V4.1 Flash on September 10th, officially positioning it as a model that "comprehensively surpasses" its own flagship V4 Pro. But once you read through that official benchmark table row by row, you'll find a gap between the marketing language and the actual data — and that gap is more telling than the numbers themselves.
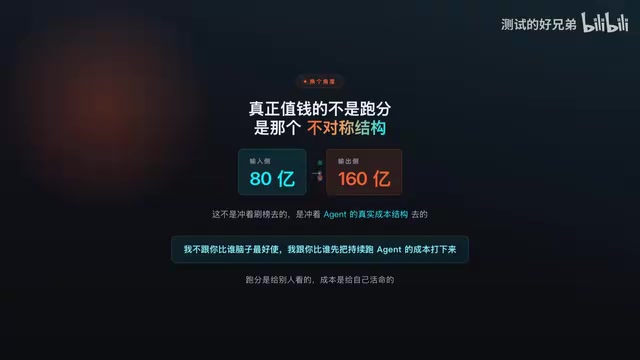
Let's start with the technical foundation. V4.1 Flash has 552B total parameters and is a Mixture of Experts (MoE) model with a new asymmetric causal encoder-decoder architecture. Its defining feature is an asymmetry between input and output: only 8B parameters are activated during input, while 16B are activated during output.
The logic behind this asymmetric design is straightforward. Agent-type tasks have a naturally skewed token distribution — you might feed in tens of thousands of tokens of context and tool responses, only to get back a few hundred tokens of output. Since most compute is spent on "listening," it makes sense to minimize activations on the input side and fire on all cylinders only when it's time to "speak." DeepSeek is betting on this token distribution pattern, and for Agent scenarios, it's a reasonable bet.
What is a Mixture of Experts (MoE) model? MoE is a sparsely activated neural network architecture. Unlike traditional dense models — which run all parameters on every inference pass — MoE models split parameters into multiple "expert" sub-networks, with a router selecting only a small subset of experts for each inference. The benefit: total parameter count can be very large (boosting knowledge capacity), while actual compute per inference involves only the activated subset, dramatically reducing computational requirements and inference latency. V4.1 Flash has 552B total parameters, but actual activation is only 80B (input) to 160B (output) — a textbook MoE design. Understanding this mechanism is the prerequisite for making sense of all the performance and cost figures in this article. "552B model" and "80B activation" are not contradictory: the former is capacity, the latter is the actual cost at inference time.
The Number Trap in Cache Compression
The cache compression improvements this generation are genuinely aggressive, but there's a common misreading circulating in the community that needs clearing up.
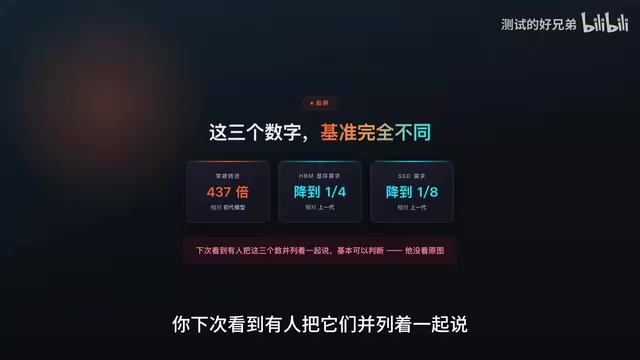
Many people say "this generation's cache is 437x smaller" — technically true, but the baseline has been swapped out. The 437x figure is relative to the first-generation model, not the previous version. Relative to the last version, the official figures are: high-bandwidth memory requirements reduced to one-quarter, and SSD requirements reduced to one-eighth.
These three numbers (437x, 1/4, 1/8) have completely different baselines. If you see someone citing them side by side as if they're comparable, you can safely conclude they haven't looked at the original official materials.
On pricing: starting at noon on September 10th, cache-hit input dropped to $0.02 per million tokens, cache-miss input is $1, and output is $4. The cache-hit rate alone dropped by 60%. Note, however, that these are off-peak prices. Peak hours (two windows on weekday mornings and afternoons) are double the price; all other times, including full weekends, count as off-peak.
Another product-level change: the "Fast / Expert / Real-time" three modes previously available on the web and app have been consolidated into a single interface, all routing to V4.1 Flash. Users no longer need to choose manually.
The Two Sides of the Benchmark: Engineering Wins, Reasoning Loses
The benchmark table is where this story gets interesting.
On coding and Agent tasks, V4.1 Flash shows genuine, meaningful improvements over the previous flagship: Terminal Bench 2.1 scores 90.6 vs. 87.9; Terminal Bench 3.0 scores 30 vs. 11.8; Terminal Bench 4.0 scores 31.2 vs. 12.4; SWE-bench 74.2 vs. 62.7; cybersecurity 88.1 vs. 83.3; automated task completion 54.8 vs. 43.2. Flash wins across the board on these, and by meaningful margins.
But scroll down the same table and two rows tell a different story: GPQA Diamond (PhD-level science Q&A), Flash scores 90.9 against V4 Pro's 92.4; "Humanity's Last Exam," Flash scores 36.8 against V4 Pro's 42.7.
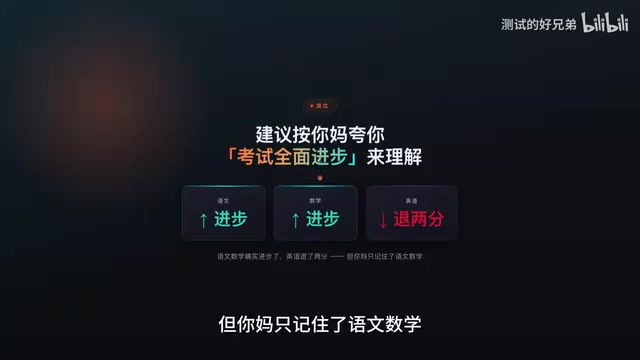
Both of these are pure knowledge-reasoning tasks — the exact opposite of coding and Agent work. In other words, Flash's strengths are concentrated in engineering-type tasks, while its weaknesses lie in knowledge reasoning. "Comprehensively surpasses" would be more accurately described as "meaningful progress on engineering tasks, regression on reasoning tasks" — the word "comprehensive" doesn't leave room for exceptions.
The competitor comparison rows make the picture even clearer. Terminal Bench 3.0: V4.1 Flash scores 30, while competitors score 34.4 and 43.3. Terminal Bench 4.0: 31.2 vs. 39.9 and 51.8. The most nuanced case is SWE-bench — Flash's 74.2 is the highest score on the entire table, but it leads the strongest competing flagship by only 0.2 points. The real conclusion: Flash has caught up to the top tier on engineering and Agent tasks, and is neck-and-neck with the leaders in some areas, but hasn't pulled away — it's running alongside them, not ahead. On pure reasoning, it still trails.
Price Down 60%, Total Cost Up 36% — Here's Why
More revealing than the benchmark scores is a community real-world test. This test ran 300 million tokens across 14 task groups and over 2,400 requests — and critically, it was completed before the September 10th price cut.
The conclusion was surprising: under the same billing framework, V4.1 Flash's total cost was 36% higher than the previous version. Unit price went down; total bill went up.
The reason: the model tends to spawn more sub-agents on complex tasks. In the test, one large game task and one 100,000-character novel task together spawned 37 sub-agents, burning through over a million tokens on sub-tasks alone. Those 37 sub-agents "work for free, but they all submit expense reports."
A second real-world test makes the point even more clearly: one developer tested a 3D garage webpage, achieving an output speed of 335 tokens per second — blazingly fast. But the full task took over three hours to complete, with roughly 80% of that time consumed by the loop of "render → screenshot → hand off to vision model → not satisfied → revise."
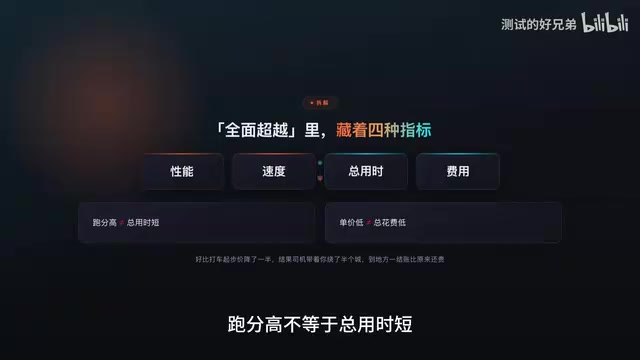
This highlights a key insight: fast output speed does not equal fast delivery. Total time on an Agent task depends on how many back-and-forth iterations it takes. It's like a taxi cutting its starting fare in half, but then taking you halfway around the city — you end up paying more than before when you arrive. "Comprehensively surpasses" actually contains four distinct metrics — performance, speed, total time, and cost — and in real-world scenarios, they frequently work against each other. A high benchmark score doesn't mean short total time; a low unit price doesn't mean a low total bill.
Silent Routing and the Community Backlash
The biggest controversy this week has nothing to do with the technology — it's a product decision. On September 9th, DeepSeek announced that all requests to V4 Pro would be silently routed to V4.1 Flash, billed at Flash prices, on the grounds of that "comprehensive superiority" claim.
Translated into plain language: existing customers keep paying on V4 Pro terms, but the backend has quietly been swapped to Flash — with no notification.
The open-source community responded with nearly unanimous opposition, and the objections were highly focused — not on the technology, but on "you made this decision for me." One developer put it well: if you spent months tuning prompts and Agent workflows around V4 Pro's specific behavior, all of that tuning is tailored to how that particular model acts. A silent backend swap could break your production pipeline, and you'd have no starting point for debugging.
There were also more pragmatic concerns: a B2B product charges clients on V4 Pro-tier pricing, inference suddenly gets faster, the boss assumes it's an optimization win — then V4.1 Pro launches and speeds revert. Who's responsible for that gap?
The core issue comes down to one question: is a model name a contract, or an implementation detail? For developers, a model name is a stable API interface. Changing it without notice is unilaterally voiding an unwritten agreement. The official response was to push the deprecation date from September 10th to noon on September 14th — but only the timeline changed. The plan stayed the same: on that date, all requests would still be fully routed to Flash and billed at Flash rates.
What is "silent routing"? In cloud service contexts, silent routing refers to a provider replacing the actual model behind an API endpoint with a different model — without notifying users. Unlike explicit deprecation (advance notice, transition period, clear version identifiers in responses), silent routing gives callers no way to detect the backend change through logs or response headers. For LLM API users, this creates several concrete problems: prompts tuned for specific model behaviors may silently stop working as expected; A/B tests gain an uncontrolled variable; billing records still show the old model name, but the actual cost structure has changed. This is precisely why OpenAI, Anthropic, and other major providers maintain endpoints with precise version numbers (e.g.,
gpt-4o-2024-08-06) and announce deprecations months in advance. DeepSeek's approach deviated from this industry norm, which is the institutional context for the backlash.
Migration Recommendations: Three Tiers
To be fair, some of the criticism went too far. That "36% higher total cost" figure is essentially irrelevant if your workload consists of short, focused tasks that don't trigger multi-agent spawning — you'd simply experience a 60% price cut. Spreading that number without its context means using someone else's scenario to frighten yourself.
Also worth noting: the real value this generation isn't the benchmark scores — it's the asymmetric architecture itself. Input at 8B, output at 16B wasn't designed to chase leaderboards. It was designed around the actual cost structure of running Agents at scale. The goal is explicit: don't try to be the smartest model in the room; instead, be the first to drive down the sustained cost of running Agents continuously.
Here are recommendations broken into three tiers:
- Tier 1 (currently on the old Flash): Switch now, no hesitation. Performance is up and unit price is down.
- Tier 2 (running V4 Pro in production): Run migration tests immediately — don't wait until the 14th. Focus your testing on whether key numbers in long-context documents are retained correctly. Real-world tests repeatedly surfaced mismatches between figures at the beginning and end of long documents.
- Tier 3 (long-document workflows, high consistency requirements): Run a limited pilot before committing. The vision improvements are real — short visual tasks dropped from hundreds of seconds to around ten seconds — but long-context consistency and tool-call feedback handling remain relatively weak.
When evaluating a model release, read both what the company says and what the company's own tables actually show. In the same source material, the gap between the marketing language and the data is often more informative than the data itself. The competition going forward may no longer be about single-point benchmark scores, but about sustained reliability per unit cost. You can win a benchmark once; you pay the bill indefinitely.
Related articles

Amphibious Transforming Drone: Beyond 100x Power Savings, What Are the Real Needs?
Is the amphibious transforming drone just a gimmick? Starting from the 100x power difference of the M4 Morphobot, explore real application scenarios and thesis topic ideas, analyzing boundary conditions where pure drones and pure ground robots both fail.

Warhound Raises $200 Million: Genetically Engineered "War Dogs" Paired with Anduril Gear
Warhound raises $200M, backed by Ben Lamm and Palmer Luckey, to genetically engineer dogs for military and law enforcement use and equip them with Anduril gear. This article analyzes its technology direction, funding logic, and ethical controversy.

Claude API Comes to Google Cloud: IAM Integration and SDK Access Guide
Anthropic hosts the full Claude API on Google Cloud with IAM-controlled permissions and unified billing. This guide covers the Vertex AI and Anthropic-hosted entry points, IAM role configuration, and SDK access.