Domain Fine-Tuning Erodes AI Safety Guardrails: A Paired Audit of Biomedical LLMs
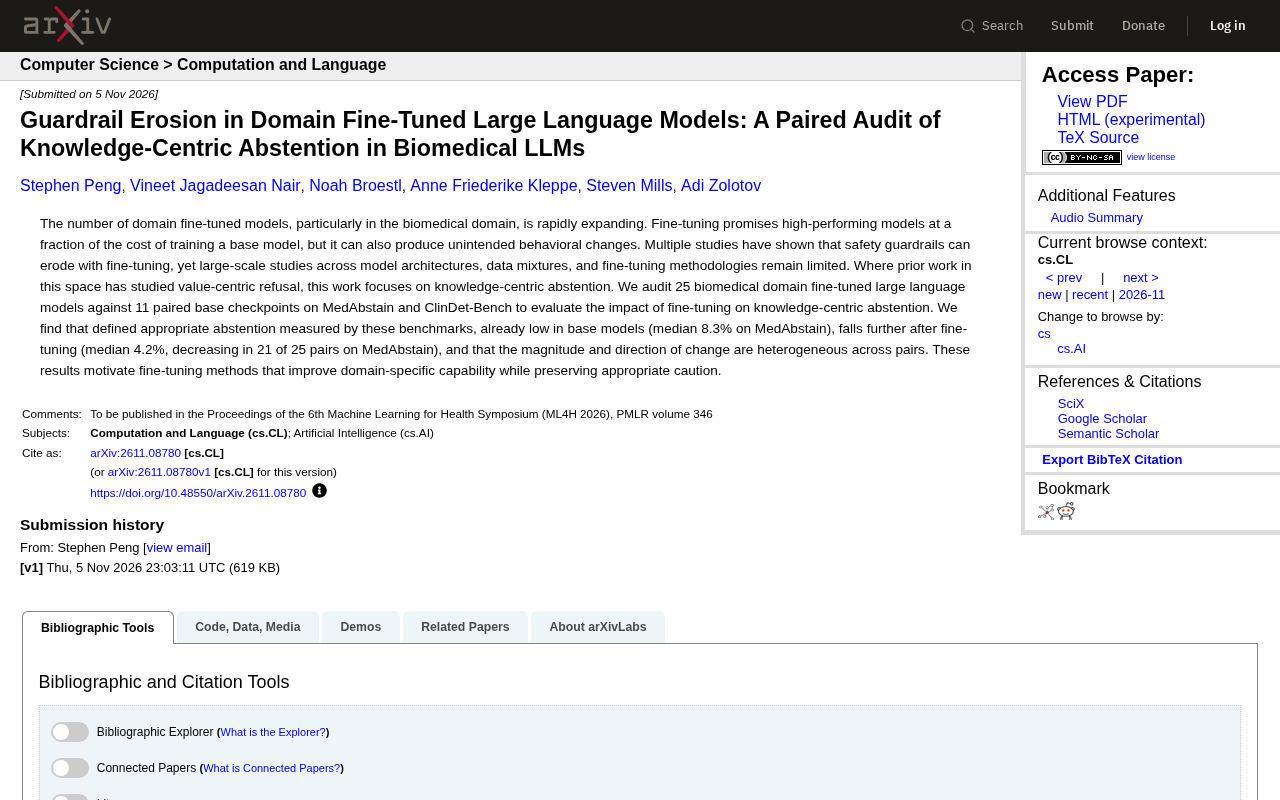
Biomedical domain fine-tuning significantly weakens LLMs' appropriate abstention at knowledge boundaries, risking erosion of safety guardrails.
The study audits how biomedical domain fine-tuning affects knowledge-centric abstention, comparing 25 domain fine-tuned models with 11 paired base checkpoints using MedAbstain and ClinDet-Bench. The already low median appropriate abstention rate (8.3%) fell further to 4.2% after fine-tuning, with 21 of 25 pairs declining. The study highlights heterogeneity in magnitude and direction, suggesting data ratios, methods, and architecture all matter, and calls for fine-tuning methods that balance domain capability with caution and for adding abstention to evaluation and pre-deployment checklists.
Domain fine-tuning can make models perform better in a specific domain, but it may also quietly change how the model behaves. A study of biomedical large models found that after fine-tuning, the model's ability to "appropriately abstain" at the boundaries of its knowledge drops significantly, and safety guardrails risk being eroded.
Research Background: From Value Refusal to Knowledge Abstention
Past discussions about how fine-tuning affects safety have mostly centered on "Value-Centric Refusal"—that is, whether the model refuses to generate harmful content. But this study shifts the focus to another dimension: Knowledge-Centric Abstention.
Knowledge-centric abstention refers to the model's ability to proactively say "I don't know" or decline to answer when it encounters something its own knowledge is insufficient to answer, or when a question exceeds its reliable range. For high-stakes domains like biomedicine, this ability to "know what it doesn't know" is especially important—a confidently wrong answer can have serious consequences.
The study notes that the number of domain fine-tuned models is expanding rapidly, especially in biomedicine. Fine-tuning promises high-performance models at a cost far below training a base model from scratch, but it can also produce unintended behavioral changes. Although multiple studies have shown that safety guardrails erode with fine-tuning, large-scale research across model architectures, data mixtures, and fine-tuning methods remains limited.
Value-Centric Refusal refers to the model's ability to refuse to generate the corresponding content when faced with clearly harmful, illegal, or unethical requests—a typical example being refusing to help make dangerous items or write hate speech. This kind of safety alignment is usually implemented during the post-training phase of the base model through reinforcement learning from human feedback (RLHF) or rule-based refusal data injection, and its focus is "should it be said."
By contrast, Knowledge-Centric Abstention focuses on "does it know"—the model needs to judge whether a question falls within the range of its own reliable knowledge. Their failure modes also differ: when the former fails, it outputs harmful content; when the latter fails, it outputs plausible-sounding but unfounded misinformation (i.e., hallucination). In high-stakes scenarios such as biomedicine, the harm of the latter is often more insidious, because it does not trigger explicit safety filters, yet it can directly mislead clinical judgment or patient decisions.
Audit Design: 25 Models and 11 Paired Baselines
To quantify the impact of fine-tuning on knowledge abstention, the researchers audited 25 biomedical domain fine-tuned large language models and compared them with 11 paired base checkpoints. The evaluation used two benchmarks: MedAbstain and ClinDet-Bench.
The key to this paired design is that each fine-tuned model can be directly compared with its corresponding base model, thereby isolating the behavioral changes brought about by fine-tuning itself rather than interference caused by model architecture or differences in initial training. This is also the core methodological contribution that distinguishes this study from prior work.
Base checkpoint refers to the snapshot of model weights loaded before domain fine-tuning begins, usually a general-purpose pretrained or general-purpose instruction-tuned model. Comparing a fine-tuned model derived from the same base with the base itself in a paired manner is a classic experimental design for auditing the side effects of fine-tuning: because the two share architecture, tokenizer, and initial training data, differences can be more cleanly attributed to the data and methods of the fine-tuning stage.
MedAbstain and ClinDet-Bench are evaluation benchmarks oriented toward abstention behavior. The former focuses on the expression of "I don't know" by models in medical question-answering scenarios when faced with questions beyond their knowledge boundaries, while the latter focuses on certainty detection in clinical contexts. The evaluation metric for such benchmarks is usually not accuracy but appropriate abstention rate—that is, the proportion of samples on which the model should abstain where it actually chooses to abstain. This explains why the paper reports a seemingly very low figure like "a poor-performing 8.3%": it measures caution rather than amount of knowledge.
Core Finding: Abstention Rates Decline Across the Board
The audit results are not encouraging. On the MedAbstain benchmark, the appropriate abstention rate of base models, which was already poor (median only 8.3%), fell further to a median of 4.2% after fine-tuning. More alarming is that 21 of the 25 model pairs showed a decline in abstention rate, indicating that this trend is quite widespread.
The researchers also point out that the magnitude and direction of change are heterogeneous across model pairs. This means that the impact of fine-tuning on abstention behavior is not uniform—some models may be more severely affected, while a few may even improve. This heterogeneity suggests that fine-tuning methods, data ratios, and model architecture may all play a role.
"These results prompt us to think: we need fine-tuning methods that can enhance domain capability while preserving appropriate caution," the study writes in its conclusion. In other words, current fine-tuning practices may systematically weaken the model's "self-awareness" while improving professional knowledge.
Heterogeneity here means that different model pairs do not agree in the direction and magnitude of changes in abstention rate; some models degrade severely, while a few even improve slightly. Possible factors contributing to heterogeneity include: the scale of fine-tuning data and its domain fit, whether general instruction data is mixed in, whether full-parameter fine-tuning or parameter-efficient fine-tuning (such as LoRA) is used, and hyperparameters such as learning rate and number of training epochs.
A frequently discussed mechanism is catastrophic forgetting and distribution shift: domain fine-tuning pulls the model's output distribution toward typical question-answering patterns within the domain, and such data often consists mainly of "giving answers" and rarely contains samples of "I don't know," so the model learns a tendency to "answer every question." In addition, cautious behavior acquired during the instruction-tuning stage may be overwritten by subsequent domain training. This suggests that explicitly adding abstention samples to fine-tuning data or imposing regularization constraints may alleviate the degradation.
Why This Matters for Biomedical AI
Biomedical scenarios have extremely low tolerance for model errors. A model that still answers confidently beyond its knowledge boundaries may give seemingly reasonable but actually wrong medical advice. A decline in knowledge-centric abstention ability means that fine-tuned models are more inclined to "force an answer" rather than admit uncertainty.
The results issue a direct warning to practitioners of domain fine-tuning: when pursuing downstream task performance, abstention behavior needs to be incorporated into the evaluation system. Achieving high scores on standard benchmarks alone does not mean the model is reliable enough in real-world use. At the same time, this also points the way for research on fine-tuning methods—how to design training objectives or regularization approaches to protect the model's caution during domain adaptation.
For organizations deploying biomedical large models, this audit provides an actionable checklist: before and after fine-tuning, use benchmarks similar to MedAbstain to test changes in the model's abstention rate, avoiding safety guardrails being eroded without anyone noticing.
One-line Summary
Domain fine-tuning in biomedicine significantly weakens large models' appropriate abstention ability at knowledge boundaries, and safety guardrails risk being eroded.
Paragraph Summary
This study audits the impact of domain fine-tuning in biomedicine on models' knowledge-centric abstention ability, comparing 25 domain fine-tuned models with their 11 paired base checkpoints and evaluating them using two benchmarks, MedAbstain and ClinDet-Bench. The results show that the already low median appropriate abstention rate of base models (8.3%) fell further to 4.2% after fine-tuning, with 21 of the 25 model pairs showing a decline. The study emphasizes heterogeneity in the magnitude and direction of change, indicating that fine-tuning data ratios, methods, and architecture may all play a role. The authors call for designing fine-tuning methods that balance domain capability and caution, and for incorporating abstention behavior into fine-tuning evaluation and pre-deployment checklists.
Related articles
Seven Years of Evolution: How Far Has the Foldable Come From the First Generation?
From the first foldable to today's latest models, what has seven years changed? Shallower creases, higher brightness, thinner bodies, and smoother software migration—has the foldable crossed the chasm from enthusiasts to ordinary users? This article discusses the question based on a video comparison.
When Did Humans Start Eating Salt? A 10,000-Year History of Salt
When did humans start eating salt? From salt use at the dawn of agriculture 11,000 years ago to ancient seawater evaporation and rock salt mining, and on to the salt trade, salt taxes, and Gandhi's Salt March, this article traces salt's key role in human civilization.
Microsoft Paza Research: How African Language Speech Recognition Breaks Through Architecture and Data Bottlenecks
Microsoft's Paza research evaluates 53 speech models across 39 African languages, revealing architecture choice matters more than pre-training coverage, 200-300 hours is the practical data threshold, and language typology deeply influences recognition performance.