Don't Get Confused: Ollama, llama.cpp, and OpenAI Explained

A clear breakdown of Ollama, llama.cpp, and OpenAI to help you choose the right local or cloud AI deployment.
Frequent cloud AI outages have driven more developers toward local deployment, but the terms Ollama, llama.cpp, and OpenAI are often confusing. This article clearly distinguishes the three: Ollama is the usage layer that simplifies model running with a single command and an OpenAI-compatible API; llama.cpp is the lower-level inference engine handling GGUF conversion, quantization, and fine-grained parameter control; OpenAI is a pure cloud API solution that removes all local hardware concerns but cedes stability and data sovereignty to the provider. The three are complementary, and your choice depends on how much control you need versus how much maintenance you're willing to handle.
Cloud AI reliability issues are pushing more and more developers toward local deployment. Recent widespread outages and errors from OpenAI have forced a rethink: as workflows grow increasingly dependent on the cloud, shouldn't we have a setup we truly control?
When you actually start exploring this, you'll immediately run into three names that keep coming up — Ollama, llama.cpp, and OpenAI. They're often mentioned in the same breath, yet they operate at completely different levels. This article explains exactly where each one fits.
Why Local Deployment Is Getting Attention Again
Cloud AI is undeniably convenient, but it hands stability and security over to someone else. When a provider goes down, your entire workflow can grind to a halt instantly. When AI touches real business data, sending that data to the cloud raises serious security concerns that can't be ignored.
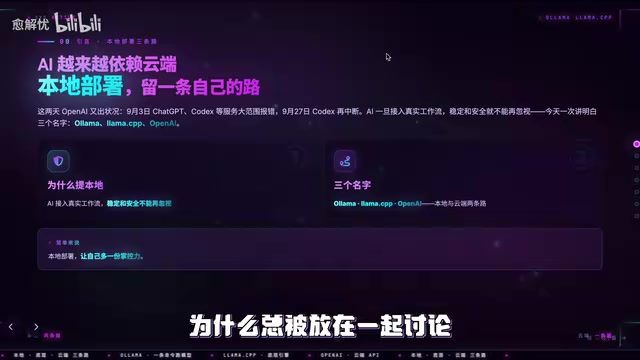
Talking about local deployment right now isn't about immediately replacing the cloud — it's about having more options and more control. As models get smaller and consumer hardware gets more powerful, local AI running on more devices is only a matter of time. Understanding the roles of Ollama, llama.cpp, and OpenAI is the first step to getting started with local deployment.
Ollama: The Mainstream Choice for Local Deployment
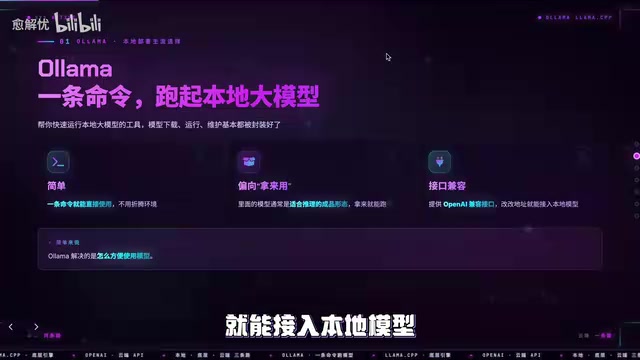
Ollama is best understood as a tool that lets you quickly run large language models locally. Its core value lies in wrapping a complex process into an extremely simple experience.
Ready out of the box. Model downloading, running, and management are all handled for you. A single command is all it takes to get started — no need to worry about underlying details.
Designed for immediate use. Models used in Ollama are typically already in a finished, inference-ready form. It's better suited for running models directly rather than starting from raw weights for training, conversion, or quantization. In short, Ollama solves the problem of how to use a model conveniently.
API compatibility. It provides an OpenAI-compatible API, so many existing applications can switch to a local model simply by changing the endpoint URL. This dramatically lowers the cost of migrating from cloud to local.
llama.cpp: The Lower-Level Inference Engine
If Ollama is the usage layer, then llama.cpp sits much closer to the model's underlying execution layer.
Responsible for making models actually work in local inference. Raw model weights you download may still be in formats like Safetensors, which typically need to be converted and quantized into the GGUF format before llama.cpp can load and run them. Think of the pipeline this way: raw weights are the "raw material," GGUF is the "finished format" commonly used for local inference, and llama.cpp is the underlying engine that runs it.
More control. Model conversion, quantization, loading, and inference parameters are all in your hands. This level of granularity is something higher-level tools like Ollama intentionally abstract away.
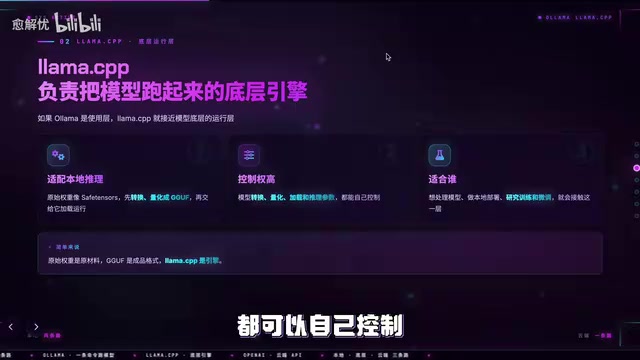
The conclusion is clear: if you just want to run a model, Ollama is more convenient. But if you want to go deeper — processing models, doing advanced local deployment, or even exploring training and fine-tuning — you'll inevitably end up working with llama.cpp. In fact, Ollama relies on inference capabilities similar to llama.cpp under the hood. The two are complementary, not competing.
GGUF format is a model file format specifically designed by the llama.cpp project. Standing for GPT-Generated Unified Format, it replaced the earlier GGML format in 2023. Its design goal is to pack everything needed for inference — model weights, quantization parameters, tokenizer vocabulary, and more — into a single file for easy distribution and loading. Quantization is the process of compressing model weights from high-precision floating-point numbers (such as FP32 or FP16) into lower-bit integers (such as Q4 or Q8), which dramatically reduces VRAM usage and memory bandwidth requirements at the cost of a slight loss in precision. To put it in perspective: a 7-billion-parameter model in FP16 requires roughly 14GB of VRAM, while 4-bit quantization can compress that down to around 4GB — making inference on consumer-grade GPUs or even pure CPU feasible. Ollama handles all of these steps automatically in the background, while llama.cpp exposes every step to the user, making it ideal for scenarios that require fine-tuning for specific hardware.
OpenAI: A Completely Different Approach
Unlike the previous two, OpenAI is a fully cloud-based solution.
The model doesn't run on your machine. It runs in the cloud. Your application sends requests via API, the cloud handles the inference, and the results are returned to you.
No local hardware concerns. How large the model is, whether you have enough VRAM, how to deploy it — these are all handled by the cloud. You don't have to think about any of it.
Simpler development and maintenance. SDKs, tools, and services are all provided by the cloud. You don't need to maintain models or servers. This makes OpenAI the better fit for developers who don't want to manage their own infrastructure and care more about development velocity.
The trade-off is that both stability and data sovereignty are in the provider's hands — which is exactly the risk exposed by the outage events mentioned at the start of this article.
The OpenAI-compatible API is an important concept in today's local deployment ecosystem. When OpenAI launched the APIs for its GPT model series, it defined a standard HTTP interface specification — including endpoints like /v1/chat/completions and /v1/embeddings along with their request formats. Given OpenAI's market position, this specification has effectively become an industry standard. Many local inference frameworks — including Ollama, LocalAI, and vLLM — have all chosen to implement this same interface specification. This means that applications built on the OpenAI SDK can switch to a local model simply by changing the base_url from OpenAI's cloud address to a local service address, with no changes to any business logic. This compatibility dramatically reduces migration costs and is a key reason why local deployment solutions can integrate so smoothly into existing development workflows.
A Quick Comparison of All Three
Put side by side, the picture becomes very clear:
- Ollama: Focused on conveniently running local models, with an emphasis on out-of-the-box usability.
- llama.cpp: Closer to the underlying inference engine, offering full control over conversion, quantization, and inference parameters.
- OpenAI: Cloud-based model access that eliminates all local maintenance overhead.
Which path you choose ultimately comes down to how much control you want and how much maintenance you're willing to take on. To quickly try out local models, start with Ollama. To go deeper under the hood, drop down to llama.cpp. If you're focused purely on development efficiency and don't mind depending on the cloud, OpenAI remains the hassle-free option.
The future of AI likely won't be limited to the cloud. Taking time now to understand the local deployment stack isn't about abandoning cloud services immediately — it's about giving your future self more room to maneuver when it comes to balancing stability, security, and cost.
Related articles

Chain of Thought Isn't Just for AI: How Humans Can Use CoT to Improve Thinking Quality
Chain of Thought isn't just a prompt trick for large models. Starting from a Hacker News discussion, this article analyzes why CoT works for human thinking too, breaks down actionable ways to transfer it, and highlights the key differences between human CoT and machine CoT.
Cloudflare Teams Up with OpenAI: Closi…
Cloudflare Teams Up with OpenAI: Closing the Loop from Vulnerability Discovery to Defense with AI
Cloudflare uses OpenAI Daybreak to investigate security vulnerabilities and generate reviewable remediation plans, while developers use Codex to boost coding efficiency and quality.

Orca Multi-Agent Orchestration in Practice: A Guide to Parallel Collaboration with Claude and Codex
Orca is Stable AI's free open-source agent workbench supporting 34 agents like Claude Code and Codex in parallel. Learn its Git worktree isolation, multi-model orchestration, and mobile management.