Gating Mechanisms Determine SSM Success: The Trade-off Between Memorization and In-Context Learning
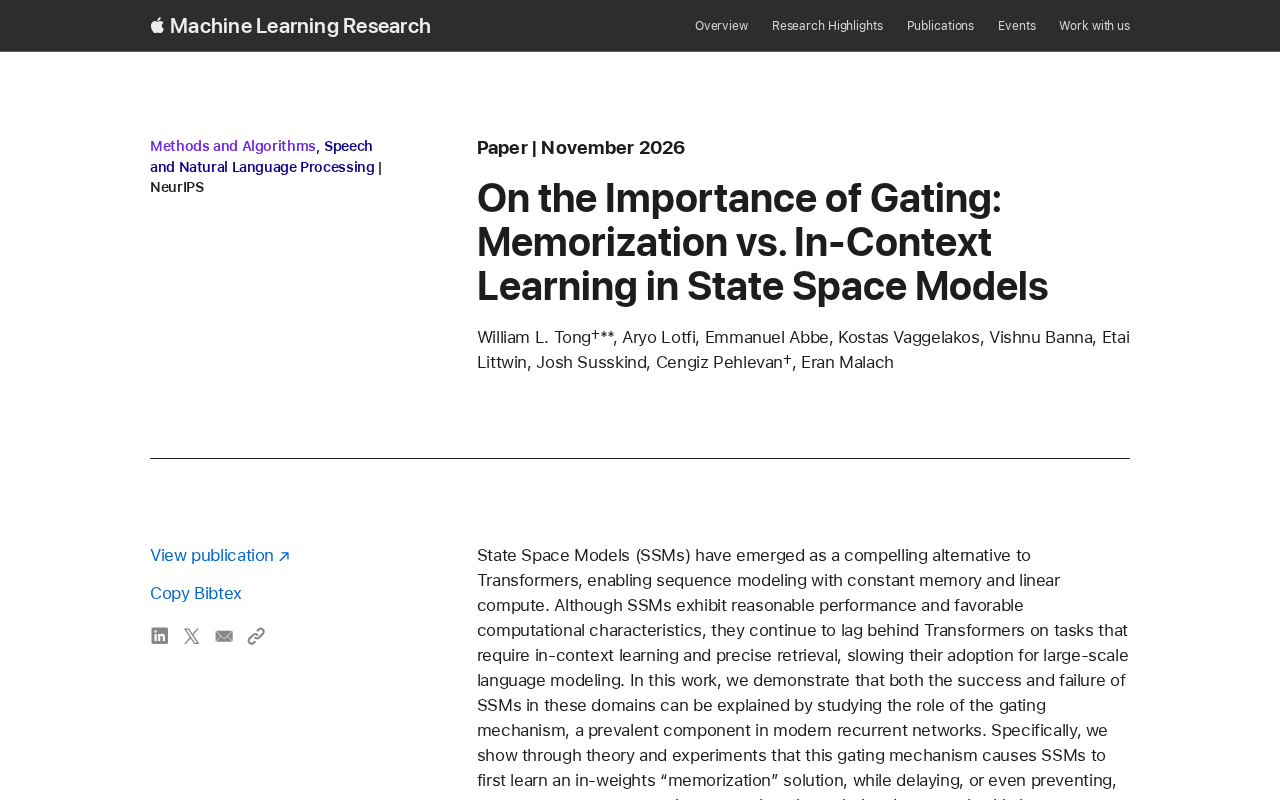
Gating mechanisms are the key determining the trade-off between memorization and in-context learning in SSMs, thereby affecting their retrieval capabilities.
This article interprets a study on the gating mechanisms of state space models (SSMs). SSMs excel at constant memory and linear complexity but lag behind Transformers in in-context learning and precise retrieval. The study identifies gating as the key: it controls information flow and retention across time steps, drawing a trade-off between "memorizing training data" and "dynamically leveraging the current context." When gating favors long-term retention, the model relies more on memorization; when it allows flexible updates, it excels at extracting information from context. This explains the source of SSM performance differences and shifts the limitation from the architectural paradigm to component design. The article accordingly proposes that designing input-dependent dynamic gating for task requirements could narrow the gap with Transformers while maintaining computational advantages, and cautions that overemphasizing dynamics can harm long-range memory.
State space models (SSMs) have recently been viewed as a strong alternative to Transformers, capable of sequence modeling while maintaining constant memory and linear computational complexity. However, SSMs consistently lag behind Transformers on tasks requiring in-context learning and precise retrieval, which has hindered their widespread adoption in large-scale language modeling. A study titled "On the Importance of Gating: Memorization vs. In-Context Learning in State Space Models" turns its attention to a ubiquitous component in modern recurrent architectures—the gating mechanism—in an attempt to explain SSMs' successes and failures in these domains.
Gating Mechanisms: A Double-Edged Sword for SSM Capabilities
The core finding of the study is that SSM performance on in-context learning and precise retrieval is closely tied to the design of the gating mechanism. Gating is not a trivial detail; it effectively draws the line between two distinct modes of information processing: memorization and in-context learning.
In SSMs, gating controls the flow and retention of information across time steps. When gating favors long-term information retention, the model relies more on memorization of training data; when gating allows more flexible state updates, the model is more likely to extract useful information from the current context. This trade-off directly affects the model's performance on tasks that require dynamic use of the input context.
The paper points out that it is precisely this dual role of the gating mechanism that explains why SSMs perform reasonably on some tasks yet fall noticeably short on tasks requiring precise retrieval and contextual reasoning. This perspective shifts SSM limitations from the architecture itself to the design choices of specific components, providing a clear direction for improvement.
The trade-off between memorization and in-context learning can be understood as two different pathways through which a model leverages information. Memorization refers to embedding statistical regularities and facts from the training corpus into the weights, which can be called upon at inference time without looking at the context; in-context learning requires temporarily using new information from the input at inference time. The two impose opposite requirements on state updates: emphasizing memorization requires the state to change slowly and remain stable over the long term in order to accumulate generalizable statistics; emphasizing in-context learning requires the state to respond quickly and selectively to the input. If the gating parameters lean overall toward "retention," the model's behavior becomes closer to lookup-style pattern matching; if they lean toward "updating," the model is better at following the context but also more prone to forgetting long-range dependencies. The paper's contribution lies in grounding this abstract trade-off in a concrete, tunable component, enabling architecture designers to consciously choose an operating point rather than passively accepting the inherent bias of the architecture.
Why In-Context Learning Becomes an SSM Weakness
Transformer's strong performance on in-context learning largely stems from its attention mechanism's ability to directly access information at any position in the sequence. In contrast, SSMs compress historical information through a recurrent state, inherently creating an information bottleneck. If the gating mechanism is designed to favor stable memorization, this bottleneck is further exacerbated, making it difficult for the model to flexibly adjust its behavior based on the current context.
By comparing SSM behavior under different gating configurations, the study reveals the dependence of in-context learning capability on gating dynamics. When gating can adaptively regulate information flow based on input content, SSMs perform better on tasks requiring retrieval and utilization of context; conversely, overly rigid gating causes the model to degenerate into shallow pattern matching that relies on memorization. This finding echoes recent research on the capacity and memory of recurrent models, indicating that gating is the key hub connecting model capacity with actual capability.
State space models (SSMs) are a class of models that recursively update a hidden state along a sequence, with typical representatives such as S4 and Mamba. Their core recurrence can be written as (h_t = A_t h_{t-1} + B_t x_t), with output (y_t = C_t h_t), where (A_t) determines how historical information decays or is retained. Because the entire history is compressed into a fixed-dimensional state (h_t), SSM inference memory is independent of sequence length and computation can be linearly parallelized—this is its main efficiency advantage over the Transformer attention mechanism. But the fixed-dimensional state also constitutes an information bottleneck: the longer the sequence, the harder it is to preserve early details losslessly. Gating is precisely the multiplicative adjustment term acting on (A_t), (B_t), or the state update path, allowing the model to dynamically decide "how much to write and how long to retain" based on the input, and thus directly determines how tight this bottleneck is.
In-context learning refers to the model's ability to complete new tasks using only the examples or contextual information provided in the prompt, without updating any weights. It requires the model to perform "read—locate—reuse" within a single forward pass: find relevant segments in the context and align them with the current query. Precise retrieval is an extreme case, such as copying a key-value pair or string verbatim from a long input. Transformer's attention can establish direct connections to any position, making it naturally suited to such operations; whereas recurrent SSMs must pass information through the state layer by layer, with more pronounced decay over longer paths. This is precisely why the paper treats gating dynamics as a key variable for in-context learning: if gating can adaptively open based on input content, the information pathway is shortened; if it is too stable, the model can only rely on patterns already memorized in its parameters.
Implications for SSM Architecture Design
The significance of this work lies not only in explaining phenomena but also in providing actionable principles for SSM architectural improvement. Since the gating mechanism is a key regulator of in-context learning capability, designing gating strategies for different task requirements could narrow the gap between SSMs and Transformers.
For example, in scenarios requiring strong contextual reasoning, more dynamic, input-dependent gating can be designed; while in tasks that rely more on knowledge memorization, stable state retention can be appropriately favored. This modular approach allows SSMs to avoid an either-or choice at the overall architecture level, instead balancing memorization and in-context learning through component-level adjustments.
The paper also cautions that the trade-off in gating design is not without cost. Overemphasizing dynamics may impair the model's ability to retain long-term information, thereby affecting tasks requiring persistent memory. Therefore, understanding the regulatory role of gating between memorization and in-context learning is a key prerequisite for designing efficient SSMs.
Implications for Large-Scale Language Modeling
The slower-than-expected adoption of SSMs is partly due to their shortcomings in in-context learning and precise retrieval. This study provides a clear explanatory framework for this predicament: the problem may not lie in the basic SSM paradigm, but rather in the specific implementation of the gating mechanism. If future work can design more suitable gating schemes based on these insights, SSMs may become competitive on a broader range of language modeling tasks while maintaining their computational advantages.
From a broader perspective, this study also echoes a general rule in AI: architectural innovation often lies not in overturning old paradigms, but in the refined understanding and redesign of key components. Although the gating mechanism is small, it carries the core tension between memorization and in-context learning, and deserves more attention in future SSM research.
One-line Summary
Gating mechanisms are the key that determines the trade-off between memorization and in-context learning in SSMs, thereby affecting their retrieval capabilities.
Paragraph Summary
This article interprets a study on the gating mechanisms of state space models (SSMs). SSMs are known for constant memory and linear complexity, yet lag behind Transformers in in-context learning and precise retrieval. The study points out that the key lies in the gating mechanism: it controls the flow and retention of information across time steps, thereby drawing a trade-off between "memorizing training data" and "dynamically leveraging the current context." When gating favors long-term retention, the model relies more on memorization; when it allows flexible updates, it is better at extracting information from context. This explains the source of SSM performance differences and shifts the limitation from the architectural paradigm to component design. The article accordingly proposes that designing input-dependent dynamic gating for task requirements could narrow the gap with Transformers while maintaining computational advantages, and cautions that overemphasizing dynamics can harm long-range memory.
Related articles
Multi-Agent Collaborative Development: Task Card-Driven Practices for Medium-to-Large AI Projects
A Bilibili creator shares a task card-driven, PM-orchestrated multi-Agent collaboration model with local-first repository state, so any Agent tool can take over a project anytime.
Cursor vs Copilot vs Claude Code: How Laravel Developers Should Choose
Compare Cursor, GitHub Copilot, and Claude Code for Laravel development: an AI-first editor, a plugin for existing editors, and a terminal agent for multi-file tasks and testing — plus workflow-based recommendations.
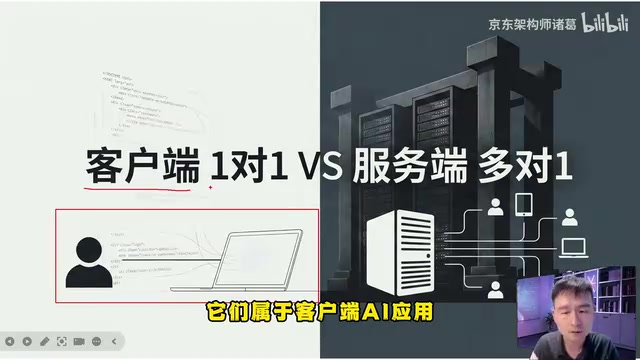
AgentScope Java Edition: A Practical Guide to Enterprise-Level Agent Frameworks
An in-depth analysis of Alibaba's AgentScope Java enterprise agent framework: contrasting client-side AI and server-side AI, explaining Java's natural advantages in high concurrency and distributed state management, and outlining a complete learning path from core principles to multi-agent collaboration.