Gemini 4 Carbon Hands-On: Worse-Than-Expected Inference Latency

Gemini 4 Carbon tested five times slower with over 11 seconds to first token, exposing systemic flaws in Google's inference hosting.
A developer who has long tracked AI models published an in-depth review of Gemini 4 Carbon, with conclusions more pessimistic than his previous video. After auditing real usage data, he found that for equivalent engineering tasks, Carbon consistently took five times as long as other models, with first-token waits exceeding 11 seconds, and that completing the same task required more steps—causing many tasks in agentic workflows to be terminated due to timeouts. He points out that the main cause of latency is not parallel tool calling or TPS, but the prefill and caching stages after requests reach the server: each file is read 8 to 16 times on average, and there is about a 30% chance of missing a just-written cache. The Vertex-hosted version performs even worse, and encoding reasoning effort into the model name creates trouble for toolchains. Combined with subscription prices about to double, he sees no reason to proactively choose Gemini for daily work.
A developer who has long tracked AI models recently published an in-depth review of Gemini 4 Carbon, and the conclusion is even more pessimistic than in his previous video: in real engineering scenarios, the model responds five times slower than comparable products, waits more than 11 seconds for the first token, and has highly unstable cache hit rates. This is not merely a question of model capability—it exposes systemic flaws in Google's inference hosting layer.
From "Barely Usable" to "Unbearable"
In the previous video, the creator had originally planned to take a negative stance on Gemini 4 Carbon, but ultimately found himself "strangely thinking it was okay"—not because the model wrote good code or excelled at 3D, but because it "seemed not to restrict me too much." However, once he actually put the model into daily engineering work, the situation deteriorated sharply.
He audited his real usage data across multiple models and found that, for equivalent tasks, Gemini 4 Carbon consistently took five times as long as other models. More seriously, he had introduced Carbon as a reviewer model in nine different scenarios, and starting from the fourth one, a large number of tasks ended up being "terminated by the parent process"—because the wait was so long that he had to update his skill configuration so that the agent would proactively give up waiting when it detected that Carbon was responding too slowly.
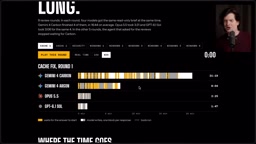
This means the real gap may be even larger than five times. "I don't know exactly how much worse it is, because I'm not willing to slow down my daily work to measure it precisely," he said. "It's like I wouldn't spend time feeding a turtle an entire head of lettuce."
The Root of the Latency Isn't Tool Calling—It's Before the Request Even Lands
Many people's first reaction is low TPS, insufficient compute, or poor parallel handling of tool calls. The creator acknowledges these problems exist, but points out that they usually cause only a 30% to 50% performance loss—not enough to explain a fivefold gap.
The real problem occurs after the request reaches the server but before the model begins responding. His measurements found that Gemini 4 Carbon consistently takes more than 11 seconds from the moment a request hits the server to the start of execution. In a live demonstration, two other models had already completed or nearly completed their work while Gemini had only just started moving—and that was just a single step, not a full round of conversation.
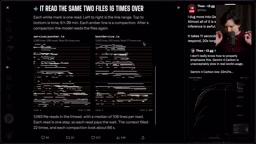
Combined with the fact that Gemini needs more steps to complete the same task, the extra 11-plus seconds of waiting per request creates a cumulative effect that makes the model "practically unusable" in agentic workflows.
Time to First Token (TTFT) is one of the core metrics for measuring the quality of LLM inference services. It refers to the time elapsed from when the client sends a request to when it receives the first output token returned by the model. In agentic workflows, models often require multiple rounds of calls, with a new request initiated each round, so the cumulative effect of TTFT is far greater than in single-turn conversation scenarios. TTFT typically consists of network round-trips, request queuing, computation during the prefill phase, and cache lookups. The prefill phase must process the entire input context, making it the main source of latency in long-context scenarios. The industry generally considers TTFT under 1 second acceptable; beyond 3 seconds, it noticeably affects the interactive experience. A TTFT of more than 11 seconds means the agent spins idle before every step, and when combined with multi-step tasks, total time is multiplied.
Caching and Hosting: Cracks in Google's Infrastructure
The creator points the finger at Google's inference hosting layer. He notes that Gemini reads each file an average of 8 to 16 times, and even when content is already cached, there is still about a 30% chance of missing the cache that was just written—possibly reading a stale cache from 30 minutes earlier, or simply failing to read it at all.
"They're the only lab where you have to write to the cache before you can read from it, and there's still a 30% chance you won't be able to read what you just wrote," he said.
Regarding hosting, the subscription version and the API version seem to diverge in speed performance. Some users report that Gemini 4 Carbon under Vertex hosting is nearly unusable, forcing them to bypass the terms of service and use other endpoints. In addition, Google writes reasoning effort directly into the model name rather than exposing it as a separate field—a design that creates extra trouble for analysis tools.
Prompt Caching is a mechanism that reduces inference cost and latency by reusing already-processed input context. The principle is to store the key-value cache (KV Cache) of long or repeated prompt prefixes (such as system instructions, file contents, and conversation history) on the server side, so that subsequent requests hitting the same prefix can reuse it directly and skip redundant prefill computation. Mainstream implementations usually adopt separate "write—read" semantics: the first request writes the cache, and subsequent requests read it by prefix matching. Hit rates are affected by factors such as cache expiration policies, exact prefix matching requirements, and the time window between writes and reads. When a hit fails, the request degrades to a full prefill, and latency rises significantly. Therefore, cache consistency and hit rate are key indicators for evaluating the engineering quality of an inference hosting platform, especially in agentic scenarios that repeatedly read the same set of files.
Public Friction with DeepMind
In the video, the creator expressed clear dissatisfaction with some members of DeepMind. He said he maintains good communication with many DeepMind engineers—people who "DM me all day asking for feedback and trying desperately to make the model better"—but the public response style of lead Varun was unacceptable to him.
When he raised the speed issue, Varun replied, "That's not what we're seeing in our workloads," and on another occasion responded to criticism with "that's a high compliment." The creator sees this attitude as a failure to confront the problem head-on, and publicly stated, "I chose to express it more personally because I want to see whether Varun can handle the pressure."
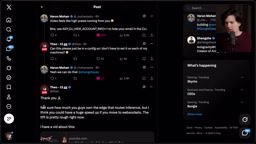
He also emphasized that he is willing to provide all run logs, prompts, and environment details—he just wants the problem fixed. "I want another player in the race. I want Gemini 4 Carbon to be usable for what it's good at."
Reasoning Effort is a parameter introduced by reasoning models in recent years to control how deeply the model performs internal Chain-of-Thought computation before producing an answer, with common values such as low, medium, and high. This parameter directly affects output quality, token consumption, and response latency, and is usually exposed to developers as a separate request field so it can be dynamically adjusted according to task difficulty. If reasoning effort is encoded into the model name (for example, distinguished by different suffixes), callers can only change behavior by switching model identifiers, which makes it difficult for monitoring, A/B testing, and cost attribution tools to analyze it as a separate variable, and also increases the complexity of multi-version model management and rollback. This design difference is a detail worth noting when evaluating the usability of a reasoning platform's API.
A Double Imbalance of Price and Value
Beyond speed, cost is another major concern for the creator. He notes that the subsidized subscription price is already "outrageously expensive," and that the price will double starting December 1. In a screenshot comparison, Gemini 4 Carbon is the most expensive, slowest, and worst-experience option, while the official response—"we're looking into how to optimize further; there's always a trade-off between latency and cost"—amounts, in his view, to admitting that it "can't keep up on any dimension."
His final recommendation is blunt: there is currently no reason to proactively choose a Gemini model for daily work, and a $20 Claude subscription provides more reasoning runs and actual output. "Friends don't let friends use Gemini," he says, quoting a viewer comment as his closing line.
Editorial View
The value of this "meltdown-style" review lies not in emotional expression but in the dimensions of model evaluation that are often overlooked: hosting quality and engineering usability. First-token latency, cache consistency, and tool-call orchestration—metrics that don't show up in benchmark scores—directly determine whether a model can enter real production workflows. If Google wants to win back developers' trust, it needs more than a stronger model; it needs an inference infrastructure worthy of the model's capabilities.
One-line Summary
Gemini 4 Carbon tested five times slower with first-token latency over 11 seconds, exposing systemic flaws in Google's inference hosting.
Paragraph Summary
A developer who has long tracked AI models published an in-depth review of Gemini 4 Carbon, with conclusions more pessimistic than his previous video. After auditing real usage data, he found that for equivalent engineering tasks, Carbon consistently took five times as long as other models, with first-token waits exceeding 11 seconds, and that completing the same task required more steps—causing many tasks in agentic workflows to be terminated due to timeouts. He points out that the main cause of latency is not parallel tool calling or TPS, but the prefill and caching stages after requests reach the server: each file is read 8 to 16 times on average, and there is about a 30% chance of missing a just-written cache. The Vertex-hosted version performs even worse, and encoding reasoning effort into the model name creates trouble for toolchains. Combined with subscription prices about to double, he sees no reason to proactively choose Gemini for daily work.
Related articles

OpenAI to Shut Down Agent Builder and Two Other Services on November 30, Developers Must Migrate Urgently
OpenAI will shut down Agent Builder, the evals dashboard, and reusable prompts on November 30; evals is already read-only. Here's the scope, OpenAI's migration paths (Agent SDK, PromptFu, your own code), and what developers should export and rebuild this week.

RankSpot: A Pay-Per-Use SEO & AI Search Execution Layer That Lets Agents Write, Publish, and Build Backlinks for You
RankSpot is an SEO & AI search execution layer for AI Agents. Connect via MCP to Claude or ChatGPT to write, publish & build backlinks. Pay-per-use, $3/article.

Appxiom: Giving AI Coding Assistants Production Context
Appxiom gives AI coding agents production context—crashes, jank, memory leaks, failed network calls—across Android, iOS, Flutter, KMP, and Web, ranking bugs by Goal Friction Impact.