Gemini 4 Hydrogen Review: A New Programming Paradigm Under the Orchestrator Model
Gemini 4 Hydrogen is faster and cheaper, promoting the Orchestrator multi-model orchestration paradigm.
The article reviews Google DeepMind's Gemini 4 Hydrogen. Positioned as faster and cheaper, it scores 51 on the Artificial Analysis Index at high setting and 54 at xhigh, slightly above Argon's 50, with clear price and speed advantages. Google also introduced Orchestrator mode, letting Argon or Carbon handle planning decisions while Hydrogen executes many subtasks, avoiding latency and quota waste from full flagship calls. The author's test of pure Hydrogen generating a cleaning service website was poor, confirming it suits repetitive work rather than design decisions; in Google Search it shows better depth of thought and result presentation. Side-by-side comparison shows its single-point cost-effectiveness is not optimal; its value lies in combined orchestration.
Gemini 4 Hydrogen Review: A New Programming Paradigm Under the Orchestrator Model
Google DeepMind recently released a new model in the Gemini 4 series, codenamed "Hydrogen." Unlike previous flagships that chased "the strongest," Hydrogen is positioned as faster, cheaper, and outperforming larger models on specific benchmarks. More importantly, Google simultaneously introduced the Orchestrator mode, attempting to redefine how we use large models: rather than letting one model do everything, let fast models handle the grunt work and strong models make the decisions.
What Exactly Is Hydrogen: A Fast Model That Overtakes
According to Google DeepMind's blog, Hydrogen scores 51 on the Artificial Analysis Intelligence Index at the "high" thinking level, slightly above Argon's 50; at the "xhigh" setting it can reach 54. Pricing is $1.50 per million input tokens and $0.75 per million output tokens, significantly lower than the flagship model.
Speed is its core selling point: compared to 3.8 Flash, Hydrogen is about 2.8 times faster while reducing token consumption by 12% to 23%. This means in long sessions and multi-turn debugging scenarios, both cost and latency will see perceptible reductions.
But the video author emphasizes one prerequisite—this model should not be used on its own. Google's official approach is to combine it with Argon or Carbon, which leads to the focus of this article.
The Artificial Analysis Intelligence Index is a widely cited third-party benchmark that doesn't just look at how many questions a model answers correctly, but integrates reasoning, knowledge, programming, math, and other task types, while also factoring in inference cost (dollars per task) and latency. Because it discloses both scores and prices, it is often used to compare "intelligence per unit cost." Note that index scores are highly sensitive to the "thinking level" (e.g., high, xhigh); the same model can differ by several points across settings, so cross-model comparisons must align settings. The article's mention of Hydrogen scoring 51 at high and 54 at xhigh reflects this mechanism; the comparison with a competitor at "$3.16 per task at max setting, index 54" should also be understood as a对照 under equal or higher thinking budgets.
Orchestrator Mode: Let the Right Model Do the Right Thing
In the Google Anti-Gravity app, a new Orchestrator option has been added. The logic is simple: when handling large projects, the main model can choose Carbon or Argon for planning and key decisions, while Gemini 4 Hydrogen is dispatched to execute large numbers of subtasks.
Google's explanation: if you invoke a frontier reasoning model at every step of every feature, every debugging session, and every routine task, it slows down the loop and consumes large amounts of frontier quota. Hydrogen exists precisely to solve this "using a sledgehammer to crack a nut" waste. The author mentions that the previously released Gemini 4 Carbon combined with /swarm is used to track large-scale multi-workflow engineering tasks, and within days tens of thousands of such tasks were launched on Anti-Gravity.
The thinking behind this is noteworthy: model capability is no longer the only variable—model orchestration itself is becoming an engineering capability.
Orchestrator mode is an architectural choice relative to "single-model end-to-end": a planning model acts as the dispatcher, breaking large tasks into subtasks, assigning them to execution models with different specialties, and then aggregating results. It is similar to the common "multi-agent" approach but emphasizes cost tiering—using frontier models for a small number of high-value decisions and cheap fast models for large amounts of repetitive execution. The key engineering challenges lie in the granularity of task decomposition, context passing between subtasks, and failure retry and result validation. The mentioned /swarm can be understood as an orchestration entry point for large-scale parallel workflows, suitable for batch tracking and dispatching hundreds or thousands of engineering tasks; Orchestrator is more oriented toward layered collaboration within a single project.
Hands-On: Pure Hydrogen Is Mediocre at Building Websites
The author did a direct test: using Anti-Gravity with Hydrogen in high mode, the prompt was "create a home cleaning service website that needs service area validation, address entry, recurring booking, and package selection."
The result was not ideal. The generated website had severe text stacking and poor visual design; the author bluntly said "it's really bad, I don't like this website." But this precisely confirms the official positioning—Hydrogen excels at quickly completing large amounts of computation and structured work, but may not make the best design decisions.
In contrast, the cases Google officially showcased are much more impressive: the "Gemini's Land" game generated with Hydrogen, an e-commerce website, and an experiment turning Google Sheets into an animated pixel canvas. The author believes these official examples better reflect the model's potential for rapid construction.
Search Scenarios: Improvements in Thinking Quality and Presentation
Hydrogen has also been integrated into Google Search. The author compared old and new results: when asked "how to create a sense of zoning in a small studio apartment for under $200," the old result was rather bland, while the new result was better in depth of thought and layout; when asked "moving to downtown Boston for work, want a neighborhood with social atmosphere but not noisy on weekends," the new version not only gave clearer reasons for recommendations but also embedded an expandable map.
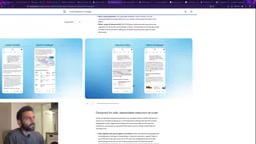
This part of the change is relatively intuitive—search is no longer just listing links but providing structured suggestions. The author judges its performance in search to be better than Gemini 3.5 Flash.
"Thinking quality" in AI search usually refers to the model's ability to perform multi-step reasoning and weigh constraints before giving an answer, different from simple retrieval summarization. Take the article's example "create a sense of zoning for under $200": a good answer needs to break down the budget, space constraints, and available products, then organize them into an executable plan; while questions like "moving to downtown Boston" involve subjective preferences (social atmosphere, noise tolerance), and the model needs to explicitly list reasons for recommendations rather than just giving conclusions. Improvements at the presentation level—structured layout, expandable maps, and other rich media components—depend on the collaboration between the search frontend and the model, turning answers from "link lists" into "directly consumable suggestion cards." This is also an important dimension for judging whether a search model upgrade is "perceptible."
Side-by-Side Comparison: Cheap Does Not Equal Optimal
The author raises a question worth discussing. In the Artificial Analysis benchmark, a competitor model costs $3.16 per task at max setting with an index of 54; another costs only $1.27 per task at max setting, with an index even higher than Hydrogen's performance at xhigh. In other words, in terms of cost-effectiveness alone, Hydrogen is not invulnerable.
The author's attitude toward this is understanding: Hydrogen's value is not in being the strongest at a single point but in combination. For developers with existing projects who need continuous bug fixing and daily coding, letting Hydrogen handle repetitive work and reserving flagship models for architectural decisions will yield better overall efficiency.
Who Should Use Hydrogen
- Developers with mature projects: Argon or Carbon builds the skeleton, Hydrogen does daily iteration and defect fixing.
- Cost-sensitive long-session users: Lower token consumption and faster responses are suitable for high-frequency interaction.
- Teams wanting to try orchestration mode: Orchestrator provides a reusable multi-model collaboration paradigm.
If you expect an answer where "a single model solves everything," Hydrogen may disappoint you; but if you accept the idea of "model division of labor," it offers a more pragmatic engineering option. Hydrogen is currently available in the Gemini app, Google Anti-Gravity, and AI Studio.
Related articles

OpenAI to Shut Down Agent Builder and Two Other Services on November 30, Developers Must Migrate Urgently
OpenAI will shut down Agent Builder, the evals dashboard, and reusable prompts on November 30; evals is already read-only. Here's the scope, OpenAI's migration paths (Agent SDK, PromptFu, your own code), and what developers should export and rebuild this week.

RankSpot: A Pay-Per-Use SEO & AI Search Execution Layer That Lets Agents Write, Publish, and Build Backlinks for You
RankSpot is an SEO & AI search execution layer for AI Agents. Connect via MCP to Claude or ChatGPT to write, publish & build backlinks. Pay-per-use, $3/article.

Appxiom: Giving AI Coding Assistants Production Context
Appxiom gives AI coding agents production context—crashes, jank, memory leaks, failed network calls—across Android, iOS, Flutter, KMP, and Web, ranking bugs by Goal Friction Impact.