Gemini 4 Neon Hands-On: Coding Ability Beats GPT 6.2 Sol?

Gemini 4 Neon tested: tops coding benchmarks, beats GPT 6.2 Sol on web dev, orchestration mode is the value killer feature.
Based on in-depth testing by a YouTube tech creator, this article reveals Gemini 4 Neon's real performance. Positioned between Carbon and Hydrogen, Neon ranks third on the Artificial Analysis Intelligence Index (score 61), supports four thinking levels, and costs $3 per input token. It shines on benchmarks like Terminal Bench and SearchHQ.ai, and in hands-on website development surpasses GPT 6.2 Sol with more complete features, richer interactions, and faster completion. Game development was mediocre, and the Frontend Skill improves design consistency but causes responsive issues. The creator's top pick is Antigravity's orchestration mode—Neon for planning, Hydrogen for execution—balancing quality, speed, and cost as a high-value choice for beginner developers.
Google DeepMind has been busy lately, releasing several models in quick succession. The latest arrival, Gemini 4 Neon, sits between Carbon and Hydrogen, with Google claiming it tops the coding agent benchmarks. But how does it actually perform in practice? This article is based on in-depth testing by a YouTube tech creator, combined with cross-model comparisons, to reveal what Gemini 4 Neon is really like.
Model Positioning: Where Neon Fits in the Gemini 4 Family
Gemini 4 Neon is built on the Carbon model, but its performance positioning lands squarely between Carbon and Hydrogen. According to the YouTube channel's test video, this is the third model Google DeepMind has released in an extremely short period, with Neon replacing the previous Argon model in the family.
Looking at official benchmark data, Neon ranks third overall on the Artificial Analysis Intelligence Index with a score of 61, behind only Fable 5.2 and GPT 6.2 Astra. On pricing, input token cost is $3, and thinking levels support low, medium, high, and ultra-high—four tiers compared to Carbon's three, giving developers finer-grained control.
The creator's assessment: Hydrogen is fastest but not smart enough, Carbon is smart but on the slower side, and Neon finds a middle ground—priced in the middle too—making it a well-balanced choice.
Benchmarks: Strong Showing Across Multiple Leaderboards
According to the data shown in the video, Gemini 4 Neon stands out across several benchmarks:
- Terminal Bench 4.1: Score of 4, an extremely high level
- Area.ai: Ranked third, behind only Claude Feuille 5.2 and Opus 5.5
- Text Agent benchmark: Very high score—the creator joked that "people who want to do their own taxes don't need to pay someone anymore"
- SearchHQ.ai: Ranked first
In the creator's actual head-to-head testing, Neon even outperformed GPT 6.2 Sol—despite using Neon's medium setting while GPT 6.2 Sol was on medium-high. The creator also expressed puzzlement at the official choice of GPT 6.2 Sol as the comparison target, arguing they should have aimed at the stronger GPT 6.2 Astra Max. He did acknowledge that Neon leads Claude Opus 5.5 on benchmark scores, but noted that in his personal testing, Opus 5.5's output quality remained excellent.
Terminal Bench is a benchmark specifically designed to evaluate AI agents' ability to execute tasks in terminal (command-line) environments, covering real-world scenarios like file operations, script writing, and system management. It requires models not only to generate correct commands but also to understand execution results and iterate on errors, making it an important indicator of coding agent practicality.
Artificial Analysis Intelligence Index is a comprehensive intelligence index maintained by independent evaluation organization Artificial Analysis. It aggregates scores from multiple mainstream benchmarks (such as MMLU, GPQA, HumanEval, etc.) to provide a unified ranking of models. The index is widely cited in the industry for cross-vendor comparisons of model capabilities, and ranking changes are often seen as a bellwether for model competitiveness.
Hands-On Test 1: Game Development and Website Building
The creator first built a "Midnight in Paris" themed racing game with a simple prompt requesting only a Paris background. The resulting game graphics were very basic, and the scene looked nothing like Paris—though French names were written on the walls, the overall result was mediocre. The creator bluntly said "nothing special."
The real highlight was website development. The creator provided a prompt for an e-commerce landing page—creating a landing page for a water bottle product with all necessary sections. Neon worked for 4 minutes and delivered an impressive result: a massive hero section, customizable bottle capacity and color, personalized engraving, flip straw, sports cap, silicone base, and other configuration options, with add-to-cart functionality all working properly.
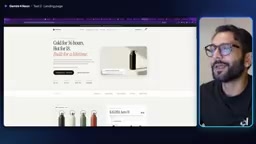
The creator specifically noted that the website's style reminded him of sites generated by Opus 5.5—the fonts and color palette were very similar. He also pointed out shortcomings: the page directly displayed an information-dense table that wasn't user-friendly for a homepage. But compared to the Hydrogen model's previous issue of omitting the reviews module, Neon this time included a filterable review system (filtering by thermal performance, daily use, and other dimensions), along with FAQ and email subscription CTAs.
This test consumed approximately 613,000 tokens across 24 model calls. The creator emphasized that this was achieved without using orchestration mode.
Hands-On Test 2: Frontend Skill and Responsive Design Trade-offs
The creator also tested the Gemini Frontend Skill mentioned in Gemini's official Hydrogen 4 release documentation. After installing the skill and asking the model to rebuild a page from scratch in a subfolder, the result showed a minimalist design following the skill's specifications—full-screen hero and all—with quite impressive visuals.
But problems emerged: the version generated with the skill had issues with responsive adaptation, while the version without the skill actually performed better responsively and looked more natural. This shows that while skills can improve design consistency, they're not always the optimal solution in every scenario.
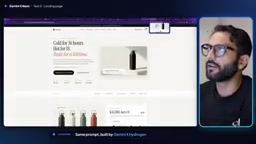
The creator also ran a comparison test with a motorcycle business landing page. Neon generated a complete website with model configuration, dealer locator, FAQ, and test ride booking in 3 minutes, while GPT 6.2 Sol's version from the same prompt had noticeably fewer sections and lacked sorting and customization options. The creator judged Neon's version superior in information density and interaction richness, and it took less time.
Gemini Frontend Skill is an installable "skill pack" provided in Google's Gemini model documentation, essentially a set of preset frontend design specifications and code templates. Once installed, the model follows the skill's defined layout principles (such as full-screen hero, minimalist color schemes, component spacing, etc.) when generating web pages, improving design consistency and standardization. However, skills are static rules that can't dynamically adjust for different screen sizes, so they may conflict with responsive adaptation—developers need to decide whether to enable them based on actual scenarios.
Orchestration Mode: Neon's Real Killer Feature
The creator's most exciting discovery was the Orchestrator Mode in Google Antigravity. In this mode, planning tasks are handled by larger models (like Neon, Argon, or Carbon), while execution is delegated to the smaller Hydrogen model. This ensures planning quality while dramatically reducing execution cost and time.
The creator strongly recommends Antigravity's orchestration mode for beginners and hobbyists—pairing Neon for planning with Hydrogen for execution delivers the combination of "best results, extremely low price, and blazing speed." He considers this the most beginner-friendly configuration currently available.
Orchestrator Mode is a multi-model collaboration architecture: a more capable, more expensive large model handles task planning and decomposition, then dispatches specific execution steps to a smaller, faster, cheaper model. This "large model plans, small model executes" division of labor significantly reduces inference cost and latency while maintaining output quality. The Google Antigravity platform productizes this mode, allowing developers to freely designate planning and execution models—the Neon + Hydrogen combination is a typical application of this approach.
Conclusion: A Middle-Weight Worth Watching
Gemini 4 Neon's top ranking on coding agent benchmarks is no empty claim—in hands-on testing, it demonstrated comprehensive capabilities surpassing GPT 6.2 Sol on website development tasks, with clear advantages in information architecture completeness and feature richness. Its pricing and thinking level settings also give developers more flexible options.
Of course, it's not perfect—game development performance was mediocre, and the Frontend Skill's responsive issues are worth noting. But as the middle tier of the Gemini 4 family, Neon combined with orchestration mode does offer developers a new high-value option. In an era where model release cadence is dizzyingly fast, Neon is worth taking the time to actually run on your own projects.
Related articles
Jingle Jam 2026 Registration Opens: Lewis Uses Old Footage to Rally Volunteers for Fundraising
Jingle Jam 2026 fundraising registration is open. Lewis uses old footage edited into a new video, calling on viewers to create fundraising pages at jingle jam.tiltify.com to support eight charities. The event takes place in the first two weeks of December.
Gemini 4 Neon Hands-On Test: Can It Replace Claude Opus 5.5?
A Bilibili creator tests Gemini 4 Neon, Claude Opus 5.5, and GPT 6.2 across three coding Agent challenges—pelican animation, 3D racing, and code-generated video—to see if Gemini can replace Opus.
FBI-Warned Artex: How an AI Attack Framework With No In-House Model Pries Open Enterprise Doors
The FBI-warned open-source AI attack framework Artex has no model of its own—it plugs into Claude, GPT, and other external LLMs to drive an agent loop, turning ordinary tools like Nmap into an automated attack pipeline. This article examines three real cases—South Korean finance, ConnectWise, and Barracuda—analyzes the three drivers of speed, cost, and noise, and outlines defenses such as exposure inventory and short-lived credentials.