Gemini Omni 1.2 Flash Debut: 30% Price Cut, 15 Seconds Without Face Swapping
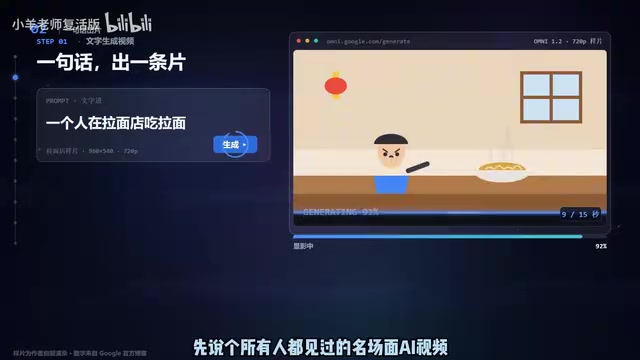
Gemini Omni 1.2 Flash extends AI video to 15 seconds, solves consistency, lip sync, and camera stability issues, and cuts prices 30%.
The article opens with the AI video "face swap at second 4" failure phenomenon and introduces the core upgrades of Gemini Omni 1.2 Flash's official GA release: duration extended from 10 to 15 seconds with per-second selection, giving videos a complete narrative structure; multi-character dialogue with syllable-level lip sync, eliminating the two post-production steps of dubbing and lip syncing; improved camera stability supporting one-take long shots. On pricing, the official 30% cut brings it to 7 cents per second, $1.05 for 15 seconds, with a tiered cost-saving path of low-res draft screening before upscaling to HD. The article also cautions that actual retry and screening costs will add up and true cost-effectiveness depends on output efficiency, but AI video is moving from novelty toy to content tool capable of batch production.
Starting with "Face Swap at Second 4": A Repeatedly Verified Pain Point
Almost everyone has scrolled past an AI video fail. The first few seconds are stunning, but once the character starts moving, eyebrows drift up to the hairline and the nose slides over next to the ear. Viewers think they've stumbled into a masterclass on disguise, laugh it off, and scroll away. Behind this meme is a very practical problem: consistency.
According to a Bilibili creator's description in the debut video for Gemini Omni 1.2 Flash, this new model was built specifically to address that complaint. It's not a concept on a launch-event slide deck — it's a GA release you can use directly in AI Studio on launch day.
Consistency in AI video generation specifically refers to the model's ability to keep the visual subject (especially faces, clothing, and scene layout) stable over the time dimension. Video is essentially a continuous sequence of frames, and the model must generate or predict each frame independently. If there aren't enough temporal constraints between frames, facial feature positions, lighting direction, and even object shapes will drift, producing what's commonly called "face swapping" or "image melting." Consistency is usually divided into identity consistency (the same character's appearance doesn't change), spatial consistency (scene structure doesn't jump), and style consistency (color tone and art style remain uniform). It's the core bottleneck in AI video's transition from "it moves" to "it's usable," and the first threshold for judging whether a model has narrative capability.
Core Upgrade 1: 15-Second Duration with Second-by-Second Control
The old 1.1 version capped out at 10 seconds. What can you tell in 10 seconds? Even a single turn feels rushed. The new version raises the limit to 15 seconds and supports any duration from 3 to 15 seconds, in one-second increments.
The extra 5 seconds aren't padding. According to the creator, those 5 seconds finally let a single clip hold a "beginning, middle, and end" without having to stitch three separate pieces together. For short dramas, product spokesperson clips, product explainers, and other scenarios that need a complete narrative structure, this is the key step from "raw clips" to "finished video."
Core Upgrade 2: Multi-Character Dialogue and Lip Sync
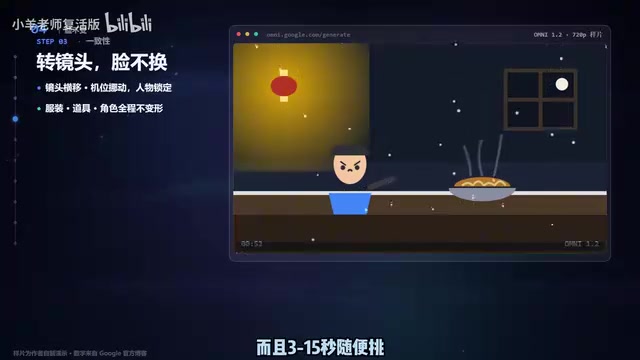
In the video, when the line "This bowl of ramen is so good" plays, the mouth movements follow the audio. The creator specifically emphasized that with multi-character dialogue, lip movements align syllable by syllable, and the tone even carries emotion.
What does this mean? When producing spokesperson clips, short dramas, or product explainers, the two post-production steps of "dubbing" and "lip syncing" can be eliminated entirely. From a production workflow perspective, this compresses two separate stages into the generation phase — a structural efficiency gain for content teams.
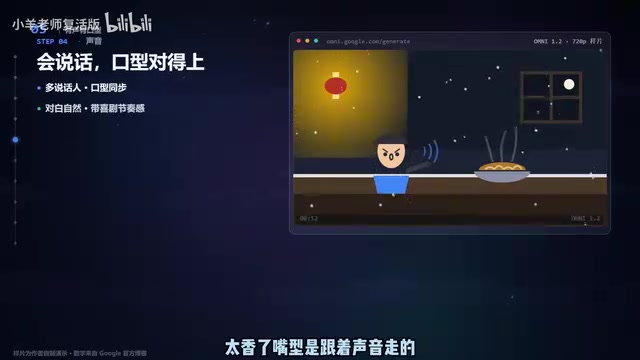
Lip Sync refers to the technology that precisely aligns a character's mouth movements with speech phonemes in time in generated video. The traditional workflow requires recording audio first, then having an animator or lip-sync software match it frame by frame — costly and difficult to scale. If an AI video model can achieve phoneme-level alignment directly during generation, it means audio and visuals are jointly modeled in the same inference process, eliminating the serial post-production steps of "dub — lip sync — fine-tune." Syllable-by-syllable sync is especially difficult for multi-character dialogue, because the model must simultaneously track multiple speakers' mouth states and switching timing, requiring stronger temporal modeling and character differentiation capabilities.
Core Upgrade 3: Camera Stability and One-Take Shots
A single continuous take — pushing in from the doorway to the bar counter, then to the steam rising from the bowl — with zero cuts in between, steady as if on a slider. The creator's assessment: "AI cameras used to make you dizzy the moment they moved; now it's its own cinematographer."
Camera stability has long been a weak point in AI video — the moment the camera moves, the visual structure tends to collapse. Being able to support a one-take long shot shows that the model's improvements in temporal consistency aren't limited to faces but extend to spatial relationships as well.
The Price Math: What Does the Official 30% Price Cut Mean?
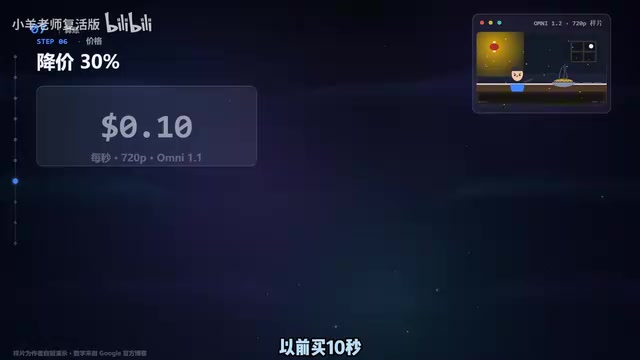
This part is the most exciting. The old 1.1 version was $1 for 10 seconds; the new 1.2 is 7 cents per second, an official 30% price cut in black and white. 15 seconds costs just $1.05 — 50% more duration for only 5 cents more total.
Do the math: for the same dollar, you used to get 10 seconds; now you get 14. The creator's stance is straightforward: anyone can calculate it — if you don't believe it, grab a calculator. Numbers don't lie.
The model also offers a tiered cost-saving approach: first generate 360P or 720P drafts for quick screening, refine details on the selected ones, and only upscale the most satisfactory take to 1080P or 4K at the end. Drafts are cheap, finished products are expensive — spend your budget where it counts.
Draft-then-Upscale is a common cost-control strategy in AI content production: first generate drafts quickly at low resolution and low sampling steps, manually screen them, then redraw or refine the selected samples at high resolution. The per-inference cost of video generation is far higher than for images, and retries and discarded takes are the main sources of expense. The tiered approach separates "exploration" from "delivery," letting cheap low-res drafts absorb trial and error while expensive high-res rendering is reserved for the final product. This approach parallels the "storyboard — rough cut — fine cut" workflow in gaming and film pre-visualization, and is a necessary cost-control measure as AI video moves toward industrialized batch production.
Where and How to Use It
Available across the board on launch day:
- AI Studio: type a sentence and start shooting
- Google VDS: billed per 15-second video generated
- Gemini APP and Flow: also integrated
Each frame also carries an invisible watermark — genuine or fake, you can tell at a glance, which has practical significance for content provenance and copyright identification.
A Few Sober Judgments
The creator's conclusion: stop using AI video fail images as memes — that was before November 5th. This claim has a promotional flavor, but the upgrade points do target real pain points — duration, consistency, lip sync, camera movement, and price, each corresponding to what creators complain about most.
One caveat: 7 cents per second is the official list price, and in practice, retry costs and draft screening costs will add up. True cost-effectiveness depends on how quickly you can pick out the take you're satisfied with. But at least in terms of pricing structure, AI video is moving from "novelty toy" to "content tool capable of batch production" — and that direction is clear.
If you've got a creative idea that's been sitting in your head for a while, open Google AI Studio now: one sentence, 15 seconds, no face swapping, it talks, one continuous take — the barrier is now low enough to be worth a try.
One-line Summary
Gemini Omni 1.2 Flash's official release extends AI video duration to 15 seconds, solves consistency, lip sync, and camera stability pain points, and cuts prices by 30%.
Related articles
 Tech Frontiers
Stylome Bot Slammed as Useless Junk: Why Do AI Detection Tools Keep Failing?
Reddit users test the Stylome AI detection bot: Gemini-rewritten text judged human-written, consistently low confidence. An analysis of AI text detection's technical dilemmas, privacy concerns, and credibility crisis in community governance.
 Tech Frontiers
When AI Becomes a Productivity Divide: Clarity or "AI Psychosis"?
A civil engineer's deep use of agentic AI boosted efficiency but bred contempt for peers who refuse to learn. Is this clarity or AI psychosis? An analysis of the cognitive and psychological challenges behind the AI productivity divide.
 Tech Frontiers
Opus 5.5 Benchmark Scores Climb, Community Says Its "Weights Are Blessed"
Reddit community discusses Opus 5.5's rising scores on the Benchmaxxing Bench, with users describing its performance as "weights are blessed." This article interprets the community reaction and cautions against conflating benchmark scores with real capability.