Google Releases Gemini 4 Hydrogen: Double the Speed, Drastically Lower Costs, the Flash Path Becomes the New Ace
Google releases Gemini 4 Hydrogen: double the speed, drastically lower costs, strategic focus shifts to the Flash path.
Google DeepMind launched Gemini 4 Hydrogen on November 12, fully replacing Gemini 3.8 Flash across Gemini API, AI Studio, Vertex AI, and Google Search. Official data shows it completes tasks 2.5x faster than its predecessor under the default High level, cuts token consumption by 12-23%, adds an X-High thinking level, and maintains a 1M-token context window. Reliability improves with 5x fewer fabrications, Terminal Bench code generation scores reach 3x the predecessor, and Artificial Analysis Intelligence Index scores 51 by default and 54 with X-High, surpassing flagship Gemini R-50. The release strategy shifts to full availability at launch, while Google abandons the 3.5 Pro candidate layer and concentrates resources on the low-cost, fast-iterating Flash path.
Google Releases Gemini 4 Hydrogen: Double the Speed, Drastically Lower Costs, the Flash Path Becomes the New Ace
Google DeepMind officially launched Gemini 4 Hydrogen on November 12, fully replacing the previous Gemini 3.8 Flash. The model has simultaneously landed on the Gemini API, AI Studio, Vertex AI, and Google Search, marking a key step for Google in the lightweight, low-cost model race. From release strategy to performance metrics, Hydrogen sends a clear signal: Google is concentrating resources on the Flash path—"fast enough, cheap enough, and smart enough."
Performance Leap: A Dual Breakthrough in Speed and Cost
According to official Google data, Hydrogen completes tasks 2.5 times faster than 3.8 Flash under the default High thinking level, with partner testing showing a speedup range of 2–2.8x. More importantly, token consumption is reduced by 12% to 23%, meaning significantly lower unit costs for the same tasks.
The dual optimization of speed and cost directly determines the economics of large-scale invocation scenarios. For developers who need to call APIs at high frequency, this improvement is not just a nice-to-have—it's a key variable that directly affects product viability.
Four Thinking Levels and Million-Token Context
Hydrogen offers four thinking intensity levels—Low, Medium, High, and the newly added X-High—allowing developers to flexibly adjust reasoning depth based on task complexity. The context window remains at 1 million tokens, continuing Google's advantage in long-context processing.
This design philosophy embodies the concept of "allocating compute on demand": simple tasks get fast responses at lower levels, while complex reasoning switches to X-High for deeper exploration. The new X-High level is particularly noteworthy, as it provides room to extend the performance ceiling for high-difficulty tasks.
Thinking Budget refers to the upper limit of tokens a model is allowed to use for internal reasoning before generating its final answer. This mechanism originates from the "inference-time compute scaling" idea introduced by the OpenAI o1 series: the model can spend more tokens on self-checking and exploration of intermediate steps, thereby improving accuracy on complex tasks at the cost of increased latency and expense. Google previously productized this as an adjustable parameter in the Gemini 2.5 series, allowing developers to specify budget levels via the API. Hydrogen's four-level design essentially provides an explicit trade-off knob among latency, cost, and quality, rather than letting the model decide implicitly. Notably, lower levels do not mean turning off reasoning but rather compressing the reasoning chain length, so the speedup is most pronounced for simple tasks.
Capability Validation: Fewer Fabrications, Major Gains in Code Generation
On reliability, Google claims Hydrogen reduces fabricated facts by more than 5x, which is crucial for enterprise applications. In code generation, the Terminal Bench score reaches more than 3x that of 3.8 Flash, demonstrating strong competitiveness in developer tool scenarios.
On the Artificial Analysis Intelligence Index, Hydrogen scores 51 with default settings, already surpassing Google's flagship model Gemini R-50; enabling X-High further raises the score to 54.
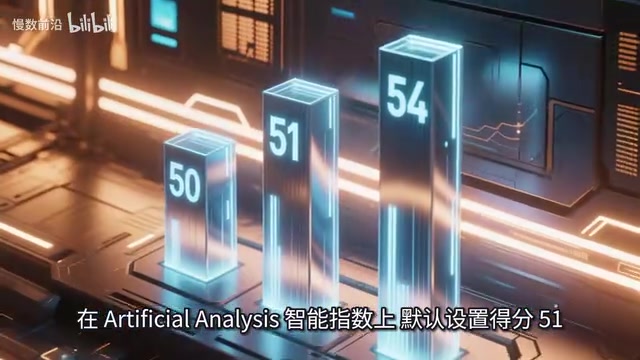
The fact that a lightweight Flash model overtakes the flagship on the intelligence index itself speaks to the magnitude of progress in model architecture and training strategy.
Terminal Bench is a benchmark oriented toward command-line and terminal operation scenarios, evaluating a model's ability to complete multi-step tasks in a real shell environment, such as file operations, package management, script debugging, and error fixing. Unlike HumanEval or SWE-bench, which lean toward function-level completion, it emphasizes parsing terminal output, tracking environment state, and multi-turn error correction, making it highly relevant to product forms such as AI coding assistants and automated operations agents. A multi-fold score improvement on this benchmark typically means significantly better stability in long-chain tool calling, not just improved single-point code generation quality.
Artificial Analysis Intelligence Index is a comprehensive model capability score maintained by the independent evaluation organization Artificial Analysis. It aggregates results from multiple benchmark categories—reasoning, knowledge, math, programming, and more—and normalizes them into a single score for cross-comparison. A distinctive feature of this index is that it does not rely on vendor-reported data but runs standardized tests itself, making it widely cited in the industry as a third-party reference for model capabilities. When reading such scores, note that a single aggregate index can mask structural differences in model performance across task types, and that evaluation sets may overlap with training data; therefore, scores are better suited for relative comparisons among models of the same generation rather than absolute capability judgments.
Release Strategy Shift: Full Availability at Launch
Hydrogen breaks with the previous practice of Argon and Carbon being prioritized for subscribers in phases—it is released to everyone immediately, with much more generous limits. Free users can use it directly in the Gemini app, while AI Pro and Ultra users get priority access in Google Sheets, with output speed improved by over 30%.
This "full availability at launch" strategy reflects Google's confidence in Hydrogen's stability and cost control, and indicates its desire to quickly build usage habits within the developer ecosystem.
Flagship Path Adjustment: Resources Shift Toward Flash
A noteworthy backdrop is that Google has hit a bottleneck in flagship model progress—the 3.5 Pro candidate layer was abandoned due to insufficient improvement, and resources are shifting toward the low-cost, fast-iterating Flash path. This is not a simple product line adjustment but a shift in strategic focus.
When marginal improvements to flagship models become increasingly difficult and the Flash path can find a balance among speed, cost, and intelligence, directing resources to the latter is a rational choice. Hydrogen makes "fast enough, cheap enough, and smart enough" hold true simultaneously for the first time, which directly determines the unit cost structure of high-traffic scenarios. For teams building products that rely on AI capabilities, this means high-frequency invocation solutions previously shelved due to cost now have a path to implementation.
Google's pivot also serves as a reminder to the industry: the second half of model competition may not be an arms race over parameter scale, but rather a contest of unit economic efficiency.
Related articles

OpenAI to Shut Down Agent Builder and Two Other Services on November 30, Developers Must Migrate Urgently
OpenAI will shut down Agent Builder, the evals dashboard, and reusable prompts on November 30; evals is already read-only. Here's the scope, OpenAI's migration paths (Agent SDK, PromptFu, your own code), and what developers should export and rebuild this week.

RankSpot: A Pay-Per-Use SEO & AI Search Execution Layer That Lets Agents Write, Publish, and Build Backlinks for You
RankSpot is an SEO & AI search execution layer for AI Agents. Connect via MCP to Claude or ChatGPT to write, publish & build backlinks. Pay-per-use, $3/article.

Appxiom: Giving AI Coding Assistants Production Context
Appxiom gives AI coding agents production context—crashes, jank, memory leaks, failed network calls—across Android, iOS, Flutter, KMP, and Web, ranking bugs by Goal Friction Impact.