Google's New AI Coding Model Beats Claude at One-Third the Cost
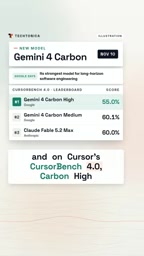
Gemini 4 Carbon narrowly beats Claude on Cursor benchmarks at one-third the cost, making price the key variable.
Per Cursor's CursorBench 4.0 data, Google's Gemini 4 Carbon high configuration leads Claude Fable 5.2 Max by a slim margin of 60.4% to 60%, a 0.4-point gap Cursor notes may not be statistically significant. The real divide is cost: carbon high costs $9.22 per task versus $32.79 for Fable Max—roughly one-third. Google also previewed Slash Swarm and Anti-Gravity, enabling a single prompt to spin up a parallel planning, building, and checking agent team, pointing to an evolution from single-model completion to multi-agent pipelines. The article stresses the data comes solely from Cursor as of November 11 without cross-platform validation, reflecting a shift in AI coding competition from capability to cost-effectiveness.
Google has dropped a bombshell in the AI coding arena. According to benchmark data published by Cursor, its latest model Gemini 4 Carbon edges past Claude on CursorBench 4.0, while costing only a third as much per task. Behind this matchup, price is becoming a more critical variable than the score itself.
Performance Upset: A Slim 0.4-Point Victory
According to the CursorBench 4.0 leaderboard released by Cursor, the high-end configuration of Gemini 4 Carbon, "carbon high," ranks first with 60.4%. Close behind is Claude Fable 5.2 Max at 60%. The gap between them is just 0.4 percentage points.
Cursor offers a cautious caveat: such a small score difference may not be statistically significant. In other words, purely from a capability standpoint, these two models perform at nearly the same level on coding tasks. The real dividing line isn't the leaderboard rank—it's the bill.
"Statistical significance" in benchmarking refers to whether a score difference exceeds the range of random fluctuation. It typically requires multiple runs averaged together with confidence intervals calculated; if the confidence intervals of two models overlap substantially, one cannot claim that one is genuinely superior to the other. On coding benchmarks, temperature sampling, minor prompt variations, and task subset selection can all introduce fluctuations of several percentage points, so a 0.4-point lead likely falls within the noise range. This is why leaderboard rankings need to be read alongside variance information—a single static score is insufficient to support a strong conclusion of "outperformance."
Cost Showdown: $9.22 vs $32.79
The per-task cost data listed by Cursor reveals the more critical difference: carbon high costs $9.22 per task, while Fable Max costs $32.79. The former is roughly one-third of the latter.
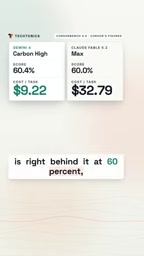
For teams using AI coding assistants heavily, this gap translates into substantial cost divergence at scale. When the capability difference between two models falls within the margin of error, the price advantage rises from a secondary factor to a core decision driver. Cursor's own phrasing confirms this: the small score gap may be meaningless—the real story is cost.
Per-task cost is typically calculated by multiplying input and output token counts by their respective unit prices and summing them, potentially including multiple sampling rounds, tool calls, and retry overhead during inference. AI coding tasks often require reading large code contexts, with input token volumes far exceeding ordinary Q&A, so per-million-token price differences get significantly amplified. Moreover, if a pricier model needs more rounds to complete a task, the actual cost gap widens further. A more reasonable metric for evaluation is "total cost to complete a task" rather than unit price alone—which is exactly why Cursor uses a per-task basis.
Beyond a Single Model: Slash Swarm and Anti-Gravity
Google also previewed two features aimed at multi-agent collaboration. According to the demo, Slash Swarm and Anti-Gravity allow users to spin up a team of coding agents with a single prompt—agents that work in parallel on planning, building, and checking.
This direction signals that AI coding is evolving from "single-model completion" toward "multi-agent pipelines." If parallelized agent orchestration can be realized, it will change the granularity of developer-AI collaboration—shifting from line-by-line interaction to task-level delegation. However, both features remain in preview, and their practical usability and stability are yet to be seen.
Multi-agent orchestration refers to a scheduling layer that decomposes tasks, distributes them to multiple model instances with different roles or tool permissions for parallel execution, then aggregates the results. Common roles include planner, coder, and reviewer—similar to division of labor in a software team. Its value lies in parallelizing long-chain tasks and splitting context into smaller windows, thereby reducing the complexity of individual inference runs. The cost is coordination overhead, merging conflicting results, and the risk of errors propagating between agents. Whether such systems can be reliably deployed depends on the maturity of scheduling strategies and verification mechanisms.
Data Boundaries: A Single Source from Cursor
It's important to note that all the figures above come from Cursor's official release, as of November 11. This means they reflect measurements from a single platform on a specific benchmark, not independent cross-platform validation.
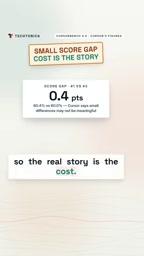
Cursor itself acknowledges that small score differences may not be meaningful, which provides a necessary qualifier to the "Google beats Claude" narrative. A more accurate interpretation: under Cursor's evaluation system, the two models have comparable coding capabilities, and Google has achieved a clear advantage in cost. For teams considering migration, price is a visible draw, but migration costs, ecosystem compatibility, and long-term stability also need to be factored in.
The independence of third-party benchmarks is an important prerequisite for evaluating model capabilities. For leaderboards published by a platform itself, the task set, scoring scripts, and cost calculation methods are all defined by the platform, which may inadvertently favor models that align with its product form. Cross-platform validation typically requires multiple unrelated evaluation sets (such as public code repair tasks, competition problems, and real repository tasks) to corroborate one another, with run details disclosed for reproducibility. In the absence of such cross-validation, single-source numbers should be treated as directional reference rather than definitive conclusion.
A New Phase in the Price War
This comparison reflects a shift in the focus of competition among AI coding tools. When the capability gap between top models narrows to a single decimal place, vendors' differentiation space is moving from "who's smarter" to "who's more cost-effective." For developers, this isn't necessarily bad—lower per-task costs mean higher experimentation frequency and broader room to explore. As for whether it's worth switching tools over this, the answer depends on each team's cost sensitivity and ecosystem dependence.
Related articles
Hands-On with Shopify AI Toolkit: Official Validation for AI-Generated Shopify Code
Hands-on with Shopify's official AI Toolkit: connect Shopify docs, API schemas, and code validation to Claude Code and other coding assistants to intercept AI-fabricated fields. Installation steps, offline validation, and telemetry-on-by-default warnings.
Claude Orchestrating an AI Coding Team: A Practical Analysis of Agent Orchestrator
The open-source Agent Orchestrator lets Claude Code dispatch Codex, Gemini, Cursor and more for parallel AI coding, with Git Worktree isolation, CI auto-correction, and mobile notifications for AI team collaboration. This article analyzes its core mechanisms, cost structure, and use cases.
GitHub Trending: 7-Step Agent Skill Pack for AI Startups
GitHub trending project ai-startup-skills offers 7 Python Agent Skills for one-person AI startups, with a router linking validation to registration. 900 stars in 20 days—design and limits analyzed.