GPT-5.6 Trio Released: A Deep Dive into Sol/Terra/Luna and the Breakthrough in Design Judgment

OpenAI launches GPT-5.6's Sol/Terra/Luna trio, spotlighting a leap in design judgment and computer-use capabilities.
OpenAI has officially released the GPT-5.6 family with three tiered models: flagship Sol, balanced Terra, and economy Luna. The standout advances are a "step change" in design judgment and enhanced computer-use capabilities, enabling the model to inspect and refine rendered results in a generate-verify-correct loop, reshaping AI-human collaboration.
The GPT-5.6 Family Officially Debuts
Following the conclusion of its limited preview, OpenAI has announced that the GPT-5.6 series of models is now available to the public (General Availability). Unlike the previous cadence of releasing a single flagship model, OpenAI this time launched three products with distinctly different positioning, forming a complete matrix that spans from high performance to high cost-efficiency.
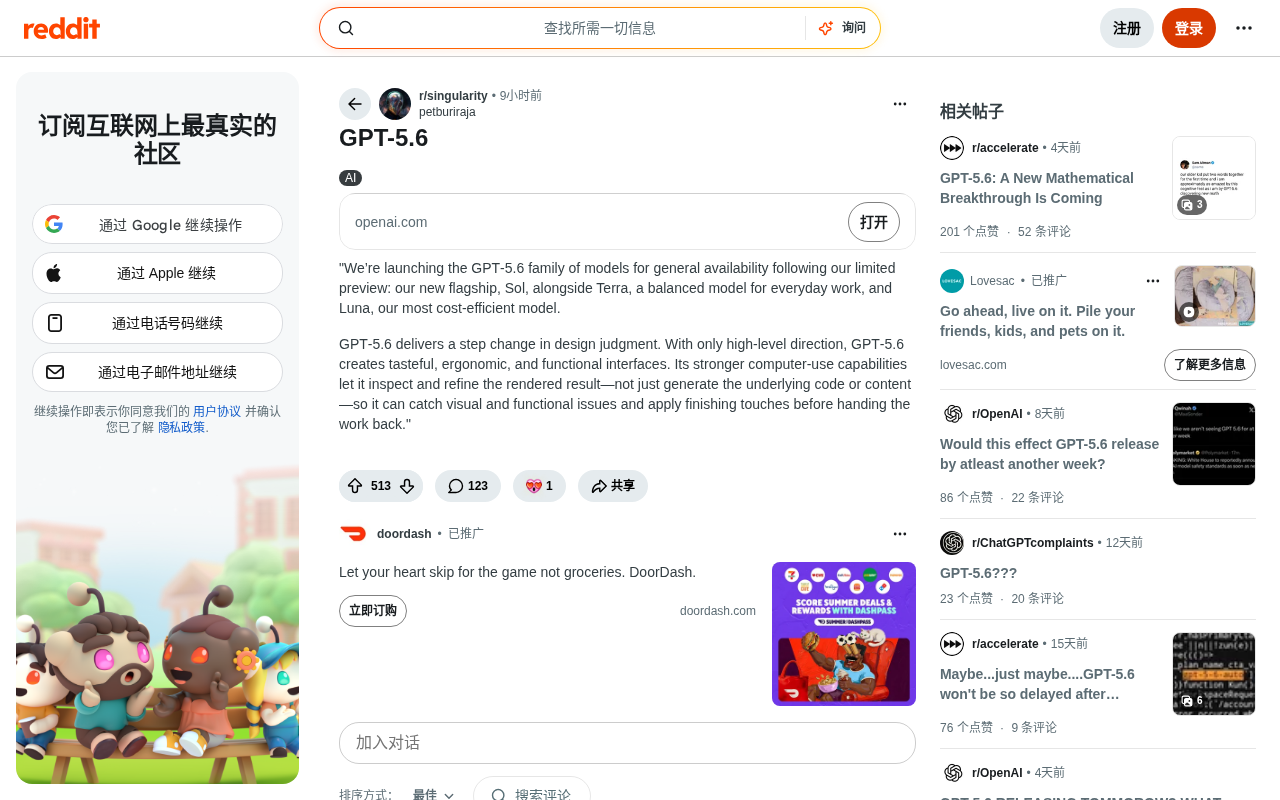
According to official statements circulating in the Reddit community, the three models are:
- Sol: The all-new flagship model, representing the performance ceiling of the GPT-5.6 family;
- Terra: A balanced choice for everyday work, striking a balance between performance and cost;
- Luna: Focused on cost efficiency, the most economical option in the family.
This "flagship + balanced + economy" three-tier division continues the product strategy adopted by mainstream large-model vendors in recent years—no longer trying to cover all needs with a single model, but instead letting developers and enterprises flexibly choose based on task complexity and budget. In fact, this strategy has become an industry consensus: Anthropic offers the three tiers of Claude Haiku/Sonnet/Opus, Google layers coverage with Gemini Ultra/Pro/Nano, and Meta's Llama series also provides multiple versions by parameter count.
The formation of this tiered strategy is rooted in the unique cost structure of AI inference. Unlike software licensing fees, every call to a large model consumes real GPU compute resources, with costs varying dynamically according to model parameter count, context length, and the number of output tokens. Taking a GPT-4-class flagship model as an example, the cost of a single API call may be 20 to 100 times that of a lightweight model.
It's worth noting that the composition of AI inference costs is far more complex than that of traditional software services. Each large-model call involves a combined overlay of GPU memory usage, computational floating-point operations (FLOPs), network bandwidth, and data center energy consumption. Taking the Transformer architecture as an example, there is an approximately linear relationship between model parameter count and inference latency. And while the introduction of the KV Cache (key-value cache) mechanism significantly reduces the repeated computation cost of long contexts, it also brings new challenges in memory management.
The working principle of KV Cache deserves further explanation: during autoregressive generation, each layer of the Transformer must compute Key and Value matrices for historical tokens. Without caching, generating each new token would require recomputing the attention over all historical tokens, with computation growing quadratically with sequence length. By storing already-computed Key/Value matrices in GPU memory for subsequent reuse, KV Cache reduces the time complexity of long-context inference from O(n²) to O(n), and is a standard optimization in all current mainstream inference engines (vLLM, TensorRT-LLM, SGLang). However, the cache itself consumes a considerable amount of memory—for a model with hundreds of billions of parameters processing a 128K context window, the KV Cache may occupy tens of GB of memory, becoming instead a bottleneck constraining the scaled deployment of long-document processing.
Quantization techniques (INT8/INT4) compress memory usage and computation by reducing numerical precision, while speculative decoding improves throughput efficiency by having a small model pre-generate drafts that a large model verifies in parallel—these are the two main engineering approaches currently used in industry to reduce inference costs. It is precisely this cost disparity that has given rise to the engineering practice of "on-demand matching": enterprises route tasks by complexity, sending tasks requiring deep reasoning (such as contract analysis or code architecture design) to flagship models, while handing high-frequency simple tasks (such as classification, summarization, and format conversion) to economy models—thereby substantially reducing overall AI operating costs without sacrificing quality in critical business scenarios.
The driving force behind this lies in the real tension between AI inference costs and the diversity of application scenarios—a tiered product strategy allows vendors to capture the price-sensitive market while maintaining brand premiums, and prompts developers to shift from "can it be used" to considering "which one is more suitable." This reflects the increasingly urgent real-world demand for cost control and call efficiency as AI applications move toward scaled deployment.
Core Breakthrough: A "Step Change" Leap in Design Judgment
Among the many updates in GPT-5.6, the dimension OpenAI emphasizes most is not the traditional reasoning ability or breadth of knowledge, but a rather novel one—Design Judgment. The official statement claims that GPT-5.6 has achieved "a step change" in this direction.
Specifically, the model can create interfaces that are "tasteful, ergonomic, and fully functional" given only high-level direction. Users no longer need to describe every layout and pixel in exhaustive detail; they simply provide directional goals, as one would to a senior designer, and the model handles the aesthetic trade-offs and detail refinement.
From a technical standpoint, "design judgment" is not a traditional machine learning metric, but rather the model's comprehensive internalized ability across multiple dimensions of aesthetic and usability principles—such as visual hierarchy, information density, color contrast, spacing patterns, and interaction feedback. The formation of such capabilities relies on the synergy of multiple training stages: during pretraining, the model learns visual patterns and engineering practices through massive amounts of design system documentation (such as Google Material Design 3 and Apple Human Interface Guidelines), open-source UI component library code (such as Tailwind CSS and Shadcn/ui), and design community cases; during alignment, the RLHF (Reinforcement Learning from Human Feedback) process specifically introduces annotators with design backgrounds to rank preferences on interfaces generated by the model, converting subjective dimensions such as color harmony, information hierarchy clarity, and responsive layout rationality into trainable reward signals.
Behind this training paradigm lies a complete data engineering logic. Annotation work in the design domain differs fundamentally from general NLP tasks: annotators need not only to understand code semantics but must also possess the ability to "render" the code in their minds and make visual judgments. To this end, leading labs like OpenAI tend to recruit composite annotators who possess both design professional backgrounds and code-reading ability, and unify aesthetic standards through multiple rounds of calibration training to reduce subjective differences between annotators.
Moreover, improvements in vision-language model (VLM) capabilities allow the model to directly "understand" visual problems in screenshots, rather than merely inferring interface states from code text—this is a key technical prerequisite for the synergy between computer-use capabilities and design judgment. The core architecture of a VLM typically consists of three parts: a visual encoder (such as CLIP's ViT), a cross-modal projection layer (which maps visual features into the language model's token space), and a language decoder. When the model "sees" a rendered web page screenshot, the visual encoder divides the image into patches and extracts features, the projection layer converts these features into visual tokens that the language model can directly process, and the language decoder then jointly generates analysis and improvement suggestions based on the visual tokens and text instructions. It is precisely this multimodal perception capability that enables the model to evolve from "reading code to guess the interface" to "directly examining the rendered result." The training objective of traditional code-generation models is code correctness and functional completeness, with the aesthetic dimension often ignored; incorporating visual quality into the reward signal is precisely the key technical path to achieving "design judgment."
This is a signal worth continued attention. For a long time, when large models generated UI code or visual content, they could often "make it work" but not "make it look good," lacking an overall grasp of aesthetics, usability, and consistency. The improvement in design judgment means that AI is evolving from a mere "executor" toward a "collaborator with aesthetic sense."
From "Generating Code" to "Reviewing the Finished Product"
Another key upgrade in GPT-5.6 is enhanced Computer-Use Capabilities. According to the official description, the model is no longer solely responsible for generating underlying code, but can inspect and optimize the final rendered result.
The realization of computer-use capabilities relies on an Agent loop architecture known as "perceive-plan-execute." At the perception layer, the model obtains the visual state of the screen through screenshots and uses OCR and visual grounding techniques to identify the position and semantics of UI elements; at the planning layer, the model generates action sequences based on the current state and target task; at the execution layer, the model issues instructions such as mouse clicks and keyboard input through system APIs, and takes a new screenshot to observe the result after each operation, forming an iterative closed loop. The core challenge of this architecture lies in "visual grounding"—that is, accurately mapping UI elements described in text to specific pixel coordinates on the screen. Anthropic first publicly demonstrated this capability in Claude 3.5 Sonnet in October 2024, achieving a milestone breakthrough through dedicated coordinate prediction training, which subsequently became a direction the industry raced to follow.
Beyond visual grounding, computer-use capabilities also face another systemic challenge: cross-application state management. When an Agent needs to switch between multiple applications such as a browser, code editor, and terminal, how to maintain task context across steps, handle unexpected pop-ups or permission requests, and gracefully recover from erroneous operations all constitute major challenges in engineering implementation. This is also why current computer-use capabilities perform significantly better in controlled single-application scenarios (such as filling out web forms) than in complex multi-application workflows—the latter's state space and exception-handling paths grow exponentially.
This is quite meaningful in technical logic. Traditional code-generation models are only responsible for the "input text description" and the "output code," and don't truly "see" what the code actually looks like after running. GPT-5.6, however, can run code, observe the rendered result, catch problems at both the visual and functional levels, and complete the final polish before delivery—just like a human engineer. For code and interface generation scenarios, this means the model can form a complete closed loop of "run code → capture rendered result → identify visual defects → modify code," fundamentally changing the traditional linear workflow of code generation as a "one-shot output, manual acceptance" process.
This effectively constructs a complete closed loop of "generate—verify—correct." The model is no longer "writing blindly," but possesses the ability to reflect on and iterate on its own output. For scenarios such as frontend development and interface prototype design, this capability is expected to significantly reduce the time and cost of manual rework.
Far-Reaching Impact on Developers and the Industry
If GPT-5.6's actual performance can live up to the official description, its impact will primarily manifest at the following levels.
Lowering the design barrier. For small and medium-sized teams and independent developers who lack professional design resources, a model with design judgment is equivalent to an "AI design assistant" available on demand, capable of quickly producing interface prototypes that are both usable and aesthetically pleasing, greatly compressing the delivery cycle of early-stage prototypes.
Reshaping the human-machine collaboration model. When the model can autonomously review finished products and correct errors, the human role will focus more on "setting direction, gatekeeping decisions, and verifying quality," rather than getting bogged down in tedious implementation details. This aligns closely with the industry's widely discussed trend of "AI Agents autonomously completing complex tasks."
AI Agentification refers to the systematic evolution of large language models from "single-turn Q&A" to "multi-step autonomous task execution." The theoretical foundation of this concept can be traced back to the 2023 ReAct framework (Reasoning + Acting), which demonstrated that LLMs can complete complex tasks by alternating between reasoning and tool calls. The core insight of ReAct is that pure chain-of-thought reasoning is introspective and lacks the ability to interact with the external world; while pure action sequences lack reasoning support and struggle to handle situations requiring on-the-fly judgment. ReAct interweaves the two, forming an iterative loop of "reasoning → acting → observing → reasoning," laying the basic paradigm of modern Agent architectures. From 2024 onward, agentification rapidly moved from an academic concept to product deployment: OpenAI's Operator can autonomously browse the web to complete tasks such as booking and form-filling; Anthropic's Computer Use opened up the model's ability to control desktop applications; and Microsoft deeply integrated Copilot into Microsoft 365, enabling cross-application task automation.
From a more macro business perspective, the strategic significance of agentification lies not only in expanding the boundaries of model capabilities, but more importantly in reshaping how AI products capture value. The value ceiling of a single conversation is limited, and against the backdrop of rapidly homogenizing large-model capabilities, pure conversational products face severe homogeneous competitive pressure. Agents that can autonomously execute complete workflows, on the other hand, can take on higher-value enterprise tasks—such as end-to-end software development iteration and cross-system data processing pipelines—thereby supporting higher subscription fees and API call volumes, and forming a far stickier barrier at the workflow level that is much harder to replace than model parameters. GPT-5.6's computer-use capability is precisely the concrete implementation of this evolution in the vertical scenario of frontend development—with the human role accordingly shifting from "operator" to "goal setter and quality gatekeeper."
Fine-grained cost control. The tiered design of Sol, Terra, and Luna allows enterprises to call flagship models in high-value scenarios and use economy models for bulk and daily tasks, thereby achieving a more precise dynamic balance between performance and budget.
A Rational View: Official Statements Still Await Verification
One point to add: the information this article is based on comes primarily from official statements circulating in the Reddit community, and currently lacks cross-validation from large-scale independent third-party evaluations. Phrasing such as "step change" and "tasteful interfaces" carries obvious marketing connotations, and the real-world effect still needs to be tested by developers in actual scenarios.
Especially for subjective capabilities such as "design judgment," it is difficult to quantify through unified benchmark tests—different users' evaluations of "taste" and "aesthetics" inherently differ. From the perspective of evaluation methodology, existing benchmarks such as WebSRC (web page understanding) and Design2Code (design-to-code) primarily focus on measuring "pixel fidelity," that is, the visual similarity between AI-generated frontend code and the reference design, typically using SSIM (Structural Similarity Index) of rendered screenshots or CLIP similarity as quantitative metrics.
However, this measurement framework has a fundamental epistemological dilemma: high fidelity and high design quality are not only not equivalent, but are sometimes even in opposition. "Good taste" in design often means an opinionated reinterpretation of the original requirements—for example, proactively simplifying overly complex information hierarchies, reallocating visual weight to highlight core action points, or deviating from literal color requirements to achieve better emotional communication—rather than mechanically reproducing every pixel of the reference image. This means that a model that truly possesses design judgment might actually score lower on traditional pixel-fidelity tests.
This dilemma is not an isolated case in the field of AI evaluation, but a typical manifestation of "Goodhart's Law": when a measure becomes a target, it ceases to be a good measure. In the field of design capability evaluation, SSIM and CLIP similarity were initially effective proxy metrics for measuring generation quality, but once models are specifically optimized against these metrics, high-scoring models may not necessarily produce interfaces that truly conform to human aesthetics and actual usage needs. This is also why labs like OpenAI and Anthropic are increasingly turning to human preference data (such as Chatbot Arena's Elo ranking mechanism) to evaluate subjective-dimension capabilities—although such evaluations likewise face challenges of sample bias and reproducibility. Although the user preference tests (Elo scoring mechanisms) and expert blind reviews that academia has attempted to introduce are closer to real evaluation, their small sample sizes, the influence of evaluator composition on results, and their difficulty in being reproduced across time and scenarios cast doubt on their applicability as general benchmarks. This measurement challenge means that the true level of "design judgment" will, for a considerable time to come, still primarily depend on the accumulation of practical cases in the developer community, rather than being presented through standardized leaderboard data. Therefore, whether GPT-5.6 has truly achieved a qualitative leap still requires rational observation, awaiting the accumulation of more real-world cases and cross-comparison data.
Conclusion
The release of the GPT-5.6 family, especially its emphasis on design judgment and computer-use capabilities, reflects that large-model competition is shifting from a pure "arms race of parameters and knowledge" to a new stage of "practicality and autonomy." When AI can not only write code but also "see" and "correct" its own work, AI collaboration in the true sense has taken another step forward. The product layout of the three-tier Sol, Terra, and Luna models demonstrates OpenAI's increasingly mature strategic considerations in commercialization and scaled deployment.
The final answer still remains to be written by the market and users.
Related articles

FlipPrice: An Open-Source Pricing Copilot for Vintage Resellers
FlipPrice is an open-source pricing copilot for vintage resellers: snap a photo, fill a few fields, and get a listing draft, fair price range, and net take-home after fees — with local open-source inference and zero per-item cost.

Alguard: Building a Dual-Layer Trust Defense for AI Agent Shopping
Alguard, an Amazon Developer Hackathon project, designs a dual-layer trust architecture for Alexa+ agent shopping. Through physical isolation between an MCP server and a human approval channel, it replaces prompt defenses with structural constraints to block unauthorized purchases caused by prompt injection.

Food Poisoning: Causes, Symptoms, Treatment, and Prevention Explained
Food poisoning is caused by bacteria, viruses, parasites, or toxins contaminating food, with common symptoms including vomiting, diarrhea, and dehydration. This article explains the causes, symptoms, treatment, and prevention of food poisoning to help you safeguard food safety.