GPT-6 Astra Real-World Testing: 20+ Use Cases & Paid Subscription Decision Guide

GPT-6 Astra handles 20+ real tasks, but problem definition and acceptance criteria determine actual results.
Based on 20+ public demos, this article systematically reviews GPT-6 Astra's real-world performance across 3D cities, architecture, design, game prototypes, software operation, and engineering workflows. It highlights three commonly overlooked pitfalls: game cases require distinguishing building, prototyping, and player-agent tasks; a 2.5× API price difference doesn't translate to the same project cost multiple; and fluent model output doesn't equal task completion — acceptance must rely on actual run evidence. The recommended workflow uses Astra for high-stakes judgment and evidence-based review, economy models for execution, and work orders with interface contracts to coordinate collaboration.
After GPT-6 Astra launched, the community has produced a flood of real-world use cases — from bringing Manhattan into Unreal Engine, to building a Minecraft-like game prototype, to designing circuit boards and handling Excel spreadsheets. This article, based on 20+ public cases and demo footage compiled by a Bilibili creator, examines Astra's actual capabilities through three core questions: what it delivers, how it accomplishes tasks, and how far the results go. By the end, you should be able to judge whether your next project is worth handing to Astra.
One important caveat upfront: many demo videos are sped up through editing, and playback speed doesn't reflect actual execution time. Claims of "done in a few minutes" are largely self-reported; real iteration often takes much longer.
3D Space & Architecture: Turning Ideas Into Something You Can Point At
The most eye-catching category is 3D spatial construction. One creator brought Manhattan into Unreal Engine — switchable between aerial and street-level views — over a week of iterative work. Another rendered Hangzhou as a web map, with West Lake, Leifeng Pagoda, and city buildings joined together in a rotatable, zoomable interface, with a reported production time of 24 minutes.
The most valuable lesson from the city examples is turning abstract ideas into something you can "point at and discuss." For a scenic area guide, start with three landmarks and a route. For an exhibition hall layout, start by confirming the entrance, zones, and visitor flow. Spatial proportions and geographic accuracy still need verification, but discussions don't have to stay stuck at the text level.
Architecture and interiors are also popular — floors, glass, greenery, restaurants, courtyard homes, and office facilities have all been attempted. But be clear-eyed: a room that looks right doesn't mean doors open properly, furniture dimensions are reasonable, or the space can actually be built to spec. For general users, the best approach is to use it for layout discussions, compare circulation paths between two schemes, and state the purpose clearly so the model output is actually correct.
Drawing, Design & Websites: How You Edit Matters More Than the First Image
The second category covers drawing and design. Some users had the model "draw" objects and figures in SVG code — lines, colors, and shapes described in code that can be adjusted afterward — while others recreated the process from line art to full color.
Two distinct technical approaches need to be understood here: writing SVG means encoding lines, shapes, and colors as code rendered by a browser; operating drawing software means selecting tools and layers in a GUI. Both can produce images, but the editing workflow, required tools, and failure points are completely different. For real projects, ease of revision often matters more than the first image.
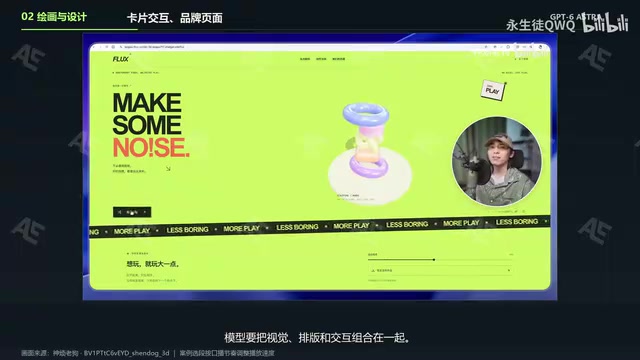
Design extends beyond a single image — there are flip-card interfaces, brand pages with 3D objects, and websites generated in multiple styles from the same brief: restrained, vivid, or with 3D objects as the hero, letting you pick a direction before refining. Abstract 3D and particle effects work well for visual experiments, but putting them in a real website requires checking mobile performance, text readability, and whether animations steal focus from the content. A practical tip: have it build a 10-second looping background first, then test loading and scrolling before piling on more effects.
SVG (Scalable Vector Graphics) is an XML-based vector image format that describes points, lines, curves, and fill colors in code — the file itself is readable text. Because it's vector-based rather than pixel-based, it scales without quality loss and renders directly in the browser without plugins. The advantage of AI-generated SVG is that the output is plain text: the model can modify a specific shape's color or coordinates line by line, without regenerating the whole image; designers can also open the file directly and make manual edits. By contrast, having a model operate Photoshop or Figma relies on screenshot recognition to read the current state, requires confirming that each interface action registered, makes errors harder to locate, and makes rollbacks more complex.
Games & Minecraft: Three Task Types That Can't Be Judged by the Same Standard
Game-related cases are the easiest to conflate — it's essential to distinguish three distinct task types:
- Building structures in an existing game — such as Jiangnan gardens, pavilions, wells, and corridors — focused on spatial layout;
- Writing a similar game prototype — with movement, mining, and a crafting interface — focused on connecting terrain and interaction;
- Having the model act as the player — reading screenshots and controlling the keyboard and mouse.
The same blocky visuals cannot be evaluated by the same standard. The material also covers a League of Legends-style demo, a Taipei GTA (with characters walking the streets and switching to driving), kart racing, a horror game, and lightweight titles like Cut the Rope.
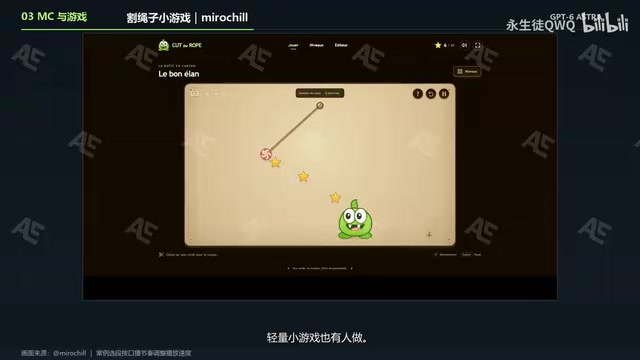
The most exciting thing about shooters and city games is how quickly prototypes emerge — but one successful movement doesn't mean collision and save systems work, and running in single-player doesn't mean multiplayer sync is done. If you genuinely want to make a game, start by defining a small, completable level with movement, one interaction, and restart all wired up, then expand outward. For independent creators, the most valuable thing often isn't replicating an existing title, but validating your own mechanic — like a room that changes over time. Keep it small enough that you can actually see what players find interesting.
Operating Software & Engineering Workflows: Acceptance Criteria Come From Your Business
The fourth category is directly operating software. Tasks like "I'm not a robot" captchas — where the rules change each round — require the model to read the current screen before deciding the next action. The key to computer operation is closing the loop between observation and action: after clicking a button, check whether the page actually changed; after saving a file, confirm it can be reopened. Evaluating this capability should focus on whether the complete task is finished, not how fast the mouse moves.
Engineering applications have also appeared: circuit board design, 3D-model-to-3D-print workflows, and more everyday tasks like Excel spreadsheets and document processing. All of these connect model output to professional tools. But a spreadsheet can't be judged by how tidy it looks — formulas and sources need checking. A circuit board can't be judged by whether the layout looks reasonable — someone with domain knowledge still needs to verify the rules. Tools let the model take action, but acceptance criteria still come from your own business. The best candidates for automation first are the parts of a workflow where you can clearly judge right from wrong.
Pricing & Intelligence Index: Don't Treat Per-Unit Price Multiples as Total Project Cost
On intelligence performance, the author specifically cautions against the outdated claim that "both score 61." According to Artificial Analysis benchmarks published September 9th, Astra at its highest reasoning tier scores 53 — 6 points above the reference model Soul. Scores must always be read alongside the date and test configuration.
On pricing, as of the time of verification, for standard-length API requests, Astra's text pricing is $10 per million input tokens and $50 per million output tokens; Soul is $4 input and $20 output — a 2.5× difference per unit. Using 100K input and 10K billed output as an example, Astra costs roughly $1.50 versus Soul's $0.60. But this is text-only billing, excluding tool fees and caching. Don't treat the 2.5× unit price difference as the cost multiplier for total project spend — the model may complete work with fewer outputs, or it may run continuously on complex tasks.
A real billing story is worth heeding: Gary Chen reported spending around $2,300 on a Taipei GTA prototype and ended up with a half-finished product. His warning is clear — the model's willingness to keep running doesn't mean it's worth letting it. Budget caps, maximum retry counts, and when to scale back your goals should all be stated upfront.
A token is the basic unit of billing and processing for large language models — roughly corresponding to one English word or half a Chinese character, though the actual conversion varies by language and tokenizer. In API calls, input (everything sent to the model: system prompts, conversation history, and the current question) and output (the model's generated response) are billed separately, with output typically priced higher than input. "Per million tokens" is the standard pricing unit: for example, Astra's $10/million input tokens means sending roughly 750,000 English words costs $10. But in multi-turn conversations or automated workflows with long contexts, every request re-transmits the full conversation history, causing token consumption to accumulate rapidly with each turn — which is the primary reason actual bills on complex projects far exceed single-request estimates.
Recommended Workflow: Astra for Judgment, Economy Models for Execution
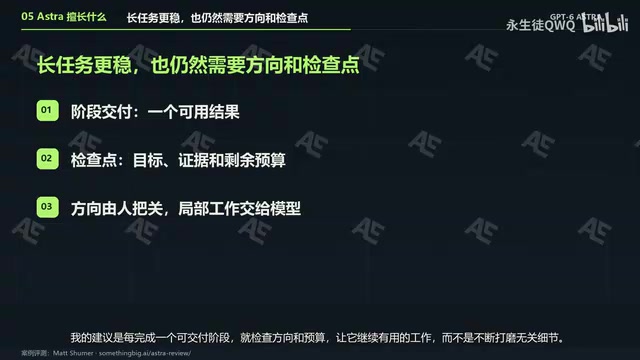
The author's core recommendation is to position Astra at the high-stakes judgment points that affect everything downstream — first locking in product specs, system architecture, interface contracts, and execution playbooks, then having economy models like Soul, Terra, or Luna do the execution, with Astra performing "evidence-based acceptance review" at the end.
This approach breaks down into several key stages:
- Product Specs: Start by answering what you're building, what you're not building, and what success looks like. The more precisely scoped the requirements, the easier it becomes to judge whether a new feature is necessary work or scope creep.
- System Architecture: Separate display, data, styles, and assets so replacing one part doesn't destabilize the whole project.
- Interface Contracts: Define handoff formats — for example, every piece of work must include a title, cover image, description, and link, with consistent field names.
- Execution Playbooks: Each work order should clearly state the owner, dependencies, inputs and outputs, what's allowed and prohibited, what counts as done, and what screenshots or run results are required. When stuck, report what's missing — don't fabricate a result just to check the box.
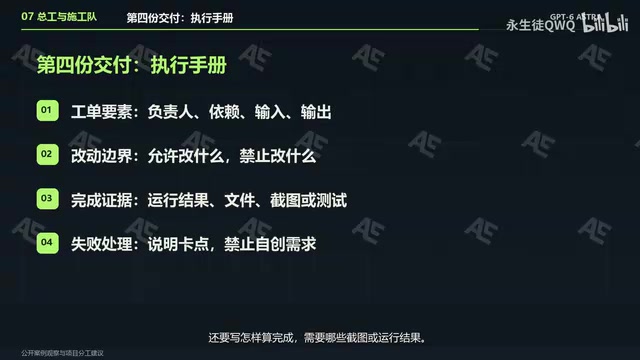
The acceptance stage is especially critical: when having Astra review completed work, provide it with the changes made, screenshots of run results, and the original acceptance criteria simultaneously. It should respond item by item — pass or return, with reasoning. When real run evidence is unavailable, outstanding items must be listed explicitly. A fluent explanation does not constitute completion.
Soul, Terra, and Luna mentioned in the article are tiered models within the same product family, differentiated by capability and price. "Economy models" refers to the lower-cost versions suited for high-frequency execution tasks — analogous to GPT-4o mini versus GPT-4o in OpenAI's lineup. The core logic of this tiered-usage strategy is: reasoning and judgment tasks (confirming architecture, checking whether output meets standards) demand more model capability but are called infrequently; code generation, format conversion, and bulk copy tasks are called frequently, so using economy models dramatically cuts overall cost while reserving top-tier compute for the nodes that genuinely require global judgment.
Conclusion: What Really Sets Work Apart Is How You Define the Problem
This workflow is best tested on a small project first — a portfolio site, a small exhibition mockup, or one complete run-through of a repetitive data-organization task. Track usage, bottlenecks, and the time you actually spend on rework, then decide which judgment calls to hand to Astra and which steps to keep with more precise models.
When generating a prototype becomes easy, what truly differentiates outcomes is problem definition, tradeoff decisions, and acceptance capability. You know why you're building it, you know what has to be accurate, and you can judge when it's good enough — at that point, the model's capabilities can actually become your results.
Related articles

Receipt Forgery Detection Near Random? Real-World Struggles and Solutions in Document Image Forensics
A receipt forgery detection project with ROC-AUC near random reveals the pitfalls of small-sample document forensics. Explores anomaly detection, self-supervised pre-training, and numerical consistency as viable alternatives.

From Workflows to Eval-Driven Development: A Paradigm Shift in How We Solve Problems with AI
AI problem-solving is shifting from deterministic workflows to "define evals + hillclimb." This piece explores how eval-driven development reshapes tasks, data vendors, human roles, and Agent UX.

Tesla Powerwall + Electric Vehicle: A Dual Backup Power Solution for Outages
Tesla Powerwall combined with EV bidirectional charging can provide multi-layer home backup power during outages. We break down runtime, V2H realities, and Supercharger loop feasibility.