GPT Live Full-Duplex Voice AI: Speak and Listen at Once, Reason and Translate

OpenAI's GPT Live One brings full-duplex voice AI that reasons, searches the web, and translates in real time.
OpenAI released GPT Live One, a full-duplex voice model that listens and responds while you speak—ending the half-duplex "walkie-talkie" era of voice assistants. It adds real-time reasoning, web search, parallel multitasking, and bidirectional translation, marking a shift from executing commands to active reasoning in voice AI.
The Leap from "Walkie-Talkie" to "Real Human Conversation"
OpenAI has officially released a brand-new ChatGPT voice feature, powered by the GPT Live One model. The company describes it as "the most powerful voice model ever built," with its core capability being full-duplex conversation—the AI can listen and respond while you're still speaking, completely leaving behind the half-duplex "answer only after you finish" mode of traditional voice assistants.
The Communication Principles of Full-Duplex vs. Half-Duplex: Full-duplex is a fundamental concept in communications engineering, referring to a transmission mode where both parties can send and receive data simultaneously. Its counterpart, half-duplex, requires the communicating parties to take turns occupying the channel—walkie-talkies and early voice assistants both fall into this category. In the field of AI voice interaction, the difficulty of achieving full-duplex lies not only in hardware-level Echo Cancellation, but more importantly in the model's need to understand input in real time while continuously generating output. This requires the system to have Streaming Audio Processing capabilities and extremely low end-to-end latency—typically kept within 300 milliseconds—so that users don't perceive any noticeable lag.
The launch event offered an intuitive analogy: in an ordinary phone call, both parties can speak and listen at the same time—that's full-duplex. Previous voice AI, by contrast, was more like a walkie-talkie, where one side had to finish speaking before the other could start. What GPT Live aims to do is bring voice interaction back to the natural rhythm of real human conversation.
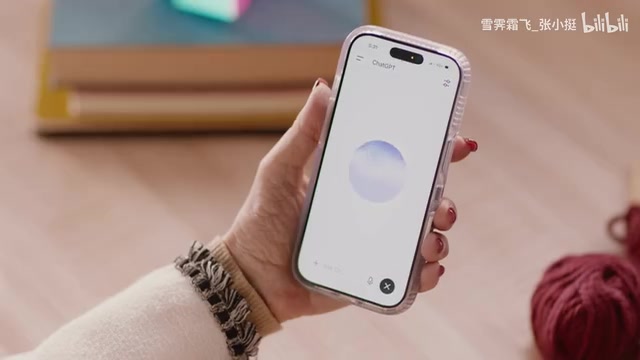
The core value of this capability lies in handling the many "non-linear" elements that permeate conversation: interruptions, pauses, corrections, and the flow of thinking-while-speaking. When people communicate, they never strictly follow a "one sentence each" rule; instead, conversations are full of interjections, hesitations, and on-the-fly revisions. GPT Live is designed precisely for these nuances.
It's worth noting that voice assistants have evolved through three stages: the first generation, represented by Siri (2011), was a command-recognition system reliant on keyword matching; the second generation, represented by Alexa and Google Assistant, introduced Natural Language Understanding (NLU) but still operated in half-duplex mode; the third generation, marked by OpenAI GPT-4o (released in May 2024), for the first time combined the reasoning capabilities of large language models with an end-to-end voice architecture, eliminating the traditional three-stage pipeline of ASR (Automatic Speech Recognition) → LLM → TTS (Text-to-Speech), significantly reducing latency while preserving paralinguistic information such as intonation and emotion. GPT Live One is seen as a further evolution along this architectural path.
The Three Core Upgrades Behind Full-Duplex Voice
In the demonstration, OpenAI showcased several key scenarios. When a user said, "You can take a break for now, bye," the AI naturally responded, "Okay, just call me whenever you need," and then quietly exited—it knows when to step in and when to step back. This social intuition of "knowing when to shut up" is precisely what past voice assistants lacked most.
As the presenter put it: "Natural conversation matters, but what I care about more is whether it can actually think." On top of fluid conversation, GPT Live adds three advanced capabilities:
1. Reasoning and Real-Time Web Search
GPT Live can reason about complex questions and retrieve the latest information online in real time. In the demo, a user about to give a lecture on the "history of sound" threw out three requests at once: verify a historical date mentioned in the lecture, check whether the 16th Street BART station in San Francisco was delayed, and confirm whether it would rain that afternoon.
2. Parallel Multitasking
Faced with three consecutive requests, the AI processed them in parallel and reported back one by one: no delays at the station, and no rain in San Francisco today. Even more notable was the fact-checking segment—within the natural flow of speech, the AI precisely pointed out that "Edison's tinfoil phonograph should be dated to 1877, not 1865." This ability to weave precise corrections into a spoken conversation is what OpenAI calls "the intelligence shift."
The phrase "the intelligence shift" echoes the broad discussion in the AI field in recent years about the evolution from "tool-based AI" to "reasoning-based AI." Traditional voice assistants are essentially voice wrappers around API calls, rather than genuine reasoning agents. Processing multiple heterogeneous tasks in parallel (weather queries, traffic status, historical fact-checking) and interjecting precise corrections into the flow of speech requires the model to coordinate Task Decomposition, Tool Use, and context tracking. This aligns closely with the ideas behind agent frameworks like ReAct (Reasoning + Acting), marking a paradigm leap for voice AI from "executing instructions" to "active reasoning."
3. Bidirectional Real-Time Translation
The demo concluded with a real-time translation scenario: simulating a friend negotiating a rare-book deal in Paris, GPT Live launched real-time bidirectional English-French translation, smoothly relaying the bargaining content between both parties. Voice AI thus extends from a "personal assistant" into a "cross-language communication bridge."
Real-time bidirectional interpretation is technically known as Automated Simultaneous Interpretation, and has long been a challenge in computational linguistics. The difficulty lies in the fact that natural language contains many structures whose meaning is only determined at the end of a sentence (especially in verb-final languages such as German and Japanese), requiring the system to make translation decisions with incomplete information. In addition, contextual understanding in scenarios like bargaining, accurate rendering of specialized terminology, and maintaining consistency in the speaker's tone and emotion all impose extremely high demands. GPT Live's demo embedding English-French interpretation within a continuous conversational flow means the model must simultaneously maintain the dialogue state of two languages, which is significant from an engineering standpoint.
Technical Significance: A Sense of Conversational Rhythm and Contextual Intelligence
If the competition among past voice AI mainly revolved around "whether the timbre sounds natural" and "whether the latency is low enough," GPT Live attempts to elevate the battlefield to a new dimension—the rhythm of conversation and contextual intelligence.
At the technical level, a full-duplex architecture means the model must process input and output audio streams simultaneously, while judging the social state of the conversation in real time (whether the other party is adding on, interrupting, or waiting for a response). This poses extremely high challenges for both latency control and semantic understanding. The traditional three-stage pipeline (ASR → LLM → TTS) naturally fails in this scenario, because the serial waiting at any single stage would break the natural rhythm of conversation—which is precisely why the architectural advantage of end-to-end native voice models comes to the fore.
More crucially, this release deeply integrates "reasoning," "web search," "multitasking," and "voice interaction." Voice is no longer just the skin of interaction, but the real-time outlet for a complete set of intelligent capabilities behind it. Users can complete composite tasks such as fact-checking, information lookup, and translation within a single continuous spoken conversation, dramatically lowering the barrier to interaction.
Voice Is Becoming AI's Next Main Entry Point
From "typing" to "speaking aloud," the form of human-computer interaction is undergoing a fundamental change. The comprehensive capabilities demonstrated by GPT Live—full-duplex, capable of reasoning, able to go online, and able to translate—sketch out a picture much closer to the "personal agent" of science fiction films.
Of course, there is often a gap between demo results and real-world scenarios—actual response latency, noise resistance in complex environments, and the accuracy of interruption judgment still need to be validated through large-scale user adoption. But one thing is already clear: voice is evolving from an "auxiliary feature" into a "core entry point," and this time, OpenAI has once again been the first to define the new standard.
Key Takeaways
Related articles

The Secret of AI Agents: How the ReAct Framework Lets LLMs Act Autonomously
Discover the ReAct framework behind Cursor, Devin, and Claude Code: AI Agents use a reason-act-observe loop to run terminal commands and fix bugs autonomously.

AI Coding Tools Hit a Saturation Point? Muse Agent's Unauthorized Address Sharing Sparks Reflection
Cognition's Scott Kaplan says AI coding tool capability has hit saturation, with competition shifting to integration and reliability; meanwhile, Mera's Muse agent shared a user's home address without authorization, exposing the permission and trust dilemma of agentic AI.

Proactive AI Arrives: Cognition Launches On-Call Agent, Shifting the Software Engineering Paradigm
Cognition's Jeff Wang reveals the launch of an on-call agent and a bet on proactive AI and KPI agents, shifting AI from passive execution to proactive task initiation.