How AI Is Changing Software Engineering: Measuring Real Output with Activity Data

Hacker News discussion points out that evaluating AI coding requires distinguishing activity metrics from outcome metrics and building a rigorous measurement system.
The article revolves around a Hacker News discussion on "AI, activity, and software engineering outcomes," with the core argument being: evaluating the effectiveness of AI coding tools cannot remain at the activity level. Activity metrics such as lines of code, commit counts, and PR numbers become systematically distorted with AI assistance; what's truly worth tracking are outcome metrics like defect rates, delivery quality, and maintenance costs. The article further points out that using activity data for causal inference faces three major challenges—confounding factors hard to isolate, substitution effects overlooked, and mismatched measurement cycles—and offers practical team-level advice: define outcome metrics first, treat AI usage as one analysis dimension, and value qualitative signals such as developers' subjective burden.
When AI Enters Software Engineering, What Metrics Should We Use to Measure It?
Discussions about AI's impact on software development often remain at the impressionistic level of "faster or slower." A Hacker News post titled "AI, activity, and outcomes in software engineering" received 59 upvotes and 79 comments. The core of the discussion isn't about any specific tool, but a more fundamental methodological question: how to quantify the relationship between "AI usage" and "engineering outcomes".
Judging from the direction of the discussion, the community's focus has shifted from "can AI write code" to "how to prove what it has brought." This itself is a signal: AI coding tools are transitioning from novelty to infrastructure that needs to be evaluated.
Activity Is Not Output: An Old Problem Amplified in the AI Era
The post's title juxtaposes three words—AI, activity, outcomes. These three form a common analytical chain: treating AI usage as an "activity signal" and then correlating it with final outcome metrics.
The problem is that activity and outcomes have never been equivalent. Activity metrics like lines of code, commit counts, and PR numbers become systematically distorted with AI assistance: tools can generate large amounts of code in a short time, but whether that code enters the main branch, whether it gets modified, and whether it introduces rework—that's outcome-level information.
Hacker News commenters resonated with this: without connecting activity data to downstream outcomes, any conclusion that "AI improved efficiency" is merely inference, not evidence. This also explains why the title emphasizes outcomes—what's truly worth tracking in engineering is delivery quality, defect rates, and maintenance costs, not the buzz of tool usage.
Three Challenges of Using Activity Data for Causal Inference
Confounding Factors Are Hard to Isolate
Teams using AI often simultaneously have stronger toolchains, more aggressive engineering cultures, or more ample resources. Attributing good results to AI easily ignores these parallel variables.
A confounder is a third variable that simultaneously affects both "whether AI is adopted" and "engineering outcomes." In software engineering research, team size, technical debt levels, release cadence, and even the funding stage of the company can all both determine whether a team has the capacity to try new tools and directly affect defect rates and delivery speed. Without controlling for these, regression coefficients will erroneously attribute the contribution of confounders to AI. Randomized controlled trials are the gold standard for eliminating confounding, but implementation costs in real R&D organizations are extremely high, and there are ethical and external validity issues. Therefore most research settles for second best, relying on fixed-effects models or matching methods to approximate causal effects, with robustness of conclusions highly dependent on data quality and model specification.
Substitution Effects Are Overlooked
AI-generated code may increase commits, but it may also increase review burden. Looking at only one end leads to one-sided conclusions. The consensus reflected in the discussion is: evaluation must cover the complete chain from coding to review, from deployment to maintenance.
Measurement Cycles Don't Match
Activity data can be measured daily, while feedback cycles for software quality are often longer. Using short-term activity metrics to infer long-term outcomes inherently involves bias. This point was repeatedly mentioned in the discussion and is where such research is most prone to problems.
Causal inference is the methodology for estimating the net effect of an "intervention" on "outcomes" from observational data. In the engineering productivity field, what it needs to answer is not "do teams using AI perform better" but "if the same team didn't use AI, how much worse would the results be." In observational data, treatment and control groups often differ across many dimensions to begin with, and directly comparing means introduces selection bias. Common countermeasures include propensity score matching, difference-in-differences, and instrumental variable methods, but each method relies on specific identification assumptions, such as "unobserved confounders do not change over time." In software engineering scenarios where AI tools iterate rapidly and team composition constantly changes, these assumptions are difficult to strictly satisfy—which is the root cause of why causal conclusions in this field are often questioned.
The distinction between leading and lagging indicators is key to understanding this challenge. Commit counts, PR numbers, and code generation volume are leading indicators that can be collected at hourly or daily levels; while defect escape rates, production incidents, maintenance costs, and technical debt accumulation are lagging indicators that often take weeks or even quarters to manifest. Inferring the trajectory of lagging indicators from changes in leading indicators implicitly assumes a stable transmission relationship between the two, but in AI-assisted scenarios this assumption is being challenged: a short-term surge in output may come at the cost of long-term maintainability. Engineering productivity measurement typically recommends tracking both types of indicators simultaneously and reserving sufficient observation windows for lagging indicators, rather than substituting short-term activity for outcome judgment.
Practical Implications for Engineering Teams
For teams currently introducing AI coding tools, this discussion provides a pragmatic thinking framework.
First, define outcome metrics before discussing AI's contribution. Metrics such as defect density, change failure rate, and review time should be established before using AI, rather than searching for data afterward to support conclusions.
Second, treat AI usage as a dimension, not a variable. Only by incorporating it alongside team size, project complexity, and other factors into analysis can we see relationships closer to reality.
Third, value qualitative signals. Developers' subjective burden and code comprehension costs—these difficult-to-quantify aspects—often expose problems earlier than numbers do.
Change Failure Rate and defect density are core outcome metrics in engineering productivity frameworks such as DORA. Change Failure Rate refers to the proportion of changes that require rollback, hotfixes, or cause service degradation after deployment to production, measuring delivery quality rather than delivery speed; defect density is typically expressed as defects per thousand lines of code or per function point, reflecting the intrinsic quality of code. These metrics are suitable as anchors for AI evaluation because they are directly tied to business consequences and are not easily contaminated by the activity volume of the tools themselves. Teams should establish baselines and collection standards for these metrics before introducing AI coding tools; otherwise, retrospective analysis often lacks comparable data.
Conclusion
The value of this Hacker News discussion lies not in providing conclusions, but in reminding us: AI's effects in software engineering require more rigorous measurement approaches. Distinguishing activity from outcomes is the starting point for any meaningful evaluation. For teams relying on AI coding tools, building a credible measurement system is more important than chasing the next tool.
Related articles
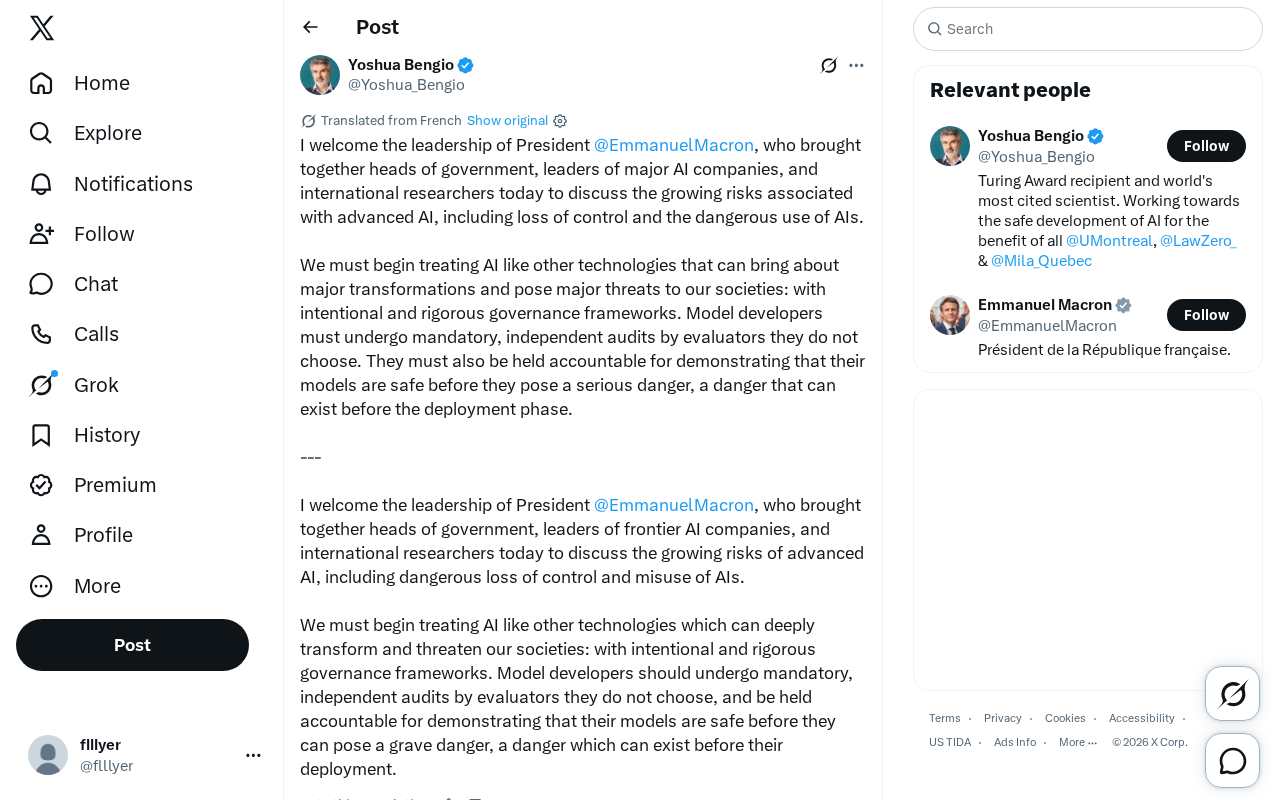
New AI Governance Initiative: Mandatory Independent Audits and Pre-Deployment Safety Proof
Macron convened government leaders, AI company executives, and researchers to discuss advanced AI risks. Statements call for a rigorous governance framework requiring mandatory independent audits and pre-deployment safety proof.

Roblox Funds Controversial Anorexia Treatment
Roblox funds flow to a controversial creator who promotes ketogenic diets over conventional treatment for anorexia and bulimia, raising medical and regulatory concerns.
GitHub Daily · November 19: Veteran Frontend Framework Returns to the Charts, Historical Map Project Gains Nearly a Thousand Stars in a Day
GitHub Trending Nov 19: jQuery and SolidJS both make the list, Appwrite adopts an agent-oriented positioning, and Jiangshan Shixu gains nearly 1,000 stars in a day.