How Does an Agent Remember a Conversation from Three Years Ago? Breaking Down the 5 Core Pillars of Long-Term Memory Architecture

A five-part breakdown of how Agents build long-term memory using storage, hybrid retrieval, and forgetting mechanisms.
LLMs have no built-in long-term memory — Agent memory is entirely powered by external engineering systems. This article uses an interview-question format to unpack five core pillars: classifying memory into short-term, long-term, and working memory; storing based on value and signals with conflict detection; retrieving using temporal decay, importance weighting, and hybrid search; applying hierarchical context compression without losing critical data; and implementing forgetting mechanisms with evaluation pipelines to close the loop.
LLMs Have No Memory — So What Gives Agents Their Memory?
Here's a question interviewers love to ask: your Agent has been serving the same user for three years — what exactly allows it to remember what that user said back then?
Most candidates fire back immediately: a vector database — store all the conversation history, then retrieve the most semantically similar entries when needed. But the follow-up question is where things get interesting: the user said they love full-sugar lattes three years ago, but switched to sugar-free last year. Both memories get retrieved — which one should the Agent trust?
That's where most people get stuck. This question isn't about reciting frameworks — it's about whether you've actually built and run a memory system end-to-end. LLMs have no long-term memory of their own; an Agent's "memory" is entirely backed by an external engineering system. Let's break that system down into five questions, going deeper at each level.
Question 1: How Many Types of Memory Are There?
Most people say short-term and long-term memory — but that's only two-thirds of the answer. A complete memory system has three types.
Short-term memory is the context of the current conversation. It arrives fast and disappears fast — close the window and it's gone. Long-term memory stores user preferences, facts, and important events across sessions, remaining available the next time a new conversation starts.
The one most people miss is working memory — the intermediate state an Agent maintains while executing a task: what sources it's already looked up, which tools it's called, how far along a multi-step task it is. Without working memory, a ten-step task will completely forget what happened in steps one through six by the time it reaches step seven, spinning in circles indefinitely. Clearly distinguishing all three types tells an interviewer you're not just theorizing.
Question 2: You Can't Store Every Single Line, Right?
Of course not. What determines whether something gets stored isn't frequency — it's value and signal strength. There are three common engineering approaches.
The first is batch extraction at session end. When a user mentions "business trip to Tokyo next week," the system stores a structured memory entry (event, time, location) rather than dumping the raw conversation into the database. The second is event-triggered immediate writes. When a user says "note that I'm allergic to mangoes," that's the highest-priority signal — it gets written to the store on the spot, not queued for later summarization. The third is background cleanup during idle periods, merging scattered memories, deduplicating, and consolidating similar entries.
There's also a bonus answer here that separates strong candidates: conflict detection. When a new memory contradicts an old one, you don't just append a new record — you update the original entry with a new timestamp, ensuring two conflicting memories aren't both active at the same time. Very few candidates get this far.
Question 3: Is Vector Similarity Enough on Its Own?
No. Relying solely on similarity will get you into trouble — retrieval needs to be a combination of signals.
Semantic similarity is the foundation, but it needs to be layered with temporal decay — a preference from last year shouldn't carry the same weight as one from three years ago. Add importance weighting on top — critical information like allergens shouldn't be treated the same as "wants to watch a movie."
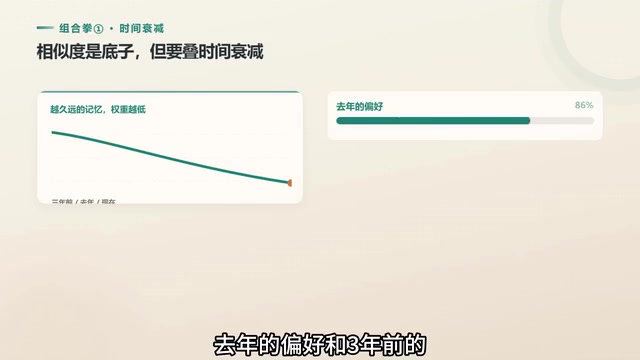
Finally, apply hybrid retrieval: use both keyword-based and vector-based search in parallel for key information, so that proper nouns — names, model numbers, IDs — don't get semantically diluted. One rule of thumb worth remembering: good memory retrieval isn't looking for "the most similar" entry, but "the most relevant one right now." This is exactly the answer to the full-sugar latte problem from the intro — through temporal decay and conflict updates, the more recent "sugar-free" preference wins out.
Vector databases work by converting text into high-dimensional numeric vectors and measuring semantic proximity via cosine similarity or Euclidean distance. This approach excels at capturing semantic similarity — even if the phrasing differs, "I don't eat sweets" and "I prefer low-sugar drinks" would be retrieved together because of their semantic closeness. But pure semantic retrieval has two inherent weaknesses: it's insensitive to proper nouns (model numbers, names, codes) because these terms lack stable semantic anchors in vector space, and it completely ignores temporal information — it can't distinguish whether a memory was written yesterday or three years ago. Hybrid Retrieval runs vector search and keyword-based sparse retrieval (such as BM25) in parallel, then merges results using strategies like Reciprocal Rank Fusion (RRF). This balances semantic coverage with exact matching and is the dominant approach in production environments today.
Question 4: The Context Window Is Limited — What Then?
No matter how powerful external memory is, the context window is still finite. The solution is to make the context "breathe" — applying hierarchical compression before it fills up: keep the most recent few turns verbatim, compress older turns into a summary paragraph, and condense anything from a month ago into a single memory entry transferred to long-term storage.
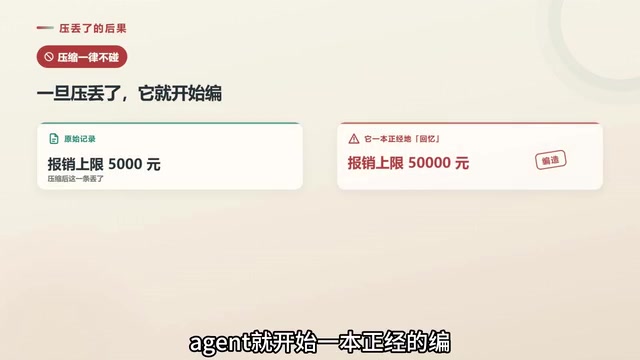
There's a pitfall here that most people only understand after stepping in it: critical numbers must be locked. System prompts, hard user requirements, monetary amounts, deadlines — these are never touched during compression. Once they're lost, the Agent starts confidently hallucinating, and this is the single most common failure mode in real-world projects.
The context window is the maximum number of tokens a model can process in a single inference call — currently ranging from 8K to 200K across mainstream models. Even as windows continue to grow, the cost is non-linear: longer contexts mean higher inference latency and cost, and research shows that models exhibit significantly reduced attention to information positioned in the middle of the context (the so-called "lost in the middle" phenomenon). So even when the window is large enough, engineering practice still requires actively managing the structure and priority of context content — not simply appending history indefinitely. Hierarchical compression is essentially an explicit tradeoff between latency and information completeness, preserving a three-tier structure of "recent verbatim + mid-term summary + long-term key facts" so the model always operates within the highest signal-to-noise context possible.
Question 5: Can an Agent Forget?
Yes — and it must be able to. Memories that haven't been retrieved in a long time, memories that have been superseded by new facts, and low-value memories should all be down-ranked and eventually purged. Otherwise the memory store keeps growing, and retrieval quality degrades over time.
So how do you verify the system is working well? The answer is the next-day quiz: tell it something today, ask about it again tomorrow using different phrasing — did it remember? Did it remember correctly? Did it appropriately forget what it should have forgotten? There are already dedicated long-term memory benchmarks in the field that evaluate five things: information extraction, cross-session reasoning, knowledge updates, temporal reasoning, and knowing when to decline to answer. Candidates who say "memory systems need evaluation too" leave a completely different impression on interviewers.
Memory evaluation remains a relatively underdeveloped area in Agent engineering. Common benchmarks in the field (such as those from the MemGPT paper and LongMemEval) construct test scenarios spanning multiple sessions and evaluate five dimensions: single-hop information extraction (can the system accurately recall facts the user stated?), cross-session reasoning (can it integrate information across multiple conversations to reach conclusions?), knowledge updates (do new facts correctly supersede old ones?), temporal reasoning (can the system determine which memory is more recent and which has expired?), and refusal judgment (the system should not fabricate answers for questions that fall outside its memory). Incorporating the memory system into an automated evaluation pipeline — running alongside functional tests — is the engineering foundation for long-term stability.
What These Five Questions Are Really Testing
At their core, these five questions test three capabilities.
Structured thinking: classify before acting — don't let "vector database" be your answer to every memory question. Real-world experience: how to handle conflicts, what gets lost in compression, why similarity alone isn't enough for retrieval. Closed-loop thinking: remembering something isn't the finish line — you need to be able to verify it was remembered correctly and that the right things were forgotten.
Someone without hands-on project experience answers the question "what is memory?" Someone who has shipped real projects answers "how do you keep memory from failing?" That's the dividing line. For developers building Agent applications today, this architecture isn't just an interview topic — it's a core engineering challenge that determines whether your product can deliver a stable, high-quality experience over the long term.
Related articles

Amphibious Transforming Drone: Beyond 100x Power Savings, What Are the Real Needs?
Is the amphibious transforming drone just a gimmick? Starting from the 100x power difference of the M4 Morphobot, explore real application scenarios and thesis topic ideas, analyzing boundary conditions where pure drones and pure ground robots both fail.

Warhound Raises $200 Million: Genetically Engineered "War Dogs" Paired with Anduril Gear
Warhound raises $200M, backed by Ben Lamm and Palmer Luckey, to genetically engineer dogs for military and law enforcement use and equip them with Anduril gear. This article analyzes its technology direction, funding logic, and ethical controversy.

Claude API Comes to Google Cloud: IAM Integration and SDK Access Guide
Anthropic hosts the full Claude API on Google Cloud with IAM-controlled permissions and unified billing. This guide covers the Vertex AI and Anthropic-hosted entry points, IAM role configuration, and SDK access.