How to Harness Frontier Models: Reflections Sparked by a Keynote

A deep dive into what it takes to harness frontier models: prompting, evaluation, cost control, and safety guardrails.
A tweet about a VP of AI keynote on "harnessing frontier models" surfaces the central challenge of production AI engineering. This article unpacks the concept of frontier models — powerful but costly and unpredictable — and explores what harnessing them actually requires: structured prompt and context design, quantifiable evaluation frameworks, cost reduction through model routing and caching, and robust input/output safety guardrails. The core argument: competitive advantage is shifting from owning models to mastering the engineering needed to deploy them reliably.
The Signal Behind a Tweet
Recently, a company posted on social media that their VP of AI had delivered a keynote at an AI conference on "how to harness frontier models," along with a link to the talk. What looked like a brief, unremarkable tweet actually reflects one of the central questions facing the entire industry right now — as large model capabilities continue to push the boundaries of what's possible, how can enterprises and developers effectively "harness" them?
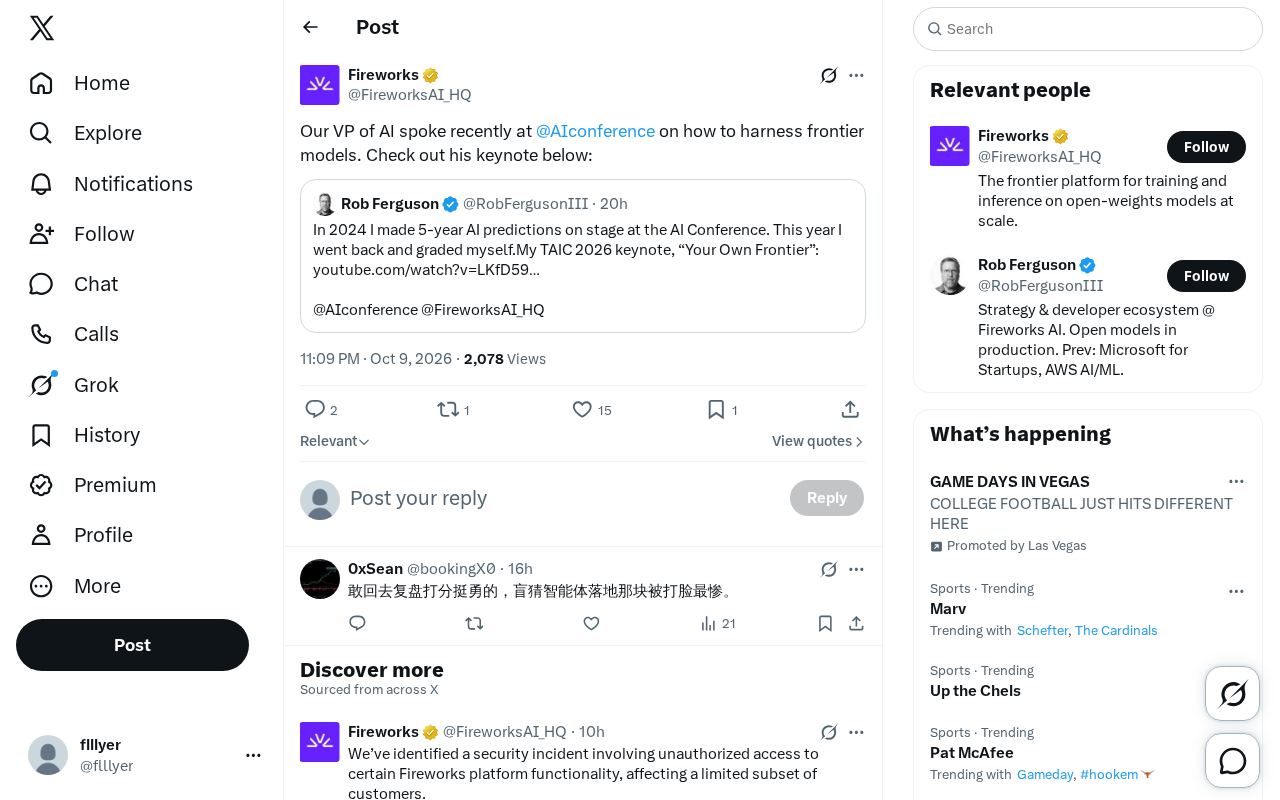
Because the original source material only provided a one-line caption, the specific content of the talk cannot be fully reconstructed here. But the phrase "harness frontier models" has itself become a high-frequency keyword in AI engineering discussions over the past two years, and is well worth a deeper exploration.
What Are "Frontier Models"?
"Frontier models" typically refer to large-scale foundation models at the cutting edge of capability — general-purpose models with massive parameter counts, multimodal understanding, complex reasoning, and long-context abilities. These models are usually trained by a small number of leading labs. They are powerful, but they also come with high costs, significant uncertainty, and potential safety risks.
For enterprises, frontier models represent both an opportunity and a challenge: they unlock product experiences that were previously out of reach, but they also introduce a host of engineering problems — hallucination control, cost management, compliance, and predictability, to name a few. "Harnessing" them is, at its core, about finding the right balance between a model's powerful capabilities and the real-world constraints of deployment.
From an academic and policy perspective, the concept of the "Frontier Model" has in recent years moved beyond technical circles into the heart of regulatory debate. Major economies including the United States and the European Union have singled out "frontier models" or "General-Purpose AI Systems" (GPAI) in their AI legislation, requiring developers to meet stricter transparency and safety assessment obligations. Models currently recognized as frontier-class include OpenAI's GPT-4o series, Anthropic's Claude 3 series, Google's Gemini Ultra, and the large-parameter versions of Meta's Llama 3. Whether a model qualifies as "frontier" is generally assessed by training compute thresholds (the EU AI Act uses $10^{25}$ FLOPs as a baseline), performance on cross-domain benchmarks, and whether the model exhibits emergent capabilities — reasoning, code generation, or tool use that arises spontaneously beyond the training objective. It is precisely this emergent quality that gives frontier models their breakthrough value while also making their behavior difficult to fully predict, which is what creates the need to "harness" them in the first place.
What Does "Harnessing Frontier Models" Look Like in Practice?
Based on publicly available industry experience, a talk on harnessing frontier models would likely cover the following areas:
1. Prompt Engineering and Context Design
Using structured prompts, system instructions, and context injection to get a general-purpose model to reliably perform a specific task is the most fundamental — and most critical — piece of the puzzle. Well-designed context often delivers better cost-efficiency than simply chasing a larger model.
2. Evaluation and Reliability
The outputs of frontier models are inherently stochastic. Enterprises need to build a quantifiable evaluation framework to continuously monitor accuracy, hallucination rates, and robustness — rather than relying on gut feel to judge whether a model is "good enough."
LLM Evaluation has evolved into its own engineering sub-discipline. Common evaluation frameworks include: automated metrics based on reference answers (such as BLEU and ROUGE, primarily used for translation or summarization tasks); the LLM-as-a-Judge approach, where a separate strong model scores outputs across multiple dimensions; and human annotation pipelines tailored to specific business contexts. Hallucination detection is particularly complex. Common industry strategies include consistency checking (sampling the same question multiple times and comparing divergent answers), retrieval-based fact verification (RAG + a validation layer), and dedicated hallucination detection models. A/B testing frameworks and shadow traffic mechanisms are also widely used to compare different model versions in real production environments, ensuring that evaluation conclusions reflect actual online performance rather than just offline benchmark scores.
3. Cost and Latency Trade-offs
The inference cost of calling frontier models is too significant to ignore. Common strategies in practice include model routing (using smaller models for simple tasks, reserving frontier models for complex ones), caching, and batching — all aimed at striking the right balance between user experience and cost.
Model Routing has become one of the dominant architectural patterns for reducing frontier model call costs. The core idea is to train a lightweight classifier or use a rules engine to predict the complexity of each incoming request, routing simple queries to smaller, lower-cost models (such as GPT-4o mini or Claude Haiku) and sending only tasks that truly require deep reasoning to flagship models. Representative open-source tools include RouteLLM and LiteLLM. On the latency side, Speculative Decoding allows a small model to generate a parallel draft that a large model then verifies, significantly reducing Time to First Token (TTFT) without sacrificing output quality. Prompt Caching is natively supported by major API providers like Anthropic and OpenAI, and can reduce redundant computation costs by 60–80% in scenarios where system prompts are fixed. The combined application of these techniques represents the core engineering competency for "harnessing frontier models" from a cost perspective.
4. Safety and Guardrails
As models become more autonomous, input/output auditing, permission controls, and behavioral constraints become increasingly important. The word "harness" inherently implies an emphasis on keeping risk under control.
Why These Talks Are Worth Paying Attention To
When a company creates a senior role like "VP of AI" and sends that person to share their methodology for harnessing frontier models at an industry conference, it signals that AI adoption has moved past the early experimentation phase and into a deeper, more systematic and engineering-intensive stage. The question enterprises are asking is no longer "can we use large models?" — it's "how do we use them well, reliably, and affordably?"
This mirrors a broader industry trend: the real competitive edge is shifting from "owning a model" to "the engineering capability to harness one." The teams that can most efficiently translate frontier model capabilities into reliable product experiences are the ones who will win the deployment race.
Closing Thoughts
Due to the limited information in the original source material, this article cannot present the specific arguments or data from that keynote — readers are encouraged to seek out the original video for first-hand content. But the question of "how to harness frontier models" is a core challenge that no team serious about putting large models into production can afford to ignore. It touches on the full spectrum of prompt design, evaluation frameworks, cost control, and safety guardrails — a comprehensive set of capabilities that must be built together.
Related articles

Agent Skills Beginner's Guide: From Concepts to Multi-Agent Collaboration in Practice
A comprehensive guide to Agent Skills: core concepts, components, the importance of Description, standardization, beginner learning paths, and multi-agent collaboration.

One Neuron Detects Both Cats and Cars? We Reproduced It and Found a New Explanation
The cat-car neuron reinterpreted: researcher Cammarata argues it distinguishes pointy from round, not cats from cars. We reproduced the experiment and found the new explanation holds on most inputs—but cars are the exception. The interpretability debate continues on language models.

MCP Server + Python Assistant: A MicroStation Design Efficiency Revolution
Explore the early preview of the MCP Server and Python Assistant in MicroStation 2026: custom tools in five minutes, intelligent sheet index checks, and how AI is reshaping drawing workflows to unleash design creativity.