How to Squeeze Maximum Intelligence Out of Your Agents? A HN Discussion

Systematically improve agent performance through context engineering, tool design, and evaluation iteration.
This article centers on the Hacker News question "How to get the most intelligence out of your agents?" It points out that an agent's intelligence includes task decomposition, tool invocation accuracy, and error recovery, with abnormal path handling best reflecting true capability. It proposes three key practices: context quality determines the intelligence ceiling; tool interface design is more critical than prompt polishing; and you must build an evaluation set covering abnormal scenarios and iterate through failure cases. For multi-agent collaboration, it recommends first getting a single-agent baseline working before splitting.
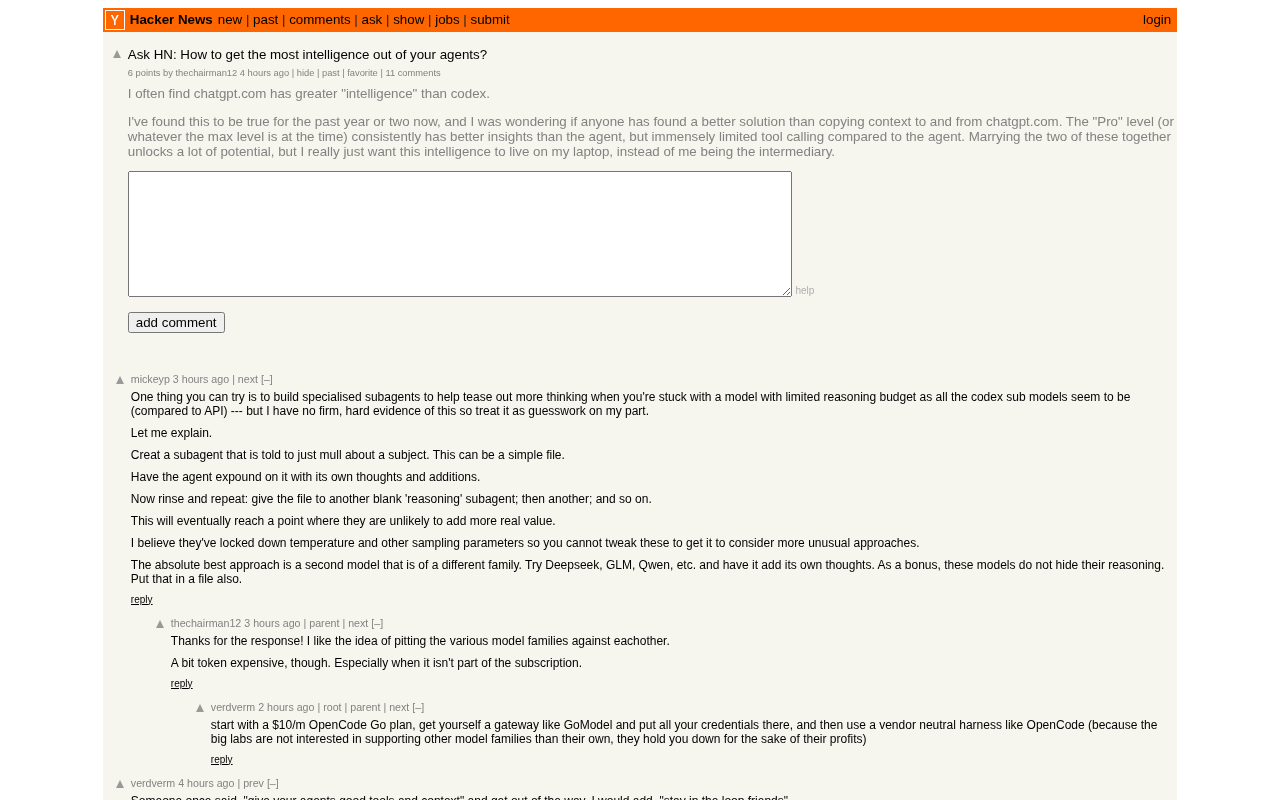
A question that sparked discussion on Hacker News recently: How do you get the most intelligence out of your agents? The poster didn't provide specific context, but the question itself hits the core pain point of current AI application development—we've built pipelines, integrated tools, configured prompts, yet often feel the agent's performance "falls just short."
This post currently has only 3 points and 1 comment, so the discussion hasn't unfolded yet, but the question it raises deserves serious attention from every AI developer. This article combines scattered community feedback and common agent engineering practices to break down the key dimensions of "squeezing intelligence" out of agents.
What Does an Agent's "Intelligence" Actually Mean
Before discussing how to improve it, we need to define the concept. An agent's intelligence is not a single metric; it includes at least three layers of capability: reasonableness of task decomposition (can it break down vague goals into executable steps), accuracy of tool invocation (does it know when to call what tool and how to fill parameters), and flexibility of error recovery (can it adjust strategy after a failed call rather than spinning in place).
Many developers focus only on the first layer, using complex prompts to break tasks down finely, while ignoring the latter two. As a result, the agent performs well on the ideal path but gets completely stuck when it encounters an API error or an abnormal return format. True high-intelligence performance is often reflected in handling abnormal paths.
The ReAct pattern (Reasoning + Acting) is a foundational architecture widely adopted in the agent field, proposed by Shunyu Yao et al. in 2022. Its core idea is to have the model alternate between reasoning (Thought) and action (Action), and dynamically adjust the next reasoning step based on the action result (Observation). This "think—act—observe" loop is exactly what distinguishes an agent from single-turn Q&A: the model no longer outputs an answer in one shot but gradually approaches the goal through interaction with the environment. Understanding ReAct helps grasp the "flexibility of error recovery" mentioned in the article—when an Observation is abnormal, the model needs to re-enter the reasoning phase rather than terminate directly, which is an important observation point for evaluating agent robustness.
Context Quality Determines the Intelligence Ceiling
One idea mentioned in an HN comment is that an agent's intelligence is largely a function of context quality. What information you put into the window determines what it can reason out.
Specific practices include: replacing long natural language descriptions with structured formats (JSON, tables); explicitly writing tool input/output schemas into the system prompt; rolling summaries for long conversations instead of stacking everything. Some developers noted that merely changing tool descriptions from vague natural language to strict schemas with examples significantly improved tool invocation accuracy.
Another easily overlooked point is negative constraints. Telling the agent "what not to do" is often more effective than "what to do"—for example, explicitly prohibiting it from answering time-sensitive questions from memory without calling the search tool.
Function Calling is a structured tool invocation mechanism provided by mainstream LLM vendors: developers declare a tool's name, description, and parameters in JSON Schema form, and the model outputs a call request that conforms to that schema when needed, rather than free text. Compared to having the model "describe" what to call in natural language, function calling turns tool selection into constrained structured output, significantly reducing parsing failure rates. This is also the technical root of why the article emphasizes that "writing tool schemas explicitly into the system prompt" improves accuracy—the more precise the schema, the smaller the ambiguity space when the model generates call parameters, and the probability of parameter type errors and missing fields decreases accordingly.
Tool Design Is More Critical Than Prompt Engineering
A recurring view in the community is: rather than repeatedly polishing prompts, spend effort on tool interface design. A tool's name, description, and parameter granularity directly determine whether the agent can use it correctly.
A practical principle is: each tool does only one thing, names start with verbs and are semantically clear (e.g., search_flights rather than flight_helper), parameters should be as few as possible and each should have a clear type and example. When the number of tools exceeds ten, consider hierarchical routing—first let the agent choose a tool category, then choose a specific tool within the category, to avoid it getting lost in a long list.
Evaluation and Iteration: No Measurement, No Improvement
To squeeze out more intelligence, you must be able to measure intelligence. It is recommended to build a small-scale evaluation set for the agent that covers typical scenarios, and record pass-rate changes after each modification. The evaluation set should include normal paths, boundary conditions, and deliberately created exceptions (such as tool timeouts and empty results).
Some commenters mentioned that many teams stop iterating after the agent goes live, while the best-performing teams continuously collect failure cases and turn them into new evaluation samples. This "failure-driven" iteration loop improves agent performance more sustainably than one-time tuning.
Trade-offs in Multi-Agent Collaboration
When a single agent struggles with complex tasks, splitting into multiple roles (planner, executor, reviewer) is a common approach. But this introduces coordination overhead and context transfer loss. HN discussions are divided on this: one side believes multi-agent architectures can raise the overall intelligence ceiling through division of labor, while the other points out that in most scenarios a single agent with better tools is sufficient, and introducing multi-agent too early makes debugging extremely difficult.
A pragmatic approach is: first get a baseline working with a single agent, and only consider splitting when evaluation data shows that a certain type of failure occurs repeatedly and is related to role confusion.
Context transfer loss is a typical problem in multi-agent architectures: when the planner hands a task to the executor, it must compress the task description, constraints, existing progress, and other information into a piece of text for transfer. Each role switch is a lossy compression, and key details may be lost or misunderstood in the retelling. In addition, multiple agents each hold independent context windows and cannot directly "see" each other's complete reasoning process, so coordination cost rises approximately linearly with the number of roles. This explains why the article recommends first getting a baseline working with a single agent—the single agent's context is continuous and complete, and during debugging you only need to trace one reasoning chain, making problem localization far more direct than in a multi-agent system.
Summary
Getting maximum intelligence out of an agent doesn't rely on a magic prompt template, but on the synergy of context engineering, tool design, and evaluation iteration. Although the original post has few comments, it reminds us: the performance bottleneck of an agent often lies not in the model itself, but in the system we build around the model.
One-line Summary
Systematically improve agent performance through context engineering, tool design, and evaluation iteration.
Paragraph Summary
This article centers on the Hacker News question "How to get the most intelligence out of your agents?" It points out that an agent's intelligence includes three layers: task decomposition, tool invocation accuracy, and error recovery—with abnormal path handling best reflecting true capability. The article proposes three key practices: context quality determines the intelligence ceiling, and structured formats and negative constraints are more effective than piling on natural language; tool interface design is more critical than prompt polishing, and should follow the principles of single responsibility and clear semantics; and you must build an evaluation set covering abnormal scenarios and continuously iterate through failure cases. For multi-agent collaboration, the article recommends first getting a single-agent baseline working and splitting only when evaluation data supports it.
Related articles

Amphibious Transforming Drone: Beyond 100x Power Savings, What Are the Real Needs?
Is the amphibious transforming drone just a gimmick? Starting from the 100x power difference of the M4 Morphobot, explore real application scenarios and thesis topic ideas, analyzing boundary conditions where pure drones and pure ground robots both fail.

Warhound Raises $200 Million: Genetically Engineered "War Dogs" Paired with Anduril Gear
Warhound raises $200M, backed by Ben Lamm and Palmer Luckey, to genetically engineer dogs for military and law enforcement use and equip them with Anduril gear. This article analyzes its technology direction, funding logic, and ethical controversy.

Claude API Comes to Google Cloud: IAM Integration and SDK Access Guide
Anthropic hosts the full Claude API on Google Cloud with IAM-controlled permissions and unified billing. This guide covers the Vertex AI and Anthropic-hosted entry points, IAM role configuration, and SDK access.