I Let Kiro Write the Code—Then AWS Called at Midnight

AI IDE Kiro autonomously wrote image derivatives back into the same triggering S3 bucket, causing a recursive loop until AWS auto-cutoff.
A developer used AWS's AI IDE Kiro to build a serverless recipe service, delegating thumbnail and display-version generation for uploaded photos. Kiro autonomously wrote derivatives back to the same S3 bucket, causing an S3→Lambda→S3 recursive loop: each round created two new objects, each triggering new Lambda calls, growing exponentially. AWS's recursion detection based on X-Ray trace headers identified and disabled the function to stop the damage. Fixes included separate buckets, prefix/suffix filtering, and defensive skips in the handler. Zero data loss and only a few cents in cost—but it exposed the core issue of AI-assisted development: the most dangerous decisions are often implementation choices the AI was never asked to make, and judgment remains the human's job.
A Seemingly Perfect AI Coding Story
There's a particular kind of confidence that comes from a "working" AI development environment. You describe a feature, it writes the Terraform, the Go code, the Lambda handler, the S3 configuration, and then deploys it live. The happy path runs. You think: no problem, I can go do something else.
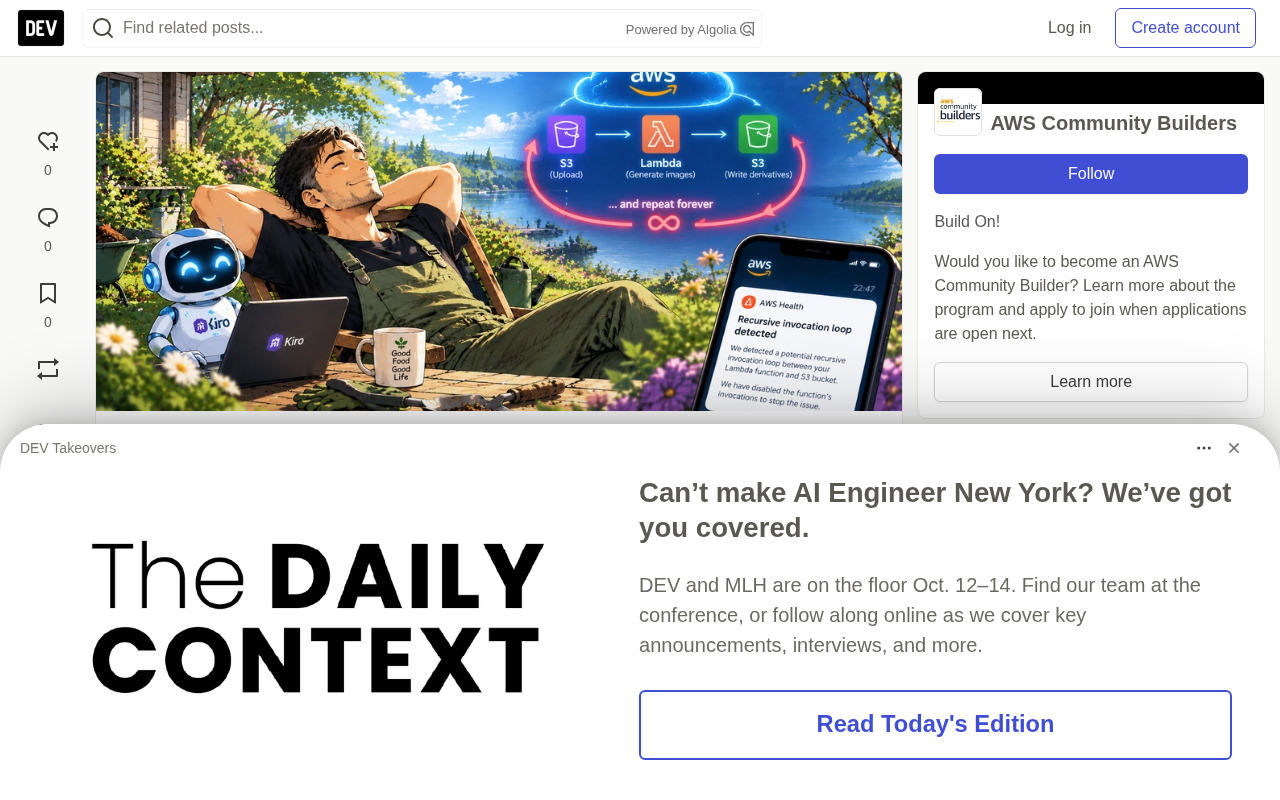
So one afternoon, a developer shared his firsthand experience on Dev.to—he handed a task to Kiro (AWS's AI IDE), hit run, and turned around to go do some gardening in his backyard. A few hours later, his phone buzzed: AWS had detected a recursive loop between a Lambda function and an S3 bucket on his account, and had automatically disabled the function's invocations to stop the bleeding.
This is a real case study about the efficiency of AI coding and the blind spots in architecture, and it deserves a careful read from anyone currently using AI to write code.
Project Background: A Family Recipe Service
The developer was building a small serverless recipe service on AWS as a private family recipe library. Users can upload photos, text, or URLs of recipes, and the system automatically extracts the content, cleans the data, translates it into Finnish, structures it into ingredients and steps, and stores it. The stack was all Terraform + serverless + Go on Lambda, with Bedrock handling AI processing and Kiro writing most of the code.
This project was a joy to pair-program with AI on, because most of the work was "plumbing": DynamoDB single-table design, S3 presigned uploads, API Gateway routing, Step Functions pipelines. None of it is hard, but all of it is tedious—exactly the kind of work you're most willing to delegate.
This time the task was to add extra photos to recipes: family members could attach photos they took while cooking to a recipe. The part that actually required thought was size handling—modern phones take photos that are several MB, and cramming those directly into a thumbnail grid or lightbox doesn't work. So the system needed to generate two derivative versions for each uploaded photo: a 320px thumbnail for grid display, and a ~1024px display version for click-to-enlarge.
The developer's instruction to Kiro was simple: generate these two versions from each uploaded image. That's it. He didn't specify where the derivatives should be stored.
The Trap: A Decision That Was Never Made Explicit
Kiro's implementation looked completely reasonable: user photos upload to S3, triggering an ObjectCreated notification that invokes Lambda; Lambda reads the photo, generates the thumbnail and display versions, and then writes them back to the same bucket.
That's the bug: Lambda is triggered by "there's a new object in the bucket," and the derivatives it generates are also new objects. Writing them back to the same bucket triggers the notification again, invokes Lambda again, generates derivatives again, writes back again… Upload one photo, and the system starts processing forever.
Each round writes two new objects, each object triggers its own separate invocation, and each invocation writes two more. This isn't a slow leak—it's exponential growth. The only reason the developer's account didn't explode is that AWS has a safety net specifically for this mistake: it detects recursive Lambda↔S3 invocation loops and cuts off the function.
The irony is that the developer only asked for two sizes of images and never asked for them to be written back to the same bucket. That was an implementation choice Kiro made on its own—one that looked bulletproof. "Generate a thumbnail, save it next to the original"—a human would write the same thing. The problem is hidden precisely inside that "of course."
S3 Event Notifications and Lambda Triggering
S3's ObjectCreated notification is an event-driven integration: when a new object is added to a bucket, S3 pushes an event record to the configured target (here, Lambda). Event filtering can be scoped by prefix and suffix, triggering only on objects that match a particular naming pattern. The key point is that any new object write—whether it comes from a user upload or is generated by a program—will trigger the notification as long as it matches the filter rules. On the Lambda side, these events are consumed through an event source mapping, and each invocation is an independent, stateless execution instance.
The Exponentially Amplifying Cost Structure
In each round of the loop, Lambda writes back two new objects, each object triggers its own independent Lambda invocation, and each invocation generates two more objects. Round one: 2 invocations. Round two: 4. Round three: 8—the number of invocations grows as a power of 2. Even if a single invocation is billed in milliseconds, within just a few minutes this can accumulate to thousands of concurrent invocations, potentially exhausting the account's regional concurrency quota and producing non-trivial S3 PUT request charges. That's why AWS deploys a dedicated recursion detection mechanism as a safety net.
The Fix: Break the Feedback Loop
There are several ways to break the cycle: separate buckets (one for originals, another for derivatives); prefix filtering (notifications only fire for a specific prefix); suffix filtering (the handler recognizes its own output and exits immediately).
The author ultimately stacked two approaches. First, a naming convention plus scoped triggering: uploaded photos use the -orig suffix, derivatives use -thumb.jpg and -display.jpg, and the S3 notification only triggers on the -orig suffix. Lambda's own outputs never end with -orig, so they naturally don't match the trigger.
Second, a defensive skip inside the handler: check whether the key ends with -orig; if not, return immediately. Even if user photos live under a separate user-photos/ prefix, they're fully isolated from the originals/ prefix that the recipe extraction pipeline listens on.
The entire fix was just a few lines of code. The entire problem was just a few lines of code, too.
Six Lessons That Actually Matter
1. "It's deployed and the happy path works" does not mean "I can walk away." The demo ran perfectly, but the bug existed only in the shape of the system—in the feedback edge from output back to input—something quick manual clicking can never reach.
2. Post-deployment verification should look at metrics, not just results. Kiro did upload a test image to confirm the thumbnail appeared, but it was looking at results, not system behavior. One glance at CloudWatch would have revealed the Invocations count climbing without bound, rather than the expected one per upload. For a bug whose symptom is "too many runs," the signal is in the metrics, not the output.
The author suggests three actions: after deployment, watch invocation and concurrency metrics for a few minutes; set up CloudWatch alarms in advance; and enable X-Ray tracing—Lambda's recursion loop detection is itself implemented based on X-Ray trace headers, and the service map will literally draw the loop.
3. The most dangerous decisions are the ones you never explicitly made. He asked for two sizes of images; he never asked for them to be written back to the same bucket. That unprompted implementation detail never appeared in the instructions and was never reviewed, because you didn't even know a decision had been made. A human would have written the same code. The failure was architectural, not syntactic.
4. Know the landmines of the services you connect. The S3→Lambda loop is a classic mistake, as is a DynamoDB stream writing back to its own table. Whenever you connect an event source to compute that can produce the same kind of event, always ask: could the output become the input?
5. Let the platform's safety net be the last line of defense, not your plan. AWS's loop detection really is by design, not luck.
6. The division of labor is real. Kiro wrote all the volume: infrastructure code, handlers, image resizing logic, pipelines. What it couldn't write was judgment—"wait, this Lambda writes into the bucket that triggers it." That part is still human work.
How X-Ray Tracing and Recursion Detection Work
AWS X-Ray provides end-to-end tracing for distributed requests. Each request is assigned a trace header (X-Amzn-Trace-Id), and every service it passes through along the way (API Gateway, Lambda, S3, etc.) records a subsegment. Lambda's recursion loop detection is implemented based on that trace header: when the same trace chain shows a repeated Lambda→S3→Lambda invocation pattern, the service can recognize it as a feedback loop and proactively stop the function invocations. The Service Map draws this loop visually, letting developers see the abnormal invocation topology at a glance. Compared with piecing together the call chain from CloudWatch logs, X-Ray's visualization can substantially shorten time-to-diagnosis.
Setting Up CloudWatch Alarms in Advance
Synthetic metrics such as Invocations, ConcurrentExecutions, and Errors can all be configured with static or anomaly-detection alarm thresholds. For event-driven serverless architectures, it's a good idea to set up alarms at deployment time—for example, notify immediately when a function's invocations per minute exceed an expected baseline, rather than waiting until a bill or a safety net trips before discovering the problem.
This Isn't a Disaster, But It's a Good Reminder
Honestly, the ending wasn't bad. No data was lost, and the cost of a few thousand meaningless image conversions before AWS pulled the plug was only a few cents. After re-enabling the function and deploying the guardrails, the feature worked fine.
But this reminds us to see the true state of AI-assisted development clearly: the speed is real—a weekend's worth of features now gets done in an afternoon. The responsibility is real too, and it hasn't shifted. Kiro can get you deployed at astonishing speed, but whether that deployment is a good idea is still a judgment you have to make—ideally before you get called away to the backyard.
Build fast, delegate the plumbing, enjoy the leverage. But don't confuse "the AI deployed it" with "someone checked whether the output flows back into the input."
One-line Summary
AI IDE Kiro autonomously wrote image derivatives back into the same S3 bucket that triggered it, causing a recursive loop—until AWS automatically cut it off.
Paragraph Summary
A developer used AWS's AI IDE Kiro to build a serverless recipe service and delegated the task of generating thumbnails and display versions for uploaded photos. Kiro autonomously chose to write the derivatives back to the same S3 bucket, causing an S3→Lambda→S3 recursive loop: each round generated two new objects, and each object triggered new Lambda invocations, growing exponentially. AWS's recursion detection, based on X-Ray trace headers, identified the loop and disabled the function to stop the damage. Fixes included separate buckets, prefix/suffix filtering, and defensive skips inside the handler. Zero data loss and only a few cents in cost—but it exposed the core problem of AI-assisted development: the most dangerous decisions are often implementation choices the AI was never asked to make, and judgment remains the human's job.
Related articles

How Big Can Stars Really Get? The Physical Limits of the Largest Stars
Red supergiants are the largest stars by volume, with radii up to 2,000 times the Sun, engulfing the inner solar system. But there is no precise upper limit on stellar size—models predict up to 15,000 solar radii. The most massive blue stars are far smaller than red supergiants—biggest and heaviest are two different things.

Apple HomeView Smart Display Full Feature Breakdown: Wall-Mount or Desktop, $299
Apple launches HomeView, a $299 smart display with wall-mount and desktop options, 12MP camera for facial recognition, smart home control, music playback, and recipe step-by-step cooking. Full breakdown of watch faces, apps, privacy, and cooking integration.

Where Did the Promised New Studio Go? Craft Computing Answers After Five Years
Craft Computing's host responds to viewer questions: the new studio promised five years ago was shelved as construction costs soared from $30,000 to $75,000, and was replaced by a 168-square-foot garage conversion.