Kimi K3.1 Pro Released: 2.8T-Parameter MoE, 1M Context
Moonshot AI releases Kimi K3.1 Pro: 2.8T total parameters, 104B activated, 1M context, with plans to open weights.
Moonshot AI has released Kimi K3.1 Pro, a Mixture-of-Experts model with 2.8T total parameters and only 104B activated per inference (about 3.7% activation), a highly sparse path aimed at broad knowledge coverage while keeping inference compute at the tens-of-billions level. It supports a 1M token context for entire technical documents, medium codebases, and long conversations, complementing low activation cost. It scores 65.7% on Terminal-Bench 4.0, which tests practical terminal operation and is relevant to agent applications. API pricing is $2 input and $10 output per million tokens, upper-middle range. Moonshot plans to open weights on November 4, significant for teams needing private deployment and fine-tuning.
Moonshot AI has officially released Kimi K3.1 Pro—a Mixture-of-Experts (MoE) model with 2.8T total parameters and 104B activated parameters, featuring a context window of 1M tokens. This combination of specs targets the two core battlegrounds in the current large-model competition: the inference cost advantage brought by extreme sparsity, and the engineering deployment enabled by ultra-long context.
Parameter Architecture: A Sparse Design with 2.8T Total and 104B Activated
Kimi K3.1 Pro adopts an MoE architecture with 2.8 trillion total parameters, but only activates 104B parameters per forward pass. The activation ratio is about 3.7%, placing it on a highly sparse design path. The logic behind this trade-off is clear: use an extremely large total parameter count to carry broader knowledge and capability coverage, while keeping the compute cost of a single inference pass at the tens-of-billions parameter level, avoiding the cost blowup of dense models in long-context scenarios.
For developers, 104B activated parameters means the inference hardware threshold is far lower than the first impression given by the number 2.8T. What really determines deployment cost is the activation path, not the total weight count.
The core idea of the Mixture-of-Experts (MoE) architecture is to split the feed-forward network into multiple parallel "expert" sub-networks, then use a gating network (router) to dynamically select a small number of experts for each token to participate in computation. This allows the model's total parameter count to be very large, while a single token's forward propagation follows only one sparse path, with compute cost roughly proportional to the "activated parameter count." Common sparsity ratios in the industry range from 5%–15%; compressing the activation ratio to about 3.7% as Kimi K3.1 Pro does is relatively aggressive sparsification. The cost is that memory usage is still determined by total parameters—2.8T weights require considerable VRAM even at low-precision storage, so MoE models typically rely on multi-GPU parallelism or expert parallelism for deployment. This is also why "large total parameters, small activated parameters" does not equal "runnable on a single GPU."
The relationship between activated parameters and deployment cost deserves separate explanation: FLOPs during inference are mainly determined by activated parameters, so throughput and latency are close to those of dense models at the tens-of-billions parameter level; but weight loading, VRAM capacity, and cross-GPU communication are still tied to the total parameter count. In actual deployment, MoE often stresses memory bandwidth and inter-GPU interconnect more than raw compute. In addition, MoE is sensitive to load balancing; if the gate concentrates tokens on a few experts, some GPUs will sit idle, which is why various vendors introduce auxiliary load-balancing losses during training.
1M Context: Infrastructure for Long-Document and Codebase-Level Tasks
A context window of 1 million tokens is one of the metrics with the highest engineering value in this release. It corresponds to real scenarios such as entire technical documents, medium-sized code repositories, and long-cycle conversation histories—not merely benchmark showmanship.
Combined with the sparse architecture of 104B activation, long context and low inference cost complement each other: the longer the context, the more important the marginal cost per token becomes, and MoE happens to have an advantage in this dimension.
The technical difficulty of ultra-long context is not just "fitting it in," but "using it well." Transformer attention computation grows quadratically with sequence length, and raw attention over 1M tokens is computationally infeasible, so long-context models generally adopt variants such as sparse attention, block attention, or linear/approximate attention, together with positional encoding extrapolation techniques (such as RoPE interpolation or frequency adjustment) to extend short-window capabilities from training to longer sequences. Another common approach is hierarchical memory or retrieval-based compression, summarizing distant context.
For evaluation, the industry commonly uses "Needle in a Haystack"-style tests to check whether a model can accurately recall information at any position in long text, but such tests focus on retrieval and cannot fully reflect capabilities in real long-document tasks such as multi-hop reasoning and cross-chapter integration. Therefore, the actual value of a 1M window depends on the model's reasoning quality and consistency over long-distance dependencies, not just the number of the window length. In addition, long context significantly increases KV Cache VRAM usage; engineering practice often mitigates this through grouped-query attention (GQA), KV Cache quantization, or paged management, which is also an important part of the inference cost of long-context models.
Terminal-Bench 4.0 and Pricing: Dual Positioning of Capability and Cost
Official disclosures state that Kimi K3.1 Pro achieved a score of 65.7% on Terminal-Bench 4.0. This benchmark mainly examines a model's practical operation and task-completion ability in terminal environments, and is highly relevant to agent-style applications. The figure of 65.7% is competitive among current models of the same class, but benchmark results and actual engineering performance still require independent verification.
On pricing, input is $2 per million tokens and output is $10 per million tokens. Given the specs of 2.8T total parameters and 1M context, this pricing sits in the upper-middle range, with output cost 5 times input cost, consistent with current mainstream API billing conventions.
Terminal-Bench is a class of evaluation benchmarks oriented toward agents, where tasks usually require completing multi-step operations in a real command-line environment, such as configuring a development environment, debugging scripts, handling files and dependencies, and executing Git operations. The evaluation provides the model with a containerized terminal; the model must autonomously issue shell commands, read outputs, correct errors, and advance the task, with success judged by whether the task is achieved. Compared with static question-answering benchmarks, it is closer to "whether the model can actually do the work," and is therefore strongly related to applications such as coding agents and automated operations.
Scores on such benchmarks are heavily influenced by the scaffold—the same model may differ noticeably under different agent frameworks and retry strategies, so cross-model comparisons require confirming that evaluation conditions are consistent. Numbers like 65.7% are better used as a reference for capability magnitude rather than a precise ranking. Regarding API pricing, asymmetric billing for input and output is an industry convention because output tokens require token-by-token autoregressive generation and occupy compute time for longer; input can be amortized through batching and KV Cache reuse. When estimating actual costs, one should also factor in the input token inflation caused by long context—in 1M-window scenarios, input cost is often the larger part.
Timeline for Open Weights
Moonshot AI plans to open the model weights on November 4. For teams concerned with private deployment, data compliance, or further fine-tuning, this is more critical information than API pricing—open weights mean model capabilities can be internalized into their own infrastructure without fully relying on cloud calls.
What This Release Means
The spec combination of Kimi K3.1 Pro reflects a clear path for current open/semi-open large models: use extremely sparse MoE to support parameter scale, use ultra-long context to open application boundaries, and use open weights to compete for ecosystem. Whether it can deliver the 65.7% Terminal-Bench performance and the stability of 1M context in real workloads will determine whether it can turn highlights on a spec sheet into developers' actual choice.
Related articles
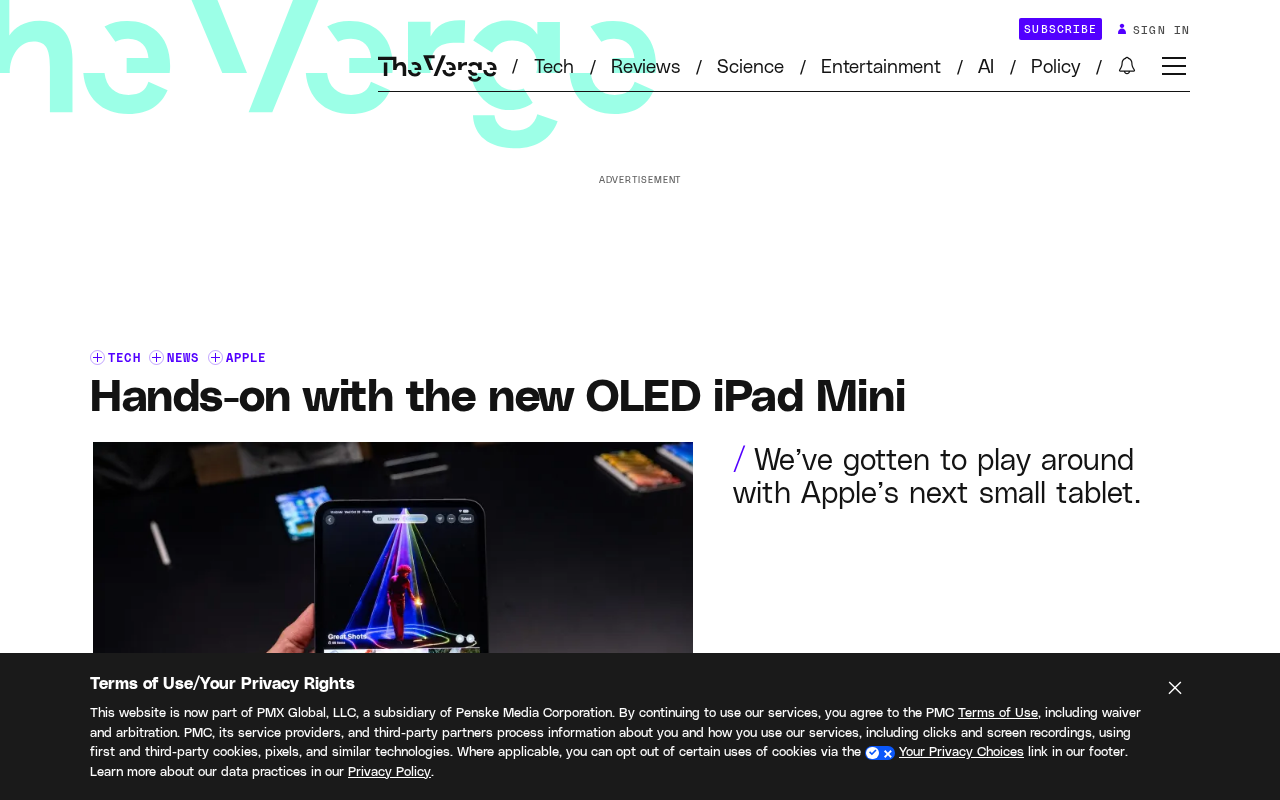
Hands-On: The New OLED iPad Mini Has a Stunning Display
Hands-on with Apple's new iPad Mini: the OLED screen looks excellent, optional nano-texture glass effectively reduces glare, and the portable positioning remains unchanged—ideal for users who want top-tier screen quality in a small tablet.
Hands-On: Apple's First Touchscreen MacBook Pro with OLED Display and Dynamic Island
Hands-on with Apple's first touchscreen MacBook Pro: ProLED XDR OLED display, thinner and lighter chassis, Dynamic Island-style camera interaction, auto-enlarged controls, a $400 starting price premium, but no Apple Pencil support.
Letting Claude Run Indefinitely: Three Key Loops for Long-Horizon Agent Tasks
How to let Claude Agent run autonomously for long periods: from RLVR principles to the four-step loop of tedious task selection, automated verification design, tool supply, and bottleneck questioning—plus a review of TS Rust, Lust, and Skate 3 Bench's real costs and limitations.