Linux Containers in 500 Lines of Code: Demystifying Container Technology
Linux containers are just ordinary processes isolated by Namespaces, Cgroups, and filesystem tricks — provable in 500 lines of code.
Using a "500-line container runtime" open-source project as a starting point, this article breaks down the three pillars of Linux containers: Namespaces using clone()/unshare() syscalls for isolation, Cgroups writing to /sys/fs/cgroup for resource limits, and pivot_root with Mount Namespaces for independent filesystem views. Containers aren't lightweight VMs — they're a combination of existing kernel capabilities. This minimal implementation strips away the complexity of production runtimes like runc and containerd, helping developers build mental models to better understand Docker networking, Kubernetes resource limits, and real-world debugging scenarios.
Containers Are Not Magic
In today's cloud-native era, container platforms like Docker and Kubernetes have become standard tools for developers. Yet many people still think of containers as little more than "lightweight virtual machines." In reality, Linux containers are neither virtual machines nor some mysterious black magic — at their core, they're simply ordinary processes that have been carefully isolated and constrained.
A technical post on Hacker News titled Linux containers in 500 lines of code demonstrated a working container runtime built from scratch in under 500 lines, offering a clear window into the core mechanisms behind containers. These "build it from scratch" projects often do more to build deep intuition about underlying principles than reading high-level documentation ever could.
The Three Pillars of Container Technology
Understanding containers means understanding a few core capabilities that the Linux kernel provides. A minimal container implementation typically revolves around three mechanisms.
Namespaces: The Walls of Isolation
Namespaces are the foundation of container isolation. The Linux kernel provides several types of namespaces, including PID (process), Network, Mount, UTS (hostname), IPC (inter-process communication), and User namespaces. By placing a process into its own set of namespaces, the container's processes "believe" they're running in an independent system environment — with their own process tree, network stack, and filesystem view.
At the implementation level, this typically means calling the clone() or unshare() system calls with the appropriate flags (such as CLONE_NEWPID, CLONE_NEWNET, etc.). Just a few lines of code are enough to send a new process into an isolated world.
Cgroups: The Leash on Resources
If namespaces answer the question of "what can a process see," then cgroups (control groups) answer "how much can it use." Cgroups allow you to precisely limit and account for the CPU, memory, disk I/O, and other resources consumed by a group of processes. This is what enables containers to enforce resource quotas and prevent a single container from exhausting the host's resources.
In a minimal implementation, resource limits are typically applied by writing configuration values to specific files under /sys/fs/cgroup — a straightforward and low-level operation.
Cgroups have gone through two major versions. cgroups v1 maintains separate hierarchy trees for each resource type (cpu, memory, blkio, etc.), making coordination across subsystems difficult, with complex configuration and consistency issues. cgroups v2, introduced in Linux 4.5 and progressively adopted in the 5.x series, unifies all resource controllers under a single hierarchy, simplifies configuration paths, and introduces more precise memory protection mechanisms (memory.min / memory.low). Modern Linux distributions (such as Ubuntu 22.04 and Fedora 31+) have switched to cgroupv2 by default, and both Docker and Kubernetes have improved their v2 support in recent versions. Understanding the differences between the two versions helps when troubleshooting inconsistent container resource-limiting behavior across different host environments.
Filesystem Isolation: An Independent Root
Containers need their own independent view of the filesystem. Traditionally, chroot was used to change a process's root directory, but modern containers more commonly use pivot_root combined with Mount Namespaces to achieve more thorough isolation. This allows the inside of a container to have a completely different directory structure and file contents from the host.
There is a fundamental security difference between chroot and pivot_root. chroot only changes how a process perceives the root directory; a process with CAP_SYS_CHROOT privileges can escape back to the host filesystem via certain paths, making it unsafe to use alone. pivot_root, on the other hand, truly switches the root of the entire mount tree within a Mount Namespace. The old root can be unmounted or hidden, dramatically narrowing the escape surface. Production-grade container runtimes like runc combine pivot_root with Mount Namespaces and execute umount2(old_root, MNT_DETACH) after entering the container to completely sever the connection to the host's mount tree. Additionally, OverlayFS, as a union filesystem, allows multiple containers to share the same read-only image layers while recording differences only in a writable layer — greatly reducing disk usage, and serving as the underlying support for Docker's layered image design.
Why 500 Lines of Code Matters
A full production-grade container runtime (like containerd or runc) involves a massive codebase covering extensive edge-case handling, security hardening, and compatibility shims. Implementing a "toy" container in 500 lines strips away all of that engineering complexity and goes straight to the core principles.
The value of this kind of implementation lies in:
- Demystification: It helps developers realize that containers are simply a combination of kernel features wrapped together, not an incomprehensible black box.
- Educational clarity: For engineers who want to deeply understand Docker's underlying mechanisms, this is an excellent learning path.
- Improved debugging ability: Once you understand the underlying principles, troubleshooting container-related networking, permission, and resource issues becomes far more intuitive.
From Building Wheels to Understanding the Ecosystem
It's worth emphasizing that the goal of writing a container runtime by hand isn't to replace mature tools — it's to build a mental model. Once you understand how Namespaces isolate networks and how Cgroups limit memory, Docker's network configuration and Kubernetes resource limits (requests/limits) start to make perfect sense.
These kinds of projects also reflect a valuable learning culture in the open-source community — using minimal implementations to convey the core ideas behind complex systems. Similar examples include the classic projects for implementing a database, compiler, or operating system in a few hundred lines. Together, they form an invaluable set of resources for engineers looking to level up.
The OCI (Open Container Initiative) specification is an important bridge between "toy containers" and the production ecosystem. OCI defines two core standards: the Image Spec, which defines the layer structure and metadata format of container images; and the Runtime Spec, which uses config.json to describe a container's namespaces, mount points, capabilities, and other configuration, requiring any compliant runtime to be able to parse and execute it. runc is the reference implementation of the OCI Runtime Spec. Higher-level runtimes like containerd and CRI-O wrap it with image management and lifecycle management capabilities, and Kubernetes interfaces with them via the CRI (Container Runtime Interface). After understanding Namespaces, Cgroups, and filesystem isolation, reading the OCI Runtime Spec documentation can help you quickly map out the layered architecture and responsibility boundaries of the entire container ecosystem.
Conclusion
Container technology dominates every aspect of modern software deployment, yet its underlying principles are surprisingly straightforward. Through the exercise of implementing containers in 500 lines of code, developers can truly "see through" containers — they are nothing more than ordinary processes isolated by Namespaces, constrained by Cgroups, and equipped with an independent filesystem. For engineers who want to move beyond being users to becoming deep practitioners, implementing a miniature container by hand may be one of the most effective learning experiences available.
(Note: Since the original source material only provided a title and limited discussion, this article is based on general principles of Linux container technology. Please refer to the original project code for specific implementation details.)
Related articles
Anthropic IPO Countdown: The Compute Cost Ledger Behind a $2 Trillion Valuation
Anthropic's IPO targets up to $2 trillion — double its Series H valuation. We break down the timeline, compute cost logic, and the key question investor day must answer.
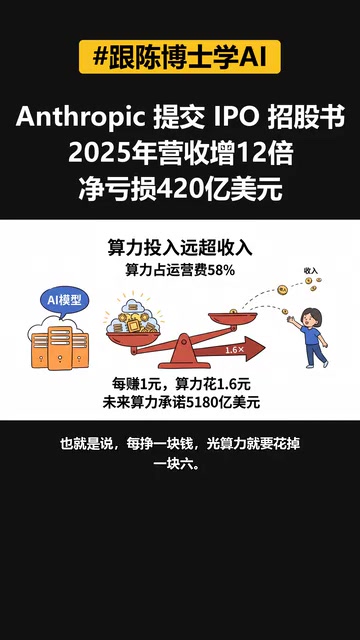
Anthropic IPO Prospectus Revealed: Behind 12x Revenue Growth, the Twin Tests of Compute Costs and Customer Concentration
Anthropic filed its IPO prospectus: 2025 revenue up 12x to $4.6B, net loss $42B including $34B non-cash. Breaking down compute costs, $2T valuation logic, customer concentration risks, and founder control.
Xteink X4 Pro Review: A Mini E-Reader That Fits in Your Pocket, Now More Affordable
Xteink X4 Pro is a 4.26-inch mini e-reader, smaller and thinner than a 6-inch Kindle, magnetically attachable to phones, and cheaper than ever. We analyze its screen, design, use cases, and value.