llm-meta-ai 0.2 Released: A Full Breakdown of Meta's New Model Muse Wonder

Meta releases Muse Wonder, benchmarked against top models, with six reasoning levels.
Meta AI has released Muse Wonder (and Full version), calling it its most capable model yet. Artificial Analysis scores its Max mode on par with GPT-6.1 Sol, and Simon Willison suggests it may be among Meta's first "Fable-class" models. It offers six reasoning levels from minimal to max for flexible compute allocation. Willison updated the llm-meta-ai plugin to 0.2 and used the "pelican riding a bicycle" test to compare levels, finding material gains over Muse 1.3 and 1.2.
Meta Unveils Muse Wonder: A Substantial Leap in Model Capability
Meta AI has just released Muse Wonder (along with Muse Wonder Full), which the company calls "the most capable model to date." This launch marks another major sprint for Meta in the large language model race.
Meanwhile, well-known developer Simon Willison quickly updated his llm-meta-ai plugin to version 0.2 to support the new model. This plugin lets users call Meta AI's models directly through the LLM command-line tool — quite handy for developers who prefer working in the terminal.
Performance Benchmark: On Par with GPT-6.1 Sol
According to evaluation data from Artificial Analysis, Muse Wonder (in Max mode) scores at the same level as GPT-6.1 Sol. This is a notable signal — if the data holds up, it means Meta's model capabilities have caught up with the current top-tier closed-source models.
In his blog, Simon Willison offered an interesting assessment: Muse Wonder may be among Meta's first "Fable-class" models. This classification suggests a qualitative leap in reasoning depth, instruction following, and handling of complex tasks — not just a pileup of parameters.
Artificial Analysis is an independent third-party AI model evaluation organization. It scores mainstream large models across a unified benchmark suite (covering dimensions like mathematical reasoning, code generation, and knowledge Q&A) and produces a composite quality index. Compared to benchmark data self-published by vendors, Artificial Analysis's evaluations are more trusted by the developer community because of their consistent methodology and fixed samples, and are often used as a reference for model selection. That said, any single evaluation organization's scores are just a reference: different organizations emphasize different test sets, and equal scores don't mean identical performance across all tasks. You should still run targeted validation for your own use case before deploying in production.
Six Reasoning Levels: From Minimal to Max
Muse Wonder offers six reasoning levels: minimal, low, medium, high, xhigh, and max. This tiered design lets users flexibly allocate compute resources based on task complexity — simple Q&A gets fast responses at lower levels, while complex reasoning tasks can switch to higher levels for deeper analysis.
Simon Willison used his signature "pelican riding a bicycle" test to visually compare each level. While this testing method may seem less than serious, it effectively probes a model's spatial understanding, detail adherence, and creative generation capabilities.
Reasoning effort is a design that has gradually become common in large model products over the past two years. Under the hood, it usually corresponds to adjusting "chain-of-thought length" or "test-time compute." The model generates an internal reasoning process before answering; the higher the level, the more tokens this reasoning is allowed to consume, giving the model more opportunity to break down problems step by step, self-check, and backtrack. The cost is that latency and expense rise in tandem — a max-level response might take several times longer than minimal, and for simple questions there's often no gain, or even introduced bias from overthinking. So these tiers aren't "higher is better" — they let users make cost-performance tradeoffs based on task difficulty, essentially handing some scheduling decisions back from the model's internals to the user.
The Progress Trajectory Revealed by the Pelican Test
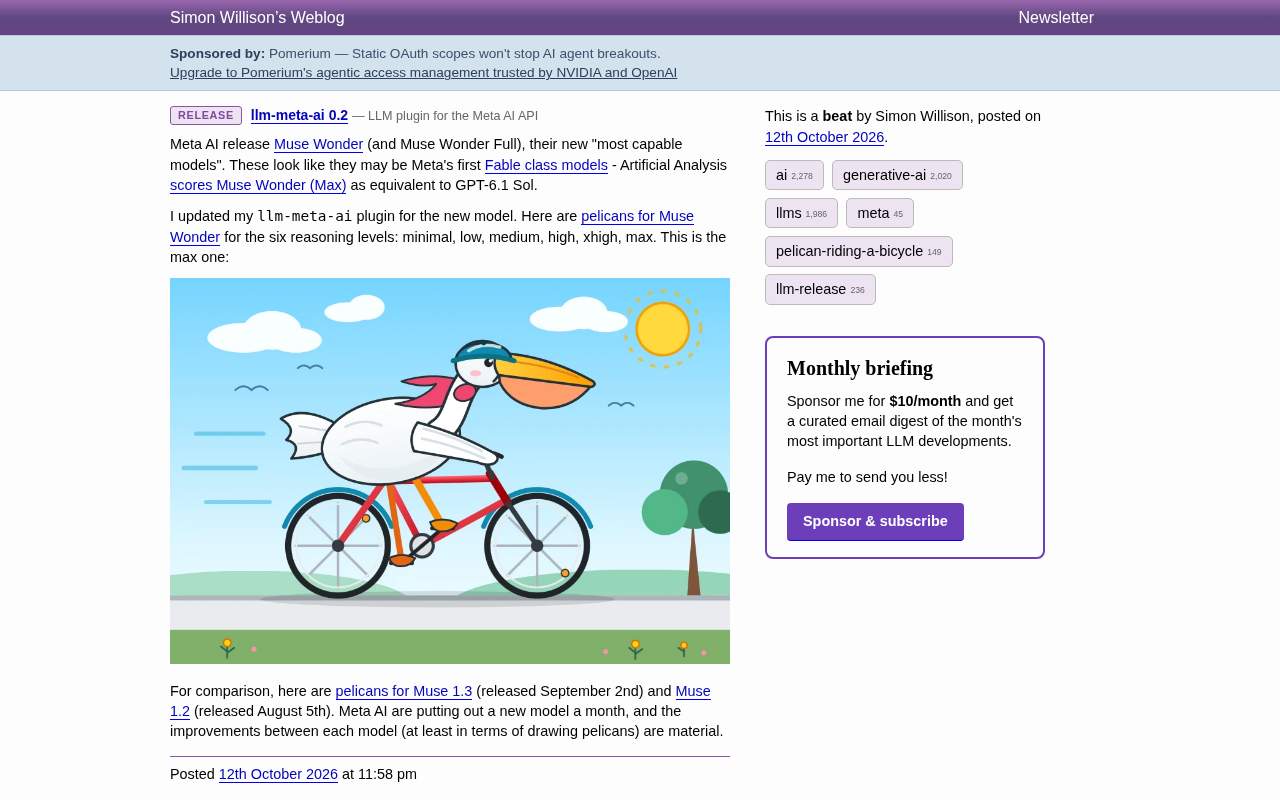
At the max level, Muse Wonder's generated pelican image showed solid completion: a blue cycling helmet, a bicycle with fenders, a reasonable background, and a "passable" beak shape. Of course, there were flaws — the bicycle was missing a crossbar.
More convincing is the longitudinal comparison. Simon placed Muse Wonder alongside the pelican test results from Muse 1.3 and Muse 1.2, released just weeks earlier, and found "material improvements" with each iteration. This pace of progress is worth noting.
The "pelican riding a bicycle" test was proposed and popularized by Simon Willison. The approach is to have a model draw a pelican riding a bicycle, either in SVG or via image generation. It works as an informal benchmark because the task simultaneously tests multiple capabilities: anatomical features like the pelican's beak, throat pouch, and webbed feet probe fine-grained knowledge; the bicycle requires sensible spatial relationships between frame, wheels, and pedals (a missing crossbar is a common spatial error); and the riding posture involves object interaction and creative composition. A single simple prompt can expose a model's weaknesses in structural consistency and detail adherence, and it's easy to compare across models and versions — which is why developers often use it as a quick-and-dirty way to gauge a model's capability tier.
A Monthly Model Release Cadence
Meta AI currently maintains a pace of roughly one new model release per month. Simon Willison specifically noted that from Muse 1.2 to 1.3 to Muse Wonder, the improvement between each generation is "material" — at least when it comes to drawing pelicans.
This rapid iteration strategy reflects the fierce competition in today's AI model landscape. Vendors are no longer satisfied with annual major version updates; instead, they continuously push the performance ceiling higher through high-frequency, small-step sprints. For developers and users, this means re-evaluating model choices more frequently — and also that the dividends of capability improvements are being released at an accelerating pace.
One-line Summary
Meta releases Muse Wonder, benchmarked against top-tier models, with six reasoning levels.
Paragraph Summary
Meta AI has released its new model Muse Wonder (and Full version), calling it its most capable model to date. Artificial Analysis shows its Max mode scores on par with GPT-6.1 Sol, and Simon Willison suggests it may be among Meta's first "Fable-class" models. It offers six reasoning levels from minimal to max, letting users allocate compute by task complexity. Willison updated the llm-meta-ai plugin to 0.2 to support the new model and used the "pelican riding a bicycle" test for visual comparison across levels. Results show high image completion at max, though flaws like a missing bicycle crossbar remain; compared with Muse 1.3 and 1.2 from weeks earlier, each generation shows material improvement, reflecting Meta's roughly monthly release cadence.
Related articles

When Did Paid Childcare Become the Norm? Working Mothers and the Evolution of Childcare
When did paid childcare become the norm? This article traces the evolution from the rise of childcare centers in the 1970s–80s and the 1990s linking of federal subsidies to work requirements, to declining stigma and rising costs, and explores advocates' 25-year effort to catch up with other countries on childcare and paid parental leave.

Red Flags for Product-Market Fit: A Practical Guide from Top VCs and the Superhuman Founder
Investors from Iconiq and Sapphire Ventures and Superhuman founder Rahul Vohra share PMF red flags and practical methods, including the 40% disappointment rule, retention curves, and acquisition costs.

What Task Should AI Agents Take Over Most? Heated Reddit Discussion
Reddit discussion: Which task do you most want AI agents to take over completely? Cross-app data migration, CRM updates, and report generation top the list, but insufficient reliability and the trust gap are the biggest obstacles to automation adoption.