Local AI King: The Compute Gap and Competitive Anxiety Behind 12M Tokens a Day
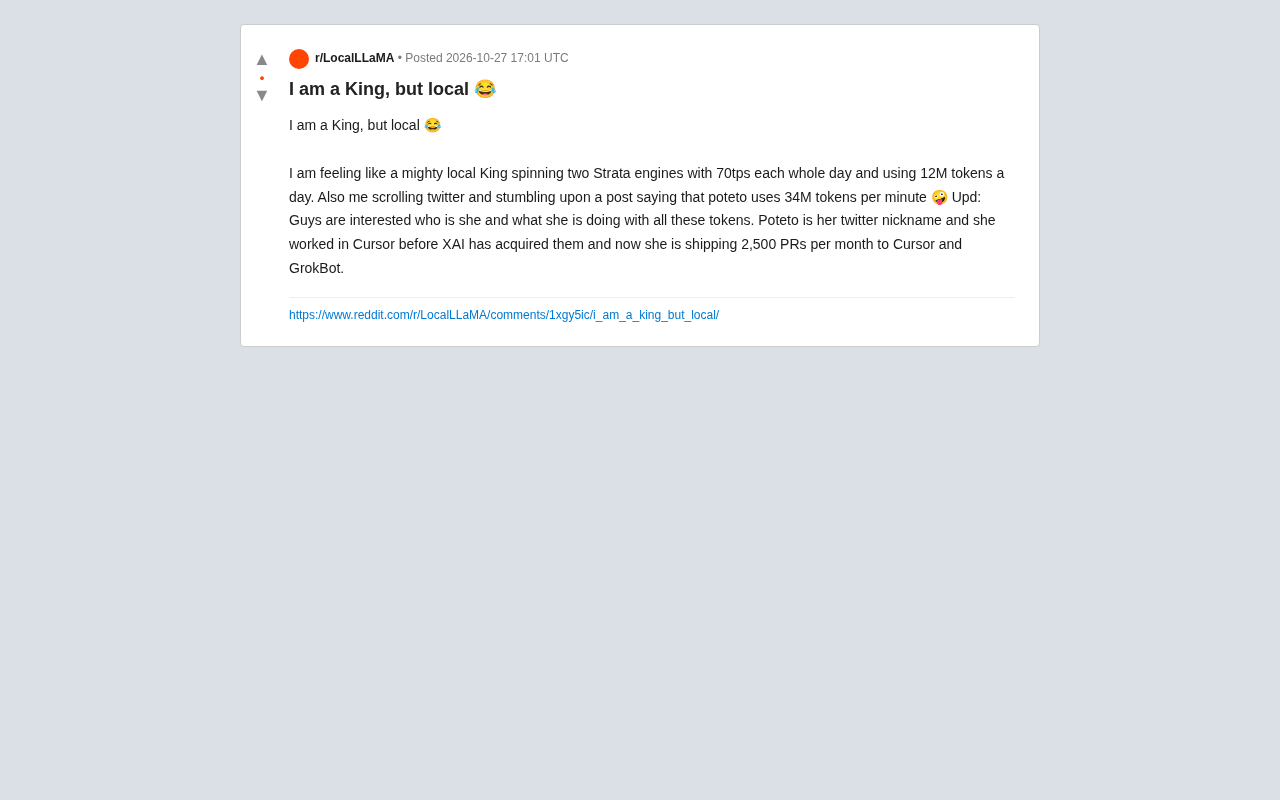
A Reddit user jokes about being a local deployment king with 12M tokens a day, but is humbled by someone using 34M tokens per minute—reflecting AI developers' compute anxiety.
Starting from the Reddit hot post "I am a King, but local," this article tells of a local developer's pride in running two Strata inference engines and consuming 12 million tokens a day, and his psychological落差 upon seeing someone on Twitter consume 34 million tokens per minute. It analyzes the advantages of local deployment—privacy, controllability, and no quota limits—along with its hardware ceiling, and explains the scale effects of large-scale cloud automation pipelines (e.g., 2,500 PRs per month). The author notes that token consumption is becoming an implicit comparison metric in the AI development community, but high consumption does not equal high-value output. Local fine-grained control and cloud-scale automation each have their reasonable scenarios and will coexist long-term; developers should find their own rhythm.
A Reddit post titled "I am a King, but local 😂" has drawn attention. The poster jokingly calls himself a "local king," running two Strata engines simultaneously at 70 tps each, consuming 12 million tokens a day, and quips that he feels "like a king." But when he scrolls Twitter and sees someone consuming 34 million tokens per minute, he instantly breaks down. This stark contrast reflects the compute anxiety and shifting sense of identity among today's AI developers.
The Satisfaction and Limits of Local Deployment
The poster's setup—"dual Strata engines, 70 tps, 12M tokens a day"—is already quite substantial for a local deployment scenario. Strata, as an inference engine, lets individual developers run relatively large models locally with decent throughput. This configuration means he can make model calls at a high frequency to support daily development and experimentation needs. For many developers constrained by API quotas and costs, this is already a "little king" experience—data stays fully local, responses are timely, and there's no worry about external service interruptions.
But the word "local" also implies a ceiling. The compute limits of local hardware dictate throughput and concurrency; no matter how large the model or how many requests, a single-machine environment will hit bottlenecks. The poster's use of "but local" to poke fun at himself shows precisely that he knows his throne is limited in scale.
The "Dimensional Strike" of 34M Tokens per Minute
What broke the poster was a tweet about poteto. According to additional information from the poster, poteto is a developer's Twitter handle; she previously worked at Cursor, which XAI later acquired, and now she submits 2,500 PRs per month to Cursor and GrokBot. That number means she processes over 80 PRs a day, requiring extremely high token consumption to support workflows like code generation, review, and testing.
What the poster saw was a consumption rate of "34 million tokens per minute." Although this figure may come from peak loads under specific workloads or a rough estimate of certain automated processes, it's enough to create a psychological impact: your whole day of careful budgeting is just a rounding error compared to someone else's minute. This magnitude of difference is no longer merely a gap in hardware configuration, but a combined reflection of work patterns, automation levels, and resource investment.
The Industry Reality Behind the Anxiety
This comparison resonates because it touches a common sentiment in the AI development community. As large model capabilities rapidly improve, token consumption is becoming a metric for measuring development intensity—even "productivity." Some teams have begun using token consumption to advertise their degree of automation, while individual developers feel pressure from such comparisons.
However, token consumption does not directly equate to output value. High-frequency PR submissions require accompanying code review and testing processes, or quality issues may arise. Although local developers consume less, they may use each token more carefully and have more direct control over model behavior. Each mode has its reasonable scenarios; it's not simply a matter of better or worse.
Be a Local King, or a Cloud Commoner?
The humor of the post lies in the fact that the poster doesn't reject his choice, but uses "I am a King, but local" to seek a kind of self-reconciliation. The privacy, controllability, and lack of quota limits that local deployment offers cannot be fully replaced by cloud services. For developers who need frequent experimentation, handle sensitive data, or want to deeply understand model behavior, the local environment remains irreplaceable.
Conversely, what large-scale cloud token consumption represents is another possibility: deeply embedding models into the development process through automated pipelines, trading scale for efficiency. This requires sufficient resource support and a more mature engineering system.
The poster's experience reminds us that in an era of rapidly evolving AI development tools, developers need to find their own rhythm. Rather than being intimidated by the number of 34M tokens per minute, it's better to focus on your actual needs and available resources. A local little king can also create real value in his own domain.
Ultimately, this banter about token consumption is actually a light observation of the AI development tool ecosystem. Local vs. cloud, small-scale vs. large-scale, fine-grained control vs. automated pipelines—these choices will coexist for a long time. And every developer is finding their own balance point in their own way.
Background
Inference Engine is a software system specifically designed to run trained large language models, perform forward computation, and generate text. Unlike training frameworks, the core goal of an inference engine is to maximize throughput (tokens per second, tps) and reduce latency on given hardware. Common inference engines include vLLM, TensorRT-LLM, llama.cpp, etc., which improve efficiency through techniques such as continuous batching, PagedAttention, and quantization (e.g., 4-bit/8-bit). The Strata mentioned in the article belongs to this category of tools, enabling individual developers to run larger models on consumer-grade or workstation-grade GPUs. tps refers to the number of tokens generated per second and is a key metric for inference speed; 70 tps means a single engine can generate about 70 tokens per second, doubling with dual engines in parallel, but limited by memory bandwidth and compute, local deployment tps is usually far lower than cloud clusters.
PR (Pull Request) is a merge request on code collaboration platforms (such as GitHub). Developers submit PRs to merge code changes into the main branch, usually accompanied by code review, automated testing, and discussion. Submitting 2,500 PRs per month means an average of over 110 PRs per working day (based on 22 days), which is clearly not achievable by manual line-by-line coding, but rather by AI coding agents automatically generating, modifying, and submitting code. In such workflows, large models are repeatedly called to generate patches, write tests, fix CI failures, etc., and each call consumes a large number of tokens, so the consumption level of 34 million tokens per minute matches a highly automated PR pipeline. This also explains why token consumption has become a proxy metric for measuring automation levels.
Token is the basic unit of text processed by large language models, which can be a word, subword, or character fragment. Models are billed by token and throughput is measured by token. The number of tokens consumed in an API call includes both input (prompt) and output (completion). Consuming 12 million tokens a day is already high in a personal local scenario, while 34 million tokens per minute is equivalent to about 567,000 tokens per second, which requires large-scale GPU cluster parallel inference to support. Using token consumption as a comparison metric has its limitations: it only reflects the scale of calls, not task difficulty, code quality, or actual value; the "value density" of tokens also differs across models and quantization precisions. Therefore, the comparison around token consumption in the community is more of an emotional expression than a rigorous measure of productivity.
Related articles
Open Source Leaders Declare "F**k Open Source": The Ideological Schism in the Free Software Movement
Leaders from GNOME, elementary OS, and the Software Freedom Conservancy endorse a "F**k Open Source" statement advocating anti-capitalist, anti-meritocratic free software. This article examines the statement, endorsers, governance controversies, and profanity rhetoric, analyzing the ideological schism's practical impact on project selection.
Professional Designers Test AI-Cloned CAD: How Far Are Fusion/SolidWorks Alternatives Really?
LTT professional designers test AI-cloned Fusion and SolidWorks alternatives SolidCraft and PuraMetric. Interfaces are similar, but shortcuts fail, constraints are missing, and interactions are inconsistent—how far are they from replacing professional CAD tools?
Why Does Nuclear Fallout Decay So Fast? Explaining the 7-10 Rule
Why does radioactive fallout decay so fast after a nuclear explosion? This article explains the exponential decay of short-lived fission products, the classic 7-10 rule, and why sheltering in the first hours to days can greatly reduce radiation dose, while noting that long-lived contaminants can remain for years.