Local AI Video Generation in Practice: Running Minimax H3 Workflows on an RTX 5090

One creator's RTX 5090 + Minimax H3 local workflow: 180 clips generated to produce one finished AI video.
A creator on Reddit demonstrated a fully local AI video pipeline: Krea2 for initial images, Qwen 2.1 edit for image editing, Minimax H3 for i2v generation with first/last frame control, all orchestrated in ComfyUI and finished with a self-trained upscaler — running entirely on an RTX 5090. About 180 clips were generated to produce one transformation video, exposing the core tension in local AI video today: the toolchain is mature and the hardware can handle complex pipelines, but consistency, motion quality, and generation efficiency remain major gaps that creators must bridge through mass iteration and custom-built tools.
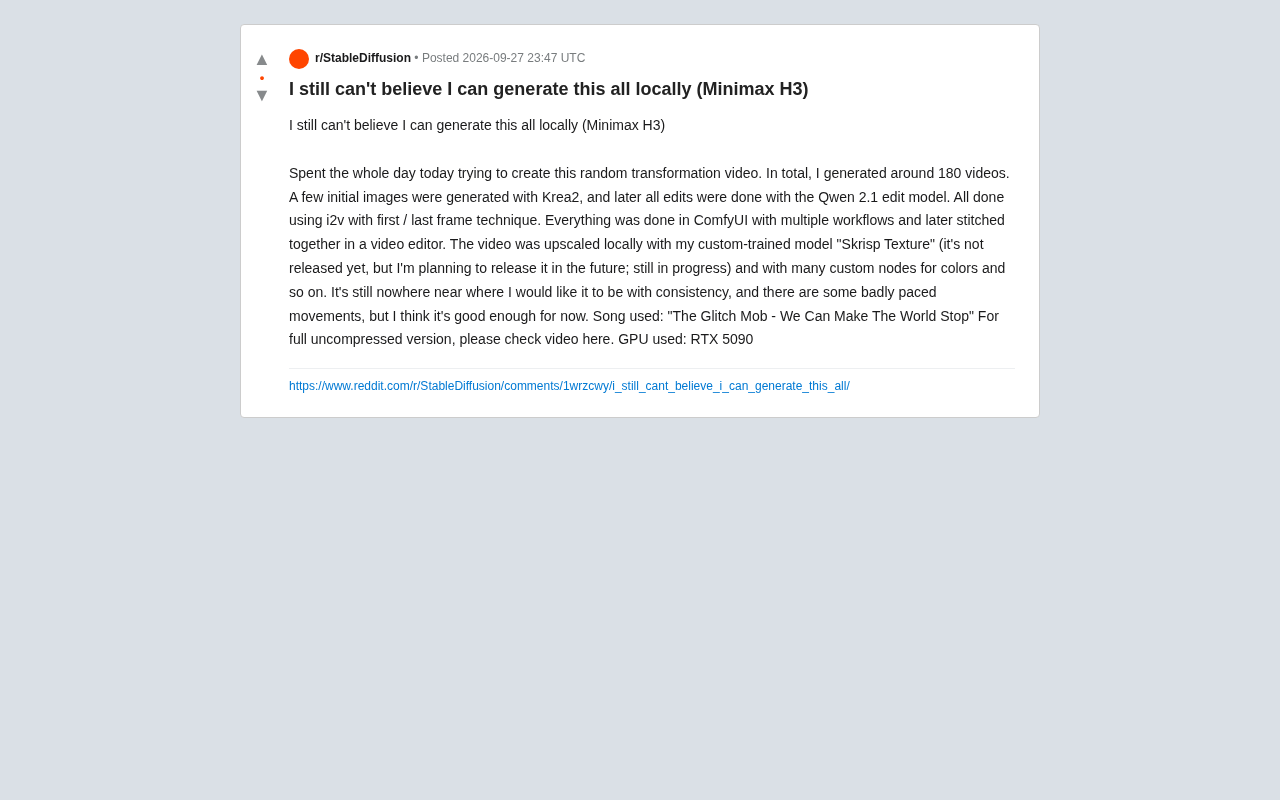
A creator shared on Reddit the complete process of generating a transformation effects video using an entirely local toolchain. The project took a full day, with roughly 180 video clips generated in total, ultimately stitched together using multiple workflows in ComfyUI. The value of this case isn't the polish of the final cut — it's what it reveals about how far consumer-grade hardware paired with open-source models can push local AI video generation.
A Complete Local Workflow Behind One Video
Breaking down the pipeline, this project chained together multiple models and tools — every step running locally:
- Initial images: A small number of starting frames were generated with Krea2
- Image editing: All subsequent edits were handled by the Qwen 2.1 edit model
- Video generation: The core engine was Minimax H3, using i2v (image-to-video) with first/last frame control to guide the motion
- Organization and assembly: Everything was orchestrated through multiple ComfyUI workflows, then assembled in video editing software
- Upscaling: Done with the creator's own trained upscaling model "Skrisp Texture" (not yet released), combined with several custom nodes for color grading and other adjustments
The first/last frame technique is central to this kind of workflow. It lets creators specify both the opening and closing frame of an animation, with the model responsible for generating the motion in between — enabling relatively controllable shot transitions without traditional keyframe animation capabilities.
ComfyUI is an open-source, node-graph-based frontend for AI creation. Users build generation pipelines by connecting functional nodes rather than writing code. Its core strength is modularity: image generation, image editing, video generation, upscaling, color correction, and more can be freely combined like building blocks and saved as reusable workflow files. This is why it has become the de facto orchestration tool for local AI creators. Compared to interfaces like Automatic1111, ComfyUI has a steeper learning curve, but offers far stronger support for complex multi-model pipelines — which is precisely why this creator was able to chain five or six different models into a single workflow.
180 Clips for One Finished Video: The Real Cost of Efficiency
The creator was candid: generating this random transformation video required around 180 clips. That number plainly reveals the reality of local AI video generation today: output depends heavily on mass trial-and-error and manual curation. Every i2v generation has an element of randomness — motion, composition, and consistency can all go wrong — so creators have no choice but to generate repeatedly and hand-pick usable clips to approximate the desired result.
In other words, going local doesn't mean going easy. It gives creators full control and zero per-call costs, but shifts an enormous time burden onto the generate-curate-redo cycle. For individual creators chasing specific artistic effects, this model offers a degree of freedom that cloud subscription services simply can't match. But for anyone prioritizing throughput, a 180:1 ratio makes clear that the technology is still far from plug-and-play.
i2v (Image-to-Video) refers to the paradigm of driving video generation from a static image as the starting condition, as opposed to t2v (text-to-video). The advantage is that creators can precisely control the composition and content of the first frame, rather than relying entirely on text prompts. Minimax H3 is a video generation model from Minimax that is highly competitive in motion smoothness and visual detail, and provides locally deployable weights — making it a common choice for high-end local workflows. First/Last Frame control adds an additional constraint on top of i2v: by specifying both the starting and ending frames of an animation, the model must interpolate plausible motion between two fixed images. This is conceptually similar to "in-betweening" in traditional animation and significantly improves the controllability of individual video segments.
Consistency Remains the Biggest Weakness
The creator's self-assessment was honest: "Still far from the consistency I want, some of the motion timing is off too, but it works for now."
Consistency is the universal pain point in AI video generation. Character appearance, scene details, and lighting relationships tend to drift from frame to frame and clip to clip — a problem that becomes even more pronounced in longer videos assembled from multiple segments. First/last frame control can constrain motion within a single clip, but cross-clip coherence across a full video remains difficult to guarantee. This is also why the creator needed to train a custom upscaling model and stack custom nodes for post-production fixes.
The unreleased self-trained upscaling model "Skrisp Texture" is worth noting. The creator mentioned it's still in development with plans to release it eventually. Custom-trained upscaling models are often tailored to specific art styles or textures, and their emergence signals that local creators are moving from "using off-the-shelf models" toward "refining their own bespoke pipelines."
Hardware Requirements: RTX 5090 Powers the Entire Pipeline
The entire workflow runs on a single RTX 5090. This is the unavoidable hardware barrier for local AI video generation — chaining multiple models, generating video, and running local upscaling are all hungry for VRAM and compute. A flagship consumer GPU has pulled this kind of workflow out of the data center and into the home office, but the entry cost remains significant.
For anyone looking to replicate these results, hardware configuration directly determines how complex a workflow you can run, how long each clip takes to generate, and whether you can realistically afford the time cost of 180 generations.
The RTX 5090 is NVIDIA's flagship consumer GPU released in early 2025, featuring 32GB of GDDR7 memory — one of the highest VRAM capacities available on a single consumer card today. Video generation models, especially high-resolution i2v models, demand far more VRAM than image generation: a single inference pass often requires holding complete temporal attention tensors in memory simultaneously, and insufficient VRAM will either prevent the model from running or force a resolution downgrade. Multi-model chained workflows also require frequent loading and unloading of model weights between different models, placing high demands on both VRAM bandwidth and total capacity. This explains why the previous generation flagship's 24GB (e.g., RTX 4090) is increasingly feeling tight for some video workflows, and why 32GB has emerged as a practical reference threshold for local video creation.
What This Case Tells Us
This video is a personal passion project, but it reads like a field report — sketching a clear picture of where local AI video creation actually stands in 2026:
The toolchain is already rich enough. From image generation and image editing to video generation and upscaling, there are locally deployable open-source or semi-open-source solutions for everything, all orchestratable flexibly through ComfyUI. The technical ceiling is also rising fast, with consumer hardware now capable of producing reasonably watchable output. But the three major obstacles — consistency, motion quality, and generation efficiency — remain standing, and creators are forced to compensate with mass trial-and-error and homegrown tools.
For creators, this is precisely the window to learn and build up workflow expertise. Those who master this pipeline earlier, and train models tailored to their own needs sooner, will be best positioned to capitalize when the next leap in model capability arrives.
Related articles

Amphibious Transforming Drone: Beyond 100x Power Savings, What Are the Real Needs?
Is the amphibious transforming drone just a gimmick? Starting from the 100x power difference of the M4 Morphobot, explore real application scenarios and thesis topic ideas, analyzing boundary conditions where pure drones and pure ground robots both fail.

Warhound Raises $200 Million: Genetically Engineered "War Dogs" Paired with Anduril Gear
Warhound raises $200M, backed by Ben Lamm and Palmer Luckey, to genetically engineer dogs for military and law enforcement use and equip them with Anduril gear. This article analyzes its technology direction, funding logic, and ethical controversy.

Claude API Comes to Google Cloud: IAM Integration and SDK Access Guide
Anthropic hosts the full Claude API on Google Cloud with IAM-controlled permissions and unified billing. This guide covers the Vertex AI and Anthropic-hosted entry points, IAM role configuration, and SDK access.