MMAS: Dual-Branch Temporal Fusion for Continuous Music Emotion Estimation
Research reveals the blind spot of pooled correlation, proposes a variance decomposition objective and the MMAS model, and analyzes the conformal interval coverage gap.
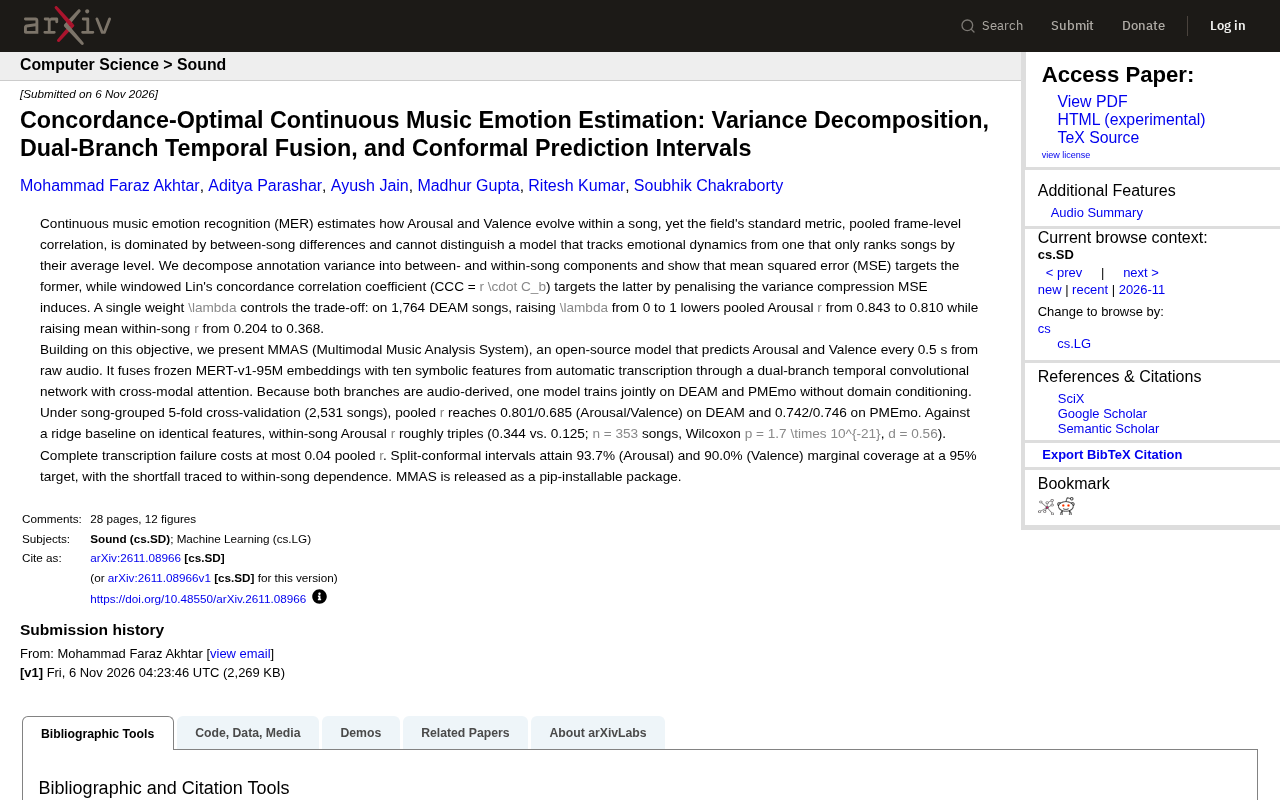
The study points out that the pooled frame-level correlation coefficient commonly used in continuous music emotion recognition mainly reflects between-song differences and cannot distinguish whether a model tracks within-song emotional dynamics. Through variance decomposition, the authors split annotation variance into between-song and within-song components, showing that MSE optimizes between-song differences while the windowed concordance correlation coefficient (CCC) targets within-song dynamics by penalizing variance compression, with a weight λ controlling the trade-off. Based on this, they propose the MMAS model, which uses a dual-branch temporal convolutional network to fuse frozen MERT embeddings with symbolic features via cross-modal attention, and a single model can be trained jointly on DEAM and PMEmo. Experiments show within-song Arousal r triples versus a ridge regression baseline, and transcription failure loses only 0.04 pooled r. The insufficient coverage of conformal prediction intervals stems from within-song dependence, offering a reference for uncertainty quantification.
Continuous Music Emotion Recognition (MER) has long relied on the pooled frame-level correlation coefficient (pooled r) as its standard evaluation metric, but this metric has a fundamental flaw: it primarily reflects average emotion differences between songs rather than the model's ability to track emotional dynamics within a song. A study titled "Concordance-Optimal Continuous Music Emotion Estimation: Variance Decomposition, Dual-Branch Temporal Fusion, and Conformal Prediction Intervals" proposes a systematic solution to this problem and open-sources a model called MMAS.
The Blind Spot of Pooled Correlation: A Variance Decomposition Perspective
The research team decomposed annotation variance into between-song and within-song components, revealing a key issue: mean squared error (MSE) primarily optimizes for between-song differences, whereas the windowed Lin's concordance correlation coefficient (CCC = r · C_b) genuinely targets within-song dynamics by penalizing the variance compression induced by MSE.
This finding has methodological significance. In the past, a model that merely ranked songs by average emotion level and a model that could track emotional fluctuations might obtain similar scores on pooled r, leading to distorted evaluation. The authors introduce a single weight λ to control the trade-off between the two objectives: on 1,764 DEAM songs, raising λ from 0 to 1 decreased pooled Arousal r from 0.843 to 0.810, while within-song mean r jumped from 0.204 to 0.368. This means the model sacrifices a small amount of between-song ranking accuracy in exchange for a significant enhancement in tracking emotional dynamics.
CCC (concordance correlation coefficient) is a common metric for evaluating continuous emotion prediction, defined as ( \rho_c = \frac{2\sigma_{xy}}{\sigma_x^2 + \sigma_y^2 + (\mu_x - \mu_y)^2} ), where (\sigma_{xy}) is the covariance between predictions and annotations, (\sigma_x^2) and (\sigma_y^2) are their respective variances, and (\mu_x), (\mu_y) are the means. CCC can be decomposed into the product of the Pearson correlation coefficient (r) and a precision factor (C_b): (\rho_c = r \cdot C_b), where (C_b) measures the deviation between predictions and annotations in mean and variance. Windowed CCC is computed over short time windows and can capture local dynamics; when the model's prediction variance is compressed (i.e., predictions tend toward the mean), (C_b) decreases, thereby penalizing this "regression-to-the-mean" behavior and forcing the model to preserve within-song emotional fluctuations.
MMAS Architecture: Dual-Branch Temporal Fusion and Cross-Modal Attention
Building on the above objective function, the researchers propose MMAS (Multimodal Music Analysis System), an open-source model that predicts Arousal and Valence every 0.5 seconds from raw audio. Its core design is a dual-branch temporal convolutional network with cross-modal attention: one branch processes frozen MERT-v1-95M embeddings, and the other processes ten symbolic features derived from automatic transcription.
As a detail, both branches are derived from audio, so a single model can be trained jointly on DEAM and PMEmo without domain conditioning. Under 5-fold cross-validation grouped by song (2,531 songs), pooled r reaches 0.801/0.685 (Arousal/Valence) on DEAM and 0.742/0.746 on PMEmo. Compared with a ridge regression baseline on the same features, within-song Arousal r roughly triples (0.344 vs. 0.125; n = 353 songs, Wilcoxon p = 1.7 × 10⁻²¹, d = 0.56).
In addition, the study examined the impact of automatic transcription failures: complete transcription failure loses at most 0.04 pooled r, indicating that the audio embedding branch bears the primary predictive responsibility, with symbolic features playing more of a supplementary role. This robustness is particularly important for real-world deployment scenarios.
Conformal Prediction Intervals and the Coverage Gap
The study uses split-conformal methods to generate prediction intervals. At a 95% target, marginal coverage for Arousal and Valence reaches 93.7% and 90.0%, respectively. The coverage shortfall is traced to within-song dependence—prediction errors of adjacent frames are not independent, violating the exchangeability assumption of conformal prediction. This finding has general reference value for uncertainty quantification in time-series emotion estimation.
MMAS is released as a pip-installable package, lowering the barrier to research reproduction and practical application.
Split-conformal prediction is a distribution-free uncertainty quantification method: the data is split into a training set and a calibration set, the model is fitted on the training set, nonconformity scores (such as absolute errors) are computed on the calibration set, and their empirical quantile is taken as the interval half-width, thereby generating prediction intervals with finite-sample coverage guarantees for new samples. Its theoretical guarantee relies on the exchangeability of calibration samples and the sample to be predicted. In time series, prediction errors of adjacent frames are autocorrelated, breaking exchangeability and causing actual coverage to fall below the nominal level. Mitigation strategies include weighted conformal, block conformal, or decorrelating the errors, but these methods remain to be explored in continuous emotion recognition.
Positioning and Limitations from Multiple Perspectives
According to the RSS source information, this work spans three levels—variance decomposition, dual-branch fusion, and conformal prediction—forming a complete chain from evaluation metrics to model architecture to uncertainty quantification. Its core contribution lies in pointing out the blind spot of the community's standard metric and providing an actionable alternative. However, the material does not disclose deployment-related metrics such as model parameter count or inference latency, and cross-dataset generalization is validated only on DEAM and PMEmo; performance on a broader range of music styles remains to be seen.
One-line Summary
The study reveals the blind spot of pooled correlation, proposes a variance decomposition objective and the MMAS model, and analyzes the coverage gap of conformal intervals.
Paragraph Summary
This study points out that the pooled frame-level correlation coefficient commonly used in continuous music emotion recognition mainly reflects between-song differences and cannot distinguish whether a model tracks within-song emotional dynamics. Through variance decomposition, the authors split annotation variance into between-song and within-song components, showing that MSE optimizes between-song differences, while the windowed concordance correlation coefficient (CCC) targets within-song dynamics by penalizing variance compression, with a weight λ introduced to control the trade-off. Based on this, they propose the MMAS model, which uses a dual-branch temporal convolutional network to fuse frozen MERT embeddings with symbolic features, integrated via cross-modal attention, and a single model can be trained jointly on DEAM and PMEmo. Experiments show that within-song Arousal r triples compared with a ridge regression baseline, and transcription failure loses only 0.04 pooled r. The insufficient coverage of conformal prediction intervals stems from within-song dependence, providing a reference for uncertainty quantification.
Related articles
Seven Years of Evolution: How Far Has the Foldable Come From the First Generation?
From the first foldable to today's latest models, what has seven years changed? Shallower creases, higher brightness, thinner bodies, and smoother software migration—has the foldable crossed the chasm from enthusiasts to ordinary users? This article discusses the question based on a video comparison.
When Did Humans Start Eating Salt? A 10,000-Year History of Salt
When did humans start eating salt? From salt use at the dawn of agriculture 11,000 years ago to ancient seawater evaporation and rock salt mining, and on to the salt trade, salt taxes, and Gandhi's Salt March, this article traces salt's key role in human civilization.
Microsoft Paza Research: How African Language Speech Recognition Breaks Through Architecture and Data Bottlenecks
Microsoft's Paza research evaluates 53 speech models across 39 African languages, revealing architecture choice matters more than pre-training coverage, 200-300 hours is the practical data threshold, and language typology deeply influences recognition performance.