Nearly Linear-Time FTPL Algorithm: A New Breakthrough for Weakly Observable Graph Bandits

Proposes an FTPL algorithm for weakly observable graph bandits, achieving nearly linear time and best-of-both-worlds guarantees in adversarial/stochastic environments.
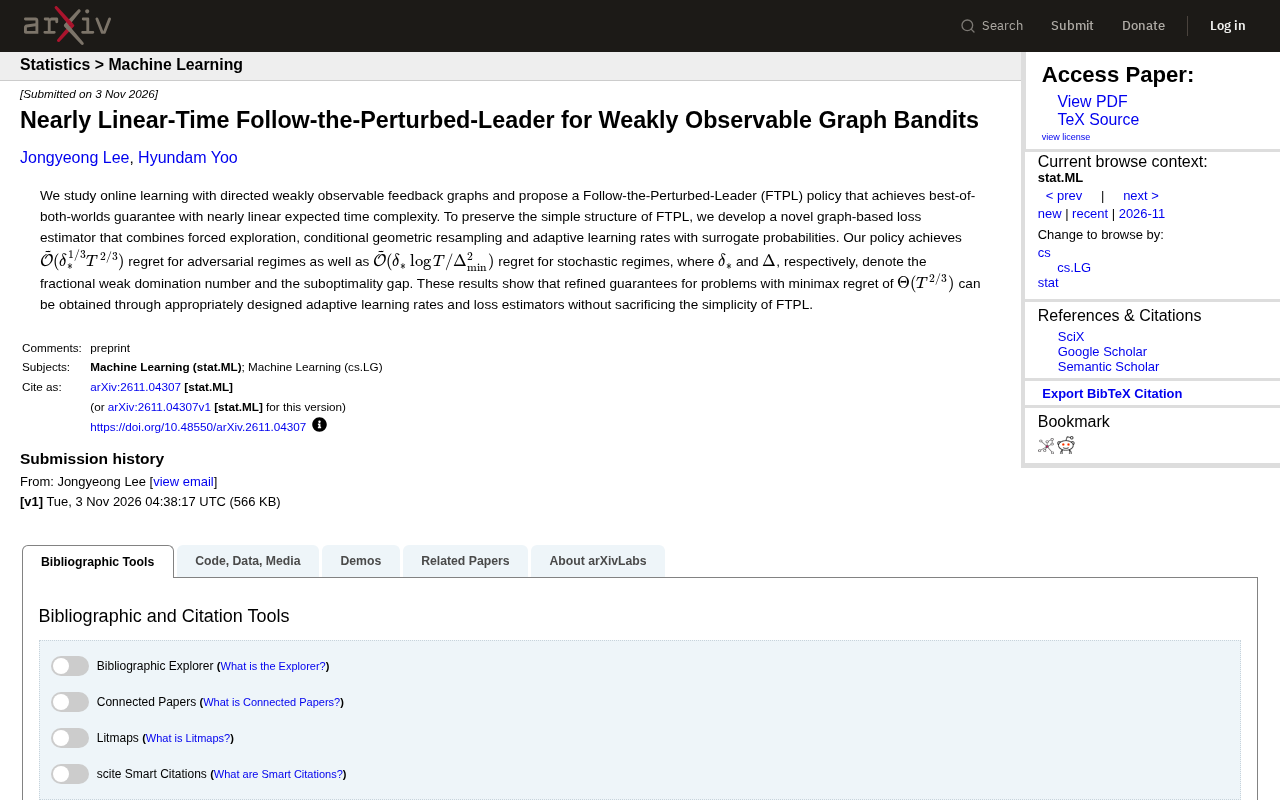
This paper addresses online learning on weakly observable directed feedback graphs and proposes an FTPL-based algorithm that combines forced exploration, conditional geometric resampling, and adaptive learning rates with surrogate probabilities to design an efficient graph-based loss estimator. Theoretically, it achieves Õ(δ_*^{1/3} T^{2/3}) regret in adversarial environments and Õ(δ_* log T / Δ_min^2) regret in stochastic environments, realizing best-of-both-worlds guarantees for the first time while maintaining expected time complexity close to linear.
Nearly Linear-Time FTPL Algorithm: A New Breakthrough for Weakly Observable Graph Bandits
The feedback graph problem in online learning has long been an intriguing branch of theoretical machine learning: in each round, the agent can only observe the losses of some neighbors in the graph, and the structure of the graph determines how information propagates. When the graph is directed and "weakly observable," the problem becomes even more challenging—you don't even know which actions' losses are observable. A recent arXiv paper, Nearly Linear-Time Follow-the-Perturbed-Leader for Weakly Observable Graph Bandits, proposes a new Follow-the-Perturbed-Leader (FTPL) strategy that, while keeping the algorithm simple, achieves "best-of-both-worlds" guarantees in both adversarial and stochastic environments, with expected time complexity close to linear.
Weakly Observable Graph Bandits: Background and Challenges
Feedback graph bandits are a generalization of the classic multi-armed bandit: each action corresponds to a node in the graph, and after selecting an action, only the losses of its out-neighbors can be observed. If the graph is directed and the agent can only see the losses that are actually observed without knowing which nodes are unobservable, it is called "weakly observable." This setting has practical significance in scenarios such as recommendation systems and social network influence maximization—you can only see partial feedback, and the visibility of feedback depends on the graph structure.
Most prior work on weakly observable graphs has focused on minimax regret, whose lower bound is Θ(T^{2/3}). However, how to design computationally efficient algorithms while maintaining adaptivity to stochastic environments (i.e., achieving log T regret) has remained an open problem. FTPL is a simple yet powerful algorithmic framework: in each round, it adds perturbation to the cumulative loss and then selects the action that minimizes the perturbed loss. But when standard FTPL is directly applied to graph bandits, it faces difficulties such as loss estimation and insufficient exploration.
Feedback graph bandit is a generalized model of multi-armed bandits, where each action corresponds to a node in the graph, and after the agent selects an action, only the losses of that node's out-neighbors can be observed. The graph structure determines how information propagates: if the graph is strongly connected, losses of all actions can be efficiently estimated through appropriate strategies; if the graph is weakly connected, information propagation is limited. Weakly observable specifically refers to the case in a directed graph where the agent can only observe the losses of out-neighbors of the actually selected action, and cannot directly know which nodes are unobservable. This setting commonly arises in practice in recommendation systems (users only give ratings for some items) and social network influence maximization (information propagates along directed edges).
Minimax regret is the standard metric for measuring bandit algorithm performance, defined as the maximum (worst-case over environments) of the difference between the algorithm's cumulative loss and the cumulative loss of the best fixed action. For weakly observable graph bandits, the known minimax regret lower bound is Θ(T^{2/3}), where T is the total number of rounds. This means any algorithm incurs at least regret on the order of T^{2/3} in the worst case. However, in stochastic environments (losses are i.i.d.), it is usually desirable for the algorithm to adaptively achieve logarithmic regret (i.e., O(log T)), which requires the algorithm to exploit randomness. FTPL (Follow-the-Perturbed-Leader) is a class of online learning algorithm frameworks: each round, it adds random perturbation to the cumulative loss vector and then selects the action that minimizes the perturbed loss. Its simplicity and theoretical guarantees have made it popular in bandit problems.
FTPL's Novel Loss Estimator: Forced Exploration and Geometric Resampling
The core contribution of the paper lies in designing a graph-based loss estimator that enables FTPL to handle weak observability. Specifically, the authors combine three key components:
- Forced exploration: selecting actions randomly with a certain probability to ensure every node has a chance to be observed, thereby avoiding estimation bias caused by the graph structure.
- Conditional geometric resampling: when the loss of a node is not observed, estimating its expected loss through geometric-distribution resampling. This method controls variance while maintaining unbiasedness.
- Adaptive learning rates with surrogate probabilities: the learning rate is dynamically adjusted based on the observed surrogate probabilities, allowing the algorithm to automatically adapt in both adversarial and stochastic environments.
These components work together so that FTPL, while maintaining a simple structure (each round only requires solving a linear optimization after perturbation), obtains theoretical guarantees. As a detail, the design of the loss estimator cleverly exploits the structural information of the graph rather than simply ignoring weak observability.
Conditional geometric resampling is a technique for estimating unobserved losses. In weakly observable graph bandits, due to graph structure constraints, the losses of some nodes may never be observable. To estimate the expected losses of these nodes, the algorithm uses geometric-distribution resampling: it repeatedly samples with a certain probability until the target node's loss is observed, where the success probability of each sample depends on the current graph structure and action selection. Conditional geometric resampling is performed conditioned on the given historical information, ensuring unbiasedness of the estimate while controlling variance through the tail properties of the geometric distribution. Specifically, for each unobserved node, the algorithm simulates a random walk starting from that node until reaching an observable node, thereby constructing an unbiased estimate of the loss.
Surrogate probabilities refer to auxiliary probabilities used in the loss estimation process to replace the true observation probabilities. In the weakly observable setting, the agent cannot directly know the probability that each node is observed, but can estimate a surrogate probability from the graph structure and historical actions. The adaptive learning rate is dynamically adjusted based on these surrogate probabilities: when the surrogate probability is small (i.e., observation uncertainty is high), the learning rate decreases accordingly to control variance; otherwise, it increases to accelerate convergence. This design allows the algorithm to automatically adapt in both adversarial and stochastic environments without prior knowledge of the environment type.
Theoretical Guarantees: Best-of-Both-Worlds for Adversarial and Stochastic Environments
The paper provides two main regret bounds:
- Adversarial environment: regret is \tilde{\mathcal{O}}(δ_^{1/3} T^{2/3}), where δ_ is the fractional weak domination number, which characterizes the degree of weak observability of the graph. When δ_* is small, the regret approaches T^{2/3}, matching the known lower bound.
- Stochastic environment: regret is \tilde{\mathcal{O}}(δ_* \log T / Δ_{\min}^2), where Δ_{\min} is the minimum suboptimality gap. This shows that the algorithm can achieve logarithmic regret in stochastic environments, with a linear dependence on δ_*.
These results show for the first time that, for problems with minimax regret Θ(T^{2/3}), finer guarantees can be obtained through appropriately designed adaptive learning rates and loss estimators without sacrificing the simplicity of FTPL. Compared with existing work, the algorithm also has a significant improvement in computational efficiency: the expected time complexity is nearly linear, whereas previous methods often required higher polynomial time.
Fractional weak domination number is a graph-theoretic parameter that characterizes the degree of weak observability of a graph, denoted by δ_. Intuitively, it measures the minimum fractional weight needed to "dominate" all nodes in the graph (i.e., ensure every node is covered by the out-neighbors of some nodes). In weakly observable graph bandits, the smaller δ_ is, the more favorable the graph structure is for information propagation, and the smaller the regret upper bound. Specifically, δ_* is defined as minimizing ∑_{v} x_v (x_v≥0) such that for every node u, there exists a node v on a path from its out-neighbors to u satisfying x_v≥1. This parameter reflects the connectivity and observability of the graph and is a key quantity in regret analysis.
Best-of-both-worlds guarantee means that the algorithm can achieve (near-)optimal performance in both adversarial and stochastic environments without prior knowledge of the environment type. In adversarial environments, the optimal regret is Θ(T^{2/3}); in stochastic environments, the optimal regret is O(log T). Best-of-both-worlds algorithms automatically adjust through adaptive mechanisms (such as adaptive learning rates) to suit both environments simultaneously. The FTPL algorithm in this paper, through carefully designed loss estimators and learning rates, achieves this guarantee for the first time in weakly observable graph bandits, with computational efficiency close to linear.
Computational Efficiency: A Nearly Linear-Time Implementation
A major advantage of FTPL is that each round only requires solving one linear optimization problem (selecting the minimum-loss action under the perturbed loss). However, in weakly observable graph bandits, the computation of the loss estimator can become a bottleneck. Through clever design of conditional geometric resampling and surrogate probabilities, the paper ensures that each update requires only a constant number of graph operations (such as sampling and table lookup), thereby achieving nearly linear expected time. Specifically, the algorithm does not need to explicitly enumerate all unobserved nodes; instead, it handles weak observability implicitly through probabilistic methods.
This efficiency improvement is crucial for online learning on large-scale graphs. For example, in social networks, the number of nodes may reach millions, and only algorithms with nearly linear time are practically scalable. Although the paper currently provides only theoretical analysis, its algorithmic framework is simple and easy to implement, laying the foundation for future empirical research.
Conclusion and Outlook
This paper provides an elegant solution for weakly observable graph bandits: through a novel loss estimator, it revitalizes the classic FTPL algorithm, obtaining best-of-both-worlds guarantees in adversarial and stochastic environments while maintaining simplicity and efficiency. Its theoretical results reveal deep connections between adaptive learning rates and loss estimator design, opening up multiple directions for future research, such as extending the framework to more general feedback structures, exploring applications in reinforcement learning, and conducting experimental validation.
For researchers interested in online learning theory, bandit algorithms, and graph-structured feedback, this work is worth reading carefully.
One-line Summary
Proposes an FTPL algorithm for weakly observable graph bandits, achieving nearly linear time and best-of-both-worlds guarantees in adversarial/stochastic environments.
Paragraph Summary
This paper addresses online learning on weakly observable directed feedback graphs and proposes a new algorithm based on Follow-the-Perturbed-Leader (FTPL). By combining forced exploration, conditional geometric resampling, and adaptive learning rates with surrogate probabilities, the algorithm designs an efficient graph-based loss estimator that overcomes the estimation difficulties caused by weak observability. Theoretical analysis shows that the algorithm achieves Õ(δ_^{1/3} T^{2/3}) regret in adversarial environments and Õ(δ_ log T / Δ_min^2) regret in stochastic environments, realizing best-of-both-worlds guarantees for the first time while maintaining expected time complexity close to linear. This work provides a simple and scalable solution for online learning on large-scale graphs.
Related articles

DSH + Ollama Local LLM Deployment in Practice: Free Chat with Da Fei Yu
Bilibili creator tests DSH + Ollama local LLM deployment end to end: Ollama install, Xunlei-accelerated downloads, ModelScope GGUF model import, DSH custom API address setup, and a comparison of Qwen 3.5 4B, 8B, Gemma, and other models on 8GB VRAM, with advice on choosing local deployment vs. API calls.

Tested: A $899 Mac Mini vs. a $200/Month AI Subscription
Real-world test of whether an M4 Mac mini can replace a $200 AI subscription: 16GB can't fit large models, and both speed and quality fall short—but privacy, no caps, and near-zero running costs make it an ideal host for an always-on agent. Includes buying advice per configuration and money-saving strategies.

RSTGameTranslation: Real-Time OCR Localization + Offline Translation with Local LLMs
RSTGameTranslation is an open-source real-time Windows game translation tool: OCR for English, Japanese, and Korean with Chinese overlays in place, plus Ollama or LM Studio local LLM offline translation and Whisper speech transcription for games, manga, and visual novels.