New Advances in Transformer In-Context Learning: Parameter ODE Estimation and Prediction

Transformer achieves theoretically guaranteed in-context learning for non-convex ODE parameter estimation and trajectory prediction via two-stage approximate maximum likelihood.
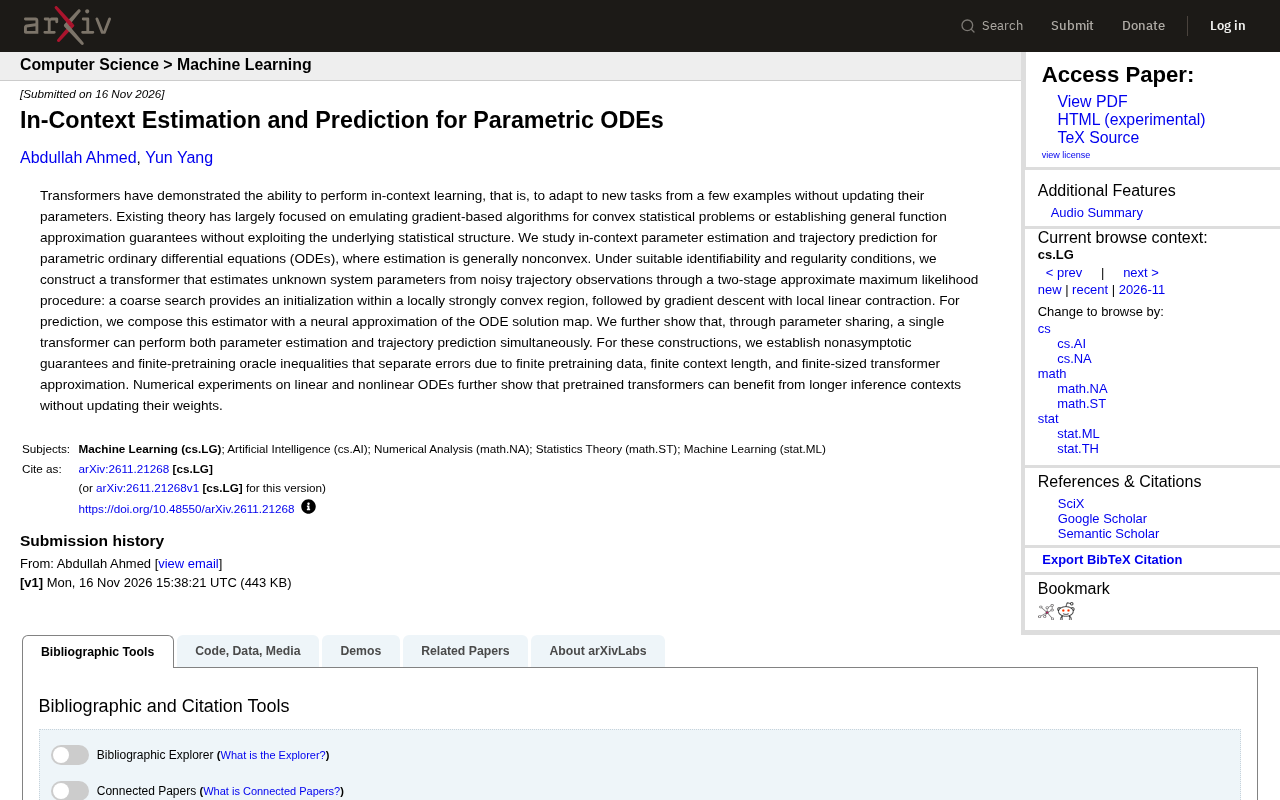
This paper addresses the gap in Transformer in-context learning theory for non-convex dynamical system parameter estimation. The authors estimate parametric ODE parameters from noisy trajectories and predict trajectories using a two-stage approximate maximum likelihood Transformer: coarse search localizes parameters to a strongly convex region, then gradient descent ensures convergence. Identifiability and regularity conditions remove reliance on global convexity. Parameter sharing lets one Transformer handle both estimation and prediction. Non-asymptotic guarantees and a finite-pretraining oracle inequality decompose error into pretraining data, context length, and model size. Experiments show pretrained Transformers benefit from longer inference contexts without weight updates.
Title
New Advances in Transformer In-Context Learning: Parameter ODE Estimation and Prediction
Meta Description
Interpreting new research on Transformer in-context learning: how to estimate parametric ODE system parameters and predict trajectories from noisy observations, two-stage approximate maximum likelihood construction, single-model parameter sharing, non-asymptotic theoretical guarantees, and performance gains from longer contexts.
Article Content
The in-context learning capability of Transformers has long been repeatedly confirmed by empirical studies—adapting to new tasks with just a few examples without updating weights. However, at the theoretical level, existing work mostly falls into two categories: either proving that Transformers can simulate gradient algorithms for convex statistical problems, or providing general function approximation guarantees, while rarely touching the statistical structure of the problem itself.
A recent study on parametric ordinary differential equations (ODEs) fills this gap. The authors investigate the problem of estimating ODE system parameters from noisy trajectory observations and predicting trajectories, and provide non-asymptotic theoretical guarantees.
Why ODE Parameter Estimation Is a Hard Problem
Parametric ODEs are widely used to describe dynamical systems, from physical modeling to biological processes. Given observed trajectories, inferring system parameters is a typical inverse problem, and it is usually non-convex—meaning the objective function may have multiple local minima, and the optimization process is sensitive to initialization.
This is fundamentally different from the convex statistical problem settings common in in-context learning theory. Previous analyses of Transformers simulating gradient descent mostly rely on convexity to guarantee convergence. Once the problem is non-convex, these tools are insufficient.
The entry point of the research is: instead of requiring global convexity, it leverages identifiability and regularity conditions to localize the problem.
Two-Stage Approximate Maximum Likelihood: Coarse Search First, Then Fine-Tuning
The Transformer constructed by the authors adopts a two-stage approximate maximum likelihood procedure:
The first stage is a coarse search, aiming to find an initialization point within the parameter space that falls into a locally strongly convex region. The second stage starts from this initialization and performs gradient descent, using local linear contraction properties to guarantee convergence.
The cleverness of this design lies in splitting the non-convex problem into two things: "localization" and "convergence." The coarse search is responsible for pulling the parameters into a "well-behaved" region, and gradient descent only needs to work within the locally strongly convex range, making theoretical analysis tractable.
For the prediction task, the authors combine the estimator with a neural network approximation of the ODE solution map: first estimate the parameters, then use the parameters to drive the solution map to generate trajectory predictions.
Local strong convexity is the key technical condition here. A non-convex function may satisfy strong convexity within a certain local region, i.e., the eigenvalues of the Hessian matrix in that region have a positive lower bound. The task of the coarse search stage is to drive the initial point into such a region; once inside, gradient descent under strong convexity achieves a linear contraction rate, and convergence speed is guaranteed. The difference from the global convexity assumption is that the authors do not require the entire parameter space to be "well-behaved," only that such a locally searchable basin exists. Identifiability and regularity conditions guarantee that such a strongly convex region indeed exists near the true parameters, and that trajectories corresponding to different parameters are separable, thereby making the estimation problem locally well-posed.
One Transformer Does Two Things at Once
The paper also demonstrates that through parameter sharing, a single Transformer can simultaneously perform parameter estimation and trajectory prediction. This is not simple multi-task stitching, but rather exploiting the statistical structure shared by the two tasks.
On the theoretical side, the authors establish non-asymptotic guarantees and a finite-pretraining oracle inequality, decomposing the error sources into three parts: error from finite pretraining data, error from finite context length, and error from finite-size Transformer approximation. This decomposition makes the contribution of each factor to final performance clear.
The finite-pretraining oracle inequality is a standard tool in statistical learning theory for characterizing estimator performance. Its meaning is: taking some "oracle" estimator (usually an ideal estimator assuming infinite data or an optimal algorithm) as a benchmark, it gives an upper bound on the error of the learning algorithm relative to that benchmark, and this upper bound explicitly depends on finite factors such as sample size and model capacity, rather than holding only asymptotically. In this paper, this inequality decomposes the Transformer's prediction error into three terms: pretraining data error, context length error, and network approximation error. The significance of this non-asymptotic decomposition is that it explicitly tells us which term is the bottleneck under finite resources, thereby guiding resource allocation in practice (e.g., whether to increase pretraining data or extend the inference context).
Experimental Observation: Longer Contexts Really Help
Numerical experiments cover both linear and nonlinear ODEs. One noteworthy phenomenon is that the pretrained Transformer can benefit from longer inference contexts without updating any weights. In other words, context length itself is a "free" means of improving accuracy—at least on these ODE tasks.
This aligns with a core intuition of in-context learning: the model has already learned some implicit algorithmic behavior during pretraining, and providing more observations at inference time is equivalent to giving this implicit algorithm more information.
Implications for In-Context Learning Theory
This work advances the theoretical analysis of in-context learning from convex statistical problems to non-convex dynamical system parameter estimation. Its value lies not only in ODEs themselves—non-convexity is a common feature of many practical inverse problems, and the two-stage "coarse localization + local convergence" construction may provide an analysis template for a broader range of non-convex in-context learning tasks.
Of course, the theoretical guarantees depend on identifiability and regularity conditions, and whether these conditions are commonly satisfied in practical systems still requires case-by-case analysis. The experiments are also currently concentrated on relatively controllable ODE scenarios, and transfer to more complex systems is a direction worth attention in future work.
One-line Summary
Transformer achieves theoretically guaranteed in-context learning in non-convex ODE parameter estimation and trajectory prediction via two-stage approximate maximum likelihood.
Paragraph Summary
This paper fills the gap in Transformer in-context learning theory regarding non-convex dynamical system parameter estimation. The authors study the problem of estimating parametric ODE system parameters from noisy trajectory observations and predicting trajectories, constructing a Transformer with a two-stage approximate maximum likelihood procedure: the first stage uses coarse search to localize parameters to a locally strongly convex region, and the second stage uses gradient descent to guarantee convergence. With identifiability and regularity conditions, the theoretical analysis no longer relies on global convexity. Parameter sharing enables a single Transformer to simultaneously perform parameter estimation and trajectory prediction. The authors establish non-asymptotic guarantees and a finite-pretraining oracle inequality, decomposing the error into three parts: pretraining data, context length, and model size. Experiments show that the pretrained Transformer can benefit from longer inference contexts without updating weights.
Related articles

AI SDK Workflow 2.0.109 Patch Update Analysis
Analysis of the @ai-sdk/workflow 2.0.109 patch update: the core is upgrading the ai package to 7.0.177, a dependency-driven patch release. This article explains the real impact on workflow developers, upgrade considerations, and a rational strategy for following high-frequency patches.
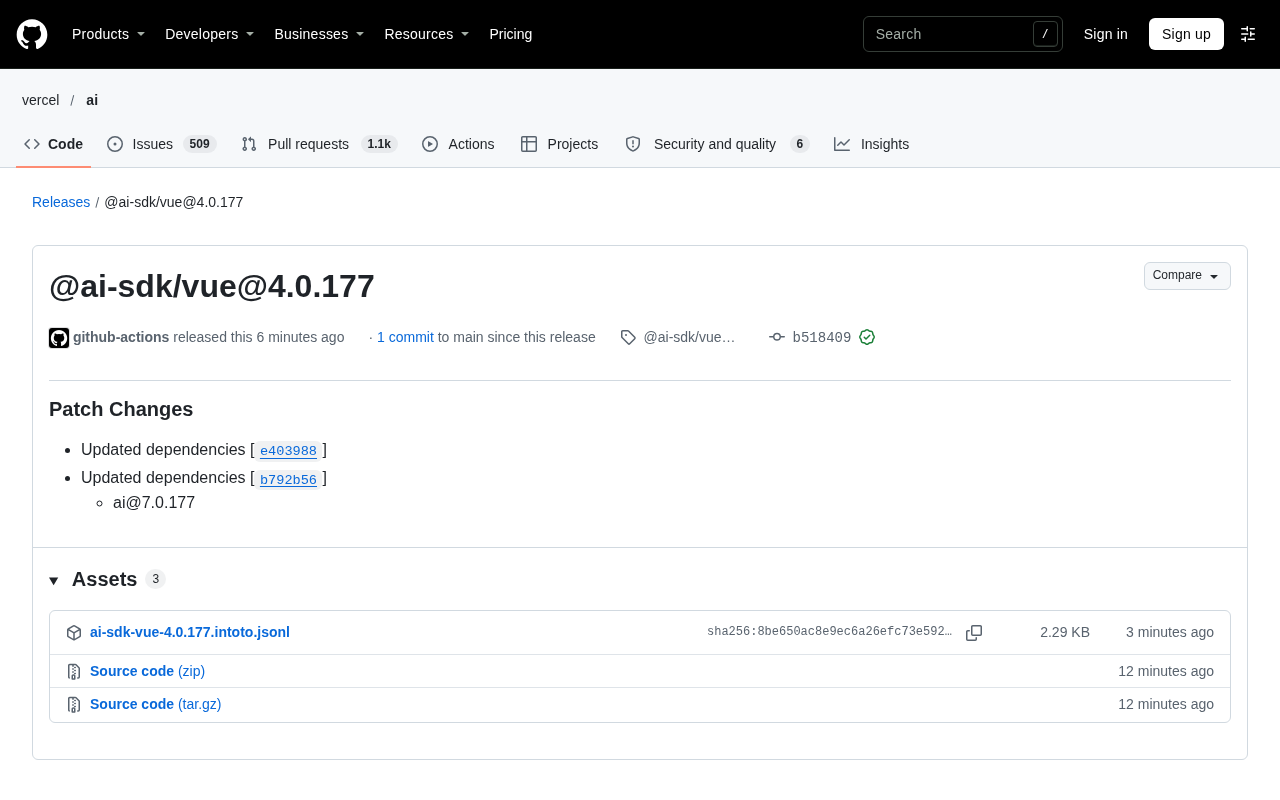
AI SDK Vue 4.0.177 Patch Released: Dependency Sync Upgrade
AI SDK Vue adapter package 4.0.177 patch released via GitHub Actions: syncs dependencies to ai 7.0.177, no API changes. Upgrade impact and automation explained.

When Everything Goes Down, These Engineers' Mental State Is a Real Concern
Starting from a Hacker News discussion on the state of outage response engineers, this analyzes the sources of stress in on-call culture, its impact on incident response quality, and structural problems like alert fatigue and responsibility-authority mismatch, along with possible directions for improvement.