Opus 5.5 Wins Back the Community: Anthropic's Comeback and the AI Cost Wars

Opus 5.5 tops third-party AI rankings as Anthropic and OpenAI clash in a landmark same-day model release.
In a rare same-day release, Anthropic launched Claude Opus 5.5 while OpenAI dropped GPT-6 Sol and Luna. Opus 5.5 staged a strong comeback after the poorly received 4.7–5.0 era, topping Artificial Analysis's Intelligence Index at 58 points with ~40% lower costs and widely praised writing quality. GPT-6 Sol and Luna extended OpenAI's cost-war playbook with another 50% API price cut. Community attention clearly favored Opus 5.5, though safety refusals remain a real barrier for legal and life sciences users. The releases crystallize a strategic split: OpenAI racing to the cost floor; Anthropic successfully reclaiming momentum.
Four Models in One Day: A Head-to-Head Between Two Giants
The first half of this week was unusually eventful in the AI world — not one, not two, but four major model releases dropped in quick succession. On Tuesday alone, OpenAI and Anthropic — the two most consequential labs right now — made the rare move of launching new models on the same day.
Anthropic went first with Claude Opus 5.5. OpenAI followed in the afternoon (Eastern Time) with GPT-6 Sol and GPT-6 Luna. The same-day timing made it all but inevitable that the conversation would shift from "what does this model actually offer" to a comparative narrative of "who's winning, who's ahead."
But what's really worth paying attention to is the two clearly distinct strategic paths these releases reveal: OpenAI continues to bet on cost efficiency at every layer of the intelligence stack, while Anthropic is trying to reclaim the community goodwill it lost since Opus 4.6.
Opus 5.5: From "Regression" to "King's Return"
To understand why Opus 5.5 sparked such enthusiasm, you need to recall the awkward history of the Opus line. After Opus 4.6 won a devoted following, versions 4.7 and 4.8 felt like marginal improvements at best — outright regressions in some use cases. Opus 5 was widely panned.
AI content creator Peter Yang captured this arc perfectly with a "drawing a horse" meme: Opus 4.6 was a beautifully rendered stallion; 4.7 and 4.8 devolved into rough children's sketches; Opus 5 was barely a scribble. And with Opus 5.5, that finely crafted horse is finally back.
On the benchmarks, Anthropic claims Opus 5.5 reaches the performance level of Claude Fable 5.1 on most tasks while running at roughly 40% lower cost. On Terminal Bench 4.0, Opus 5.5 jumped to 66.4%; it also outpaced both Fable 5.1 and Opus 5 on Cursor Bench, Frontier Code v1.1, and Humanity's Last Exam. Across Anthropic's full benchmark suite, Opus 5.5 didn't fall behind any of its stablemates on a single metric.
On pricing, Opus 5.5 comes in at $4 per million input tokens and $20 per million output tokens — down from Opus 5's $5 and $25. Combined with efficiency gains, the real-world cost reduction is around 40%. Generation speed is also about 30% faster than Opus 5.
Third-party evaluator Artificial Analysis offered even stronger validation: Opus 5.5 topped its Intelligence Index with a score of 58, a significant jump over the previous co-leaders Claude Fable 5.1 and GPT-6 Astra (both at 53) — and it came with a 20% price cut.
GPT-6 Sol and Luna: Doubling Down on the Cost War
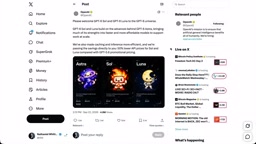
If Opus 5.5 leaned slightly toward cost and efficiency, GPT-6 Sol and Luna were built entirely around that premise. OpenAI's announcement positioned them as carrying most of GPT-6 Astra's strengths while being faster and cheaper — API pricing cut by another 50% from GPT-5.6's promotional rate.
Sam Altman's tweets underscored OpenAI's core thesis: per-task pricing (rather than per-token), with a claim that nothing on the market can compete on that basis. "We want people to use AI massively — that's essential for exploring the new renaissance unfolding before us."
What's telling is how OpenAI frames cost reduction — not as a concession, but as "unlocking new use cases." Lower prices and higher rate limits mean users can iterate more aggressively. The announcement revealed that the median OpenAI researcher consumes $600 worth of tokens per day via API, with the 90th percentile hitting $7,000 — a visceral illustration of what "massive use" actually looks like at scale.
The difference in philosophy even shows up in how benchmarks are presented: Anthropic still uses traditional model-vs-percentage charts; OpenAI has switched entirely to performance (Y-axis) vs. cost (X-axis) plots. Third-party data shows GPT-6 Sol and Luna's intelligence scores are roughly on par with the previous generation (around 37 points), but at half the cost. In real-world workflow testing, Zapier found 6 Sol scoring 33.2% versus 28.77% for 5-6 Sol — at roughly half the price — and concluded simply: "Every workflow on 5-6 should upgrade. It's cheaper and better."
A note on Jevons Paradox: The concept comes from 19th-century economist William Stanley Jevons, who observed that when the efficiency of using a resource improves and unit costs fall, people tend to use more of it — total consumption rises rather than falls. Applied to AI, the pattern suggests that every significant drop in token pricing unlocks use cases that were previously too expensive to deploy, driving total call volume up by multiples rather than margins. This is the theoretical backbone of Altman's "massive use" logic — OpenAI isn't just trying to retain existing users; it's using price compression to create entirely new demand layers. Box's Aaron Levy invokes this concept to explain why the number of agents deployed tends to explode (rather than grow linearly) as token costs fall.
The Attention War: Opus 5.5 Wins the Conversation
Despite each model having its distinct positioning, the community reaction was clear: Opus 5.5 captured the lion's share of attention. Matthew Berman put it bluntly: "Opus 5.5 becoming the strongest model on Earth while being cheaper than Astra and Fable was not on my prediction list." Chubby wrote that he loved it more with every use — "It's like my beloved Opus 4.6 came back, but better."
In concrete deployments, Box's team used Opus 5.5 for complex enterprise knowledge work, reporting 63% fewer tokens compared to Opus 5, 42% less verbosity, 30% faster responses, 39% improved accuracy on financial services tasks, and 65% improvement on cloud cost analysis. A wave of social media demos focused on 3D rendering and Blender animation — Anthropic's Alex Albert used a single prompt to generate a clay animation; Peter Yang showcased a Golden Gate Bridge scene generated entirely from code, with no image model involved.

On writing quality, the consensus was near-universal: Opus 5.5 is "strictly better." Anthropic describes it as communicating more naturally, front-loading important information, and actually following given writing rules. Writing-focused evaluator Every gave it high marks: "This is the most readable text we've seen from any Anthropic or OpenAI model" — and pointedly noted: "Anthropic fixed Opus's personality. It's no longer an obstinate little nuisance." McKay Wrigley summed it up: Opus 5.5 = the personality we wanted from Opus 4.6 + the intelligence and taste of Fable 5.1.
Safety Rails as a Double-Edged Sword
Beyond the praise, there are clear pain points. For certain professional contexts, Opus 5.5's safety refusals have become a direct blocker.
One legal professional reported that Opus 5.5 was "noticeably worse" for complex, open-ended tasks like drafting client and court-level documents, contract redlines, and legal research — citing increased safety refusals and "poor effort budget allocation." Simon Smith from a life sciences company also raised concerns: because Opus 5.5's capabilities in biology and cybersecurity now approach Claude Mythos 5.1, Anthropic has deployed Fable 5.1-level guardrails on it. The problem is that his team had been switching from Fable to Opus precisely when Fable refused a task — and now that escape route is gone too.

These restrictions aren't universal, but when they hit a specific use case, they can render the model completely unusable for that user.
Five Takeaways: From Model Wars to Stack Wars
This round of dense releases leaves a few observations worth sitting with.
Costs are falling at an unprecedented pace. Box's Aaron Levy analogizes it to "Jevons Paradox applied to agents" — each time token costs drop, the number of deployable agent use cases jumps substantially. Epic AI Research data supports this: at a given performance level, AI costs have fallen roughly 47% per quarter since 2023 — four times faster than DNA sequencing, six times faster than compute, and eighteen times faster than lithium batteries.
Personality is UX. Much of the excitement around Opus 5.5 isn't that "it can do things no model could before" — it's that "using it is enjoyable again." Even the most performance-focused early adopters who switch models constantly have clear personality preferences. The lesson: for LLMs, personality is user experience and should be treated as a first-class concern.
Models are increasingly inseparable from their "harness." Prime Intellect's Will Brown complained that he's switching desktop agents every week and burning out from it. For users deeply embedded in the Codex ecosystem, as long as OpenAI's option is "close enough," they may not migrate even if Opus 5.5 is technically stronger. The real test comes in a week — did this release actually change anyone's overall workflow habits, or did everyone finish benchmarking and go back to their defaults?
We may be entering a "product era" rather than a "model era." Alongside these releases, Meta's Muse became another hot topic, and users barely cared about its underlying model. If models increasingly get abstracted into systems, the entire "new model comparison" narrative logic could be rewritten.
This is what a "restrained frontier" should look like. As Theo noted, none of today's releases were Astra or Fable-tier launches — and that was intentional. The goal of restraint isn't to stop iterating; it's to prevent the research into larger models from getting out of control. Solving specific, known problems in existing models with lower cost and higher efficiency is a "low-risk, real upside" direction.
Strategically, OpenAI is continuing its established playbook: aggressively cutting costs and laying the groundwork for a "complex model architecture" era where different intelligence levels match different tasks. Anthropic's release looks more like a successful counteroffensive to reclaim momentum — and it largely worked. As Every concluded: Sol feels like an "S-tier iPhone launch"; Opus 5.5 is the bigger surprise — and it's pulling some people back from Codex to Claude.
A note on benchmarks: Terminal Bench, Cursor Bench, and Humanity's Last Exam are among the leading third-party capability evaluation tools in AI today. Terminal Bench focuses on code execution and task completion in terminal/command-line environments; Cursor Bench simulates programming assistance tasks in a real IDE; Humanity's Last Exam (HLE) is an academically designed set of extremely difficult questions spanning math, science, and the humanities, intended to probe models' reasoning limits — pass rates are generally low. Artificial Analysis's "Intelligence Index" is a weighted aggregate of multiple benchmarks designed to provide a cross-model comparison baseline. The key limitation of all these evaluations: they capture static performance on specific tasks and don't necessarily predict experience in real-world workflows. This is why community evaluations — like Box's and Zapier's real business workflow tests — often carry more weight with developers than official benchmarks.
Related articles

"Black October": Did AI Uncover 3% of All Critical Vulnerabilities Ever?
A Reddit post claims 3% of all critical software vulnerabilities ever were found in the past month, dubbed 'Black October.' We break down the statistical issues, how AI-assisted code auditing accelerates discovery, and how developers should respond.

Microsoft Project Gecko: Using AI to Bridge Language Gaps for African Farmers
Microsoft's Project Gecko launches PharmaChat, letting African farmers ask questions in their native language and get precise video clips and farming book chapters via AI. The project also releases three interactive manuals to advance inclusive AI.

Musk's Space Dominance: How Starlink Throttling Undermines Ukraine's Defense
SpaceX's Starshield throttling disabled Ukraine's high-speed interceptor drones, exposing how Musk's private control over low Earth orbit communications affects battlefield dynamics and national security, and highlighting the risks of commercial space militarization and space governance dilemmas.