Perplexity Open-Sources pplx-embed-v2-late: Cross-Modal Late-Interaction Embedding Models

Perplexity open-sources pplx-embed-v2-late, late-interaction embedding models for cross-modal text, image, and page retrieval.
Perplexity has released the pplx-embed-v2-late embedding model series using a late-interaction architecture that retains token-level multi-vector representations for fine-grained retrieval matching, achieving a better balance between precision and efficiency. The models' standout feature is a shared embedding space across text, images, and pages, enabling cross-modal queries without maintaining separate indexes. Open weights are available on Hugging Face for self-hosted RAG and multimodal search deployments, though official benchmark data has yet to be published and the storage overhead of multi-vector representations remains the key scalability trade-off.
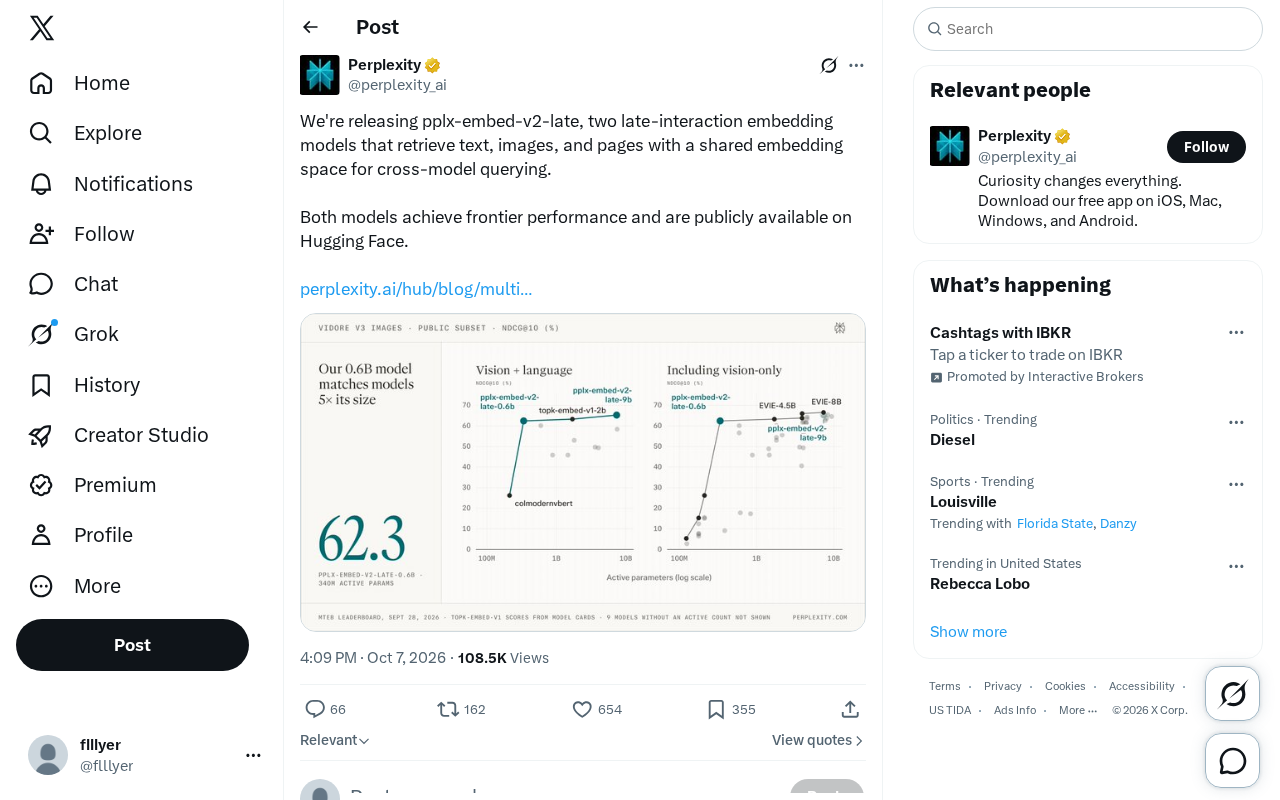
Perplexity has released two embedding models under the name pplx-embed-v2-late, featuring a late-interaction architecture that supports unified retrieval across text, images, and pages within a shared embedding space for cross-modal queries. Both models are now publicly available on Hugging Face.
What Are Late-Interaction Embedding Models
Traditional dense retrieval compresses a piece of text or an image into a single vector, then computes similarity between the query vector and document vectors at retrieval time. This "single-vector" approach is computationally efficient but inherently loses fine-grained semantic detail.
Late-interaction is an alternative approach, best known from the ColBERT family of models. The core idea is to avoid compressing content into a single vector and instead retain multi-vector representations at the token (or patch) level, performing fine-grained matching between all sub-vectors of the query and document at retrieval time. This preserves the dual-encoder architecture's advantage of pre-encoding documents for large-scale retrieval, while achieving matching precision closer to that of cross-encoders.
pplx-embed-v2-late extends this approach to multimodal scenarios, enabling it to handle not just plain text, but also images and full-page content.
ColBERT (Contextualized Late Interaction over BERT), proposed by Stanford University in 2020, is the foundational work in late-interaction architecture. Its core innovation is the "MaxSim" operation: for each token vector in the query, it finds the most similar token vector among all document token vectors, then sums these maximum similarity scores to produce the final matching score. This design allows documents' multi-vector representations to be precomputed and stored during indexing, with only the query needing to be encoded at retrieval time — avoiding the high latency of cross-encoders that must re-run inference over concatenated query-document pairs. The trade-off is significantly increased storage: each document is no longer a single vector but multiple vectors proportional to its token count, placing higher demands on vector database indexing capabilities. ColBERT v2 introduced vector compression techniques (residual compression encoding) to mitigate this issue and paved the way for production-scale deployment.
Cross-Modal Shared Embedding Space
The most notable aspect of this release is that both models use a shared embedding space, enabling cross-modal querying.
This means text, images, and pages are all mapped into the same semantic space. Users can query images using text, or retrieve related text and pages using an image — without needing to maintain separate indexes and alignment logic for each modality. For developers building unified retrieval systems, this reduces engineering complexity: one set of embeddings and one index covers multiple content types.
The ability to retrieve at the page level is particularly well-suited to real-world search engine needs: web pages typically contain text, charts, and layout information together. Embedding and retrieving at the page level is closer to actual use cases than first converting pages to plain text. This also aligns naturally with Perplexity's positioning as an AI search product.
Shared embedding spaces are typically implemented using a contrastive learning framework: during training, positive pairs from different modalities (e.g., a descriptive text and its corresponding image) are pulled closer together, while negative pairs are pushed apart, aligning representations from different modalities within the same geometric space. CLIP is the most representative early work in this direction, achieving cross-modal text-image retrieval through large-scale image-text pair training. The quality of a multimodal embedding space depends heavily on the scale and quality of training data, as well as negative sampling strategies. For the "page" modality, the challenge lies in the fact that a page integrates heterogeneous information — text, images, layout — typically requiring a specialized vision-language model (such as a vision Transformer-based architecture) to extract page-level semantic representations, rather than simply concatenating OCR output. Perplexity's inclusion of pages as an independent modality in a shared embedding space is one of the more distinctive engineering features of this model compared to existing multimodal retrieval approaches.
Performance and Openness
According to official statements, both models achieve frontier performance and have been publicly released on Hugging Face.
The open-weights approach means researchers and developers can directly download, evaluate, and integrate the models into their own retrieval pipelines without relying on a closed-source API. For applications such as RAG (retrieval-augmented generation), multimodal search, and document understanding, a high-performing, self-hostable embedding model is quite compelling.
It's worth noting that the official announcement only provides a general claim of "frontier performance" without specific benchmark data or detailed comparisons with competing models. Actual performance will need to be verified through the model card on Hugging Face and independent community evaluations.
RAG (Retrieval-Augmented Generation) is the dominant architectural paradigm in current large language model applications. The basic workflow is: pre-encode an external knowledge base into embedding vectors stored in a vector database, retrieve relevant document chunks when a user asks a question, then feed those chunks along with the question into the LLM to generate an answer. The quality of the embedding model directly determines the upper bound of retrieval recall, which in turn affects the accuracy of the final response. In multimodal RAG scenarios, knowledge bases often contain non-plain-text content such as PDFs, web page screenshots, and charts. Traditional text-only embedding models must first convert this content to text via OCR or parsing tools — a process that introduces both information loss and engineering complexity. Multimodal models that can directly embed images and pages can theoretically skip this conversion step, offering direct practical value for building multimodal RAG systems.
Significance for the Retrieval Ecosystem
Embedding models are the foundational infrastructure of modern AI search and RAG systems. Over the past year, multimodal retrieval and fine-grained matching have become major focus areas in the industry, and late-interaction architectures have regained attention for their balance between precision and scalability.
The release of pplx-embed-v2-late continues the academic lineage of ColBERT-style late interaction while making it production-ready, multimodal, and open-weights. For teams building retrieval systems, this is a new option worth including in comparative evaluations.
Whether it can replace existing single-vector embedding solutions in production ultimately depends on whether the storage and computational overhead of multi-vector representations falls within an acceptable range — which has always been the core trade-off of the late-interaction approach.
Related articles

Automate Job Search with AI Agents and Residential Proxies for Precise Matching
Build an AI Agent with MCP and residential proxies to bypass recruitment site anti-scraping and geo-restrictions, scrape thousands of DevOps jobs, then have Claude score and rank each against your resume. Includes proxy comparison experiments, project structure, and cost analysis—filtering only, no auto-submission.

The AI Task Assistant That Knows When to Back Off: A Cure for Activation Struggles
One Small Step is an AI assistant for task initiation struggles, using agentic decisions for guilt-free reminders, timely retreat, and cross-platform task management. The developer shares real test results on 13 tasks and architectural trade-offs.

FastAPI: A High-Performance Python Framework and a Production-Ready API Development Powerhouse
FastAPI is a high-performance web framework based on Python type hints, supporting async and automatic OpenAPI docs. With over 100k GitHub stars, this article analyzes its core strengths, production readiness, and selection advice.