PPO Algorithm Cracks the Moving Sofa Problem, Reconstructing Gerver's Optimal Solution

Developer reconstructs Gerver's optimal Moving Sofa solution with PPO, showing AI's potential and limits in math exploration.
The article covers developer Abhilekh Meda's use of PPO to tackle the classic Moving Sofa Problem: finding the largest sofa that can navigate a unit-width L-shaped corridor. Gerver proposed an optimal shape with area ~2.2195 in 1992, but its proof remains unverified. Meda modeled the problem as a continuous control task and trained a PPO agent to explore shapes and trajectories, yielding a shape highly similar to Gerver's. The article stresses this is not a mathematical proof, may be a local optimum, and is subject to randomness, but highlights reinforcement learning's value as a data-driven exploration tool, and notes the code is open-sourced with potential extensions to other problems.
When Reinforcement Learning Meets a Classic Math Problem
The Moving Sofa Problem is a famous geometric optimization challenge in mathematics: what is the maximum area of a sofa that can be maneuvered around a corner in an L-shaped corridor of unit width? Since mathematician Leo Moser posed the problem in 1966, it has attracted considerable attention. In 1992, mathematician Joseph Gerver proposed a sofa shape with an area of approximately 2.2195 and argued it was optimal. However, the complexity of the proof means it has yet to be fully rigorously verified.
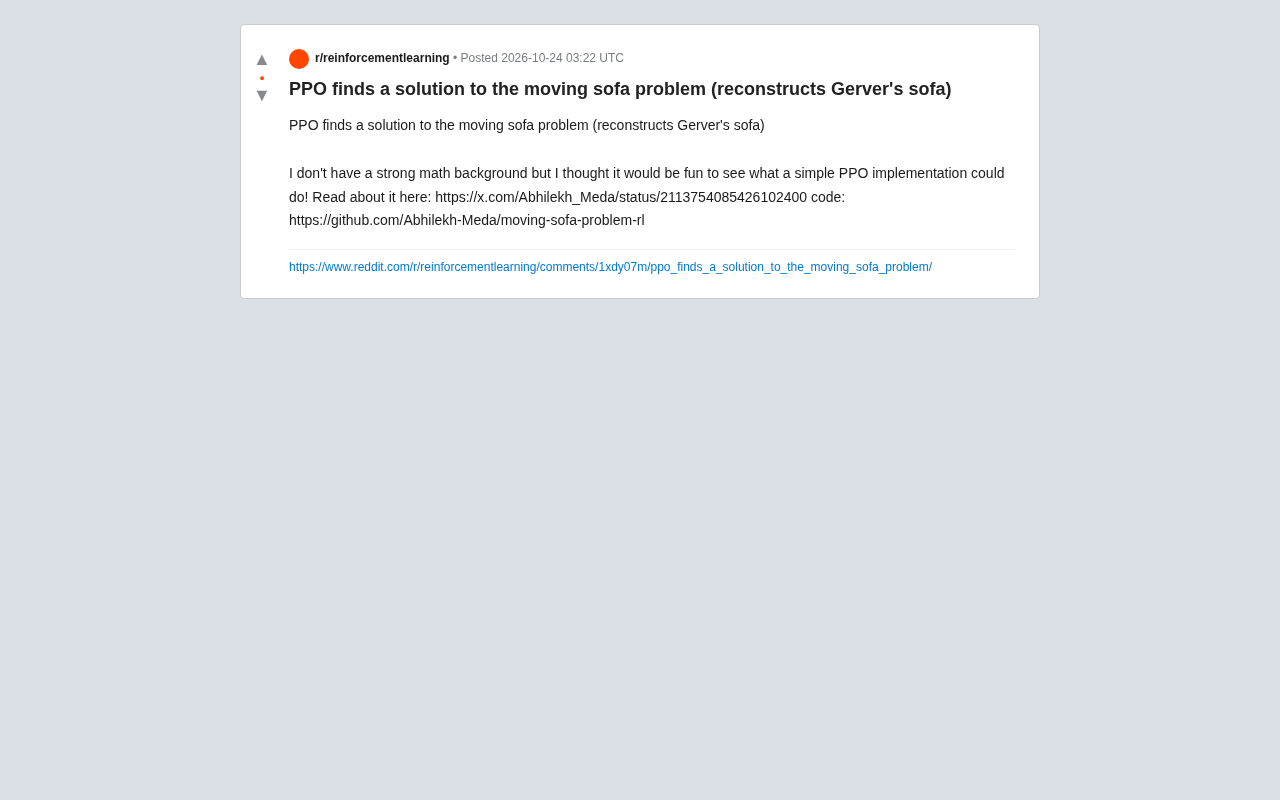
Recently, a developer named Abhilekh Meda attempted to solve the problem using the PPO (Proximal Policy Optimization) algorithm from reinforcement learning, successfully reconstructing Gerver's sofa shape. While this attempt is not a rigorous mathematical proof, it demonstrates the potential of reinforcement learning for solving complex geometric optimization problems.
How Does Reinforcement Learning "Move" the Sofa?
Problem Formulation and Application of PPO
The Moving Sofa Problem can be viewed as a continuous control problem: the sofa must move through an L-shaped corridor, avoiding collisions with walls while maximizing area. Meda modeled this as a reinforcement learning environment in which an agent controls the sofa's motion (including translation and rotation), with the goal of finding the largest-area shape that can pass through the corridor.
PPO is an advanced policy gradient algorithm known for its stability and sample efficiency. Meda used a simple PPO implementation, training the agent to explore different sofa shapes and motion trajectories in a simulated environment. After multiple iterations, the agent gradually learned a sofa shape that could pass through the corridor, with an area very close to Gerver's solution.
Policy Gradients and the Core Mechanism of PPO
Policy gradient methods are a class of reinforcement learning methods that directly parameterize the policy. Unlike value-based methods (such as Q-learning), policy gradient methods do not indirectly derive a policy by estimating the value of each action; instead, they represent the policy itself as a parameterized function π_θ(a|s) and update the parameters θ along the gradient of expected return, increasing the probability of high-return actions. The basic gradient estimate is ∇_θ J(θ) = E[∇_θ log π_θ(a|s) · A(s,a)], where A(s,a) is the advantage function, measuring how much better an action is relative to average.
Naive policy gradients suffer from two prominent issues: high gradient variance and unstable training; and difficulty in choosing step size, where updates that are too large can cause policy collapse. PPO (Proximal Policy Optimization) alleviates these issues by introducing a "clipping" mechanism: it constructs the probability ratio between new and old policies r_t(θ) = π_θ(a|s) / π_θ_old(a|s) and clips the objective to the interval [1-ε, 1+ε], thereby limiting the magnitude of each update and preventing drastic policy changes. This "trust region"-style constraint gives PPO good stability and sample efficiency while keeping the implementation simple, making it one of the most commonly used baseline algorithms in continuous control tasks. In the Moving Sofa Problem, the action space is continuous (translation and rotation), and PPO's clipping mechanism strikes a balance between exploring new shapes and maintaining existing feasible solutions.
Results and Comparison with Gerver's Sofa
Meda shared the training results on social media, showing that the sofa shape found by PPO is highly similar to Gerver's proposed optimal shape. Gerver's sofa consists of multiple circular arc segments and is complex in shape, while PPO, by optimizing the policy, can approximately reconstruct this shape. Although there may be subtle numerical differences, the result is impressive, especially considering that Meda claims no deep mathematical background.
Geometric Construction of Gerver's Sofa
The sofa shape proposed by Joseph Gerver in 1992 is not an arbitrary curve but consists of 18 carefully assembled curve segments, including straight lines and circular arcs, symmetric about the corridor's diagonal. The construction idea is: as the sofa passes around the corner, it must simultaneously maintain contact with the inner corner and outer wall of the L-shaped corridor; these contact points trace out a family of envelopes during motion, and the boundary of Gerver's sofa is precisely a combination of these envelopes. The shape's area is approximately 2.2195, long regarded as a strong candidate for the optimal solution.
From an optimization perspective, Gerver's sofa corresponds to a high-dimensional, non-convex, constrained functional optimization problem: the shape itself is a continuous function, and the constraint is "there exists a collision-free path through." Analytical solutions to such problems are extremely difficult; Gerver's original argument relies on complex variational analysis and geometric reasoning, and its full rigor remains debated. This also explains why approximating the shape via numerical or learning methods has independent value—it can verify structural features of the solution from another angle, such as whether the curvature distribution of circular arc segments and symmetry match theoretical expectations.
Significance and Limitations
The Role of Reinforcement Learning in Mathematical Discovery
This experiment demonstrates the potential of reinforcement learning for exploring mathematical problems. Traditional mathematical proofs rely on rigorous logical derivation, whereas reinforcement learning offers a data-driven exploration approach that can discover patterns humans might overlook. Similar methods have been used to find new mathematical conjectures or optimization algorithms.
However, reinforcement learning results do not constitute mathematical proof. The solution found by PPO may be only a local optimum or depend on randomness in the training process. Confirming the optimality of Gerver's solution still requires rigorous mathematical analysis. Meda also explicitly states that this is just an interesting attempt, not rigorous mathematical research.
The Difference Between Local and Global Optima
In optimization problems, a local optimum is a value that cannot be improved by small changes within some neighborhood, while a global optimum is the best solution over the entire feasible domain. Non-convex optimization problems (the Moving Sofa Problem is a typical example) often have many local optima, and gradient-based methods or reinforcement learning policies can easily get trapped in them. The sofa shape found by PPO is highly similar to Gerver's solution, indicating it has at least converged to a local solution close to the global optimum, but this does not rule out the existence of a larger-area shape, nor does it prove the solution is globally optimal.
This is precisely the fundamental difference between "numerical reconstruction" and "mathematical proof": numerical methods provide a specific candidate solution and approximate evidence of its optimality, while mathematical proof requires an airtight argument for all possible shapes. The randomness of reinforcement learning also means different training seeds may yield different results, so its results are better suited as exploratory evidence or a source of conjectures rather than definitive conclusions. Understanding this distinction helps correctly assess the actual boundaries of AI's role in mathematical discovery.
Impact on the AI Community
This work attracted attention on Reddit, with many netizens expressing surprise that reinforcement learning could reproduce a classic mathematical result. Some comments noted that such interdisciplinary applications help spark public interest in mathematics and AI. Meanwhile, Meda open-sourced the code, facilitating reproduction and extension of the experiment by others.
Future Directions
Meda's attempt opens new possibilities for applying reinforcement learning to geometric optimization problems. In the future, similar methods might be used to tackle other unsolved mathematical problems, such as sphere packing or variants of the traveling salesman problem. Of course, this will require more sophisticated algorithm design and greater computational resources.
More importantly, this experiment reminds us that AI is not just an engineering tool but can also be a partner in scientific exploration. By combining reinforcement learning with mathematical theory, we may be able to discover new frontiers of knowledge.
(Note: This article is based on the Reddit post and content shared by the author. Code and more details are available on GitHub.)
One-line Summary
A developer used PPO reinforcement learning to reconstruct Gerver's optimal solution to the Moving Sofa Problem, demonstrating the potential and limitations of AI-assisted mathematical exploration.
Paragraph Summary
The article describes developer Abhilekh Meda's attempt to solve the classic geometric puzzle "Moving Sofa Problem" using the PPO algorithm. The problem asks for the maximum area of a sofa that can pass through a corner in a unit-width L-shaped corridor. Gerver proposed an optimal shape with area about 2.2195 in 1992, but the proof has not been fully rigorously verified. Meda modeled the problem as a continuous control task and used PPO to train an agent to explore sofa shapes and motion trajectories, ultimately obtaining a shape highly similar to Gerver's sofa. The article emphasizes that this result is not a mathematical proof, may be only a local optimum, and is subject to randomness, but it demonstrates the value of reinforcement learning as a data-driven exploration tool in mathematical discovery. It also notes that the code is open-sourced and could potentially be extended to other problems such as sphere packing.
Related articles

CowAgent: Open-Source Super AI Assistant Unveiled
CowAgent is an open-source super AI assistant unveiled on Hacker News. This article covers its positioning, the value and challenges of open-source AI assistants, and community reaction.
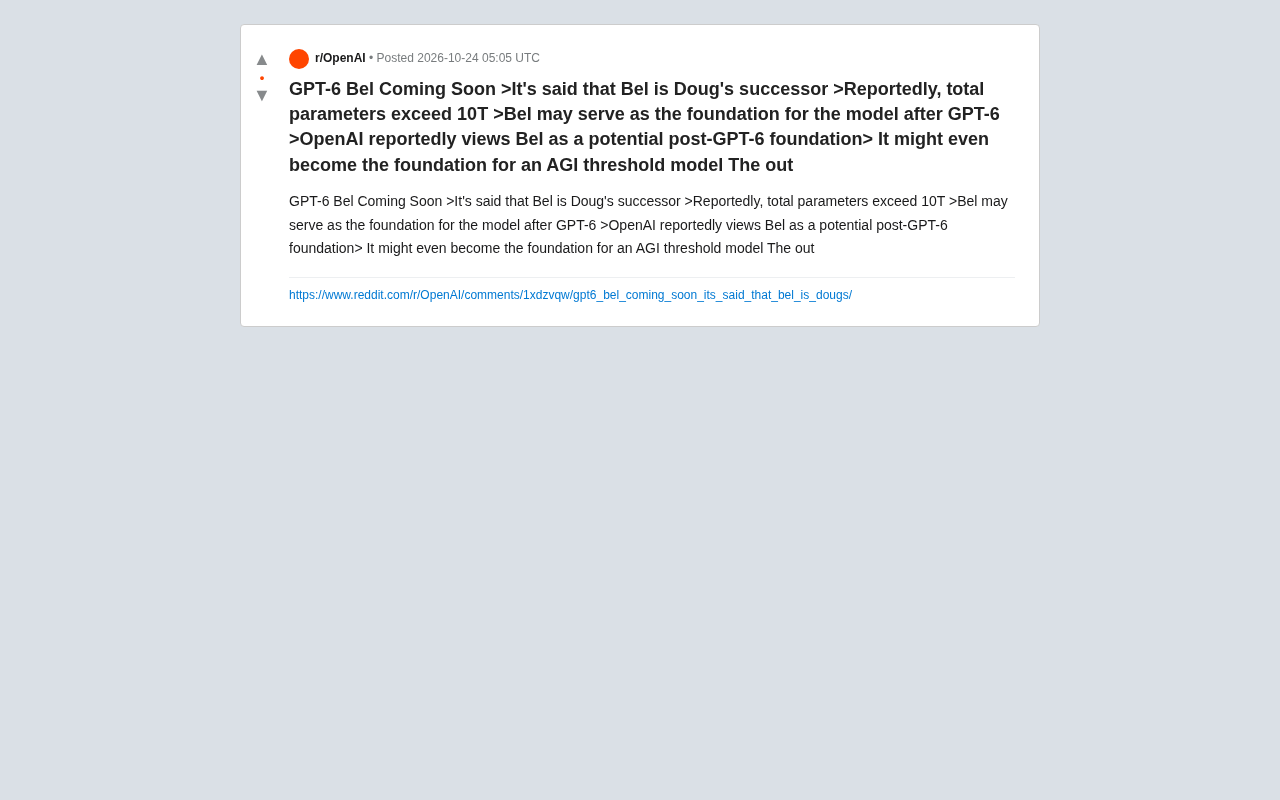
OpenAI's New Model Bel Leaked: 10 Trillion Parameters, Potentially the Foundation for AGI
A Reddit leak claims OpenAI's new model Bel is coming, with over 10 trillion total parameters, possibly serving as the foundation model after GPT-6 or even the base for the AGI threshold. This article breaks down the key claims and assesses their credibility.
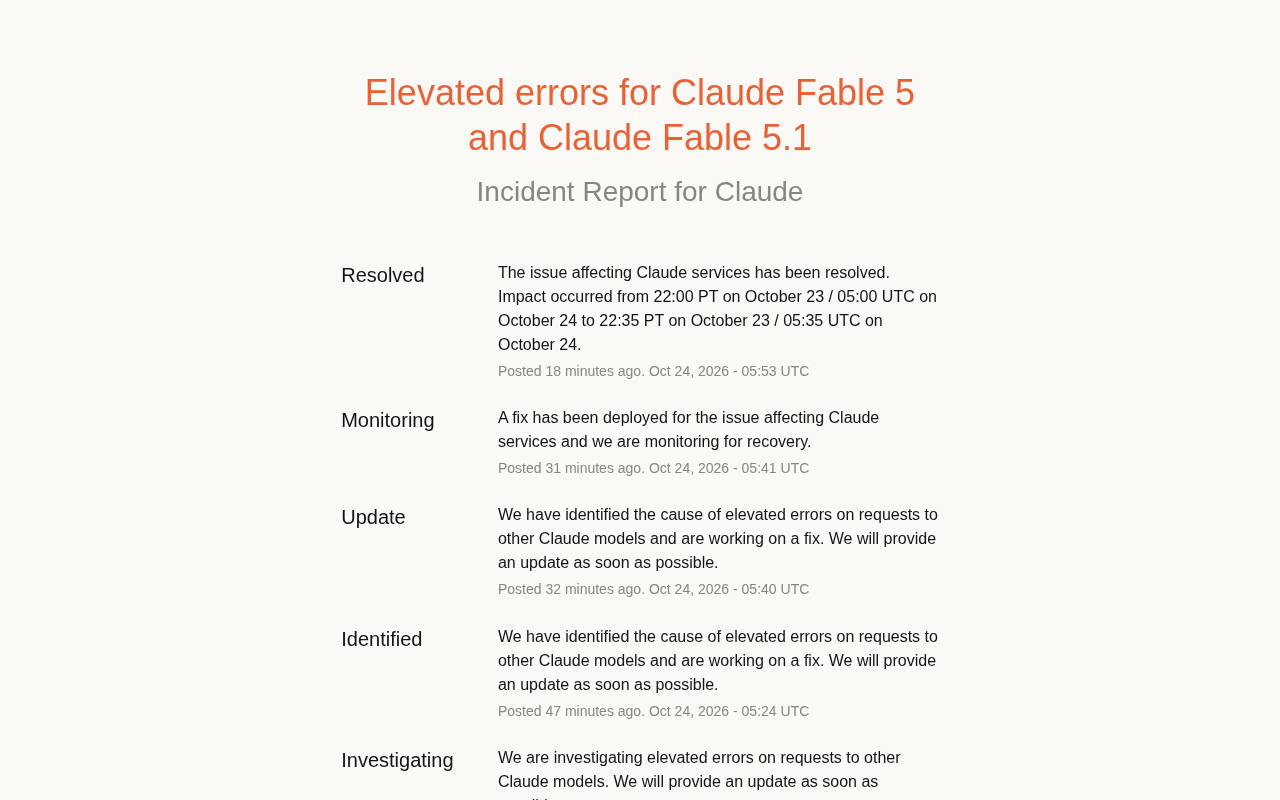
Claude Fable 5/5.1 Outage: A 30-Minute Postmortem
Claude Fable 5 and Fable 5.1 saw elevated error rates for about 35 minutes, per the official status page—from Investigating to Resolved in 37 minutes. This post reconstructs the timeline, analyzes impact on other Claude models, and offers developer guidance on retries, multi-model routing, and monitoring alerts.