Pruned Models Got Dumber? Rethinking LLM Pruning via Test-Time Scaling

Study re-evaluates pruning via test-time scaling: lower pass@1 doesn't mean lost reasoning ability.
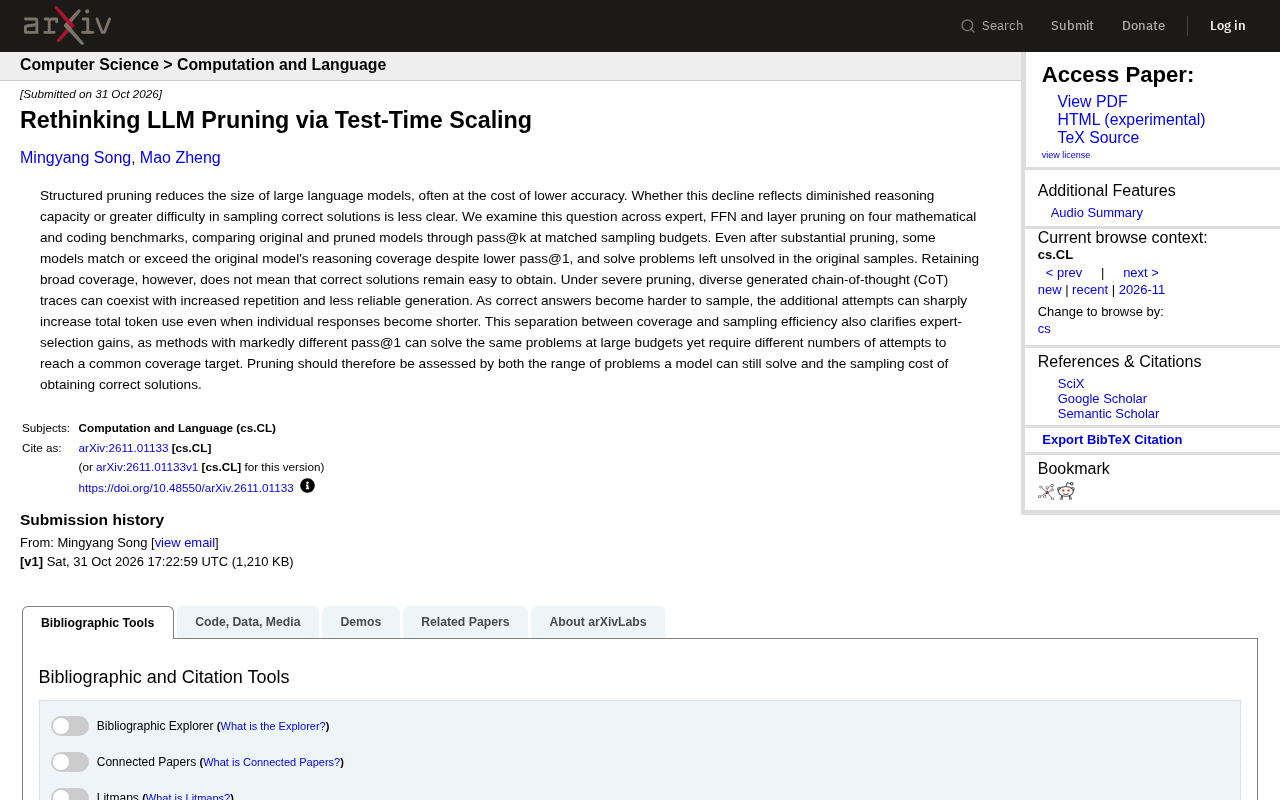
This study re-examines structured LLM pruning through test-time scaling, showing that a drop in pass@1 after pruning does not necessarily mean impaired reasoning. Comparing expert, FFN, and layer pruning on math and coding benchmarks, it finds some pruned models still match or exceed the original's reasoning coverage in pass@k, though correct answers are harder to sample. It distinguishes "coverage" from "sampling efficiency," notes severe pruning raises token costs despite diverse CoT, and proposes evaluating pruning on both coverage and efficiency.
Structured pruning of large models typically comes at the cost of accuracy degradation—but does this degradation mean reasoning ability is impaired, or does it merely make correct answers harder to sample? A new study offers a more nuanced answer to this question through the lens of Test-Time Scaling.
The Core Question: Accuracy Drop ≠ Loss of Reasoning Ability
In conventional evaluation, pruned models are often judged as "dumber" because of a drop in pass@1. But this study systematically compares expert pruning, FFN pruning, and layer pruning across four categories of math and coding benchmarks, observing pass@k performance of both original and pruned models under matched sampling budgets.
The key finding: even after substantial pruning, some models can still match or even exceed the original model in reasoning coverage, despite lower pass@1. This means pruning does not necessarily destroy the model's reasoning ability—it may simply change the samplability of correct answers within the generation distribution.
The difference between pass@k and pass@1: pass@1 refers to the probability that the model answers correctly in a single generation, while pass@k refers to the probability that, given k independent samples, at least one is correct. The relationship between the two is not simply linear: if a model with low pass@1 has an output distribution that covers the correct answer, then as k increases, pass@k may rapidly approach or even surpass that of a model with higher pass@1. This metric originated from code generation evaluation (e.g., HumanEval) and has since been widely used to measure the "potential upper bound" of large models on tasks such as mathematical reasoning. The key to understanding pass@k lies in distinguishing "whether the model has the ability to generate the correct answer" from "the probability that this answer appears in a single sample"—pruning may primarily affect the latter.
Separating Coverage from Sampling Efficiency
The study further reveals an easily overlooked distinction: retaining broad coverage does not mean correct answers remain easy to obtain. Under severe pruning, models can generate diverse Chain-of-Thought (CoT) trajectories, but this comes with increased repetition and decreased generation reliability.
When correct answers become harder to sample, the additional attempts required sharply increase total token consumption—even if individual responses become shorter. This separation between "coverage" and "sampling efficiency" has direct implications for practical deployment costs.
Chain-of-Thought (CoT): refers to the prompting and generation paradigm in which a model generates intermediate reasoning steps before giving a final answer. CoT enables models to decompose multi-step reasoning into traceable intermediate states, significantly improving accuracy on complex tasks such as math and logic. In pruning research, the diversity of CoT trajectories can serve as a proxy for "reasoning coverage": if a pruned model can still generate multiple different solution paths, its reasoning ability is not completely destroyed. But CoT also brings cost issues—longer trajectories mean more token consumption, and severe pruning may cause trajectory repetition or degradation, reducing effective coverage while driving up sampling overhead.
Reunderstanding the Gains from Expert Selection
This perspective also clarifies the source of gains from expert-selection pruning. Different methods may differ significantly in pass@1, yet under large budgets they can solve the same problem sets—only the number of attempts required to reach a common coverage target differs. In other words, the benefits of expert selection are reflected not only in single-pass accuracy but also in sampling cost.
Expert pruning (expert-selection) and MoE architecture: Expert pruning typically targets Mixture-of-Experts (MoE) models, whose feed-forward layers consist of multiple "expert" sub-networks, with only some experts activated during inference. Expert pruning removes redundant or unimportant experts to compress model size. Different expert selection strategies (e.g., importance scoring based on activation frequency, weight norms, or calibration data) lead to different retained expert combinations, thereby affecting the output distribution. The study points out that differences in pass@1 among these strategies may stem from correct answers being pushed toward the tail of the distribution, rather than from essential differences in reasoning ability; under large sampling budgets, different strategies may cover the same problem sets, differing only in the number of attempts required.
A New Framework for Evaluating Pruning
The study thus proposes that evaluation of pruned models should consider two dimensions simultaneously: how broad a range of problems the model can still solve (coverage), and the sampling cost required to obtain correct answers (efficiency). Judging pruning quality solely by pass@1 may underestimate the actual potential of pruned models under test-time scaling, and may also obscure the hidden overhead caused by decreased generation reliability.
For engineering practice that must trade off inference cost against model size, this framework offers an evaluation approach that is closer to real-world usage scenarios.
Test-Time Scaling: refers to methods that improve model performance at inference time by increasing computation (e.g., multiple sampling, longer CoT, tree search, or voting mechanisms), as opposed to training-time scaling (enlarging models or data). Its core assumption is that a model's potential upper bound is higher than its single-pass greedy decoding performance, and additional computation can "mine out" correct answers. Evaluating pruning under the test-time scaling lens means not just looking at single-forward-pass accuracy, but comparing pass@k curves and total token costs under a given sampling budget. This framework is closer to the trade-off decisions in real deployment: "how much inference compute for how much accuracy."
One-line Summary
A study re-evaluates pruning from a test-time scaling perspective, showing that a drop in pass@1 does not equal a loss of reasoning ability.
Paragraph Summary
This study re-examines structured pruning of large models from the perspective of test-time scaling, pointing out that a drop in pass@1 after pruning does not necessarily mean reasoning ability is impaired. By comparing expert pruning, FFN pruning, and layer pruning on math and coding benchmarks, the study finds that some pruned models can still match or even exceed the original model's reasoning coverage in pass@k, though correct answers are harder to sample in a single attempt. The study further distinguishes "coverage" from "sampling efficiency": under severe pruning, models can generate diverse CoT but with increased repetition and decreased reliability, leading to higher total token consumption. This perspective also clarifies that the gains from expert selection methods partly come from sampling cost rather than single-pass accuracy, and accordingly proposes evaluating pruned models along both coverage and efficiency dimensions.
Related articles

AI Can Read Neural Network Weights Directly: Do Models Already Exceed Expectations?
A Reddit developer experiment shows language models can directly read neural network weights and infer their function. Astra, Opus 5.5, and Muse Spark 1.3 all passed the test, sparking discussion on model generalization and training sources.

India's Microdrama Market Explodes: EloElo Secures $80M Investment from NBCUniversal
EloElo secures $80M from NBCUniversal to boost StoryTV, its microdrama platform with over 33M monthly active users, as India's microdrama market draws global capital.

Acoustic Detection of Multi-Rotor UAVs: Fusing Handcrafted Features with Pre-Trained Embeddings
Study reveals data leakage from random splits in UAV acoustic detection, proposes source-disjoint protocol with stacked ensemble of handcrafted features and YAMNet embeddings, achieving 95.29% accuracy for low-cost drone detection.